Command Palette
Search for a command to run...
視覚と行動のショートカットを断つ:汎化可能なロボット基盤モデルのための潜在インターフェース学習
視覚と行動のショートカットを断つ:汎化可能なロボット基盤モデルのための潜在インターフェース学習
Jianman Lin Shailesh Shailesh Zhongyi Luo Jiafei Duan
概要
ロボット基盤モデルは、学習分布内では高い性能を達成するものの、視覚的な分布シフト下では性能が低下することが多い。事前学習済みの視覚表現から行動を生成する学習過程において、モデルは学習分布内で示範行動と相関する、タスクに無関係な視覚的手がかりを悪用する可能性がある。このような視覚と行動のショートカットは、分布シフトによってこれらの相関関係が変化した際に、汎化性能を損なう恐れがある。これらのショートカットを軽減するには、タスクに関連する空間情報を保持しつつ、行動生成に視覚情報がどのように利用されるかを制約する必要がある。我々は、フレームワークに依存しない2段階の戦略であるLatent Interface Training (LIT)を提案する。LITは、まず画像を用いずに空間目標に条件付けられた行動事前分布を確立し、その後、姿勢教師ありの潜在インターフェースを通じて視覚的条件付けを制約する。第1段階では、行動エキスパートを訓練し、言語、ロボットの状態、および各示範動作チャンクの終端におけるエンドエフェクタのSE(3)姿勢に基づいて行動チャンクを生成させる。これにより、視覚的手がかりに依存せず、目標指向の行動生成を学習する。第2段階では、視覚表現と意味表現を集約し、事前学習済みの行動エキスパートにとって唯一の視覚的条件付け経路として機能する潜在インターフェースを導入する。このインターフェースは、第1段階で条件付けに用いた終端姿勢を再構成するよう教師あり学習され、行動生成に必要な目標関連の空間情報を保持するよう促される。4つの視覚-言語-行動および世界-行動アーキテクチャ(π0.5、MolmoAct2、FAST-WAM、ImageWAM)にわたる評価では、LITはLIBERO-Plusの全体成功率を3.87~10.70パーセントポイント向上させると同時に、平均LIBERO成功率を維持または改善した。実環境評価では、未知のカメラ設定、照明変動、および妨害物体の存在下での3つのタスクにおいて、集計した成功率が13.30~16.70パーセントポイント向上した。
One-sentence Summary
The authors propose Latent Interface Training (LIT), a two-stage framework that mitigates vision–action shortcuts by first learning a goal-conditioned action prior without images and then constraining visual information through a pose-supervised latent interface, which boosts robot foundation model generalization under visual distribution shifts with 3.87–10.70 percentage-point gains on LIBERO-Plus across four architectures (π0.5, MolmoAct2, FAST-WAM, and ImageWAM) and 13.30–16.70 percentage-point gains in real-world tasks under unseen camera configurations, lighting variations, and distractors.
Key Contributions
- Latent Interface Training (LIT) is a framework-agnostic two-stage strategy that mitigates vision–action shortcuts by constraining the action expert’s visual conditioning to a pose-supervised latent interface.
- In the first stage, the action expert is pretrained without images on language, robot state, and each action chunk’s terminal SE(3) end-effector pose. In the second stage, a latent interface aggregates visual and semantic representations and is supervised to reconstruct that terminal pose, serving as the action expert’s sole visual conditioning pathway.
- When applied to π0.5, MolmoAct2, FAST-WAM, and ImageWAM, LIT preserves LIBERO performance while improving zero-shot LIBERO-Plus success by 3.87–10.70 percentage points, and yields real-world gains of 13.30–16.70 percentage points across three tasks with unseen camera setups, lighting variations, and distractors.
Introduction
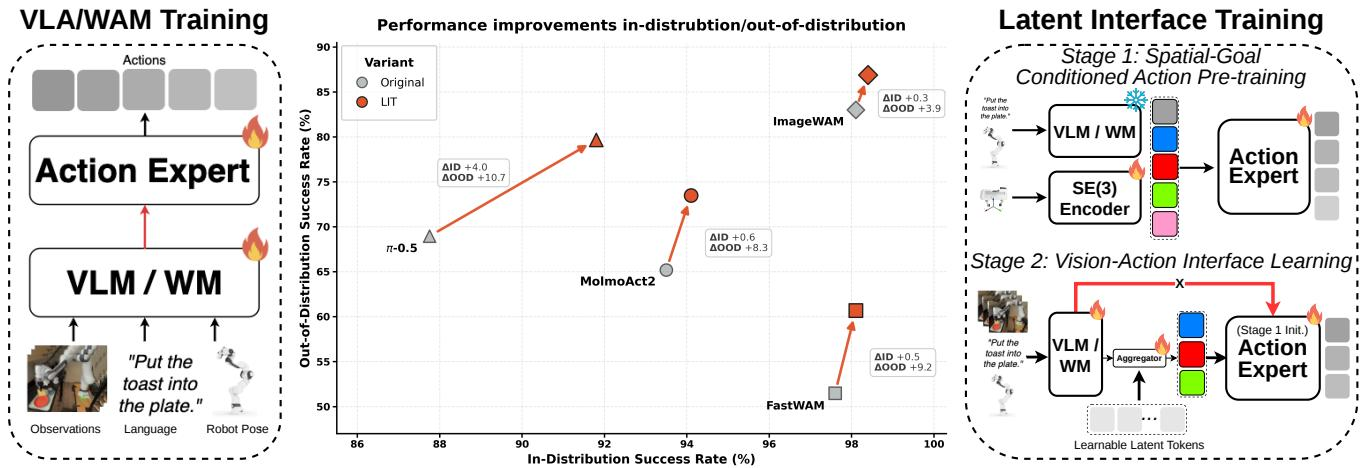
Robot foundation models that combine vision–language backbones with action experts achieve strong in-distribution manipulation performance but struggle to generalize when visual conditions shift. Because action experts receive rich visual representations, they can latch onto task-irrelevant visual cues that correlate with training actions—a vision–action shortcut—and this reliance is worsened by limited visual diversity in robot demonstration data. Prior work tries to address this by injecting structured spatial information or by pretraining image-free action priors, yet neither approach directly constrains how the action expert uses visual inputs when they are reintroduced. The authors propose Latent Interface Training (LIT), a model-agnostic two-stage strategy that first learns a spatial-goal-conditioned action prior without images, then introduces visual conditioning exclusively through a pose-supervised latent interface. By forcing all visual information through this interface and requiring it to reconstruct the same end-effector pose used during pretraining, LIT reduces vision–action shortcuts while preserving the spatial information needed for accurate action generation.
Method
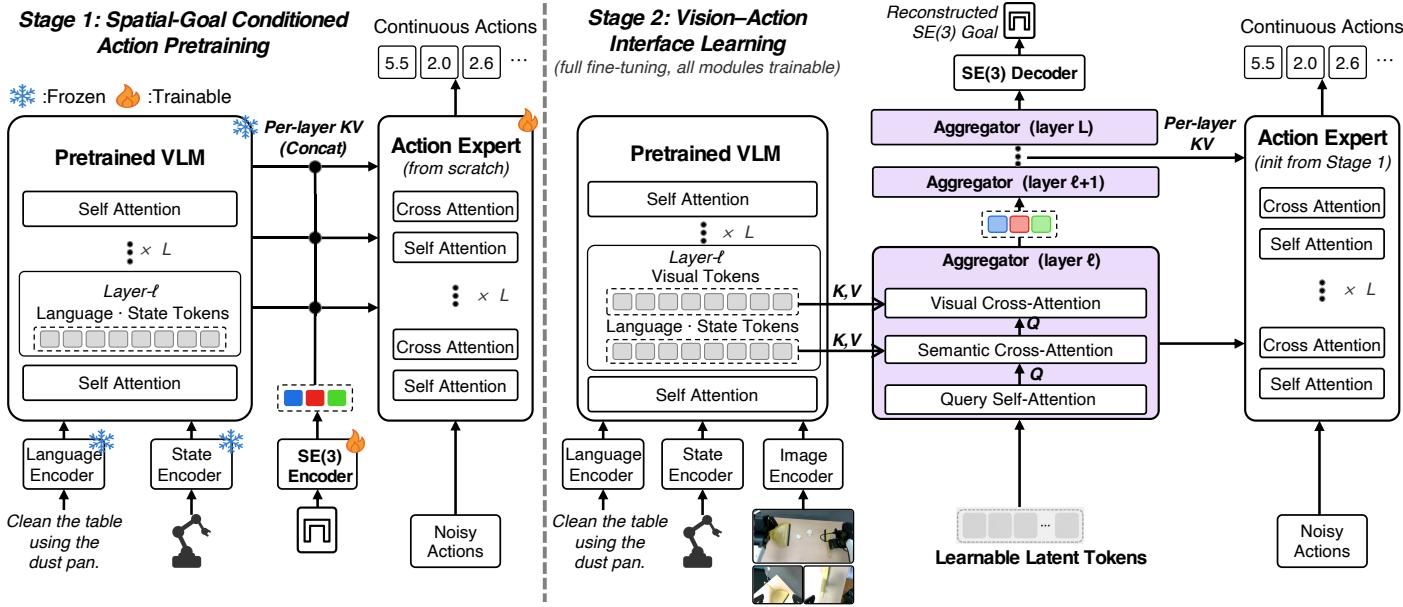
The authors propose Latent Interface Training (LIT), a model agnostic two-stage strategy designed to reduce vision-action shortcuts while preserving task-relevant spatial information. The overall framework first establishes an action prior without images and then introduces visual conditioning exclusively through a pose-supervised latent interface.
Refer to the framework diagram:
Problem Setup At each timestep t, the policy receives a visual observation ot, a language instruction l, and a robot state st to predict an action chunk of horizon H:
At=(at,…,at+H−1).For each demonstrated chunk, the terminal robot state is used as the spatial goal:
gt=[pt+H;rt+H;qt+H]∈R8,where p∈R3 and r∈R3 represent the world-frame end-effector position and axis-angle orientation, and q∈R2 contains the gripper joint positions. This goal acts as a conditioning signal in the first stage and a reconstruction target in the second stage.
Stage 1: Spatial-Goal-Conditioned Action Pretraining In the first stage, the authors train the action expert from scratch to generate demonstrated action chunks conditioned on the language instruction, robot state, and the terminal pose gt, effectively learning a spatial-goal-conditioned action prior without any visual input. The frozen backbone processes only the language instruction and robot state, producing semantic representations Hℓ,tsem at each of the L coupling layers. A trainable three-layer MLP with GELU activations maps the goal gt to goal tokens Gt, which are concatenated with the backbone representations:
Gt=Eη(gt),Cℓ,t=[Hℓ,tsem;Gt],ℓ=1,…,L.These concatenated tokens Cℓ,t condition the corresponding action expert layer through the native conditioning mechanism. The authors retain the framework's native flow-matching objective. They sample τ∼U(0,1) and ϵ∼N(0,I) to construct the noisy action chunk and target velocity:
Atτ=(1−τ)ϵ+τAt,vt⋆=At−ϵ.Given the conditioning tokens, the action expert predicts the velocity and minimizes the prior loss:
vtτ=vθ(Atτ,τ;C1:L,t),Lprior=EAt,τ,ϵ[∥vtτ−vt⋆∥22].Only the action expert parameters θ and the SE(3) encoder parameters η are updated, while the backbone and its modality encoders remain frozen.
Stage 2: Vision-Action Interface Learning In the second stage, the action expert is initialized from Stage 1, and visual conditioning is introduced exclusively through a pose-supervised latent interface. The authors define learnable latent tokens Z0∈RK×d shared across inputs, with K=100. For each policy input, the interface starts from Z0,t=Z0. At coupling layer ℓ, the backbone provides language and state representations Hℓ,tsem alongside visual representations Hℓ,tvis. The latent tokens are updated through self-attention, semantic cross-attention, and visual cross-attention:
Zℓ,t=Zℓ−1,t+SAq(ℓ)(Zℓ−1,t),Zℓ,t=Zℓ,t+CAq(ℓ)sem(Zℓ,t;Hℓ,tsem),Zℓ,t=Zℓ,t+CAq(ℓ)vis(Zℓ,t;Hℓ,tvis),ℓ=1,…,L.The latent tokens act as queries in each cross-attention operation, while the backbone representations provide the keys and values. For parameter efficiency, every m consecutive coupling layers share interface attention parameters, indexed by q(ℓ)=⌈ℓ/m⌉. The updated tokens condition the action expert layers, which predict the velocity:
vtτ=vθ(Atτ,τ;Z1:L,t).An MLP decoder reconstructs the terminal goal state gt from the final latent tokens:
gt=Dω(ZL,t),Lpose=∥gt−gt∥22,Lstage2=Lact+λposeLpose.The authors set λpose=0.3. This reconstruction loss encourages the interface to retain goal-relevant information. Stage 2 jointly optimizes the backbone, the action expert, the latent tokens, the interface attention modules, and the MLP decoder.
Framework Integration and Inference LIT introduces a latent interface between a pretrained backbone and an action expert, making it applicable to various architectures. The interface provides layer-wise conditioning through each architecture's native mechanism while retaining the original architectures and objectives. At inference, the latent interface remains active, while the pose encoder and pose decoder are omitted. The policy requires only visual observations, language, and robot state, following the native action sampling and execution procedures.
Experiment
LIT was evaluated across multiple VLA and WAM architectures, where it preserved or slightly improved in-distribution task performance and consistently enhanced zero-shot generalization under diverse visual and task perturbations. Real-world robot experiments confirmed increased robustness to lighting, camera, and distractor changes, and analyses showed that LIT reduces reliance on spurious visual correlations by routing visual information through a pose-supervised latent interface. Ablation studies further verified that the combination of spatial-goal-conditioned action pretraining, pose supervision, and restricted visual access is essential for these gains.
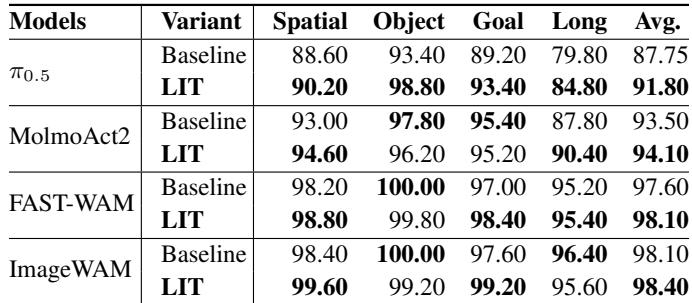
LIT consistently improves in-distribution success rates over the baseline across diverse architectures on LIBERO. The benefit is more pronounced for lower-performing baselines, while already strong models such as FAST-WAM see only marginal gains. ImageWAM attains the highest overall average, reaching perfect or near-perfect scores on object and goal subtasks. LIT raises the average success of the base model from 87.75% to 91.80%, a gain of over 4 percentage points, whereas for FAST-WAM the improvement shrinks to 0.5 points (from 97.60% to 98.10%). ImageWAM achieves a perfect 100% on object and 97.60% on goal subtasks, resulting in the highest average in-distribution success rate (98.10%) among all evaluated variants.
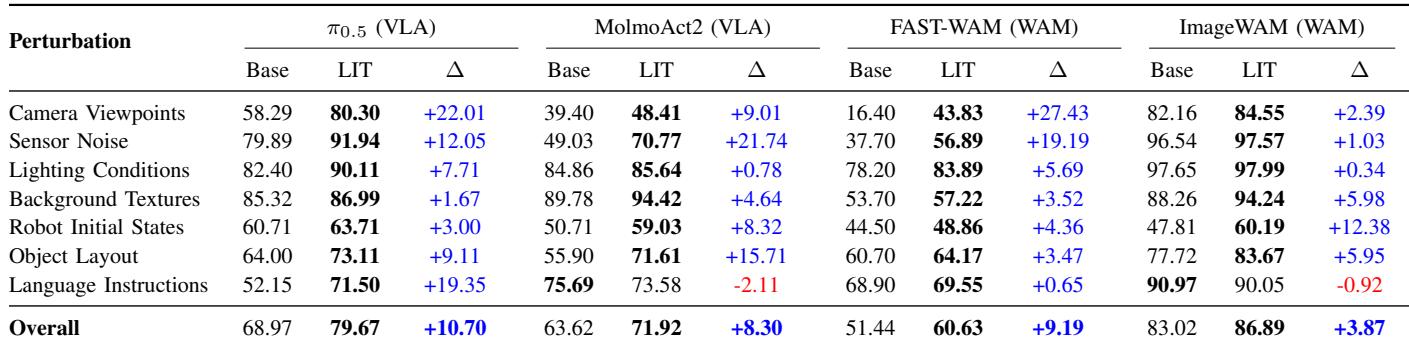
LIT delivers consistent zero-shot improvements across all evaluated manipulation architectures on LIBERO-Plus, with the largest absolute gains under camera viewpoint changes and sensor noise. Architectures starting from low baselines gain the most, while already-robust models like ImageWAM see meaningful improvement mainly under robot initial state variability. Ablation studies show that both the restricted visual pathway and pose supervision are essential for this generalization, especially against task-irrelevant visual perturbations. For the π₀.₅ VLA, LIT raises success on camera viewpoint changes by 22.0 percentage points and on sensor noise by 12.1 points. MolmoAct2 gains 21.7 points under sensor noise and 15.7 points on object layout changes with LIT. FAST-WAM, with a baseline of only 16.4%, improves by 27.4 points on camera viewpoint perturbations after LIT. ImageWAM already exceeds 96% on sensor noise and lighting; its largest LIT gain is 12.4 points on robot initial states. Removing pose supervision drops sensor noise performance by 10.8 points and background texture performance by 6.0 points. Giving the action expert direct visual access reduces overall OOD success from 71.9% to 67.7%, supporting the restricted latent interface.
LIT substantially improves over the MolmoAct2 baseline in overall out-of-distribution success, with each of its three design elements—Stage 1 action pretraining, pose supervision, and restricted visual pathway—contributing to the gain. Ablating any single component reduces generalization, and alternative simpler designs fail to match LIT, showing that the combination of a spatial-goal-conditioned prior, explicit pose reconstruction, and a latent-only visual bottleneck is essential for the observed robustness. Removing Stage 1 action pretraining lowers overall OOD success, especially under robot initial states and object layout variations, confirming that spatial-goal-conditioned pretraining aids visual policy adaptation. Ablating pose supervision causes the largest drops in sensor noise and background texture scenarios, aligning with the idea that spatial-goal supervision improves robustness to task-irrelevant visual perturbations. Allowing the action expert direct visual access rather than routing through the latent interface reduces OOD success, supporting the importance of the restricted visual pathway for generalization. Training only the latent-token aggregation without the action prior and pose supervision yields only minor improvement over the baseline, indicating the latent interface alone is far from sufficient. Staged training without LIT’s specific components or simply adding pose supervision to the baseline both reach only about 65.5% OOD success, well below LIT, ruling out these simpler explanations for the gains.
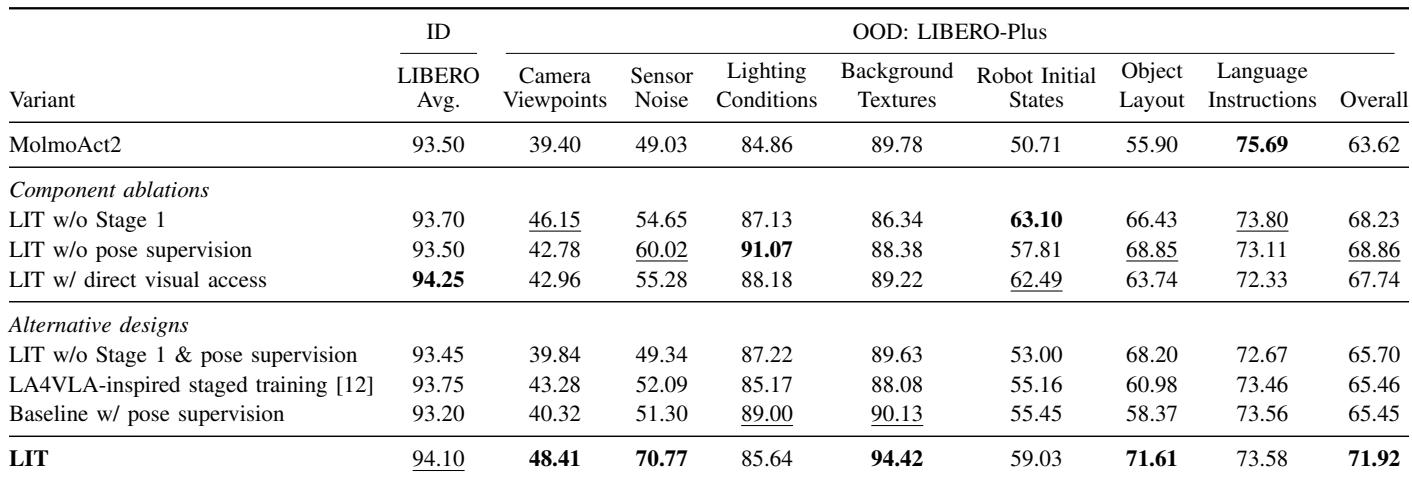
The experiments evaluate LIT's in-distribution performance on LIBERO and zero-shot generalization under diverse perturbations on LIBERO-Plus. LIT consistently improves success rates, with the largest gains for lower-performing baselines, while already strong models see only marginal benefits. Across camera changes, sensor noise, and visual variations, the restricted visual pathway and explicit pose supervision prove essential for robustness, and ablations confirm that all three design components—spatial-goal-conditioned action pretraining, pose reconstruction, and the latent-only bottleneck—jointly underpin the observed out-of-distribution improvements, ruling out simpler alternatives.