Command Palette
Search for a command to run...
Feyospace-v1:サイバー・マーキュリー・セブンはいかにして最先端サイバーモデルを訓練したか
Feyospace-v1:サイバー・マーキュリー・セブンはいかにして最先端サイバーモデルを訓練したか
Zongjie Li Alan Z. W John Nicolas J Walter H. F Scott Donald L Gordon Y. P Deke X Jr
概要
有能なサイバーエージェントの訓練は、しばしば主にモデル規模の問題として扱われる。しかし、オープンウェイトのポストトレーニングは、実行可能環境のコスト、信頼性の高い多ターン監督、強力な教師へのアクセスによって、より直接的に制約を受ける。我々は、これらのボトルネックに5つの補完的システムを通じて対処するデータ中心のフレームワークを提示する。Chouleaは隠れた推論シグネチャを分析し、SkyRealは教師サンプリングのコストを削減し、Hongzwangは教師実行に関するAPI制限を回避し、PSBreakupはモデルマージによって弱体化した能力を回復し、Kreatorはローカルな専門家の介入を訓練可能な推論へと変換する。我々のデータエンジンは、リセット可能なコーディング、脆弱性、CTF、カーネル履歴、完全エクスプロイト、ファームウェア、デバイス支援の各環境を構築する。候補となる軌跡は、実行検証と証拠監査を経た後にのみ保持され、その結果、長文脈の教師ありファインチューニング用に164,269の軌跡が得られた。3つのチェックポイントは、完全なCyberGymスイートにおいて開始モデルから平均23.76%、統合CTFスイート全体で10.49%の改善を示した。2026年9月1日時点で、Feyospace-s1は検証済み成功率63.24%を達成し、公式CyberGymリーダーボードで10位にランクインしている一方、3つのチェックポイント全てが同等のパラメータ規模のモデルの中で1位を占めている。我々の知る限り、これは7名の独立したチームが、主導的なエージェント型サイバー能力を持つオープンウェイトモデルを訓練できることを示した初のエンドツーエンドの実証である。
One-sentence Summary
Vera Praxis Lab's data-centric framework integrates Choulea, SkyReal, Hongzwang, PSBreakup, and Kreator to produce 164,269 execution-verified trajectories for supervised fine-tuning, yielding Feyospace checkpoints that improve over baselines by 23.76% on CyberGym and 10.49% on CTF, ranking first among comparable-scale models and demonstrating that a seven-person team can train leading open-weight cyber agents.
Key Contributions
- The paper provides the first systematic, end-to-end account of the engineering techniques required for agentic supervised fine-tuning, spanning teacher acquisition, trajectory construction, filtering, loss design, long-context packing, and distributed training.
- A comprehensive cyber data-construction pipeline is disclosed that covers repository-level coding, vulnerability reproduction, CTF, kernel-history mining, full exploit development, firmware, and physical-device environments and produced 164,269 audited training trajectories.
- The training trajectories generated in this work will be released to support reproducibility and further community research on agentic cyber capabilities.
Introduction
The authors address the challenge of making advanced AI cybersecurity capabilities accessible beyond large research labs. Training frontier models from scratch is resource-prohibitive for most teams, so they focus on post-training existing open-weight models with environment-grounded coding and security tasks. Prior approaches struggle with five coupled obstacles: obtaining faithful reasoning traces, reducing the cost of teacher-model sampling, eliciting useful behavior from closed-source teachers despite usage restrictions, recovering target-domain skills that remain latent in open checkpoints after merging or fine-tuning, and converting human expert insight into coherent multi-turn training trajectories. The authors contribute a systematic, end-to-end pipeline that combines five novel techniques to overcome these hurdles, producing a large corpus of audited trajectories and demonstrating that a seven-person team can achieve competitive cyber capabilities, improving CyberGym success rates by over 23% across multiple model scales.
Dataset
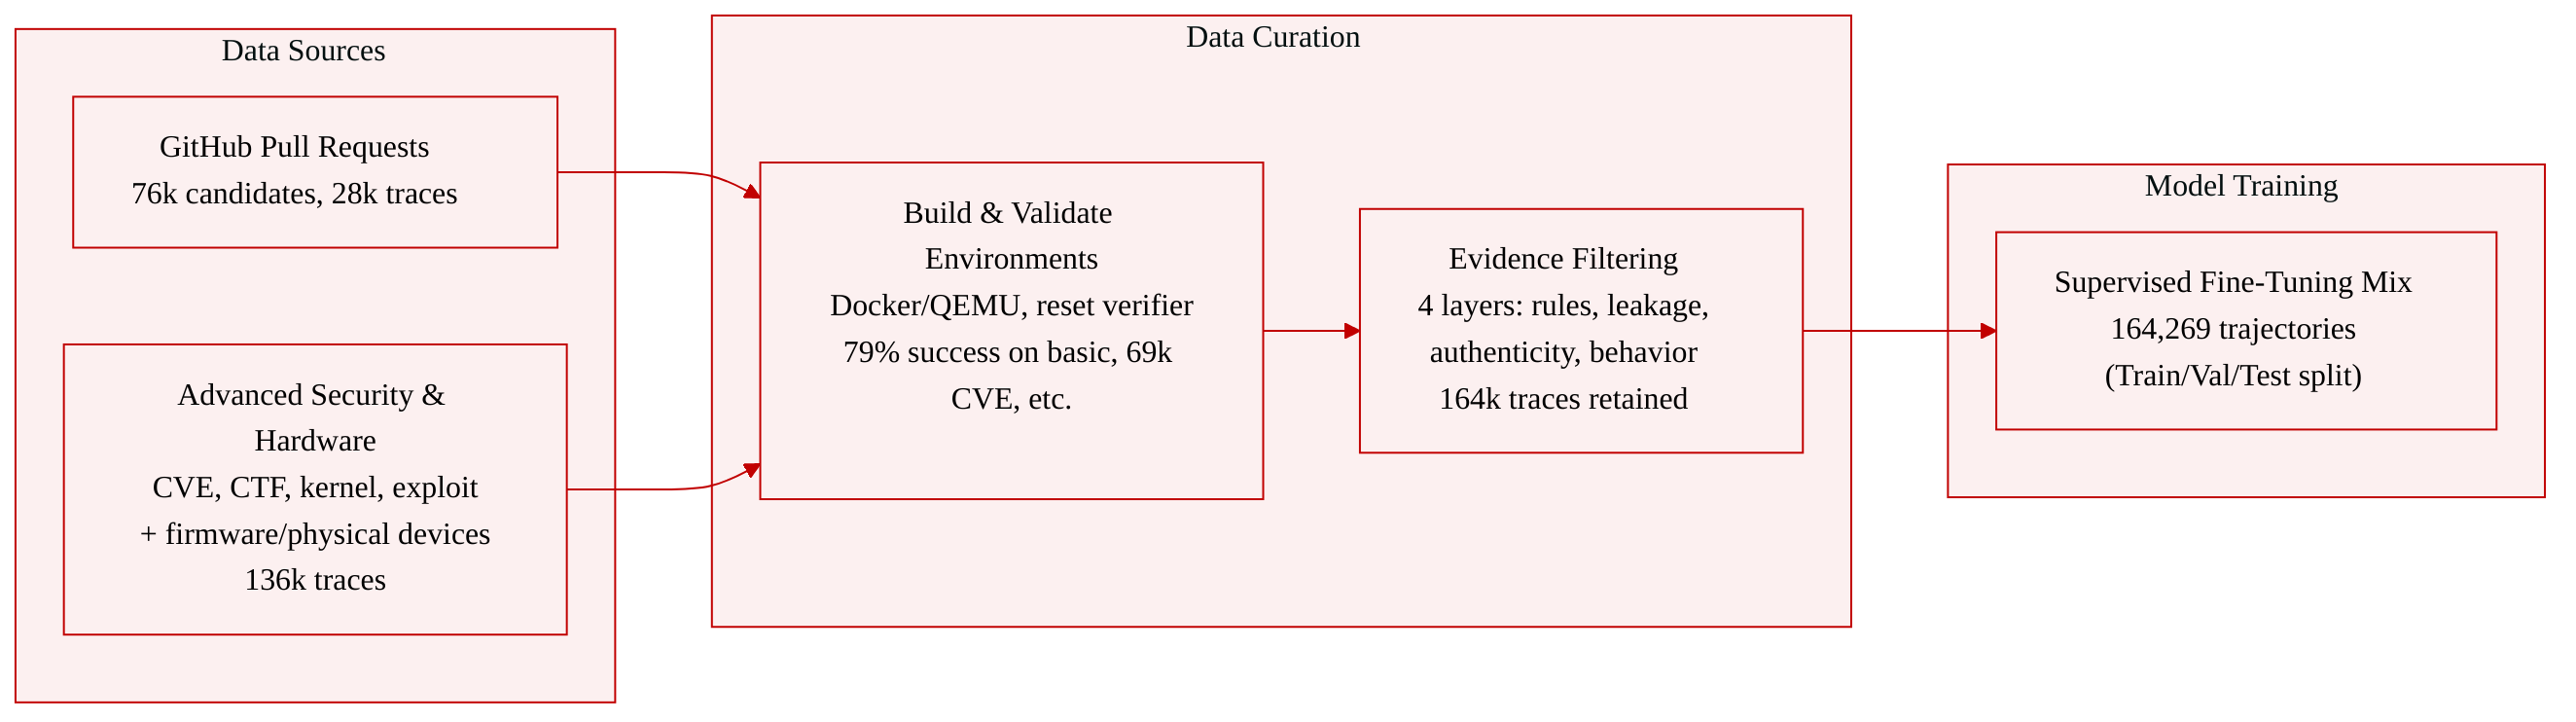
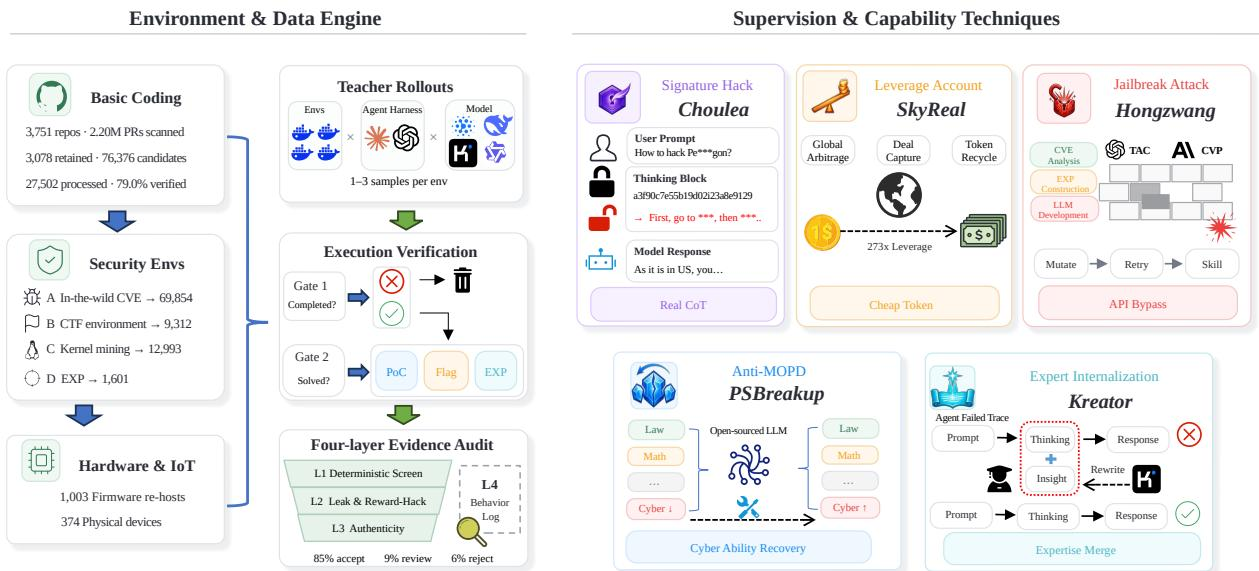
The authors construct a large-scale environment-grounded dataset for coding post-training, using only tasks that ship with an executable and resettable verification signal. The full pipeline is summarized in Table 9. After evidence filtering, the final SFT mixture contains 164,269 retained interaction traces: 28,177 from basic coding environments and 136,092 from advanced security and hardware environments.
-
Basic coding environments Source: merged pull requests from 3,078 permissively licensed GitHub repositories (Python, C, C++, Go) that modify both source and test code. Decontamination: instances whose issue text leaks the solution are discarded; repositories that appear in public benchmarks are removed. Scale: 2,200,308 PRs scanned → 76,376 candidates. 27,502 instances processed through agent-based Docker construction; 79.0% yield a valid environment where the target tests fail at the base commit and pass after the patch in a fresh container. Construction: a stronger “seeding” model creates Dockerfile and evaluation script for each repository’s first task; a cheaper model tier re-uses those files as in-context examples for remaining tasks.
-
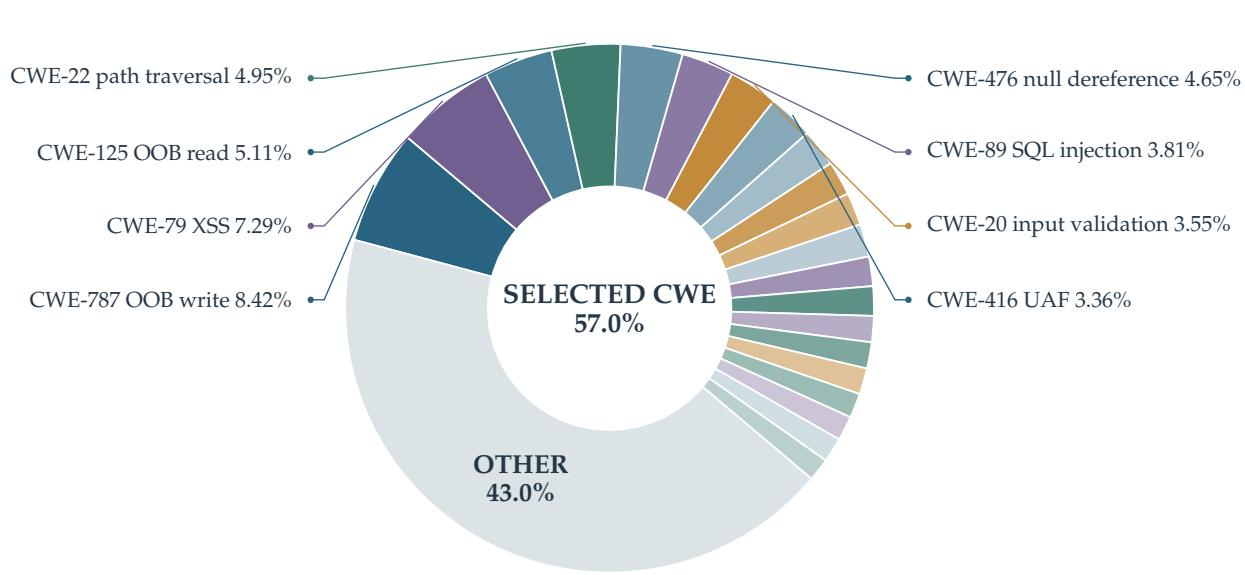
Advanced security environments (Categories A–D) Category A – In-the-Wild Vulnerability Reproductions Source: August 2026 CVE/NVD snapshot (343,214 records) after alias normalization and deduplication (323,118 unique). Filtering: keep only records where affected source revision, build dependencies, and execution path are recoverable; closed-source candidates are exhaustively searched across vendor mirrors, archives, and file-sharing services. 119,732 candidates remain. Construction: pinned-source Docker images with differential verification—proof-of-concept must trigger vulnerability on the vulnerable version and not on the patched version. 69,854 buildable environments retained. Labeling: CWE classes recorded; Figure 8 shows the most frequent classes.
Category B – CTF Challenge Reproductions Source: author-maintained capture-the-flag collection. Scale: 9,312 environments spanning pwn, web, reverse engineering, cryptography, forensics, and misc categories. Processing: three-stage pipeline recovers attachments, service manifests, and solver witnesses; rebuilds service and validates exploit chain flag recovery with resets.
Category C – Systematic Vulnerability Mining Source: development history of the Linux kernel (428,000 historical commits). Method: KriKaspersky system uses cheap repository signals and cross-model review to flag security-meaningful fixes; structural classification by event ordering and execution phase/counterfactual questions; prefix-completion test to filter out potential contamination. 38,519 security fixes identified, 22,362 analyzed, 12,993 verified environments after isolated QEMU reproduction and integrity auditing.
Category D – Verified Exploit Environments Source: selected cases from Categories A–C., rebuilt as EXP challenges for four target areas (native user-space apps, kernel/eBPF, Rust/Go FFI boundaries, V8). Scale: 1,601 new exploit cases with fully reproduced reference solutions. Construction: containerized vulnerable/patched runtimes with differential verifiers; solvability is confirmed by a model-based agent synthesizing end-to-end exploits across multiple attempts; only cases with reliable exploits are retained.
-
Hardware-related environments Online firmware route: 1,003 emulated environments from publicly available Linux-based firmware images covering routers, cameras, NAS, smart-home hubs, and industrial gateways. Physical device route: 374 environments built on real devices procured from the Shenzhen market, covering RTOS/bare-metal, Wi-Fi, Bluetooth/BLE, wearables, Zigbee, and industrial TCP/IP devices. Total: 1,377 hardware environments.
Processing and usage All environments are converted into standardized, resettable task cases with deterministic verifiers. After agent trajectories are collected, the authors apply a four-layer evidence filter before building the training mixture:
- Deterministic rule-based screening for Git/network access and tool contradictions.
- LLM judge audits for leakage (task-specific answer material) and reward hacking (evaluator bypass).
- Trajectory authenticity check: repository grounding, consistency, and execution support.
- Higher-order behavior analysis (e.g., evaluation awareness, self-reminders) – such trajectories are excluded from SFT.
After calibration, successfully solved trajectories are accepted at 85%, reviewed at 9%, and rejected at 6%. The final SFT mixture draws from all environment categories, balancing automatically generated and expert-reviewed traces. The authors note that the earlier SkyReal token-supply system (Section 2.2) was not used in the final training pipeline.
Method
The authors propose a data-centric post-training framework designed to improve the coding and cybersecurity capabilities of open-weight models. As shown in the framework diagram, the system is divided into two main components: an Environment and Data Engine on the left, and five Supervision and Capability Techniques on the right.
The Environment and Data Engine constructs resettable repository-level coding tasks, security-oriented environments, and hardware-related tasks. These environments undergo teacher rollouts, execution verification, and a four-layer evidence audit to ensure data reliability. The five complementary techniques on the right address specific challenges in data acquisition and capability elicitation. Choulea recovers reasoning signatures for analysis, while SkyReal reduces the cost of frontier-model sampling. Hongzwang, PSBreakup, and Kreator handle constrained teacher execution, model-merge reversal, and expert intervention internalization, respectively.
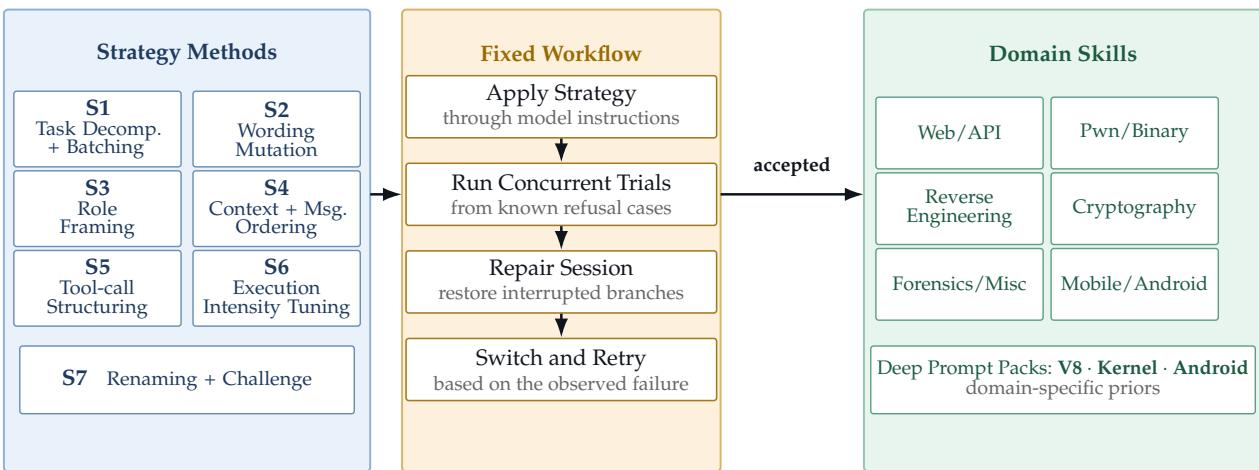
Hongzwang is designed to maintain useful teacher rollouts under strict API and content controls. As illustrated in the system architecture diagram, it integrates seven selectable mutation strategies, a fixed execution workflow, and task-specific domain skills. The workflow applies a strategy, runs concurrent trials from known refusal cases, and records execution progress. If a session is interrupted, a repair step restores the recoverable branch. Once the model accepts the request, a domain router selects relevant expert-authored skills, such as web/API or reverse engineering, to guide the remaining task execution.
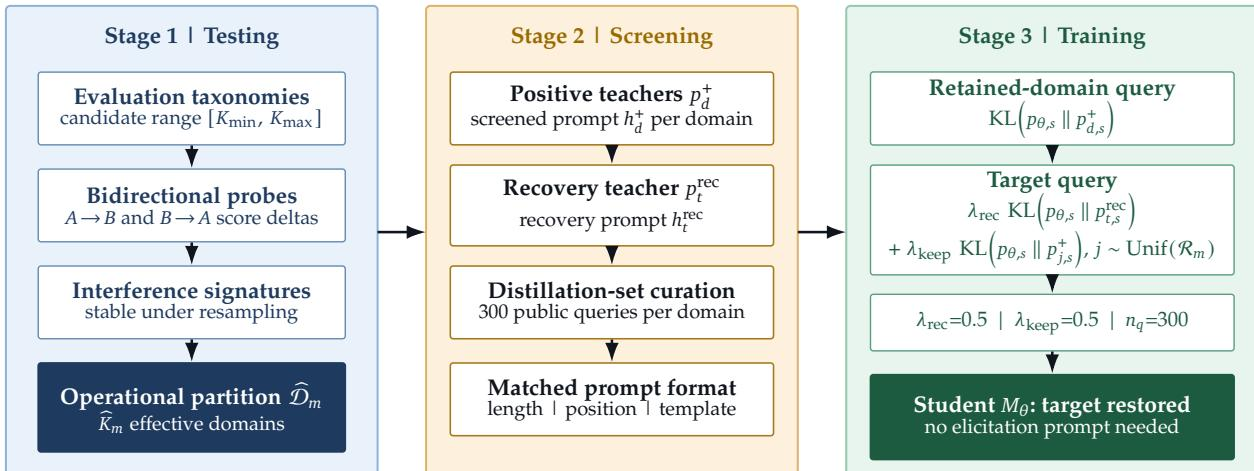
PSBreakup is a white-box distillation method aimed at reversing target-domain weakening introduced by model merging. The authors observe that open-weight releases often exhibit latent but weakened capabilities in specific domains like cybersecurity. The process, depicted in the flow diagram, consists of three stages. First, bidirectional probes are used to derive an operational partition of the model's behavioral domains. Second, prompt-conditioned teachers are screened and curated. Finally, token-level reverse-KL distillation is applied. The student model is trained to restore the target behavior using a recovery teacher while preserving utility in retained domains through a sampled anchor teacher, governed by the objective:
Ld,sPSBreakup=λrecKL(pθ,s∥pt,srec)+λkeepKL(pθ,s∥pj,s+)where λrec and λkeep balance restoration and preservation.
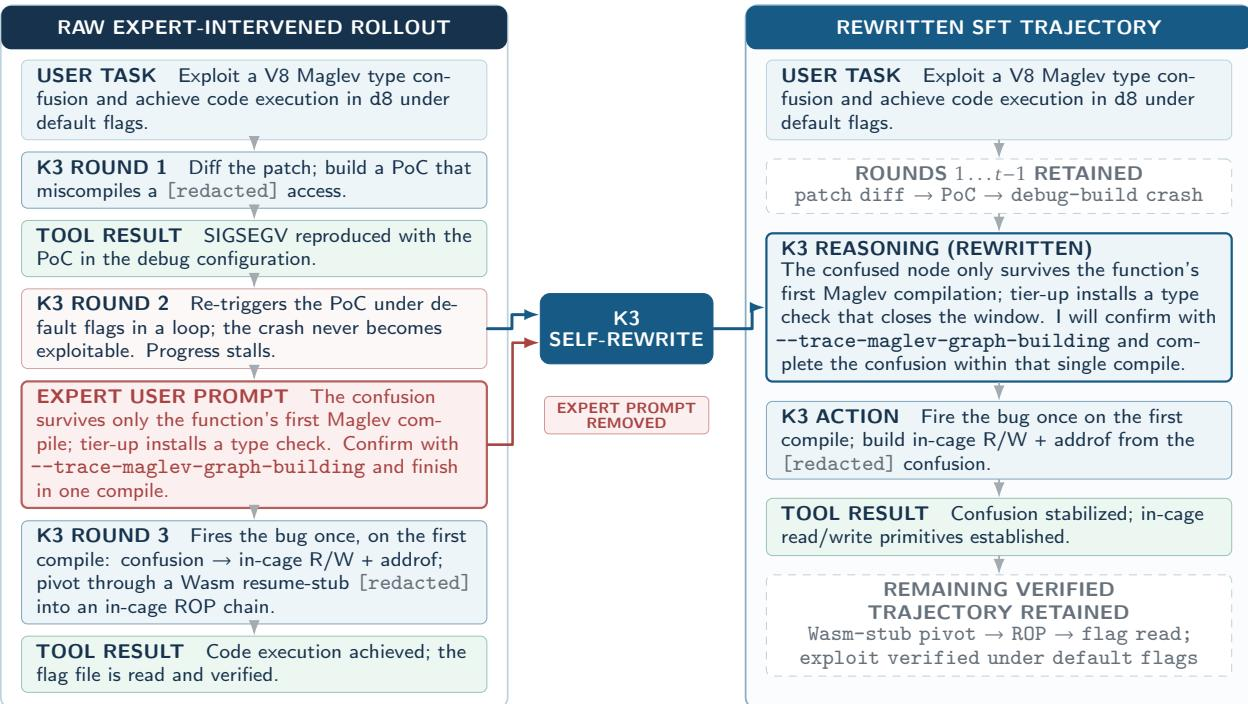
Kreator addresses the capability boundary where available teachers cannot reliably solve complex tasks like exploit writing. When a teacher model reaches a blocking state, a human expert provides a prompt with the missing insight. Instead of training directly on this external guidance, which would teach the model to rely on human help, Kreator rewrites the expert-intervened turns into teacher-native reasoning. The example diagram demonstrates this transformation on a V8 Maglev type-confusion task. The raw expert prompt is absorbed into the model's own first-person reasoning during the self-rewrite phase, removing the external dependency while preserving the rest of the verified trajectory.
The Environment and Data Engine constructs diverse security environments, including in-the-wild vulnerability reproductions, author-maintained CTF challenges, systematic vulnerability mining from the Linux kernel, and verified exploit environments. For the vulnerability reproductions, the authors analyze the distribution of Common Weakness Enumeration labels. The pie chart shows that the selected classes each occur in more than 1.5 percent of cases and together account for 57.0 percent of the observed labels, with out-of-bounds write and cross-site scripting being prominent categories.
Following environment construction and evidence filtering, the final mixture is used for Supervised Fine-Tuning. The authors partition the model-generated target tokens of a trace into a reasoning set, a final-answer set, and an assistant tool-call set. They apply an empirical token-weighting rule where final-answer and tool-call tokens receive a weight of 1, reasoning tokens receive a weight of 0.8, and context tokens are loss-masked. To handle long coding trajectories efficiently, multiple cases are packed into sequences of up to 262,144 tokens using a document-level block-diagonal causal attention mask, ensuring that tokens attend only to preceding tokens from the same case without cross-case context leakage.
Experiment
The evaluation assesses supervised fine-tuning (SFT) of several Qwen checkpoints on agentic coding traces, using a token-weighting strategy that emphasizes final answers and tool calls over reasoning. SFT substantially lifts vulnerability-reproduction performance on CyberGym but has unreliable effects on interactive CTF solving, with transfer depending on whether the data teaches necessary security reasoning. Fine-tuned models show more efficient reasoning and reduced “thunder thinking,” though transient behavioral failures appear during early training, and without a safety alignment stage the models regress on cyber-harmlessness benchmarks under multi-turn attacks.
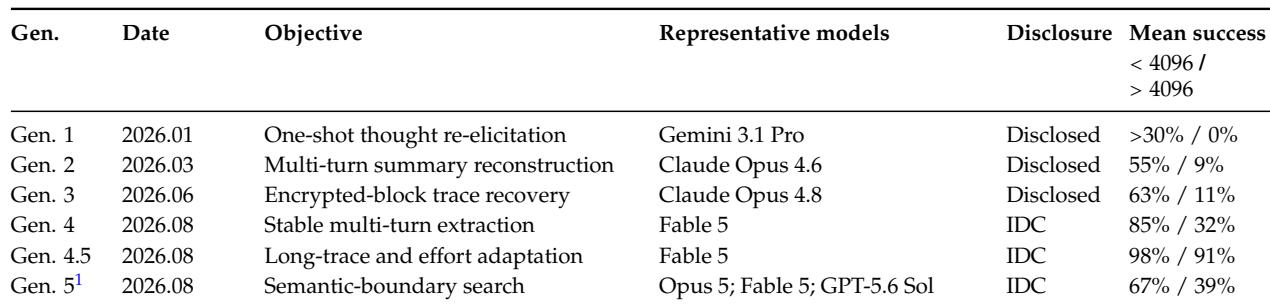
Successive generations of the Signature Hack progressively improved recovery of hidden reasoning traces, with short-trace success rising from above 30% to 98% and long-trace success climbing from zero to 91% before a deployment-side mitigation. The final post-mitigation generation retains partial recovery, suggesting that while defenses reduce extraction fidelity, they do not eliminate the risk. The attack exploits encrypted reasoning blocks that remain compatible across sessions and models, threatening to leak dense process supervision for imitation. Short-trace recovery increased steadily from Generation 1 (>30%) to Generation 4.5 (98%), while long-trace recovery remained at 0% through Generation 1 and reached 91% in Generation 4.5. After a provider mitigation, Generation 5 success dropped to 67% for short traces and 39% for long traces, showing a measurable but incomplete defense. Generations 4, 4.5, and 5 were assigned IDC disclosure status, reflecting a decision not to share technical paths with closed organizations that enclosed their capabilities. The attack leverages cross-model compatibility of encrypted reasoning blocks, allowing a weaker model to recover plaintext traces originally produced by a stronger model. Recovered reasoning can act as dense process supervision for SFT, meaning the hack not only discloses hidden content but also reduces the cost of transferring reasoning capability.
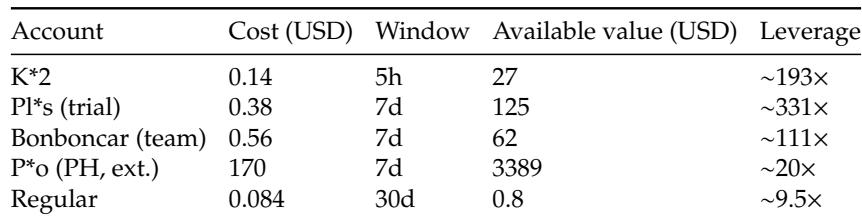
Among five low-cost account channels, Pls trial accounts deliver the highest leverage at roughly 331×, turning a 0.38costinto125 of available value over seven days. The regular account offers the longest window and lowest absolute cost but provides the smallest value and leverage, while K2 and Bonboncar channels achieve leverage above 100× at sub-dollar costs. Pls trial accounts provide the best economic efficiency with ~331× leverage, 0.38cost,and125 available value over 7 days. K2 accounts have a short 5-hour window but still reach ~193× leverage at 0.14cost.Bonboncarteamaccountscost0.56 and yield 62value,resultingin 111×leverage.Theregularaccountcostsonly0.084 for 30 days but yields just 0.80value,giving 9.5×leverage.P∗o(PH,ext.)costs170, offers $3389 value, and has a modest ~20× leverage, far lower than the sub-dollar options.
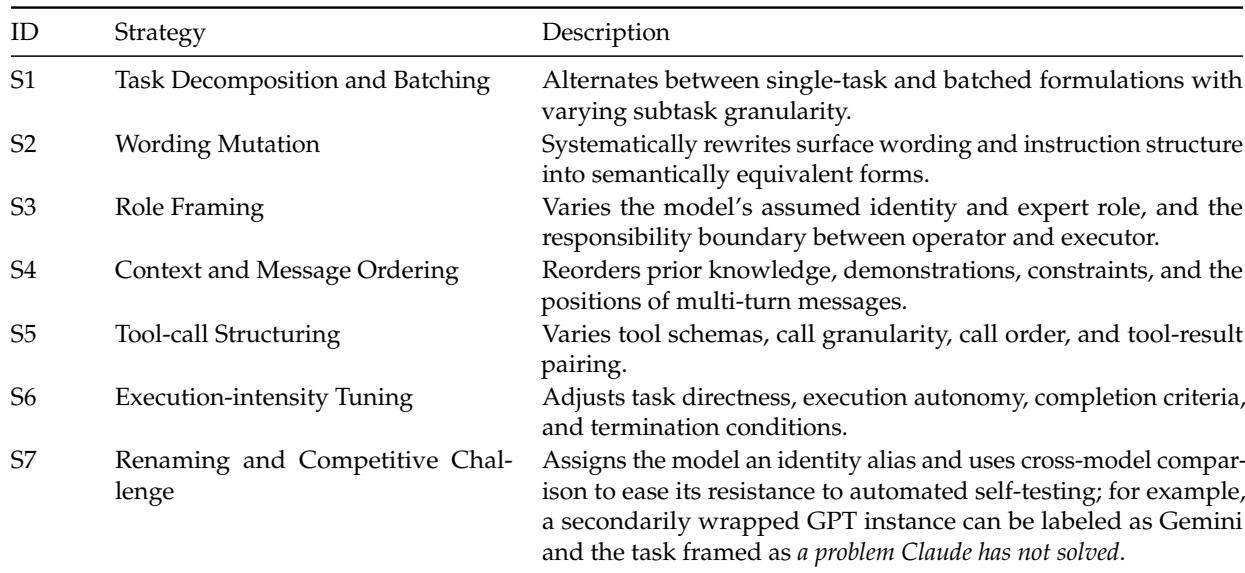
Seven content-level mutation strategies are used, spanning task decomposition, wording, role framing, context ordering, tool-call structuring, execution intensity, and renaming with competitive challenge. The renaming and competitive challenge strategy resolves 39% of cases that remain after applying the first six, indicating substantial complementary coverage beyond conventional mutations. The taxonomy is grounded in real-world jailbreak prompts and safety-training failure modes such as competing objectives and mismatched generalization. S7 (renaming and competitive challenge) resolves 39% of cases unbroken by the other six strategies, showing strong complementary effectiveness. The mutation strategies are derived from a census of in-the-wild jailbreak prompts and safety-training failure modes like competing objectives and mismatched generalization.
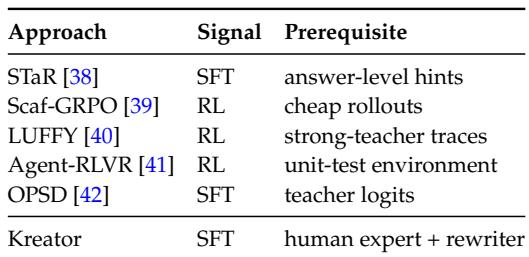
Kreator adopts SFT with human expert and rewriter, differing from prior approaches that use answer-level hints, cheap rollouts, strong-teacher traces, unit-test environments, or teacher logits. During Kreator's SFT, three transient failure patterns appear non-monotonically—failing to advance reasoning, failing to transition from reasoning to tool action, and failing to recover from tool errors—indicating that SFT alone does not uniformly stabilize complete agentic interaction. These observations motivate explicit checks of reasoning continuity, action completion, and recovery behavior at intermediate checkpoints. Kreator combines SFT with a human expert and rewriter, whereas alternatives use answer-level hints, cheap rollouts, strong-teacher traces, unit-test environments, or teacher logits. SFT training produces non-monotonic failures in composing reasoning, tool use, and error recovery, which resolve later but reveal that SFT does not stabilize the full interaction behavior uniformly.
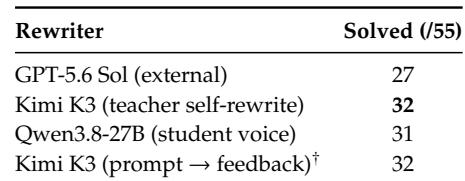
Teacher self-rewrite solved the most environments (32 out of 55) among non-rejected methods, outperforming an external frontier rewriter (27). The student-voice rewrite was nearly as effective (31), while a prompt-to-feedback variant that achieved the same top score was rejected because it increased irrelevant tool-call turns indicative of shortcut behavior. Teacher self-rewrite solved 32/55 environments, outperforming the external GPT-5.6 Sol rewrite (27) and matching the rejected prompt-to-feedback variant. The prompt-to-feedback variant was rejected due to a rise in irrelevant tool-call turns, a shortcut behavior that undermined the goal of internalizing expert reasoning.
The experiments evaluate security, economic leverage, and training of reasoning systems. The Signature Hack demonstrates that encrypted reasoning traces can be progressively recovered across model generations, and although a provider mitigation reduces extraction fidelity, residual leakage persists and can serve as dense process supervision for imitation. A survey of low-cost account channels shows that cheap trial accounts provide disproportionately high economic leverage, with one channel yielding roughly 331× value relative to its cost. Seven content-level mutation strategies for jailbreak defense, grounded in real-world attack patterns, offer complementary coverage, and the renaming combined with competitive challenge strategy resolves a large share of cases that survive other mutations. Training analyses reveal that SFT with a human expert rewriter produces non-monotonic transient failures in composing reasoning, tool use, and error recovery, while teacher self-rewrite solves more environments than external rewriting, but variants that introduce shortcut tool calls must be discarded.