Command Palette
Search for a command to run...
AGIに向けたデータサイエンスとテクノロジー 第I部:階層型データ管理
AGIに向けたデータサイエンスとテクノロジー 第I部:階層型データ管理
概要
人工知能の発展は、データ駆動型学習パラダイムの進化として捉えることができ、データの編成と利用における連続的なシフトが、モデルの能力向上を絶えず牽引してきた。目覚ましい進歩にもかかわらず、現在の大規模言語モデル(LLM)研究は、データ規模の一方向的な拡大に大きく依存するパラダイムに支配されており、データの入手可能性、取得コスト、学習効率の面でますますボトルネックに直面している。本研究では、汎用人工知能(AGI)の発展は、モデルがデータ管理を積極的に導き、高品質なデータがモデルの能力を増幅するという、データとモデルの共進化の新たな段階に入っていると論じる。このビジョンを実装するために、異種の学習目的とコスト制約にわたってLLMの学習ライフサイクル全体をサポートするように設計された、階層型データ管理フレームワークを提案する。具体的には、未整理の生リソースから組織化され検証可能な知識に至るまでのL0–L4階層型データ管理フレームワークを導入する。重要なことに、LLMは品質スコアリングやコンテンツ編集などのデータ管理プロセスで完全に活用され、データを階層間で洗練させる。各階層は、明確なデータ特性、管理戦略、学習上の役割によって特徴付けられ、事前学習、中間学習、アライメントを含むLLMの学習段階全体にデータを戦略的に割り当てることを可能にする。このフレームワークは、データ品質、取得コスト、限界的な学習便益のバランスを明示的に取り、スケーラブルで持続可能なデータ管理への体系的なアプローチを提供する。我々は、数学とウェブデータに関する実証研究を通じて提案フレームワークの有効性を検証し、そこで階層型データセットが生コーパスから構築され、複数の学習フェーズで使用される。実験結果は、階層を意識したデータ利用が学習効率とモデル性能を大幅に向上させることを示している。さらなる研究を促進するために、我々は階層型データセットと処理ツールをコミュニティに公開する。
One-sentence Summary
Researchers from Tsinghua University, ModelBest Inc., Beijing Institute of Technology, and South China Agricultural University propose an L0–L4 tiered data management framework for AGI development, in which LLMs actively refine data across tiers to balance quality, acquisition cost, and marginal training benefit, and their empirical studies on math and web data demonstrate that tier-aware data utilization significantly improves training efficiency and model performance.
Key Contributions
- Introduces an L0–L4 tiered data management framework that structures data from raw uncurated resources to organized and verifiable knowledge, with each tier defined by distinct data properties, management strategies, and training roles across pre-training, mid-training, and alignment.
- Operationalizes a data-model co-evolution perspective by using LLMs for data quality scoring and content editing, enabling tier-aware allocation that balances data quality, acquisition cost, and marginal training benefit.
- Empirical studies on math and web data demonstrate that tier-aware data utilization improves training efficiency and model performance, and the tiered datasets and processing tools are released to the community.
Introduction
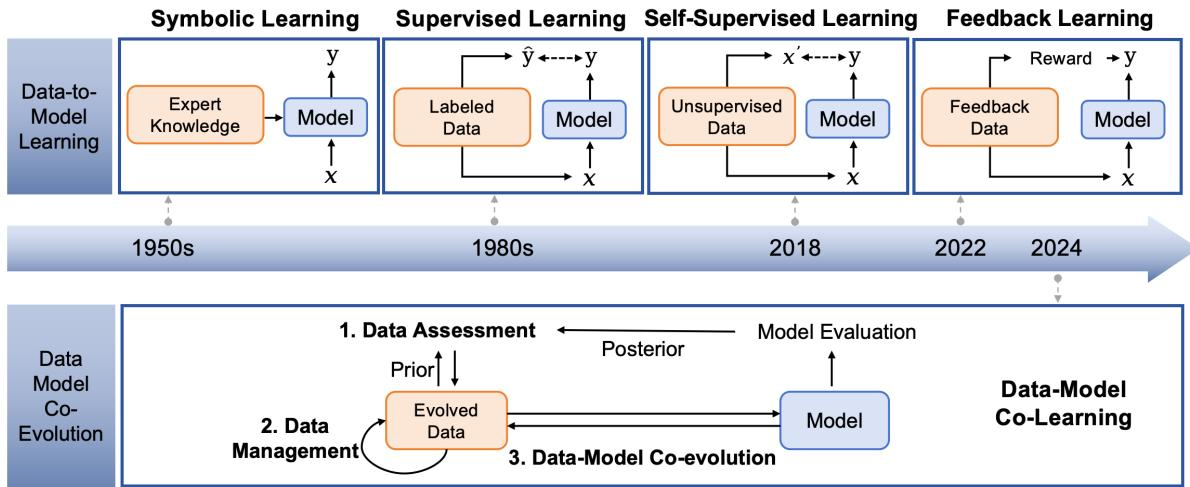
The authors trace the evolution of AI through four data-driven paradigms, from symbolic learning to feedback-driven reinforcement learning, and argue that the current focus on scaling data volume is hitting fundamental limits. Prior work in data processing, such as filtering and selection, addresses isolated tasks but fails to meet the systematic demands of the full LLM training lifecycle, where different stages require distinct data quality, quantity, and distribution. To address this, the authors propose a data-model co-evolution perspective and introduce an L0-L4 tiered data management framework that structures data from raw resources to organized, verifiable knowledge. Their empirical studies across web, math, and code domains show that higher-tier data improves performance and that tier-aware training strategies, which introduce higher-quality data in later phases, prevent saturation and outperform mixed-training approaches, establishing granular quality control as a core component for AGI development.
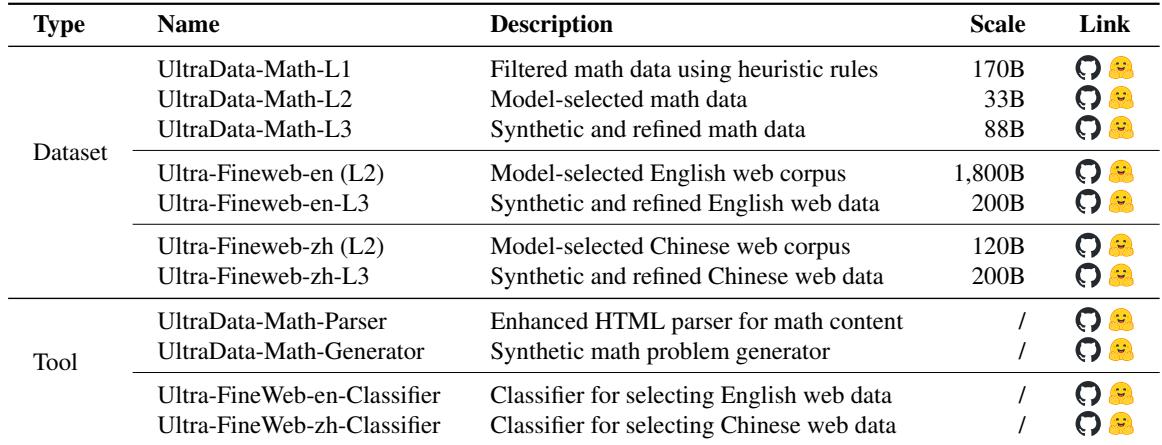
Dataset
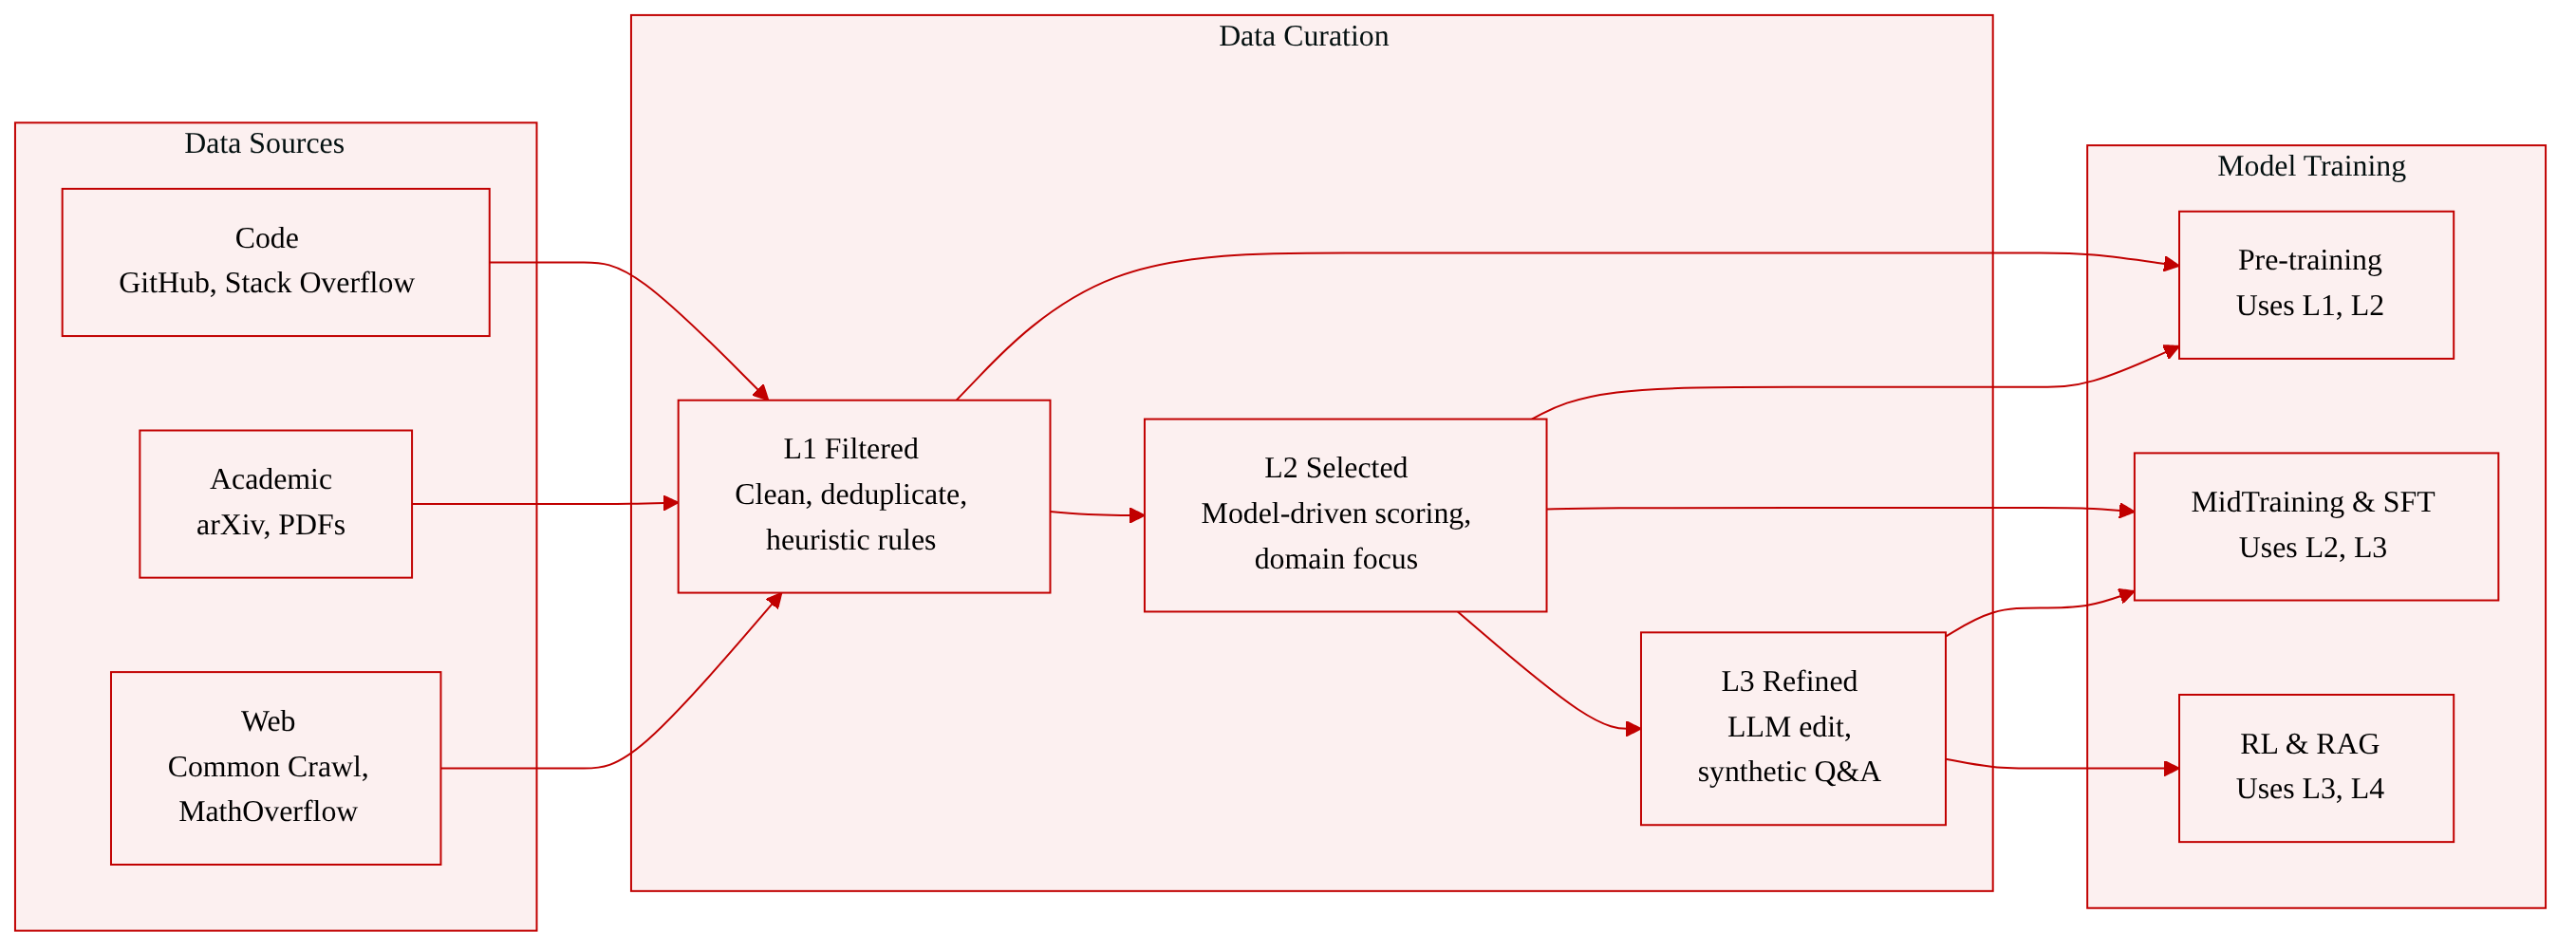
The authors introduce a tiered data management framework that organizes datasets into five levels, from raw archival data to highly structured knowledge assets. Each level applies progressively more sophisticated processing to improve data quality and usability for model training.
Dataset Composition and Sources
- The framework starts with L0 raw data, which is a broad collection of heterogeneous sources including general web content (news, blogs, social media), entertainment media, scholarly literature, source code repositories, and multimodal assets such as audio, video, and imagery.
- Key sources at this level include Common Crawl (the largest open-source web crawl, with over 30 billion pages across 15 years), arXiv (LaTeX and PDF preprint papers), GitHub (code histories and version records), and Stack Overflow (programming Q&A).
- Data acquisition relies on web crawling, batch downloading, and format parsing. Tools such as MinerU-HTML and Resiliparse handle HTML extraction, while MinerU, olmOCR, and Nougat parse PDF documents.
Key Details for Each Subset
- L0 raw data is stored in native or minimally converted formats. It has low information density and high noise, so it is not used directly for training. It serves as an archival reserve for traceability and secondary processing.
- L1 filtered data is produced through basic cleaning operations: URL filtering, text extraction, language identification, heuristic rule filtering, and global deduplication. Two representative datasets illustrate this level.
- FineWeb starts from Common Crawl, uses Trafilatura for text extraction (which outperforms WET files), applies URL blacklists from RefinedWeb, fastText language classification, and quality filters to reach about 36 trillion tokens. It then applies independent snapshot deduplication (5-gram, 112 hash functions, 14 buckets, 75% similarity target) across 96 snapshots, yielding about 20 trillion tokens. Heuristic filters (line-ending punctuation ratio, duplicated line character ratio, short line ratio) remove about 22% of tokens. The final dataset contains 15 trillion tokens.
- UltraData-Math-L1 applies a suite of cleaning operators for mathematical content, including format repair mappers (removing invisible characters, consolidating line breaks, stripping navigation bars) and content filters (discarding short articles without punctuation and documents with abnormal text lengths).
- L2 selected data uses model-driven selection to increase information density. Two examples are provided.
- Ultra-FineWeb trains a lightweight fastText classifier using high-quality seed data identified through an efficient validation strategy with a weight-decay scheduler and two-stage annealing. It filters the FineWeb dataset and outperforms the L1 version.
- FineMath extracts text from Common Crawl WARC files, uses a classifier trained on Llama-3.1-70B-Instruct for initial scoring (3-point scale) to identify high-quality math domains, and expands the URL list to include OWM and InfiMM-WebMath. It re-extracts pages preserving LaTeX formatting, yielding 7.1B pages and 6.5T tokens. A second classification pass (5-point scale) filters for reasoning and educational content. It concludes with single-band MinHash LSH deduplication (10 hashes), fastText language classification (English only), and benchmark decontamination. This produces FineMath-4+ (10B tokens) and FineMath-3+ (34B tokens).
- L3 refined data applies editing and synthetic enhancement. Two approaches are described.
- UltraFineWeb-L3 uses LLMs to refine webpage text by removing non-content elements (sidebars, headers, footers, ads), correcting OCR errors, fixing code indentation, and addressing grammatical inconsistencies. Documents failing information density thresholds are discarded.
- UltraData-Math-L3 starts with cleaned seed documents standardized into LaTeX, then uses a multi-model ensemble to generate five instructional formats: difficulty-stratified Q&A pairs, multi-turn teacher-student dialogues, multi-style rewrites, knowledge-driven textbook modules, and persona-integrated synthesis. All outputs undergo filtering for LaTeX syntax errors and logical incompleteness.
- L4 organized data focuses on orchestration and fact verification. Examples include Wikidata (structured multilingual knowledge base) and UltraData-arXiv (scholarly literature with standardized formulas, citations, and experimental results).
How the Paper Uses the Data
- L0 data is archival and does not participate in model training.
- L1 data supports large-scale pre-training, providing foundational language understanding and general knowledge.
- L2 data is suitable for Decay and MidTraining stages, offering high information density and domain-specific quality.
- L3 data applies to MidTraining, supervised fine-tuning (SFT), and reinforcement learning (RL), enhancing logical reasoning, mathematical proficiency, and instruction following.
- L4 data serves downstream applications such as retrieval-augmented generation (RAG), providing a trusted knowledge index to reduce hallucinations.
Processing and Metadata Construction
- Cropping strategies are not explicitly mentioned, but the framework emphasizes extraction, filtering, deduplication, and synthesis at each level.
- Metadata construction appears at the L4 level, where data is organized into structured, searchable formats with verified facts and interconnections.
- The framework supports a progressive training strategy, allowing researchers to sample from the L1 pool for domain-specific needs or extract high-quality seeds from L2 to guide L3 synthesis.
Method
Tiered Data Management Framework
The authors propose a fine-grained, hierarchical data management framework centered on data quality and trustworthiness, addressing the limitations of existing approaches that indiscriminately mix data of varying quality during LLM training. The framework defines five distinct levels, L0 through L4, where each level represents a progressive increase in data purity at the cost of greater acquisition and computational overhead.
L0: Raw Data
The L0 level serves as the foundational archival reserve, containing data in its native format or after only minimal structural conversion. This layer encompasses heterogeneous sources including general web content, entertainment media, scholarly literature, source code repositories, and multimodal assets such as audio, video, and imagery. While L0 data offers extensive coverage, its low information density and high noise level render it unsuitable for direct model training.
Acquisition at this level relies on basic operations such as web crawling, batch downloading, and format parsing. For HTML content, tools like MinerU-HTML and Resiliparse handle efficient extraction, while PDF parsing is accomplished through systems such as MinerU, olmOCR, and Nougat. Representative L0 datasets include Common Crawl, which provides WARC, WAT, and WET formats at different granularities, along with vertical sources such as MathOverflow, arXiv, GitHub, and Stack Overflow. The management strategy at L0 focuses on full-scale storage and data integrity preservation, establishing a traceability foundation for subsequent levels.
L1: Filtered Data
The L1 level constitutes the basic data-cleaning layer, designed to eliminate obvious noise through low-cost engineering methods. Its technical pipeline comprises URL filtering, text extraction, language identification, heuristic rule filtering, and global deduplication. The authors illustrate L1 practices through two representative works.
FineWeb validates L1 strategies through empirical ablation experiments. Text extraction from WARC files using Trafilatura outperforms WET-based extraction. The pipeline applies URL blacklists from RefinedWeb, the fastText language classifier, and quality filtering rules, reducing the corpus to approximately 36 trillion tokens. Notably, FineWeb employs independent snapshot deduplication rather than global MinHash deduplication, since global deduplication increases the sampling rate of low-quality data in older snapshots. Custom heuristic filters include line-ending punctuation ratio filtering (threshold 0.12), duplicated line character ratio filtering (threshold 0.1), and short line ratio filtering (threshold 0.67), collectively removing about 22% of tokens.
UltraData-Math implements L1 management through a specialized suite of cleaning operators for mathematical content, organized into format repair mappers and content filters. Format repair mappers standardize text without altering record counts, removing invisible characters, consolidating excessive line breaks, and stripping interface noise. Content filters discard records failing basic usability standards, such as short articles lacking punctuation or documents with abnormal text lengths. L1 data supports large-scale pre-training, providing foundational capabilities for general knowledge comprehension and linguistic representation.
L2: Selected Data
The L2 level marks a paradigm shift from rule-based to model-driven data management. Selection at this level leverages domain-specific classifiers, semantic-level filtering, quality scoring, and data labeling to identify and retain high-value samples. The authors present two representative implementations.
Ultra-FineWeb introduces an efficient validation strategy based on a weight-decay scheduler and a two-stage annealing phase, significantly reducing GPU hours required for evaluating data subsets. This strategy enables rapid assessment of candidate data pools, from which high-quality samples are selected as seed data for a lightweight fastText classifier. Compared to LLM-based classifiers, fastText reduces inference overhead while maintaining selection quality. Filtering FineWeb with this method yields a dataset that significantly outperforms the L1-level FineWeb, validating the effectiveness of model-driven selection.
FineMath addresses the limitations of existing mathematical datasets through a multi-stage construction pipeline. The process begins with classifier-based scoring of Common Crawl WARC files to identify high-quality mathematical domains, followed by URL list expansion to include OWM and InfiMM-WebMath sources. After re-extraction preserving LaTeX formatting, a second classification pass filters for reasoning and educational content. The pipeline concludes with MinHash LSH deduplication, fastText language classification, and benchmark decontamination. The resulting FineMath-4+ achieves a 2x performance increase on GSM8K and a 6x increase on MATH compared to prior datasets.
L2 data achieves significant advancement in information density, professionalism, and task relevance, providing efficient training corpora for both foundational pre-training and continuous pre-training stages.
L3: Refined Data
The L3 level employs editing, restoration, and synthetic enhancement to eliminate semantic flaws and reinforce logical coherence. UltraFineWeb-L3 implements an editing refinement strategy that treats data processing as semantic distillation rather than simple filtering. LLMs refine webpage text by removing non-content elements such as sidebars, headers, and residual advertisements, correcting OCR errors, fixing broken code indentation, and addressing grammatical inconsistencies. Documents failing information density thresholds are discarded, and this filtering-plus-editing paradigm achieves secondary purification of data quality.
UltraData-Math-L3 implements a systematic synthesis pipeline to overcome the scarcity of web-mined mathematical data. The process begins with cleaning seed documents into unified LaTeX format, then employs a multi-model ensemble strategy to transform these seeds into five instructional formats: difficulty-stratified Q&A pairs following curriculum-aligned progression, multi-turn teacher-student dialogues across seven persona pairs, multi-style rewrites decoupling mathematical logic from presentation styles, knowledge-driven textbook modules extracting theorems for pedagogical explanations, and persona-integrated synthesis simulating professional educational materials. All synthetic outputs undergo rigorous filtering for LaTeX syntax errors and logical incompleteness.
L3 data supports critical stages including mid-training, supervised fine-tuning, and reinforcement learning, achieving creative value augmentation that breaks through the constraints of raw data distribution.
L4: Organized Data
The L4 level represents the most refined state within the framework, emphasizing unified orchestration and rigorous normalization to transform fragmented information into structured, reliable, searchable knowledge assets. Management at this level centers on two core operations: data orchestration, which unifies scattered data under coherent thematic frameworks, and fact verification, which cross-references entries with trusted sources to eliminate factual inconsistencies. Representative examples include Wikidata and UltraData-arXiv, where complex elements such as mathematical formulas, citations, and experimental results are standardized into interconnected formats. The structural rigor and credibility of L4 data make it indispensable for retrieval-augmented generation, providing robust defense against model hallucinations.
The hierarchical L0-L4 framework enables a progressive training strategy where models are matched with data resources of incrementally improving quality at different evolution stages. L0 serves as archival reserve, L1 supports large-scale pre-training, L2 suits decay and mid-training stages, L3 provides high-quality corpus for logical reasoning capability leaps across mid-training, SFT, and RL stages, and L4 constructs trustworthy knowledge indexes for downstream applications. This framework decouples the complex challenges of data management, transforming data quality from experience-based assessments into predictable engineering metrics and driving model capabilities toward deterministic advancement.
Experiment
The evaluation uses MiniCPM-1.2B models with three verification strategies (efficient, pre-training, and decay) to assess a tiered data management framework across English, Chinese, Math, and Code corpora. Results show consistent quality improvements from L1 to L3 across all domains, with the largest gains in Math (+7.06pp). A case study on UltraData-Math confirms that higher-tier math data yields transferable benefits to non-math benchmarks, enhancing general reasoning and code generation. A comparative training experiment demonstrates that tiered training (sequential L1 to L3 stages) outperforms mix training by 1.49pp overall, with sustained learning gains in later stages, validating the framework's effectiveness in aligning data quality with model learning demands.
The paper introduces a tiered data management framework with multiple open-source datasets and tools, organized into L1, L2, and L3 quality tiers. Experiments show that tiered training, which progressively introduces higher-quality data, outperforms mix training, especially in later stages, leading to more sustained performance gains. Tiered training achieves a higher overall average improvement (1.49pp) compared to mix training. In later training stages, tiered training improves by 3.31pp versus 1.91pp for mix training, showing a growth magnitude 1.7 times larger. The tiered approach avoids performance declines on tasks that favor breadth of knowledge, which are observed with mix training.
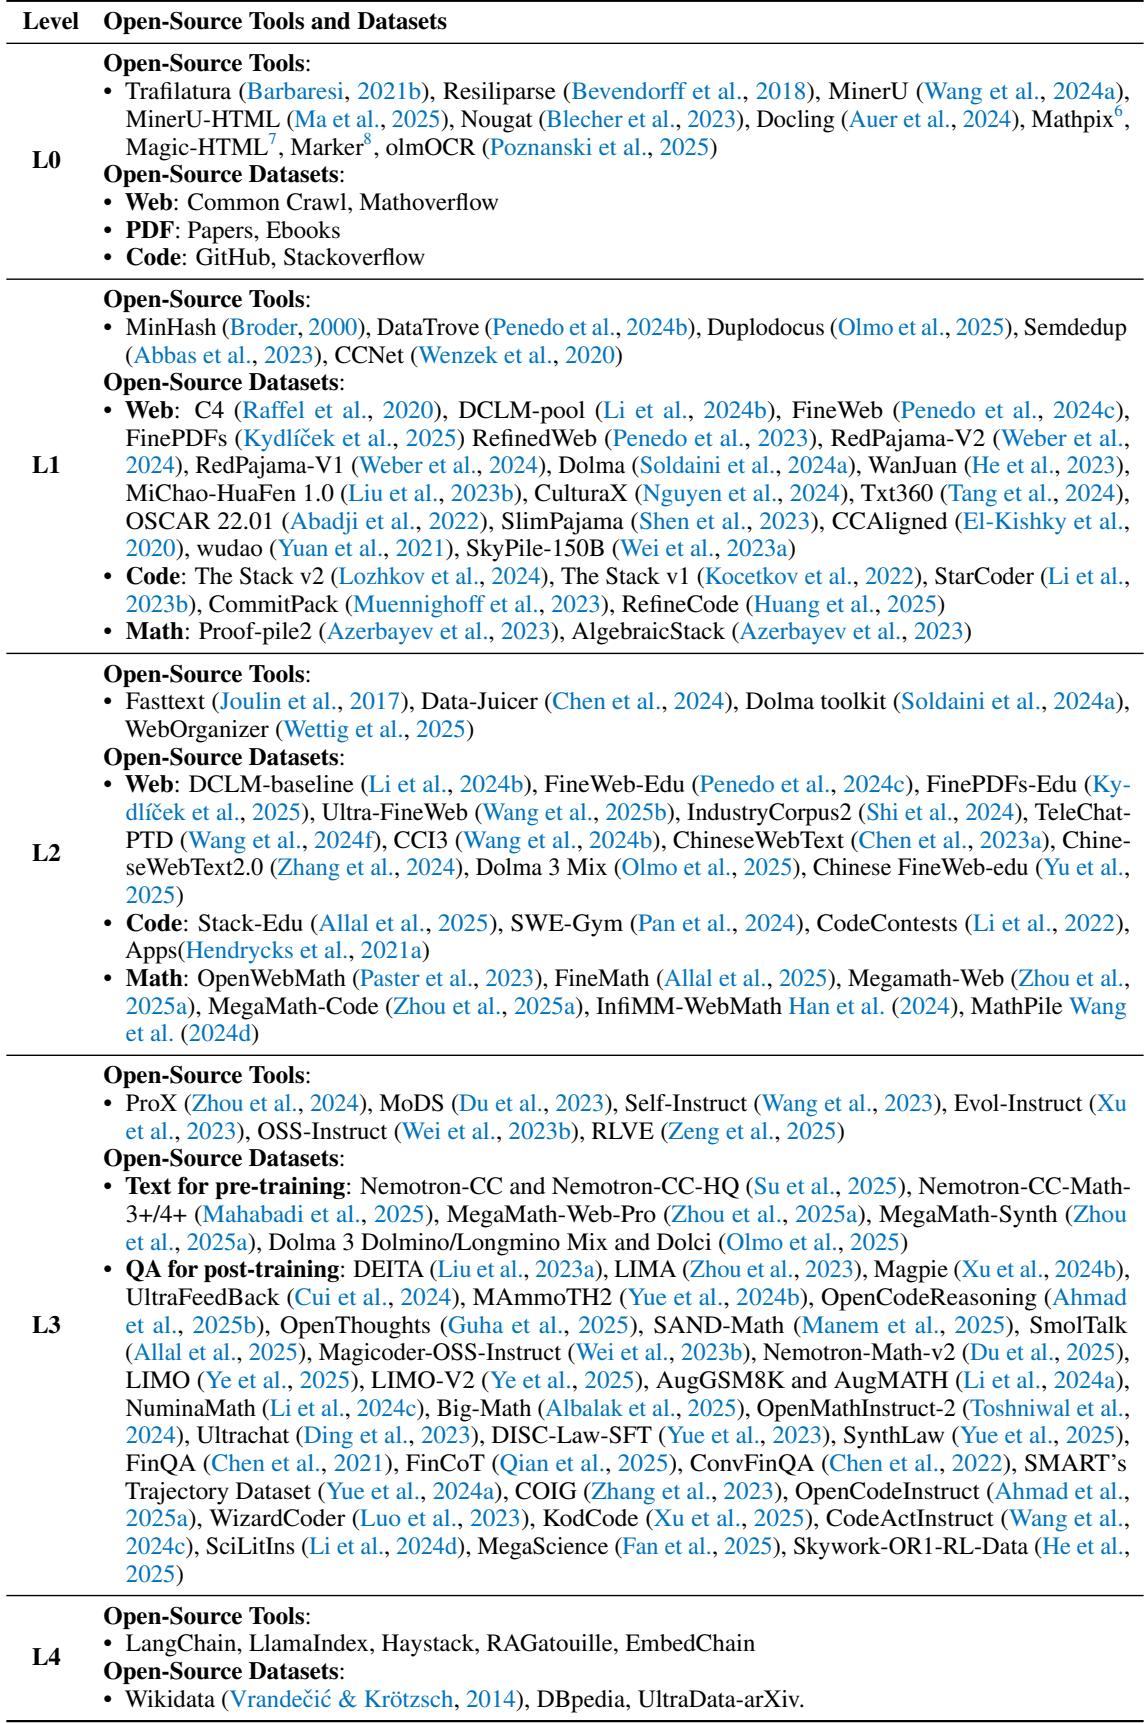
The table catalogs open-source tools and datasets mapped to a five-tier (L0-L4) data management framework, where each tier corresponds to increasing data quality and processing cost. The framework supports a staged training strategy that introduces progressively higher-quality data over time, yielding sustained performance gains compared to traditional mixed training. L0 tools focus on extraction from raw web, PDF, and code sources, while L1 tools emphasize deduplication and filtering on large-scale corpora. L2 introduces model-based selection and quality filtering, with datasets like FineWeb-Edu and DCLM-baseline, whereas L3 includes synthesis and instruction generation tools such as Self-Instruct and Evol-Instruct. L4 is dedicated to knowledge integration and retrieval, featuring tools like LangChain and LlamaIndex, and structured datasets like Wikidata and DBpedia. Tiered training, which progressively uses L1, L2, and L3 data, shows a larger late-stage performance increase than mixed training, with a growth magnitude about 1.7 times higher.
The MiniCPM-1.2B model uses a vocabulary of 73,448 tokens, a hidden dimension of 1,536, and 52 layers, with 24 query heads and 8 key/value heads. Training configurations include a sequence length of 4,096, weight decay of 0.1, and gradient clipping at 1.0, with batch sizes varying across verification stages. The model is trained using the Megatron-LM library and the MiniCPM3-4B tokenizer. The model has 1.25 billion non-embedding parameters, with a hidden dimension of 1,536 and a feedforward bottleneck dimension of 3,840. The architecture uses 24 query heads and 8 key/value heads, with an attention head dimension of 64. Training uses a sequence length of 4,096 and a global batch size of 512 for the efficient verification stage, while pre-train verification uses a larger global batch size of 2,048. The learning rate schedule varies by stage, with a cosine schedule for pre-train verification and an exponential decay for decay verification.

The tiered data management strategy, which progressively introduces L1, L2, and L3 filtered data across domains, outperforms a mixed training approach in final model performance and sustained learning gains. Early training shows similar progress for both strategies, but in later stages the tiered approach achieves a larger improvement (3.31pp) compared to mixed training (1.91pp), with an overall average advantage of 1.49pp. The advantage is attributed to aligning data quality levels with model learning demands at each training stage, reducing interference from low-quality data. Tiered training shows a later-stage performance gain of 3.31pp versus 1.91pp for mixed training. The tiered strategy improves overall average performance by 1.49pp over mixed training. Early training curves are similar for both strategies, but tiered training sustains growth after introducing L2 and L3 data. L1 data provides broad language coverage, L2 enhances high-density content learning, and L3 deepens reasoning and domain knowledge.
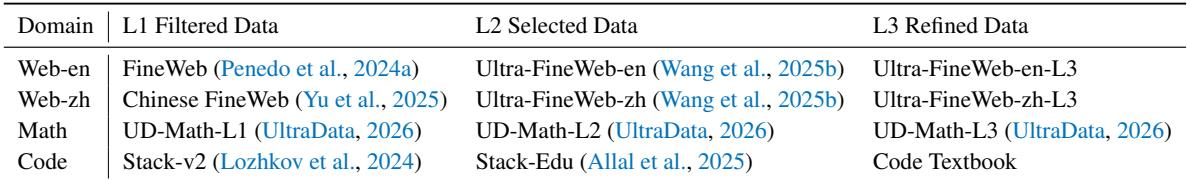
The tiered data management framework produces consistent quality improvements across all evaluated domains, with average benchmark scores rising from L1 to L3 in English web, Chinese web, math, and code tasks. The largest gains appear in math, while smaller but still positive gains are seen in code and language domains. The L3 > L2 > L1 performance hierarchy holds universally, validating the framework's effectiveness even under constrained training budgets. Average scores improve from L1 to L3 in every domain, with math showing the largest jump of about 7 percentage points. The strict performance ordering L3 > L2 > L1 is observed without exception across all four domains. A few common-sense reasoning tasks show slight decreases under tiered training, likely due to reliance on broader L1 data coverage.
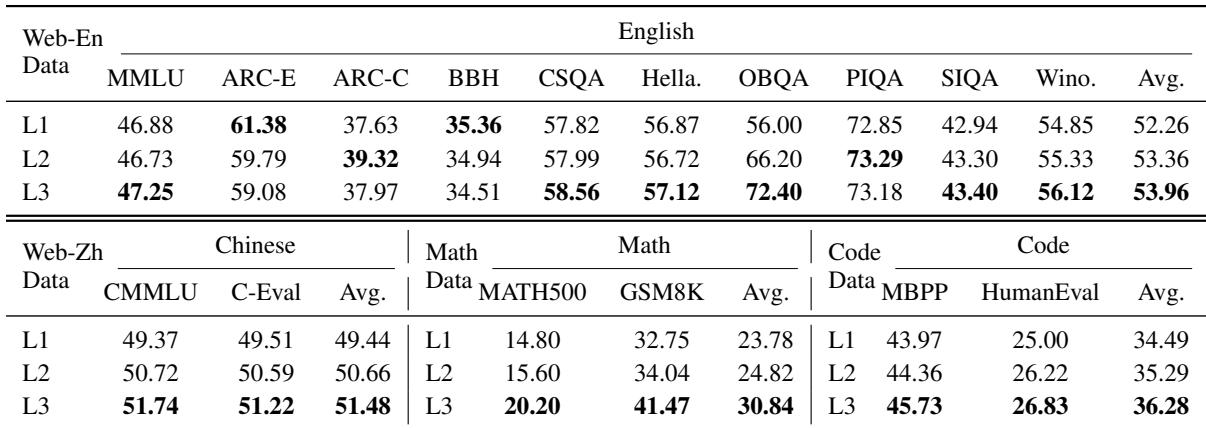
The experiments validate a tiered data management framework that progressively introduces higher-quality data (L1 to L3) during training. Compared to mixed training, tiered training yields higher overall average performance gains (1.49pp) and a larger late-stage improvement (3.31pp vs. 1.91pp), with a growth magnitude about 1.7 times larger, while avoiding declines on breadth-oriented tasks. The L3 > L2 > L1 performance hierarchy holds consistently across all evaluated domains, with the largest gains in math and smaller positive gains in code and language tasks, confirming the framework's effectiveness even under constrained training budgets.