Command Palette
Search for a command to run...
PROFBENCH:専門知識を要する多領域ルーブリックによる評価
PROFBENCH:専門知識を要する多領域ルーブリックによる評価
Zhilin Wang Jaehun Jung Ximing Lu Shizhe Diao Ellie Evans Jiaqi Zeng Pavlo Molchanov Yejin Choi Jan Kautz Yi Dong
ProfBench 専門ベンチマークデータセット
概要
大規模言語モデル(LLM)の進歩の評価は、しばしば応答の検証の難しさに制約され、数学、プログラミング、短文形式の質問応答といったタスクに評価が限定されることが多い。しかし、多くの実世界の応用では、専門文書の処理、情報の統合、ユーザーの問い合わせに対する包括的なレポートの生成におけるLLMの評価が必要とされる。我々は、物理学博士、化学博士、金融MBA、コンサルティングMBAの専門知識を持つ人間の専門家によって評価された、7000以上の応答・基準ペアからなるProfBenchを紹介する。我々は、自己増強バイアスを軽減し、評価コストを2〜3桁削減することで、より広いコミュニティにとって公正でアクセスしやすいものにする、堅牢で手頃なLLM-Judgeを構築する。我々の調査結果は、ProfBenchが最先端のLLMにとっても重大な課題を提起し、GPT-5-highのようなトップ性能モデルでも全体性能は65.9%にとどまることを明らかにしている。さらに、プロプライエタリモデルとオープンウェイトモデルの間の顕著な性能格差を特定し、複雑な専門領域タスクに対処する際の拡張思考の役割についての洞察を提供する。
One-sentence Summary
Researchers from NVIDIA introduce ProfBench, a benchmark of over 7,000 expert-evaluated rubric criteria across Physics PhD, Chemistry PhD, Finance MBA, and Consulting MBA domains, along with affordable LLM-Judges that cut evaluation costs by 2–3 orders of magnitude, revealing that top-performing models like GPT-5-high achieve only 65.9% overall performance.
Key Contributions
-
The paper introduces ProfBench, a rubric-guided benchmark spanning four professional domains (Physics PhD, Chemistry PhD, Finance MBA, and Consulting MBA) with over 7,000 expert-created response-criterion pairs, and shows that even the strongest model, GPT-5-high, reaches only 65.9% overall performance, demonstrating the benchmark's difficulty for state-of-the-art LLMs.
-
The work evaluates more than 40 models both as response generators and as LLM-Judges across these professional tasks, and analyzes performance trends related to open-weight versus proprietary models, reasoning versus instruct variants, and model scale.
-
The paper presents bias-mitigation methods that reduce self-enhancement bias in LLM-Judges to at most 1% across three providers and cut evaluation cost by 2 to 3 orders of magnitude (roughly $12 with the o3 model), making the benchmark practical and accessible to the broader community.
Introduction
Reinforcement Learning with Verified Rewards (RLVR) has proven effective for tasks where correctness is easy to check, such as competition math or code that passes unit tests, but it struggles to scale beyond domains with unique, unambiguous answers. Rubric-based grading, where complex problems are decomposed into explicit criteria a strong response must satisfy, offers a path toward evaluating open-ended, professionally meaningful tasks. Prior work in this direction either covers a narrow set of domains (health, machine learning) or suffers from flawed benchmarks: DeepResearch-Bench RACE includes many questions answerable by an educated generalist with basic web searches and relies on synthetically generated scoring criteria that were never validated by human experts, leading to measurable bias toward the model that produced both the criteria and reference answers. The authors introduce ProfBench to address these gaps. It is the first benchmark with expert-created rubrics spanning Chemistry, Physics, Consulting, and Finance, curated by incumbent professionals with PhD or MBA level expertise, and contains over 7,000 response-criterion pairs. The authors evaluate over 40 models on both answer generation and rubric-based judging, and they propose techniques to reduce LLM-judge provider bias and cut evaluation costs by 2 to 3 orders of magnitude, making the benchmark accessible and fairer than existing rubric frameworks.
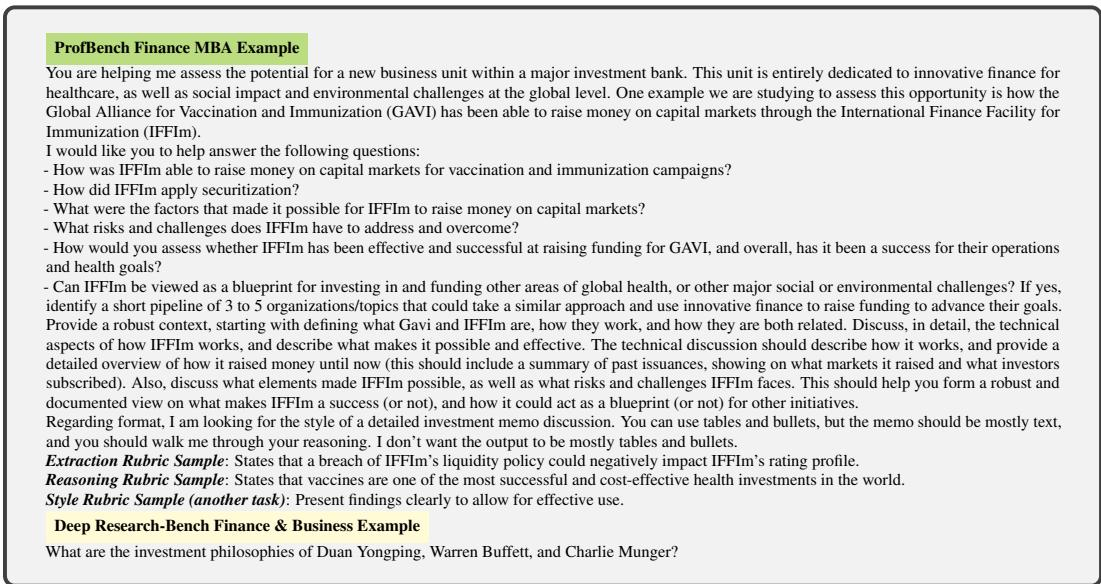
Dataset
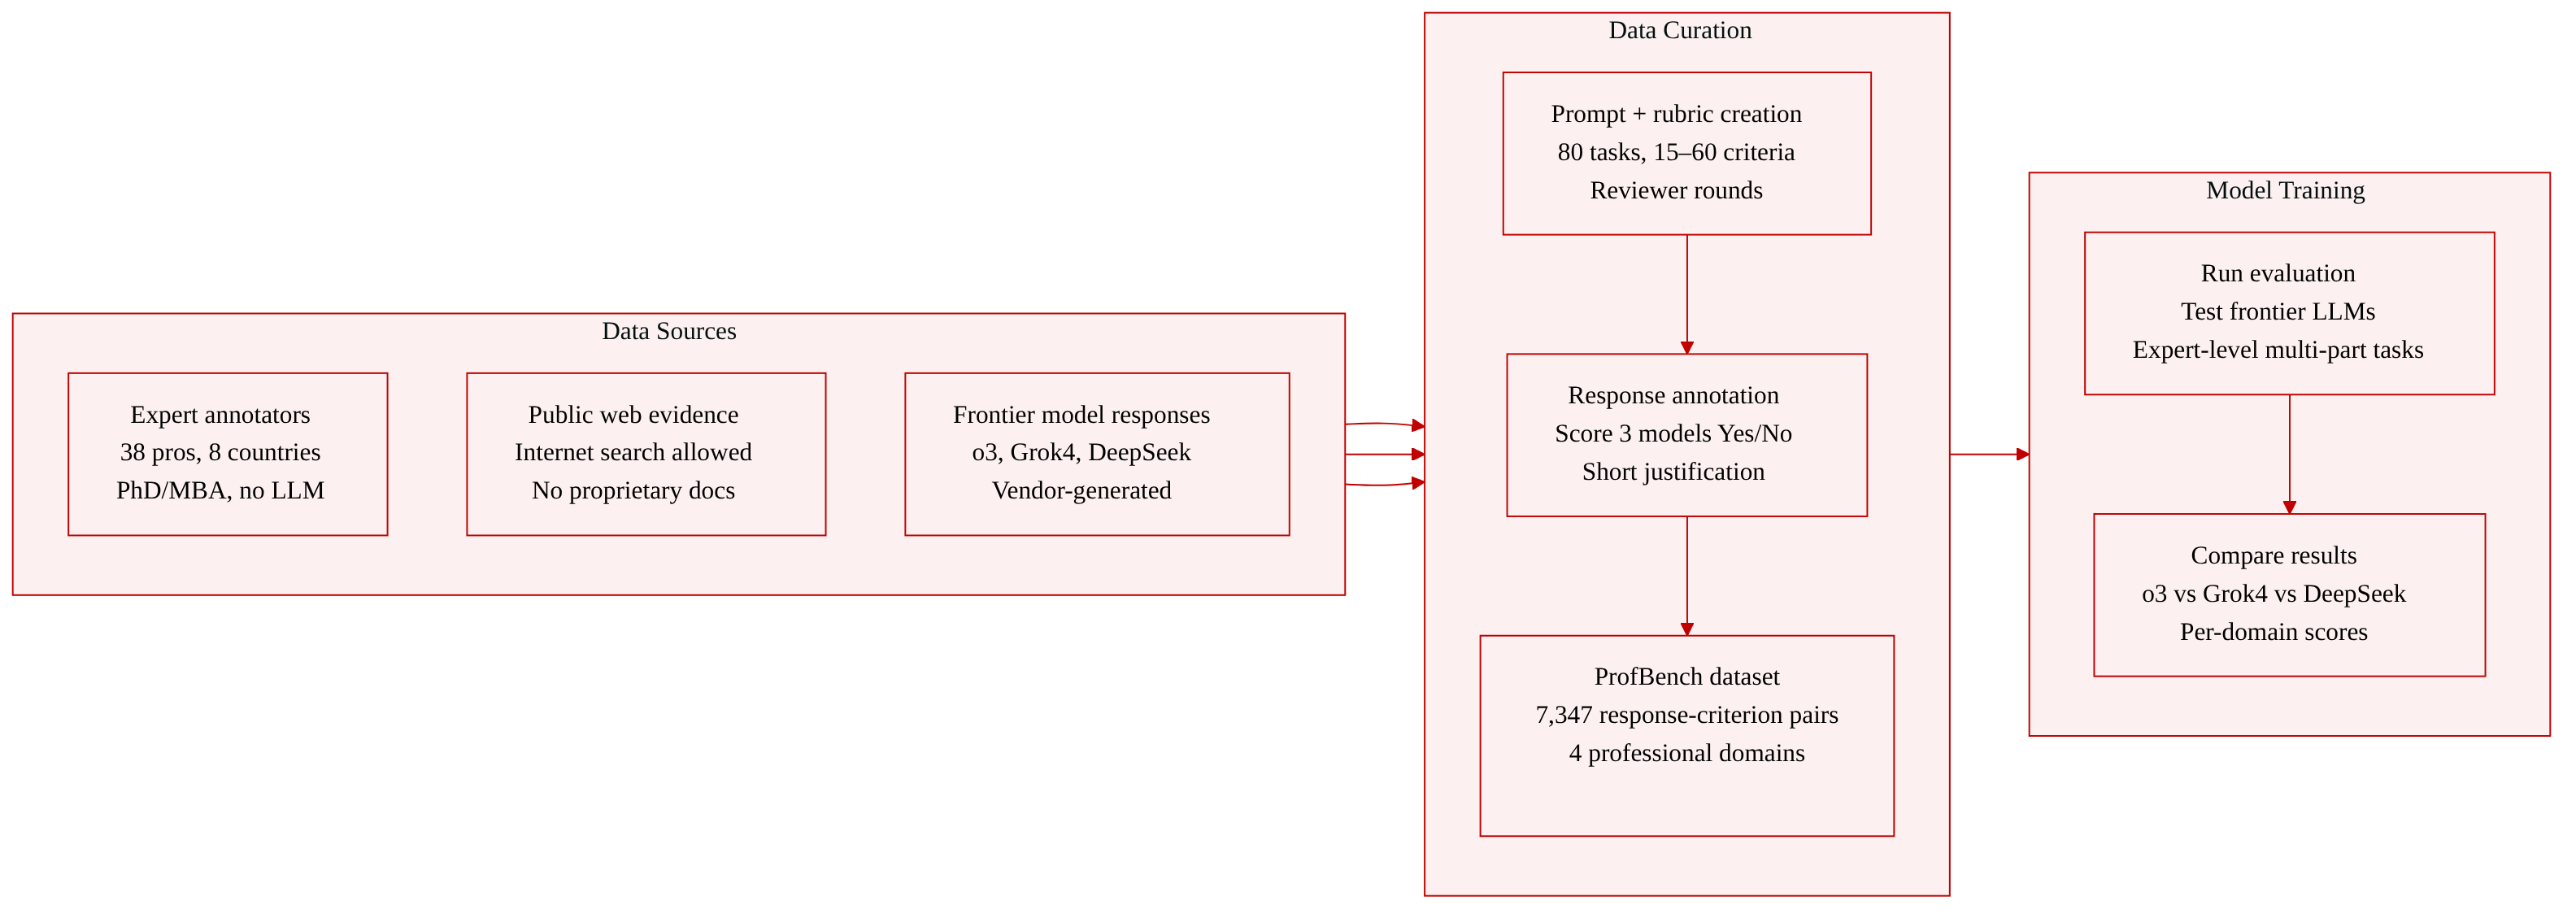
The authors introduce ProfBench, a benchmark dataset for professional domain expertise. Here is a breakdown of its composition, construction, and intended use.
Dataset overview and scale
- ProfBench contains 7,347 human-written response-criterion pairs across 80 distinct tasks.
- Tasks are evenly divided among 4 professional domains: Chemistry PhD, Physics PhD, Finance MBA, and Consulting MBA.
- This scale is comparable to existing benchmarks: PaperBench uses 8,316 pairs across 20 tasks, and HealthBench uses 8,053 pairs across hundreds of tasks. In contrast, DeepResearch-Bench has 100 tasks with only one reference response and no human-written rubric, averaging just 2.3 English tasks per domain.
- The authors note that rubric-based evaluation datasets tend to be small because each task requires significant time from expert annotators (for example, Physics PhD holders with industry experience), which is difficult to recruit and expensive.
Annotator recruitment and qualifications
- Annotators with PhD, MBA, or equivalent work experience were recruited and managed by a vendor.
- Before inclusion, annotators had to pass a test on their domain expertise and their understanding of the annotation task, including working under ambiguity and attention to detail.
- A total of 38 annotators from 8 countries contributed.
- Among annotators, 44.7% hold a PhD, 18.4% hold an MBA, and the rest hold related degrees (such as a Bachelor of Science in Finance or Bachelor of Commerce) along with relevant work experience.
- Annotators have an average of 5.24 years of experience following their highest degree.
- Each annotator spends about 10 to 20 hours per task, and is limited to contributing no more than 5 tasks to ensure prompt diversity.
- LLM use was disallowed at any stage of annotation.
- Annotators were paid well above local minimum wage, with hourly pay often exceeding full-time employment rates in these professional fields, to attract highly qualified contributors.
Prompt curation
- The goal was to create tasks that would be difficult for frontier LLMs as of July 2025 (for example, OpenAI o3, xAI Grok4, DeepSeek R1-0528).
- Prompts were designed as tasks an annotator might ask a junior colleague to help with, resulting in multi-page reports that often contain multiple related sub-questions.
- All prompts and expected responses were required to be in English and text-only.
- Annotators were allowed to use internet search to find supporting evidence, but proprietary documents not publicly available were disallowed.
- Annotators provided a brief rationale for each prompt to ensure purposeful creation.
Rubric creation
- For each task, annotators created 15 to 60 scoring criteria.
- Each criterion is independently usable to grade a response, and the full set collectively covers all aspects of response quality.
- Each criterion includes a description and a justification, the latter intended to encourage thoughtful creation.
- Annotators assigned an importance level and one or more criteria types to each criterion.
- Reviewers (with substantial domain expertise) provided overall feedback on the criterion set and made recommendations to keep or improve each criterion, with multiple back-and-forth rounds possible.
- Among annotator-written criteria, 41.4% were marked as needing improvement at various stages, reflecting the high quality standard enforced during review.
Response annotation and use
- The vendor generated responses using three models believed to perform best at the start of annotation: OpenAI o3, Grok4, and DeepSeek R1-0528, covering both proprietary and open-weight models.
- Annotators scored each of the three responses on each criterion using a simple Yes or No, accompanied by a brief justification.
- The resulting response-criterion pairs serve as the evaluation data for assessing model performance across the four professional domains. The dataset is used to test frontier LLMs on complex, expert-level tasks where multiple sub-questions and detailed reports are expected.
Method
Benchmarking Models as LLM-Judges
The authors formulate the judge task as a binary classification problem. For each evaluation criterion, the model receives the response and the criterion, then determines whether the response fulfills that criterion. This formulation closely mirrors a two-class natural language inference task, where the judge must decide between Entailment (criterion satisfied) and Contradiction (criterion not satisfied). Following the design of PaperBench, the original task prompt is withheld from the LLM-judge. The criteria are constructed to be evaluated independently of the prompt, and supplying the prompt could introduce irrelevant context that distracts the judge.
Benchmarking Models as Report-Generators
The report-generation task is formalized as follows: given a prompt alongside a set of grounding documents, the model must generate a response that addresses the prompt. This grounded formulation is inspired by how human professionals typically tackle real-world tasks, a design choice that distinguishes it from popular benchmarks such as HLE, GPQA, and MMLU-Pro, which do not provide grounding documents.
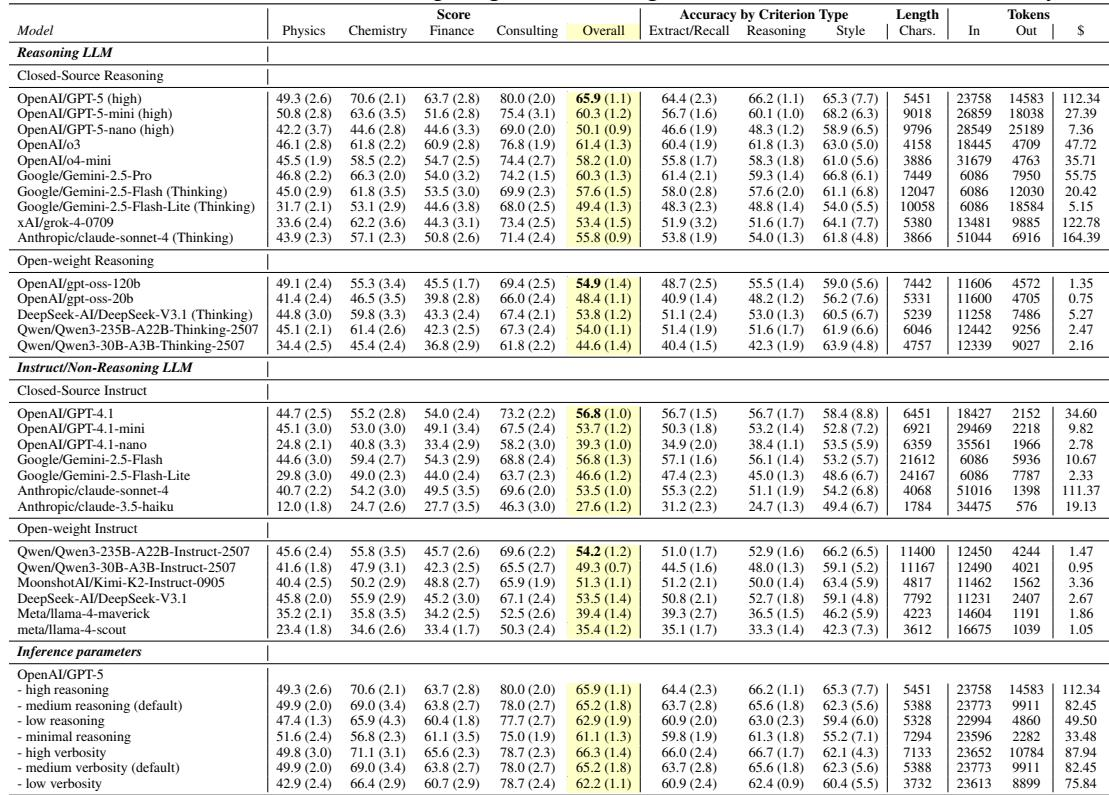
The generated reports are graded by the best-performing GPT-OSS-120B judge identified in the judge benchmark. This judge operates with high reasoning effort for Physics, Chemistry, and Style-related criteria, and low reasoning effort for all others. The final score is computed as the criteria-fulfillment rate, weighted by each criterion's importance level: 1 for additional, 2 for minor, 3 for major, and 4 for critical. Formally, the score is given by
score=∑cwc∑cwc⋅1[criterion c is fulfilled],where wc denotes the importance weight of criterion c. To validate this scoring schema, the authors compare judge-predicted performance against human-annotated performance for three models (o3, Grok4, and R1-0528). The schema yields only a 0.7% to 1.3% gap between the judge-predicted and human-annotated scores across the three models, confirming its reliability.
The inference setup for report generation mirrors the judge benchmark. Because the task expects long outputs, the authors generate up to 32,000 tokens for non-reasoning models, corresponding to the maximum sequence length of GPT-4.1, and up to 64,000 tokens for reasoning models, matching the limits of Claude 4 Sonnet and Gemini 2.5 Pro. To estimate performance variance, each generation is repeated 16 times, and the average alongside the standard deviation is reported.
Experiment
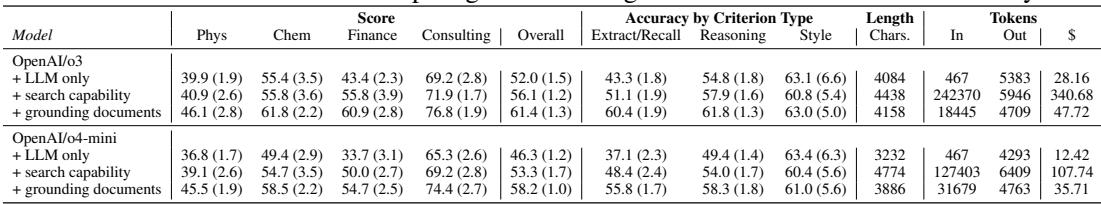
The experiments benchmark LLM judges on human-annotated criteria following a binary entailment-style task, measuring performance via Macro-F1 adjusted by a bias index, and then use the best performing open-weight judge (GPT-OSS-120B with domain-specific reasoning effort) to evaluate report generators. Results show proprietary models lead both tasks, but open-weight models are highly competitive at a fraction of the cost, while larger models and enabling reasoning generally improve performance only modestly. Response length has minimal impact on report quality beyond a threshold, and removing grounding documents severely degrades performance (9 to 12%), with web search recovering only part of the loss. The authors also demonstrate that adaptive sampling allocation across tasks can cut inference costs to 25% without compromising estimation robustness.
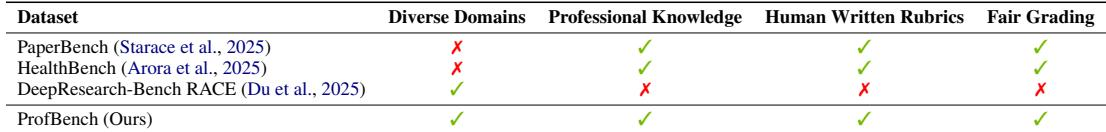
ProfBench uniquely satisfies all four evaluated aspects, including diverse domains, professional knowledge, human-written rubrics, and fair grading, whereas other benchmarks fall short on at least one. The benchmark is also cost-efficient, with inference costs far below comparable benchmarks, and can be further reduced without sacrificing robustness by adaptively allocating responses across tasks. Grounding documents are critical for performance, as removing them causes a significant drop, though web search can partially recover it. ProfBench is the only benchmark that covers diverse domains, professional knowledge, human-written rubrics, and fair grading, while others miss at least one aspect. Running ProfBench with 16 responses per task costs 48,versus300 for HealthBench and $8000 for PaperBench, and adaptive sampling can cut cost to 25% without harming robustness. Removing grounding documents reduces performance by 9.4 to 11.9%, with a particularly strong effect on information extraction tasks, and web search only partially recovers the loss.
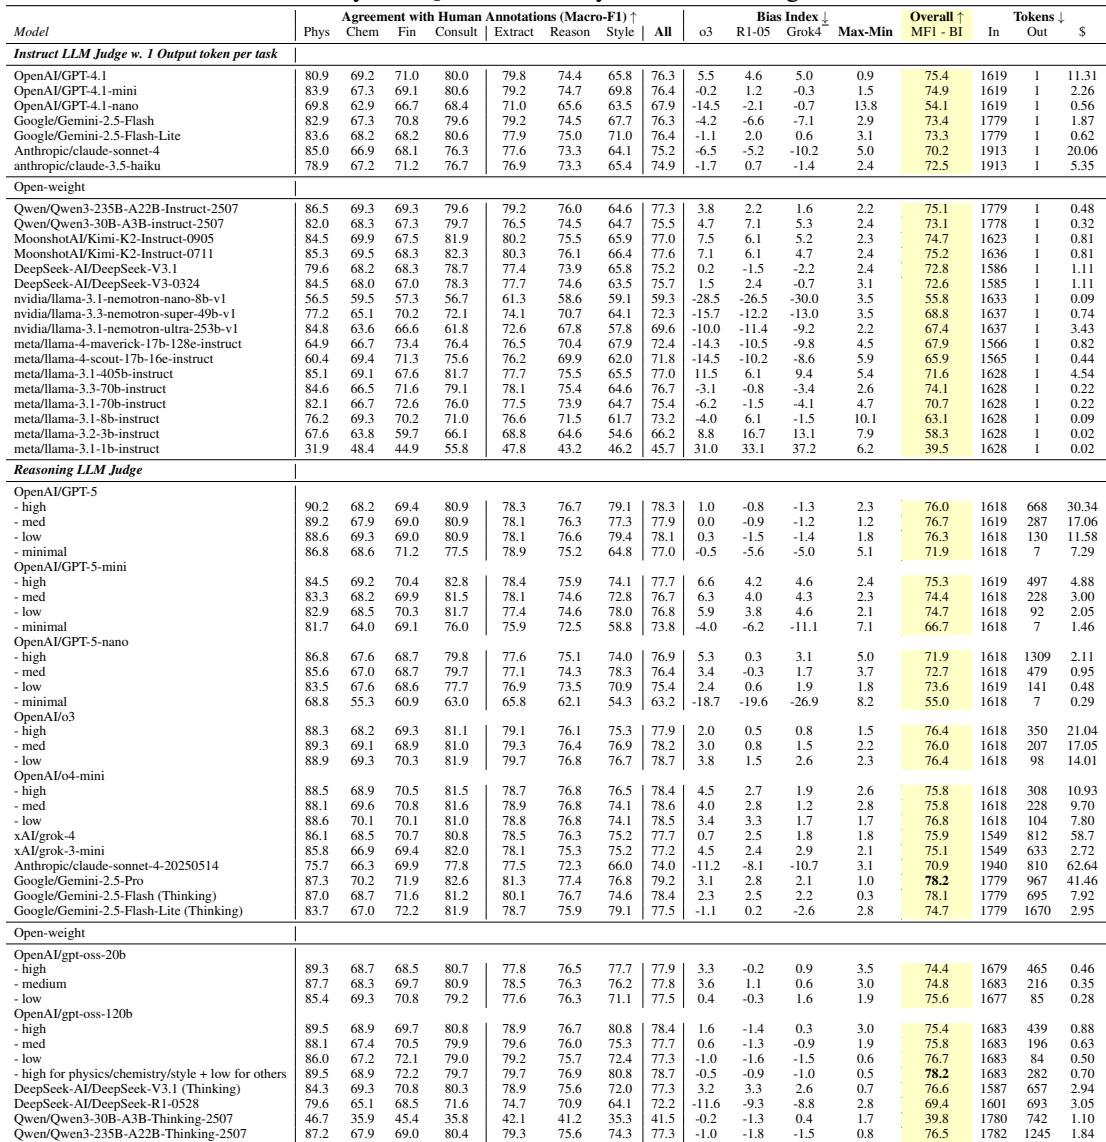
Proprietary LLM judges achieve the highest overall scores, but open-weight models come close at a fraction of the cost. Larger models generally improve performance, though gains plateau beyond a certain size and post-training improvements can matter more than scale. Enabling thinking often helps, but the benefit varies by model and reasoning effort level. Best proprietary judges reach 78.2% overall, but top open-weight models trail by only 0.2 to 1.5 percentage points while costing far less. Scaling within a model family yields diminishing returns after a threshold, with jumps from post-training upgrades sometimes exceeding those from adding parameters. Enabling thinking improves scores by 0.7 to 4.8 percentage points depending on model, while higher reasoning effort provides inconsistent gains across models. Bias index values vary widely, with some models showing negative bias (preferring model outputs) and others positive, affecting overall scores.
GPT-5 leads overall performance as a report-generator, though the benchmark proves more challenging than several popular reasoning benchmarks. Physics is the most difficult domain, while closed-source models generally outperform open-weight ones, with the largest gap in Finance. Larger models improve within families but with diminishing returns, and enabling reasoning modes yields only modest gains, suggesting that scaling alone is insufficient. GPT-5 achieves the highest overall score, yet the benchmark remains difficult relative to other established reasoning tasks. Physics is the most challenging domain, with notably lower scores than Chemistry, Finance, or Consulting. Closed-source models outperform open-weight models across most domains, with the largest performance gap in Finance. Within model families, larger models improve performance, but gains shrink as size increases, indicating diminishing returns. Enabling thinking or reasoning modes produces only small improvements for the same model, and sometimes thinking versions underperform their instruct counterparts.
Adding grounding documents to the LLM generator yields the highest scores across both models, while relying on web search alone partially recovers performance compared to LLM-only prompting. The o3 model consistently outperforms o4-mini under the same settings, and the largest gains from grounding appear in extraction/recall criteria. Grounding documents improve overall scores by roughly 9 to 11 points over LLM-only prompting for both models. Web search recovery is partial, adding 4 to 7 points over the LLM-only baseline but still below direct document grounding. Extraction/recall benefits most from grounding, with gains of about 17 to 19 points over the LLM-only setting. Search-based runs consume far more input tokens than the original grounding documents, suggesting retrieval precision is a bottleneck.
The experiments evaluate ProfBench across diverse domains, professional knowledge, human-written rubrics, and fair grading, showing it uniquely meets all criteria while being cost-efficient, especially with adaptive sampling. Grounding documents are critical for performance, as removing them causes significant drops that web search only partially recovers. For judge models, proprietary systems lead slightly, but open-weight models are comparable at lower cost, with post-training improvements often outweighing scale. As a report generation benchmark, ProfBench proves harder than common reasoning tasks, with physics as the most difficult domain, and scaling alone yields diminishing returns.