Command Palette
Search for a command to run...
CancerGUIDE:内部不一致推定による癌診療ガイドライン理解
CancerGUIDE:内部不一致推定による癌診療ガイドライン理解
CancerGUIDE 合成患者データ
概要
米国国立包括癌ネットワーク(NCCN)は、癌治療のためのエビデンスに基づくガイドラインを提供している。複雑な患者の臨床像をガイドライン準拠の治療推奨に変換することは、時間を要し、専門的な知識を必要とし、エラーが発生しやすい。大規模言語モデル(LLM)の能力の進歩は、治療推奨の生成に必要な時間を短縮し、正確性を向上させることが期待されている。我々は、非小細胞肺癌(NSCLC)患者に対するガイドライン準拠の治療経路を自動生成する、LLMエージェントベースのアプローチを提示する。我々の貢献は3つである。第一に、臨床診察、診断結果、病歴を含む121症例のNSCLC患者からなる新しい縦断的データセットを構築し、それぞれに、専門医認定を受けた腫瘍専門医によって対応するNCCNガイドライン経路が専門的に注釈付けされている。第二に、既存のLLMが、モデル開発と評価の両方のための高品質な代理ベンチマーク生成を可能にするドメイン固有の知識を有することを実証し、専門家による注釈付きベンチマークと強い相関(スピアマン係数r = 0.88、RMSE = 0.08)を示す。第三に、高価な人間の注釈とモデルの整合性情報を組み合わせたハイブリッドアプローチを開発し、患者に対する関連ガイドラインを予測するエージェントフレームワークと、治療推奨の校正された信頼スコアで予測精度を検証するメタ分類器(AUROC=0.804)の両方を作成する。校正された信頼スコアリングは、出力の精度を伝達し、パフォーマンスのトレードオフをカスタマイズし、規制順守をサポートするための重要な機能である。この研究は、精度、解釈可能性、規制要件のバランスを取りながら注釈コストを削減する、臨床的に実行可能なLLMベースのガイドライン順守システムの枠組みを確立し、自動化された臨床意思決定支援へのスケーラブルな経路を提供する。
One-sentence Summary
Microsoft Research, Stanford University, and collaborating teams propose CancerGUIDE, an LLM agent framework that generates NCCN guideline-concordant treatment trajectories for NSCLC patients via a 121-case expert-annotated dataset and a hybrid approach merging annotations with model consistency, achieving calibrated confidence verification (AUROC=0.804) and strong correlation with expert benchmarks (Spearman coefficient r=0.88, RMSE=0.08), while balancing accuracy, interpretability, and regulatory compliance for scalable clinical decision support.
Key Contributions
- Introduces a longitudinal dataset of 121 NSCLC patient cases containing clinical encounters, diagnostic results, and medical histories, each annotated with NCCN guideline trajectories by board-certified oncologists for training and evaluation of guideline-recommendation systems.
- Demonstrates that consistency-based synthetic supervision from existing LLMs produces proxy benchmarks closely approximating expert judgment, achieving a Spearman correlation of 0.88 and RMSE of 0.08 against expert-annotated benchmarks while avoiding large-scale human annotation costs.
- Develops a hybrid agent framework combined with a meta-classifier that predicts relevant guidelines for a patient and verifies recommendation accuracy with calibrated confidence scores, reaching an AUROC of 0.804 and enabling ROC-based error tradeoff optimization and regulatory compliance support.
Introduction
Cancer treatment planning requires oncologists to integrate complex patient histories with frequently updated clinical guidelines, such as those from the National Comprehensive Cancer Network (NCCN). While these evidence-based guidelines promote consistent, high-quality care, navigating them is time-intensive and error-prone, contributing to variable adherence, especially in resource-constrained settings. Large language models (LLMs) offer promise for automating guideline-concordant treatment recommendations, but deploying them in clinical decision support demands rigorous validation. Regulatory bodies like the FDA recommend ROC curve analysis as part of performance assessment, which is difficult to produce from generative model outputs that lack semantically aligned confidence scores.
Prior evaluation efforts are fundamentally bottlenecked by the scarcity of expert-annotated datasets, as obtaining high-quality ground truth for complex clinical reasoning requires substantial specialist investment. Synthetic data generation often fails to capture clinical complexity and suffers from distributional shift, while using actual patient treatments as ground truth is problematic because real-world decisions incorporate factors exogenous to guidelines, such as patient preferences, drug availability, and institutional protocols. These limitations leave practitioners without scalable methods to assess model reliability before deployment in high-stakes settings.
The authors address this bottleneck through two complementary approaches. First, they evaluate models across six proxy-benchmark generation methods, including two synthetically generated datasets and four based on real clinical notes with consistency-derived labels, enabling model selection without ground-truth annotations. Second, they demonstrate that self- and cross-model consistency serve as reliable predictors of accuracy on expert-annotated cases. To validate these methods, they construct the first benchmark for NCCN guideline adherence in non-small cell lung cancer, eliciting 13 oncologists to annotate 121 complete patient pathways. Their proxy benchmarks achieve high correlation with human judgments (Spearman r = 0.88, RMSE = 0.08), and their meta-classifier framework, which combines weak supervision signals to classify prediction correctness, achieves an average AUROC of 0.804 across models while also producing calibrated confidence scores that support ROC analysis and regulatory compliance.
Dataset
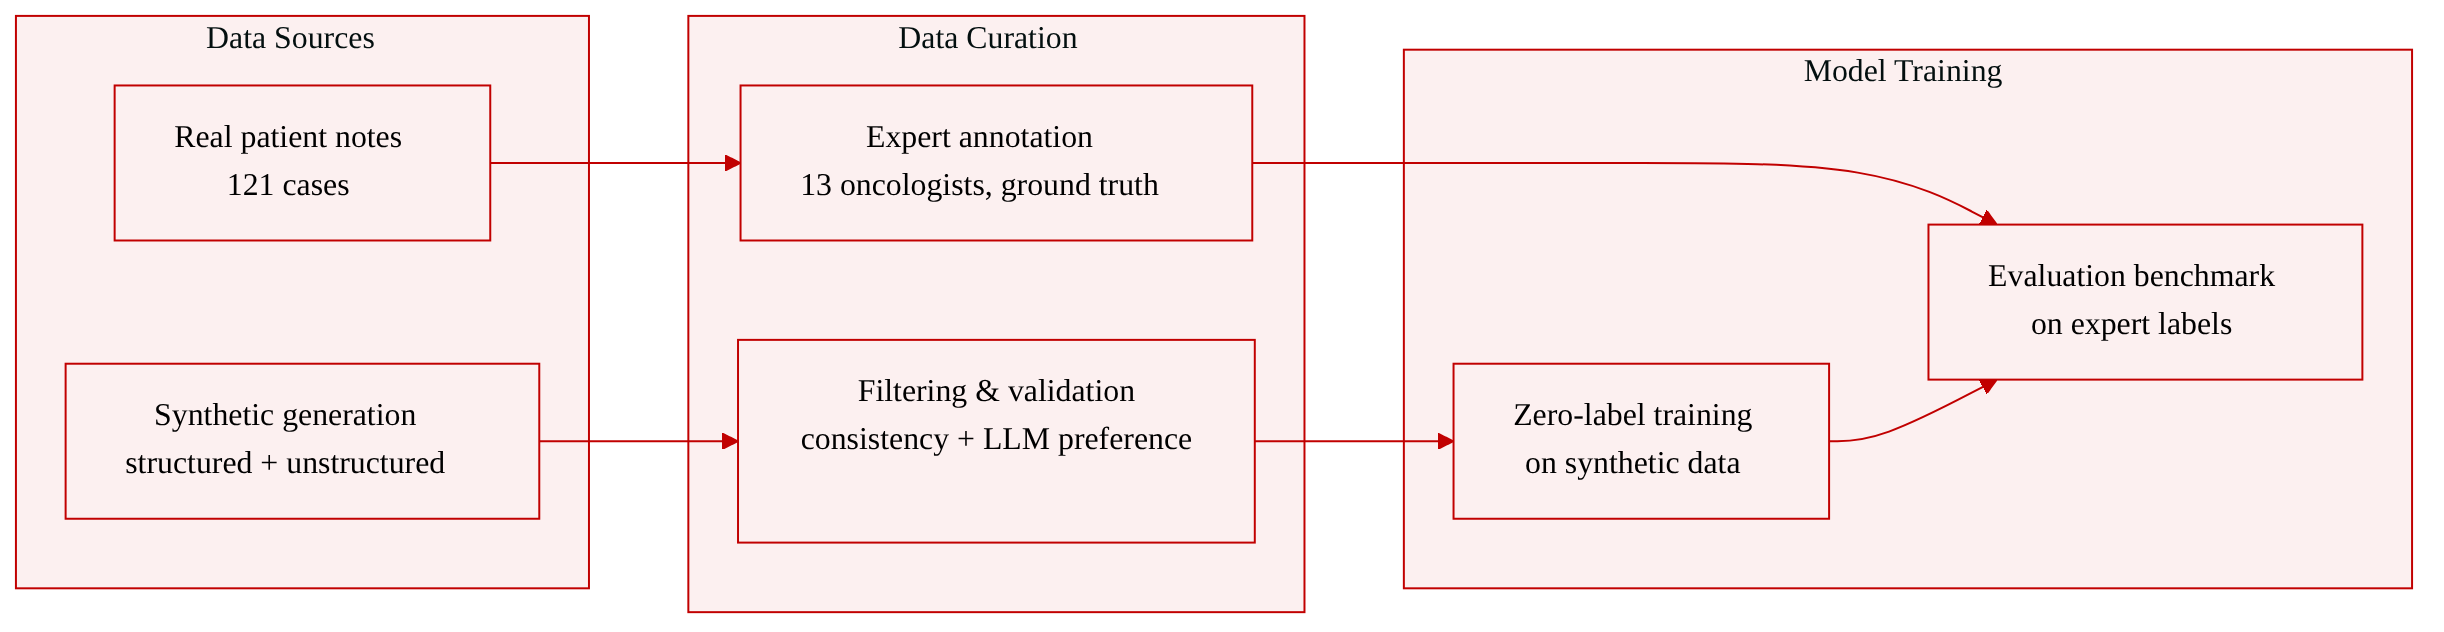
The authors construct two complementary datasets to study guideline-concordant treatment prediction: an expert-annotated benchmark for evaluation and a synthetic dataset for scalable zero-label training and validation.
Expert-Annotated Dataset
- Contains 121 real patient notes annotated by 13 oncologists, with an average annotation time of 46.5 minutes per note and a cost of $500 per US board certified clinician hour.
- Notes average 54,755 characters in length and contain 82 distinct NCCN guideline paths and 48 distinct final treatment recommendations.
- For reliability, 11 examples were dually annotated, yielding an average treatment match of 0.636 and path overlap score of 0.692; further disagreement analysis is provided in the appendix.
- This dataset serves as ground truth for evaluating eight frontier LLMs (GPT-5, GPT-4.1, o3, o4-mini, DeepSeek-R1, LLaMA-3.3-70B-Instruct) with default temperature 1.0 and varying reasoning effort for GPT-5 (minimal, medium, high).
- Two clinically relevant metrics are reported: path overlap (structural agreement with the annotated guideline path) and treatment match (whether the recommended treatment node matches expert annotation).
Synthetic Supervision Dataset
- Generated to support zero-label settings where expert labels are unavailable or too costly.
- The pipeline produces high-fidelity synthetic patient notes paired with generated guideline paths using two strategies:
- Structured Generation: fills empty structured fields conditioned on the target path and full clinical guidelines, performs consistency checks by reconstructing implied paths and discarding mismatched cases, then generates unstructured notes from structured data, target path, guidelines, and real clinical note examples.
- Unstructured Generation: bypasses structured fields and generates synthetic notes directly from target paths, guidelines, and clinical note examples.
- Synthetic data was generated with GPT-4.1, except for cases used to evaluate GPT-4.1, which were produced by GPT-5 under minimal-reasoning conditions.
- A filtering step selects valid pairs: after generating a note, the LLM predicts a path from it. If the prediction matches the target path, the pair is accepted. Otherwise, the LLM chooses between the predicted and target paths in a position-agnostic format, retaining only cases where the target path is selected.
- The final synthetic dataset consists of pairs where the generation model either correctly regenerated the target path from the note or could select the target path when offered alongside its own prediction, capturing cases where direct generation fails but verification remains feasible.
Method
Method
The authors formalize guideline-compliant treatment prediction as a structured prediction problem. Given patient notes x∈X, the goal is to predict a guideline-compliant pathway y∈Y, where Y is the space of decision graphs whose nodes represent clinical decisions and whose terminal nodes correspond to treatments. An LLM f:X→Y yields predictions y^=f(x). Since gold-standard pairs (x,y) are difficult to obtain at scale, the authors avoid direct supervision and instead introduce a two-tiered evaluation framework built on proxy signals.
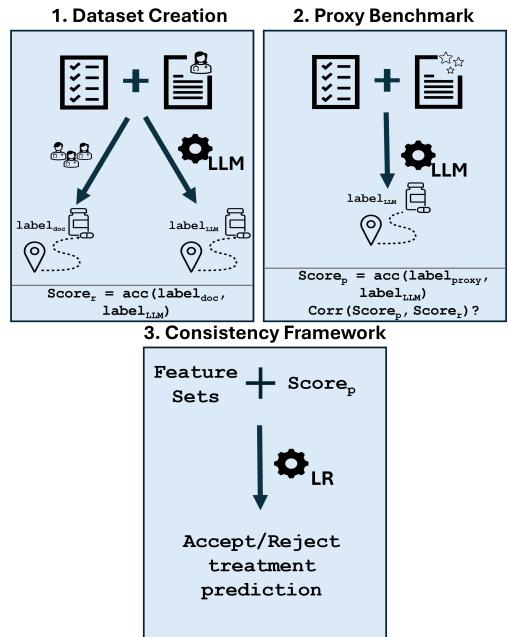
To ground the formalization, the authors extract the NCCN NSCLC guideline decision tree using o3's vision capabilities and curate an expert-annotated dataset in which oncologists trace patient notes through the decision tree, recording node sequences and assessing guideline adherence. Because direct supervision does not scale as X grows, they define two classes of proxy evaluations. The first uses synthetic inputs (x^,y^), where x^ is generated conditionally on guideline paths, enabling controlled assessment of model reliability under perturbations or alternative representations of patient data. The second uses real inputs (x,y^), where the model prediction is sampled multiple times and the pair is retained only if a minimum self-consistency threshold is reached.
These proxy evaluations feed a surrogate evaluator g that predicts whether y^ is guideline-compliant. The authors define a feature mapping
ϕ:(X,Y,f)→Rdthat extracts signals including model self-consistency across rollouts, agreement across models, and alignment with proxy benchmarks. The evaluator is trained as a binary classifier:
g(ϕ(x,y^,f))≈1{y^=y},with the objective of minimizing the expected classification loss
gminE(x,y)∼D[L(g(ϕ(x,y^,f)),1{y^=y})],where D is the patient distribution and L is a standard loss. This formulation allows evaluation of f in zero-label settings by leveraging model agreement, self-consistency, and benchmark-derived features for meta-classification.
Evaluation Metrics
The authors employ two complementary metrics. Path Overlap measures the proportion of nodes in predicted paths that repeat across compared paths, capturing consistency of decision sequences and reflecting the model's ability to navigate the guideline-adherent decision process even when the final treatment is incorrect. Treatment Match is a binary score indicating whether the final predicted treatment matches the ground truth when available; in settings without ground truth, it is computed as the proportion of repeated final treatments across multiple predictions. These metrics offer complementary perspectives: Path Overlap emphasizes process fidelity and decision-support potential, while Treatment Match captures outcome correctness. To ensure deterministic scores, LLM judges are not used for path similarity assessment, as their stochasticity would confound direct model comparison.
Zero-Label Benchmark Generation
To approximate (x,y) pairs for evaluation, the authors propose two complementary approaches with six proxy benchmarking methods in total.
Synthetic supervision. The authors generate high-fidelity synthetic patient notes x^ paired with guideline paths y^, using a multi-step pipeline that separates note generation from label selection to filter incorrect labels while preserving realistic clinical cases. Two generation strategies are used for x^. Structured generation fills empty structured fields conditioned on the generated path and full clinical guidelines, performs consistency checks by reconstructing implied paths and discarding mismatched cases, then generates unstructured notes from the structured data, target path, guidelines, and real clinical note examples. Unstructured generation bypasses structured fields, generating synthetic notes directly from target paths, guidelines, and clinical note examples. Synthetic datasets are generated with GPT-4.1, except for those used to evaluate GPT-4.1 itself, which are produced by GPT-5 under minimal-reasoning conditions.
Once x^ is generated, y^ is obtained by having the LLM generate the path from x^. If the prediction matches the target path, the pair is accepted directly. Otherwise, the LLM selects between the predicted and target paths in a position-agnostic format, and cases are retained only when the target path is chosen. This captures examples where direct generation fails but verification remains feasible, exploiting the asymmetry that generating the correct path is harder than identifying it.
Consistency-based pseudo-labeling. The authors derive pseudo-labels from two sources: self-consistency (agreement within repeated predictions of a single model) and cross-model consistency (agreement across different models). For each source, they define two benchmarks based on whether consistency is measured via path overlap or treatment match, yielding four benchmarks. For self-consistency, k independent predictions are sampled from model m for each note x. Agreement is assessed along path overlap and treatment match, and notes with agreement above a threshold δ=0.9 on the target metric are retained, while inconsistent cases are scored 0. Performance is computed as accuracy over the retained subset, counting inconsistent answers as incorrect. For cross-model consistency, pseudo-labels are assigned when two or more models converge on the same exact path after k independent samples. Inconsistent cases are excluded rather than penalized, and all models are evaluated on the resulting proxy benchmark.
Final Treatment Accuracy Prediction
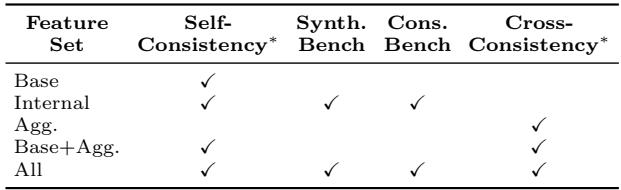
The authors train a meta-classifier that predicts the accuracy of a generated final treatment prediction using features derived from self-consistency metrics (k-rollout path overlap and treatment match), cross-model consistency (fraction of models producing the same path), and proxy benchmark scores. In addition, they demonstrate label-free evaluation through unsupervised methods: clustering self- and cross-model consistency features naturally separates high-confidence correct from low-confidence incorrect predictions. For error identification, they tabulate inconsistencies across k rollouts for each model on each patient, leveraging consistency signals to detect potential errors without human labels.
Experiment
The experiments validate guideline-compliant treatment prediction using two complementary metrics, path overlap for process fidelity and treatment match for outcome accuracy. They introduce six zero-label proxy benchmarks combining synthetic supervision and consistency-based pseudo-labeling, finding that unstructured synthetic generation yields lower error and that thresholding by treatment match outperforms path overlap, while cross-model aggregation adds noise. On a 13-oncologist annotated dataset of 121 notes, frontier LLMs are evaluated, and a meta-classifier leveraging self-consistency signals predicts treatment accuracy with 0.804 AUROC, generalizing across models and patients and detecting 40% of errors without any human labels, demonstrating that consistency patterns alone enable reliable error detection.
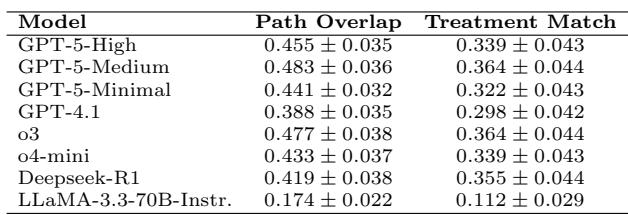
On an expert-annotated oncology treatment benchmark, all evaluated models show moderate structural path overlap but lower exact treatment match, with the best performance around half of the guideline path. GPT-5 with medium reasoning effort leads on path overlap and ties for the top treatment match with o3, while GPT-4.1 trails on both metrics. Increasing reasoning effort from minimal to medium helps, but further effort to high slightly reduces performance. GPT-5 with medium reasoning effort achieves the highest path overlap and ties with o3 for the best treatment match. GPT-4.1 shows the weakest performance on both path overlap and treatment match among the models. Raising GPT-5's reasoning effort from minimal to medium improves scores, but using high effort yields slightly lower results than medium.
A meta-classifier predicts treatment recommendation accuracy with 0.804 AUROC using consistency-based features, where cross-model consistency signals outperform proxy benchmark features. Even without cross-model information, self-consistency alone provides strong classification, and unsupervised consistency signals detect a meaningful portion of errors without labeled data. Feature sets with cross-model consistency outperform those relying on synthetic benchmarks, showing minimal gain from proxy benchmark performance. Self-consistency features alone (without cross-model information) still yield high AUROC, indicating they are a strong standalone signal. Unsupervised consistency-based error detection achieves an F1 of 0.666 versus 0.702 for supervised classification, and detects 40.42% of all model errors without human labels.
On an oncology treatment benchmark, all models achieved only moderate structural overlap with guidelines and low exact treatment matches, with GPT-5 at medium reasoning effort leading and GPT-4.1 performing worst; moderate reasoning effort outperformed both minimal and high effort. A separate meta-classifier for treatment recommendation accuracy showed that consistency-based features, especially cross-model consistency, were strong predictors, with self-consistency alone being sufficient for robust performance and unsupervised error detection catching many mistakes without labels.