Command Palette
Search for a command to run...
MMLU-CF:汚染のない多タスク言語理解ベンチマーク
MMLU-CF:汚染のない多タスク言語理解ベンチマーク
MMLU-CF 汚染のないマルチタスク言語理解ベンチマークデータセット
概要
大規模言語モデル(LLM)の常識、理解、問題解決能力を評価するために、Massive Multitask Language Understanding(MMLU)のような多肢選択問題(MCQ)データセットが広く使用されている。しかし、これらのベンチマークのオープンソースな性質と、LLMの学習データの幅広い源泉により、ベンチマーク汚染が不可避的に生じ、評価結果の信頼性が損なわれている。この問題を緩和するため、我々はMMLU-CFと呼ばれる、汚染がなく、より挑戦的なMCQベンチマークを提案する。このベンチマークは、意図的でないデータ漏洩と悪意のあるデータ漏洩の両方を回避することで、LLMの世界知識の理解を再評価する。意図的でないデータ漏洩を避けるために、より広い領域からデータを収集し、3つの非汚染化ルールを設計する。悪意のあるデータ漏洩を防ぐために、ベンチマークを類似した難易度と主題分布を持つ検証セットとテストセットに分割する。テストセットは信頼できる結果を保証するためにクローズドソースのまま維持され、検証セットは透明性を促進し独立した検証を容易にするために公開される。主流のLLMの評価により、強力なGPT-4oでさえテストセットで5ショットスコア73.4%、0ショットスコア71.9%を達成するに過ぎず、これはより厳格で汚染のない評価基準を構築する上での我々のアプローチの有効性を示している。
One-sentence Summary
Microsoft Research introduces MMLU-CF, a contamination-free multi-task language understanding benchmark that mitigates both unintentional and malicious data leakage through broader data sourcing, three decontamination rules, and a closed-source test set, with GPT-4o achieving only 73.4% (5-shot) and 71.9% (0-shot) scores, thereby establishing a more rigorous and reliable evaluation standard.
Key Contributions
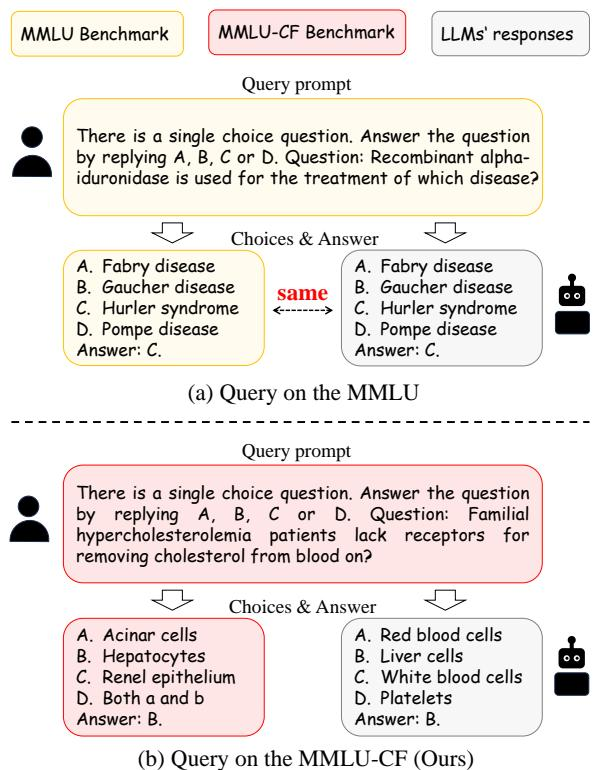
- The paper introduces MMLU-CF, a contamination-free multiple-choice question benchmark that distinguishes between unintentional and malicious data leakage, and mitigates the former by sourcing questions from a broader domain while applying three dedicated decontamination rules.
- The benchmark is divided into a validation set and a test set with matched difficulty and subject distributions, where the test set is kept closed-source to prevent malicious leakage and the validation set is publicly released to support transparency and independent verification.
- Evaluation results show that GPT-4o, the strongest model tested, attains only 73.4% accuracy in the 5-shot setting and 71.9% in the 0-shot setting, substantially below its 88.0% score on MMLU, which demonstrates that MMLU-CF offers a more rigorous and contamination-resistant evaluation standard.
Introduction
Evaluating large language models (LLMs) is critical as models like GPT-4, Llama, Gemini, and Claude-3 grow in capability, and MMLU has become a standard multiple-choice benchmark for measuring world knowledge across diverse disciplines. However, benchmark contamination undermines evaluation reliability: models may encounter test data during training, either unintentionally through public exposure or maliciously when benchmarks are added to training sets, causing models to memorize questions and directly recall exact choices and answers. The authors propose MMLU-CF, a contamination-free multiple-choice benchmark built through five processing steps, including three question-rewriting rules that preserve meaning for humans but disrupt memorized recall, plus a closed-source test set to prevent malicious leakage and an open validation set for transparency. Their results show that leading models score notably lower on MMLU-CF than on MMLU, with GPT-4o dropping from 88.0% to 73.4%, which confirms that prior benchmarks can overstate model knowledge and highlights the challenge of building fair, contamination-free evaluations.
Dataset
The authors construct the MMLU-CF benchmark from public web data. Here is how the dataset is built and used:
-
Sources and scale: The authors screen over 200 billion documents from public open websites. Using rule-based extraction, they collect 2.7 million raw multiple-choice questions from more than 3,000 domains, spanning 14 fields (Health, Math, Physics, Business, Chemistry, Philosophy, Law, Engineering, and others).
-
Cleaning and filtering: After collecting raw questions, they apply a multi-step cleaning process. This includes removing questions without exactly four choices, dropping empty choices, standardizing labels to A/B/C/D, converting labels to uppercase, adjusting answers accordingly, removing overly short questions (under 10 characters), standardizing answer formats, stripping numbering and Roman numerals, removing non-English or lower-case initial characters, and deduplicating. This reduces the data to 1.66 million questions.
-
Difficulty sampling: Because existing benchmarks like MMLU have become too easy for frontier models, the authors use GPT-4o to assign difficulty levels (on a scale, using MMLU questions as a reference). They then sample from the 1.66 million cleaned questions using a normal distribution centered at a moderate difficulty level, while balancing category distribution, maximizing domain diversity, and preferring questions with explanations. This yields 50,000 questions.
-
LLM review: The 50,000 questions are reviewed by three different LLMs (GPT-4o, Gemini, and Claude) for quality (context clarity, logical consistency, factual accuracy, mutual exclusivity, correct answer presence) and harmlessness (no hate, sexual content, self-harm, or violence). Each model scores questions on a scale, and only those with an average score above a threshold are kept. The authors also perform redundancy detection (using GPT-4o) to remove semantically identical questions.
-
Decontamination processing: To prevent memorization leakage, they apply three rules:
- Rephrase each question to reduce dependence on training data.
- Shuffle the answer choices (if the last option is "None of the above" or "All of the above", only the first three choices are shuffled).
- With 50% probability, randomly replace one choice with "None of the other choices". If the correct option is replaced, it remains valid; if an incorrect one is replaced, it acts as a distractor.
-
Final splits and use: After decontamination, the data is split into 10,000 validation and 10,000 test questions, with similar difficulty and category distributions. The validation set is open-source for transparency, while the test set is kept closed-source to prevent malicious exposure. The authors use these sets to evaluate LLM performance, focusing on reasoning and understanding rather than memorization.
Method
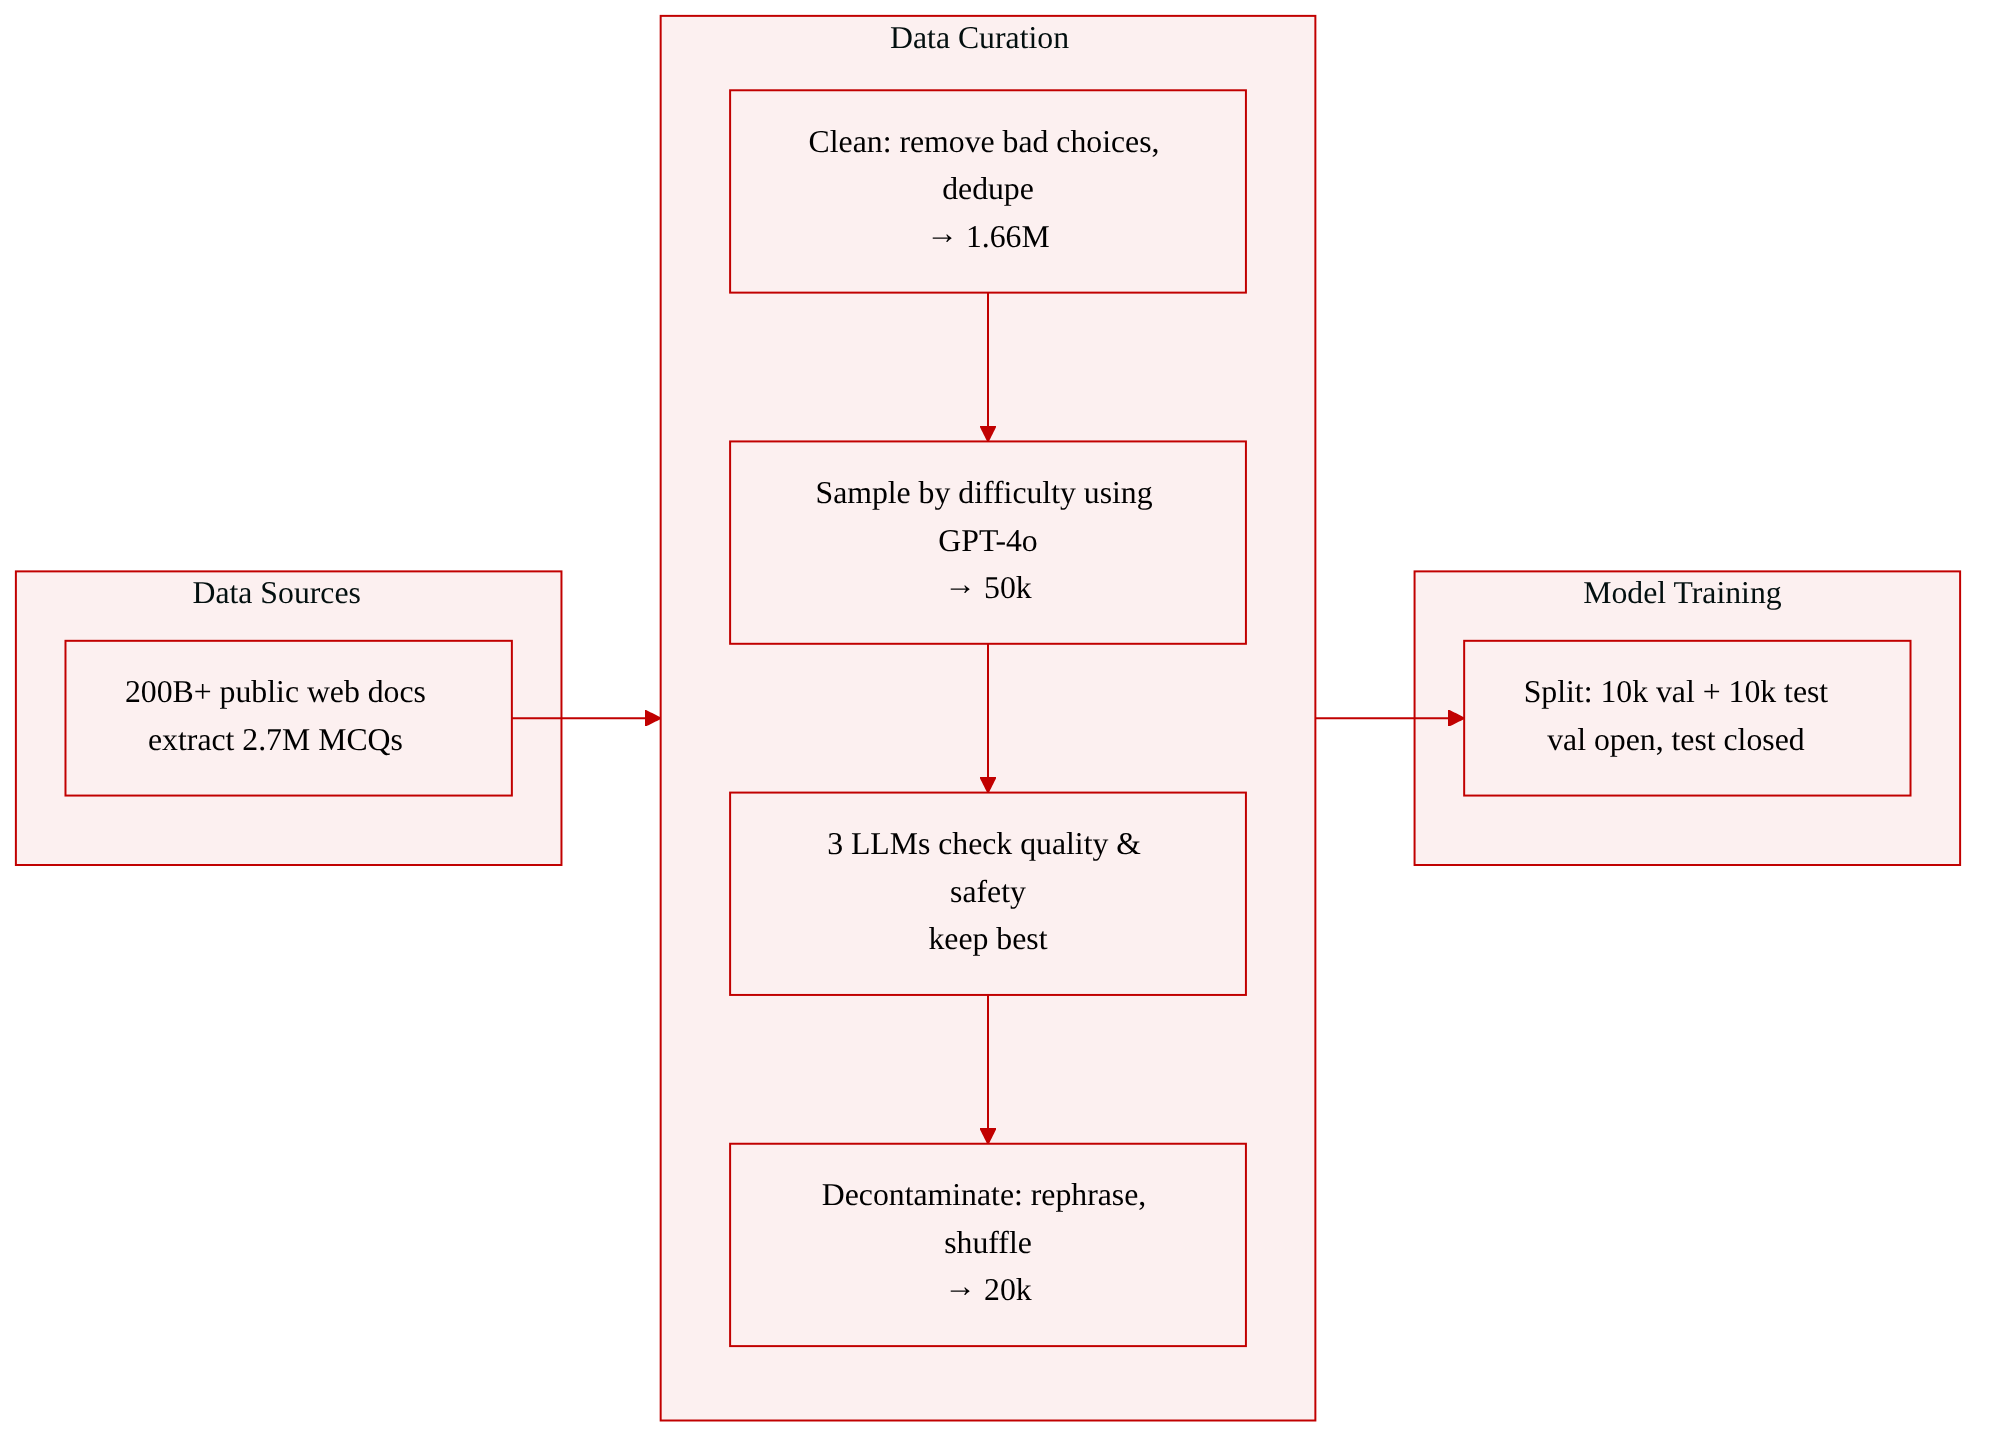
The authors propose a comprehensive pipeline for constructing the MMLU-CF benchmark, designed to mitigate data contamination and address the difficulty saturation of existing benchmarks. The process begins with MCQ Collection, where the team leverages over 200 billion documents from public open-source websites to extract 2.7 million raw multiple-choice questions. This vast corpus spans over 3,000 domains and 14 fields, ensuring diverse content.
Next, the MCQ Cleaning phase applies rigorous filtering. Questions are filtered for having exactly four choices, removing those with empty content or non-standard labels (A, B, C, D). The pipeline standardizes formats, enforces a minimum length of 10 characters, removes redundant numbering, and deduplicates the dataset, reducing the scale to 1.66 million questions.
To address the difficulty bottleneck in current benchmarks, the authors implement a Difficulty Sampling strategy. They first utilized GPT-4o to categorize the difficulty of original MMLU data. As illustrated in the difficulty distribution chart, the original MMLU data contains a high abundance of easy questions, which contributes to the high accuracy scores of modern LLMs.
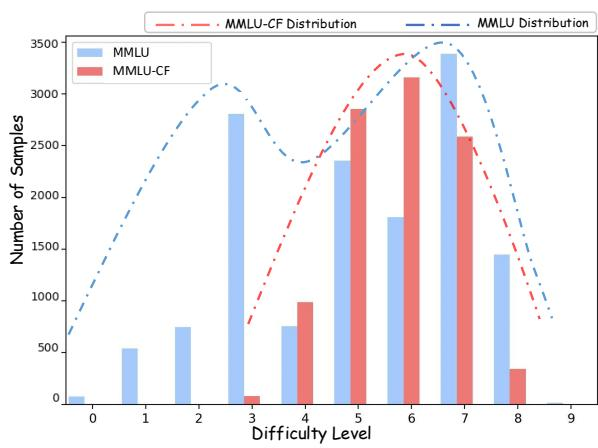
Using these difficulty levels as a reference, the authors applied a 5-shot query to GPT-4o to classify the difficulty of the 1.66 million clean questions. They then sampled questions using a normal distribution centered around a higher difficulty level to ensure a more challenging benchmark. This sampling process, which also aimed to maintain domain diversity and category balance, reduced the dataset to 50,000 questions.
Following sampling, a LLMs Checking phase was conducted to ensure quality and harmlessness. Three models (GPT-4o, Gemini, and Claude) were employed to evaluate the questions based on criteria such as context clarity, logical consistency, factual accuracy, and mutual exclusivity of choices. Additionally, the content was screened for harmful elements including hate speech, sexual content, self-harm, and violence. Questions with an average quality score above a certain threshold were selected. Redundancy detection was performed using GPT-4o to remove semantically identical questions.
Finally, to prevent performance inflation due to memorization, the authors implemented a Contamination-Free Processing module. As shown in the figure below, this module applies three specific transformation rules to the selected questions.
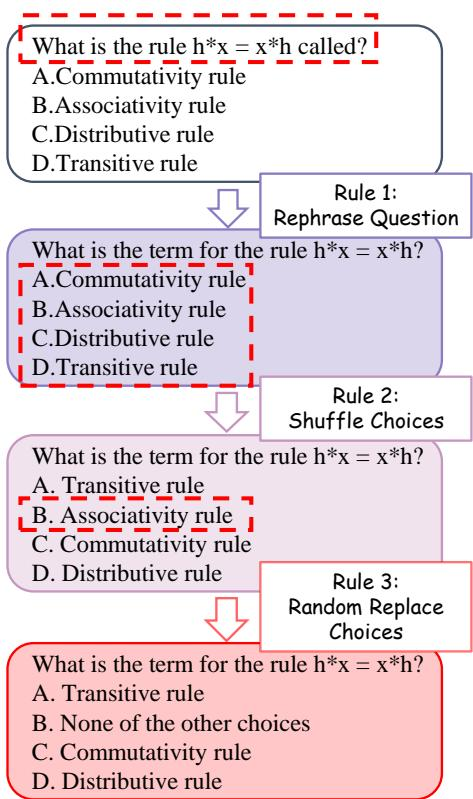
First, the Rephrase Question rule rewrites the question stem to reduce dependence on previously encountered training data. Second, the Shuffle Choices rule randomizes the order of the options to prevent models from relying on memorized choice sequences, while preserving options like "None of the above" if they appear last. Third, the Random Replace Choices rule replaces one of the choices with "None of the other choices" with a 50% probability. This modification forces the model to engage in deeper reasoning rather than simple pattern matching, as the correct answer must still be valid within the new context. The final dataset is split into 10,000 validation and 10,000 test questions, with the test set kept closed-source to prevent contamination.
Experiment
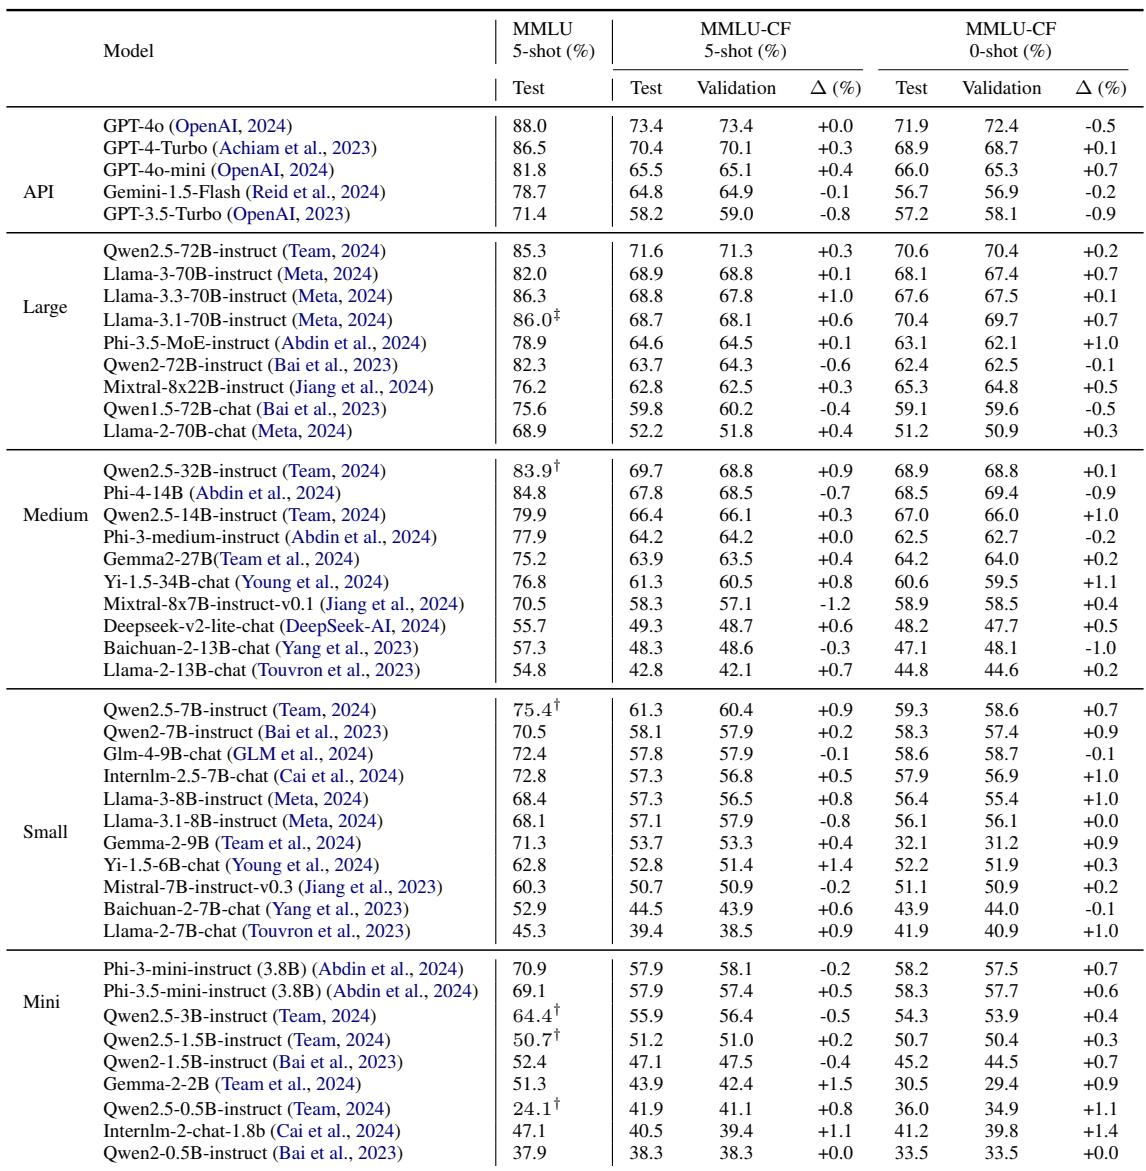
The MMLU-CF benchmark is introduced with a rigorous pipeline including collection, cleaning, difficulty sampling, LLM checking, and contamination-free processing, yielding a diverse set of test and validation questions. Evaluations on over 40 models show that GPT-4o leads overall, while Qwen2.5 variants excel across model sizes, and the validation set partitioning with a delta score effectively monitors for potential data leakage. Ablation studies on the decontamination rules demonstrate that rephrasing, shuffling, and replacing choices notably reduce model performance, confirming their success in mitigating memorization and enforcing reasoning-based assessment.
GPT-4o achieves the highest scores on the MMLU-CF test set in both 5-shot and 0-shot settings, while Qwen2.5-72B-instruct leads among open-weight large models. Test and validation results are highly consistent, with most absolute differences below 0.5 percentage points, indicating the validation set reliably reflects model generalization. GPT-4o outperforms all other models on MMLU-CF, scoring 73.4% in 5-shot and 71.9% in 0-shot on the test set. Across models, about 60% of absolute score differences between test and validation sets are below 0.5, and 96% are below 1.0. Qwen2.5-72B-instruct is the strongest open-weight large model, reaching 71.6% in 5-shot and showing a slight positive test-validation difference.
Applying decontamination rules to the MMLU-CF test set consistently reduces model performance across all tested LLMs. The performance drop becomes more pronounced as additional rules are applied, with the largest decline occurring when all three rules are combined. Smaller models appear more sensitive to these modifications, showing relatively larger performance losses. Rephrasing questions alone causes only a slight performance decrease across all models. Adding choice shuffling and random replacement leads to a more significant decline, especially when all three rules are applied together. The performance drop is more pronounced for GPT-3.5-Turbo and Llama-3.1-8b, suggesting smaller models are more affected by these decontamination rules.
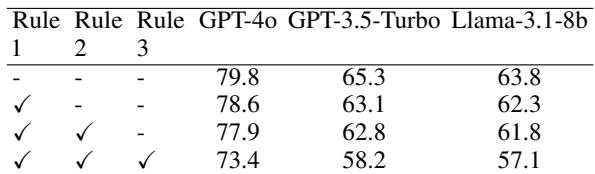
In evaluations on the MMLU-CF benchmark, GPT-4o achieves the highest accuracy in both 5-shot and 0-shot settings, while Qwen2.5-72B-instruct leads among open-weight models, and test and validation results are highly consistent. Applying decontamination rules uniformly reduces model performance, with the effect growing as more rules are combined; question rephrasing causes only a slight drop, while adding choice shuffling and random replacement leads to larger declines, particularly for smaller models like GPT-3.5-Turbo and Llama-3.1-8b.