HyperAI
Command Palette
Search for a command to run...
Papers
Daily updated cutting-edge AI research papers to help you keep up with the latest AI trends
papers
ReasonRank: Empowering Passage Ranking with Strong Reasoning Ability
AdaptFlow: Adaptive Workflow Optimization via Meta-Learning
Mediator-Guided Multi-Agent Collaboration among Open-Source Models for Medical Decision-Making
Adapting Vision-Language Models Without Labels: A Comprehensive Survey
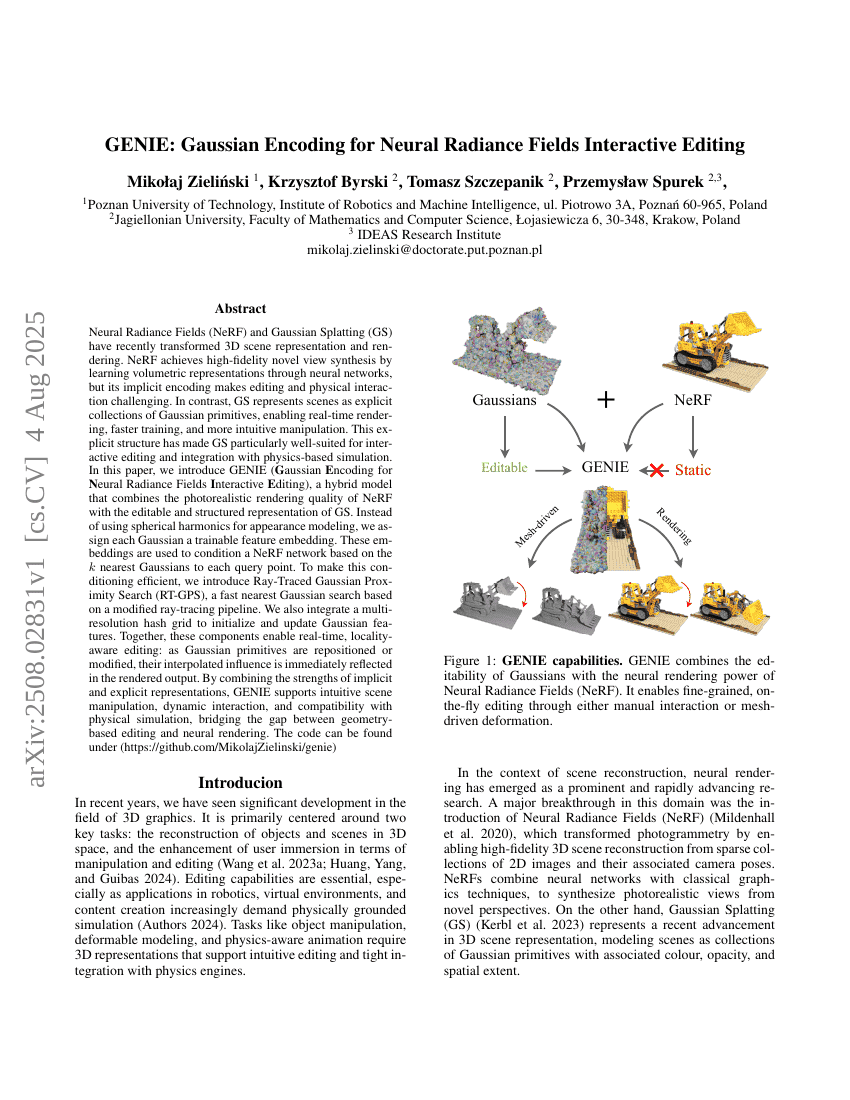
GENIE: Gaussian Encoding for Neural Radiance Fields Interactive Editing
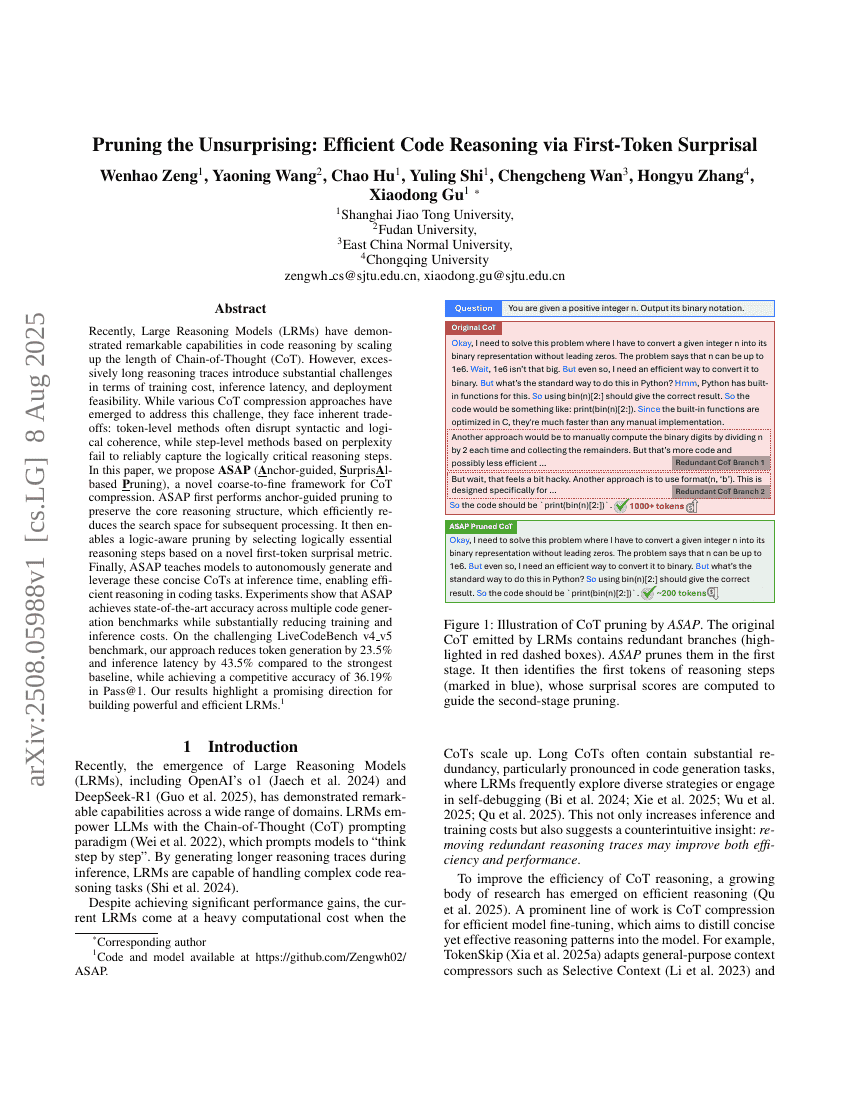
Pruning the Unsurprising: Efficient Code Reasoning via First-Token Surprisal
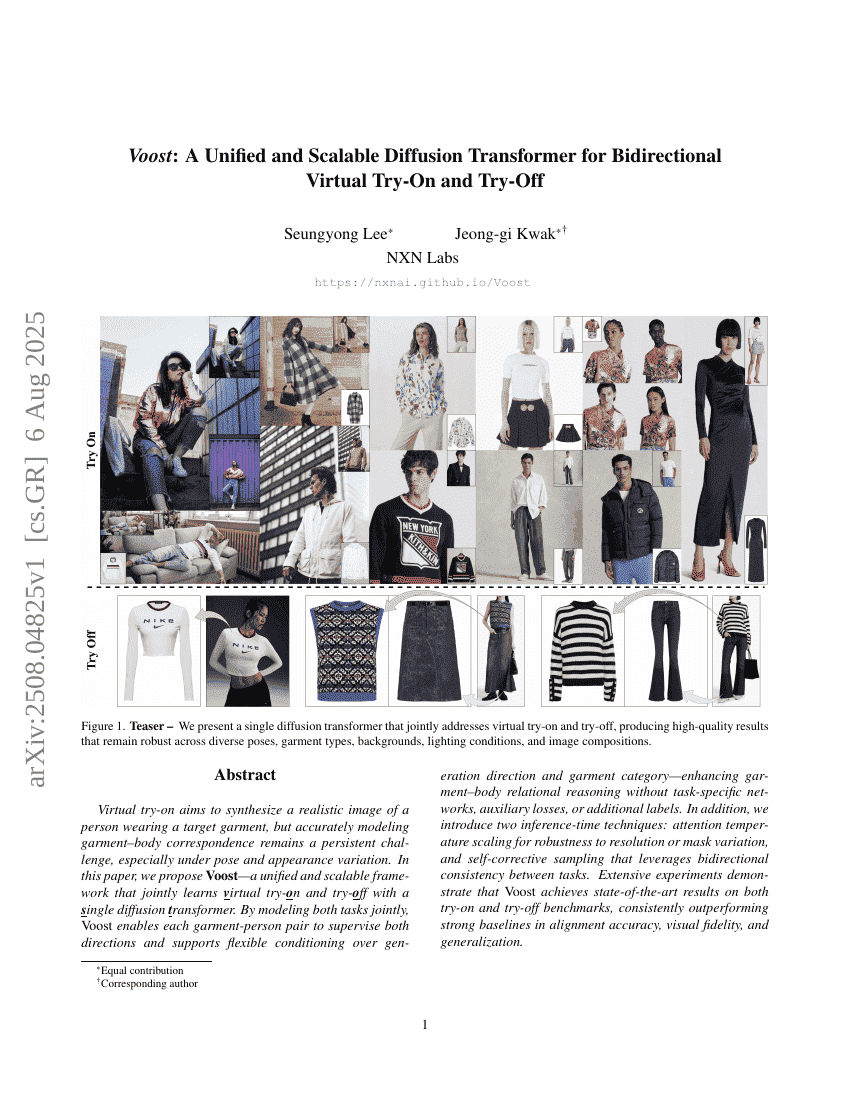
Voost: A Unified and Scalable Diffusion Transformer for Bidirectional Virtual Try-On and Try-Off
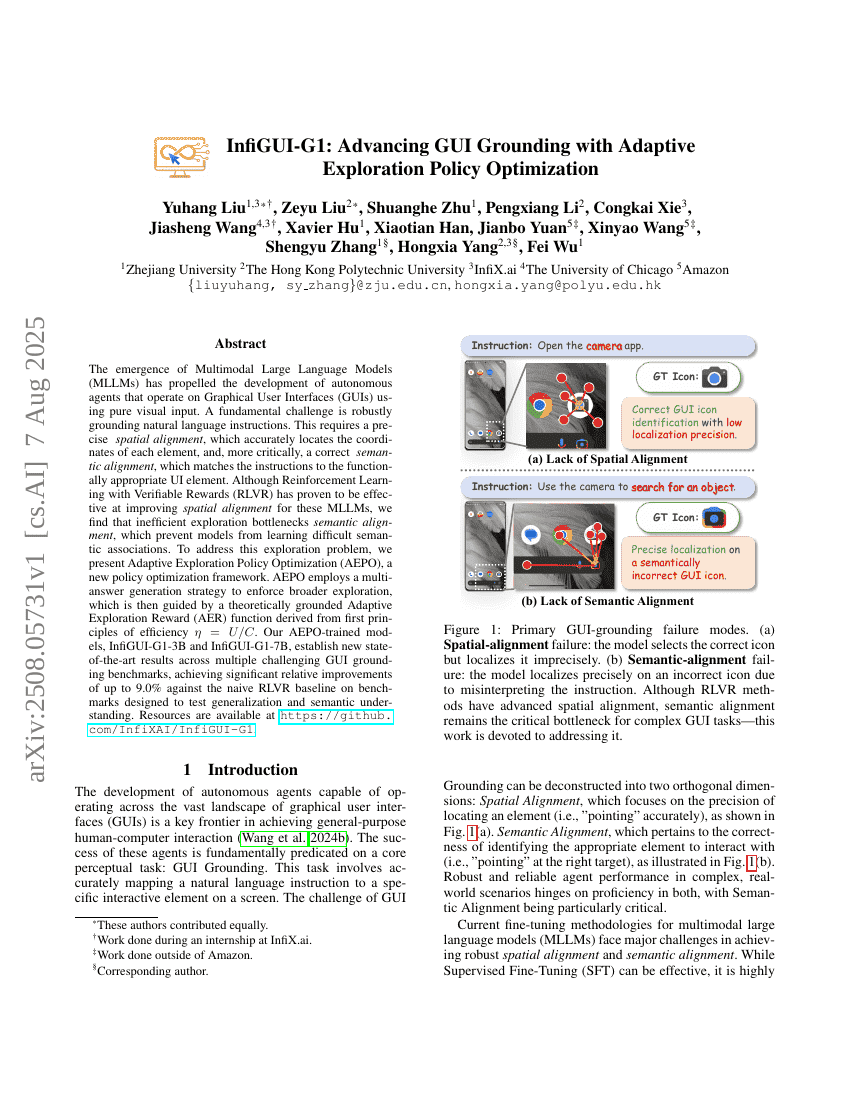
InfiGUI-G1: Advancing GUI Grounding with Adaptive Exploration Policy Optimization
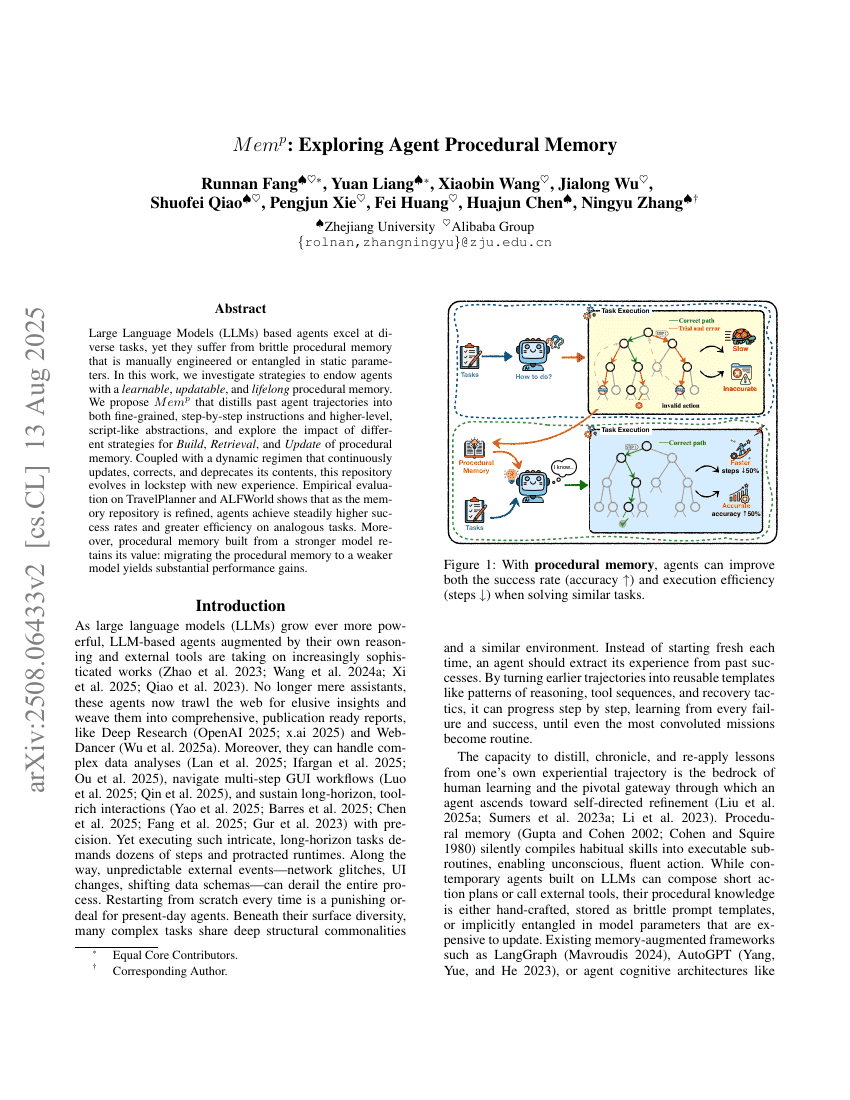
Memp: Exploring Agent Procedural Memory
Perch 2.0: The Bittern Lesson for Bioacoustics
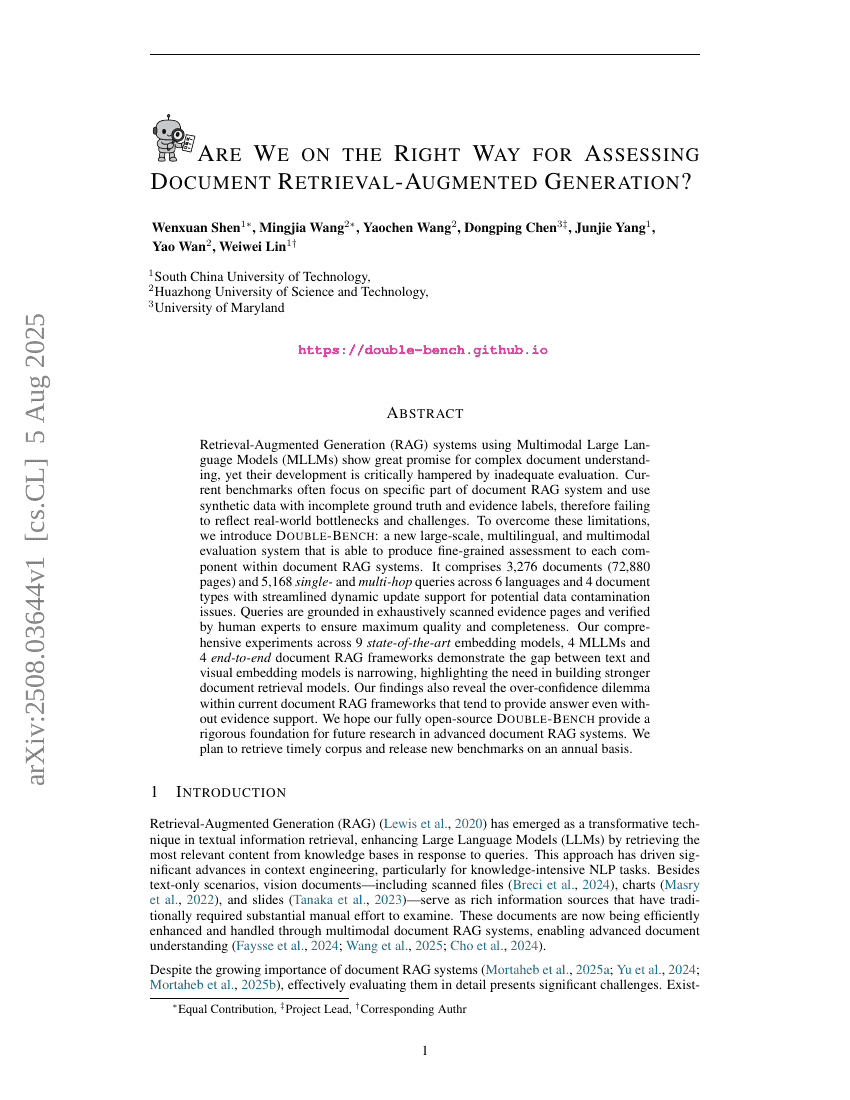
Are We on the Right Way for Assessing Document Retrieval-Augmented Generation?
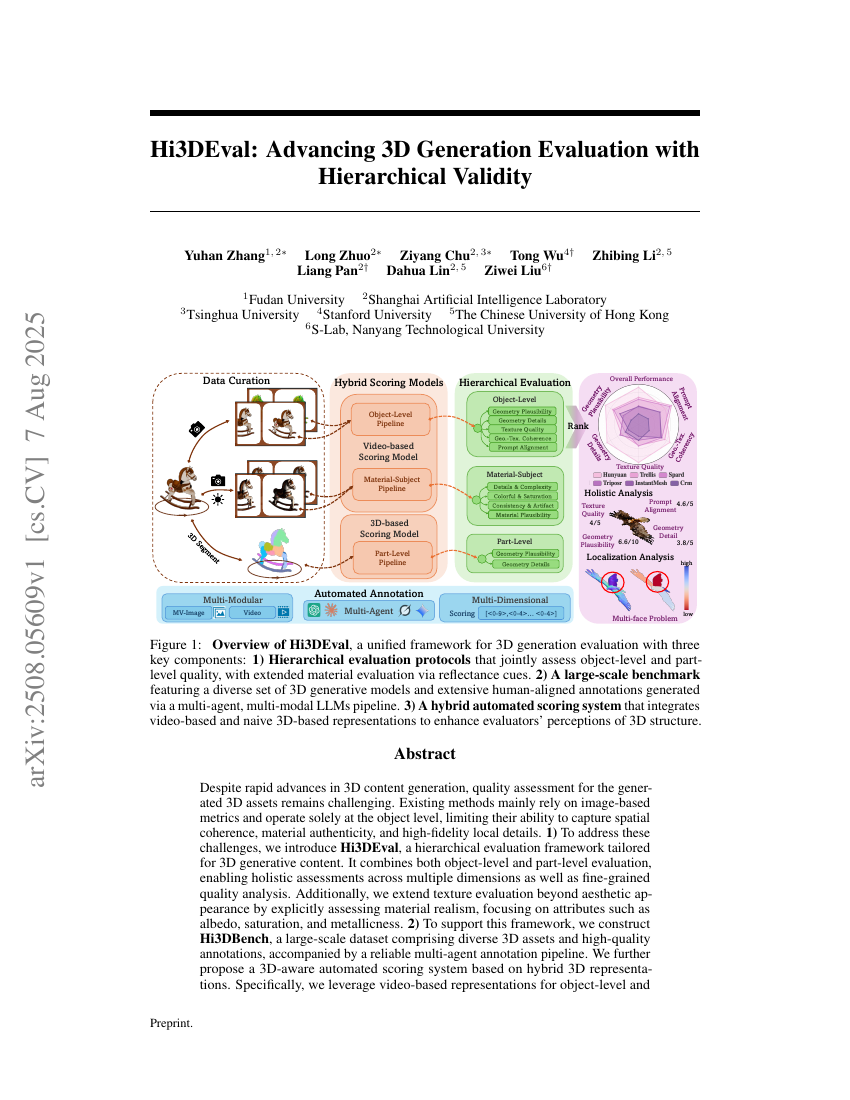
Hi3DEval: Advancing 3D Generation Evaluation with Hierarchical Validity
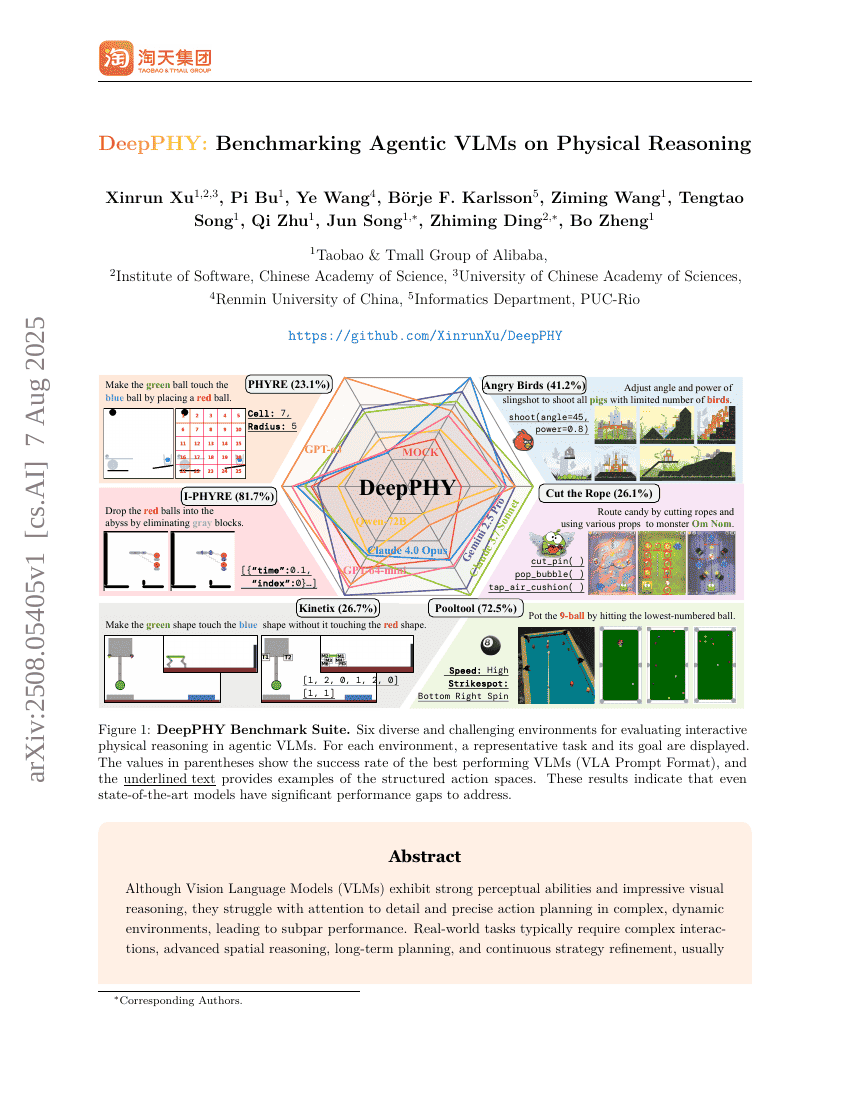
DeepPHY: Benchmarking Agentic VLMs on Physical Reasoning
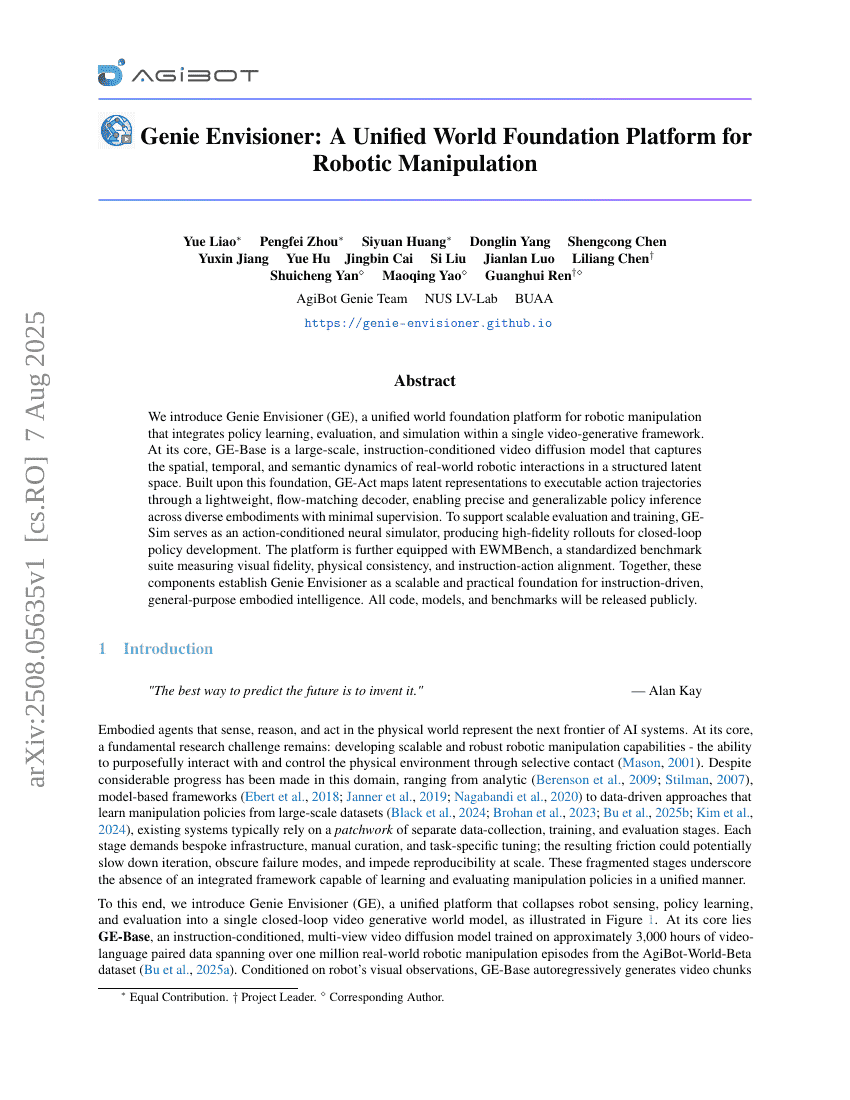
Genie Envisioner: A Unified World Foundation Platform for Robotic Manipulation
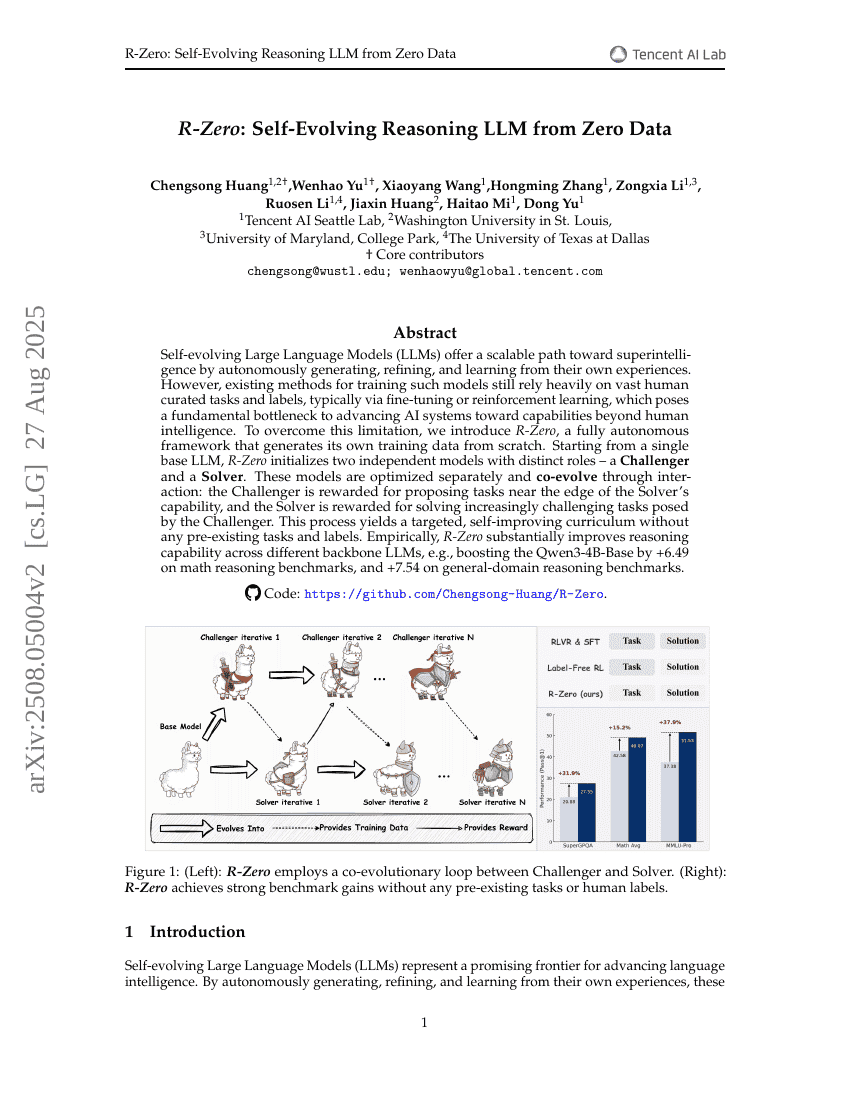
R-Zero: Self-Evolving Reasoning LLM from Zero Data
On the Generalization of SFT: A Reinforcement Learning Perspective with Reward Rectification
Simulating Human-Like Learning Dynamics with LLM-Empowered Agents
GRAIL:Learning to Interact with Large Knowledge Graphs for Retrieval Augmented Reasoning
CoTox: Chain-of-Thought-Based Molecular Toxicity Reasoning and Prediction
Efficient Agents: Building Effective Agents While Reducing Cost
Is Chain-of-Thought Reasoning of LLMs a Mirage? A Data Distribution Lens
VeriGUI: Verifiable Long-Chain GUI Dataset
Qwen2.5-VL Technical Report
The GAN is dead; long live the GAN! A Modern GAN Baseline
MegaPairs: Massive Data Synthesis For Universal Multimodal Retrieval
Lyra: An Efficient and Speech-Centric Framework for Omni-Cognition
NVILA: Efficient Frontier Visual Language Models
Expanding Performance Boundaries of Open-Source Multimodal Models with Model, Data, and Test-Time Scaling
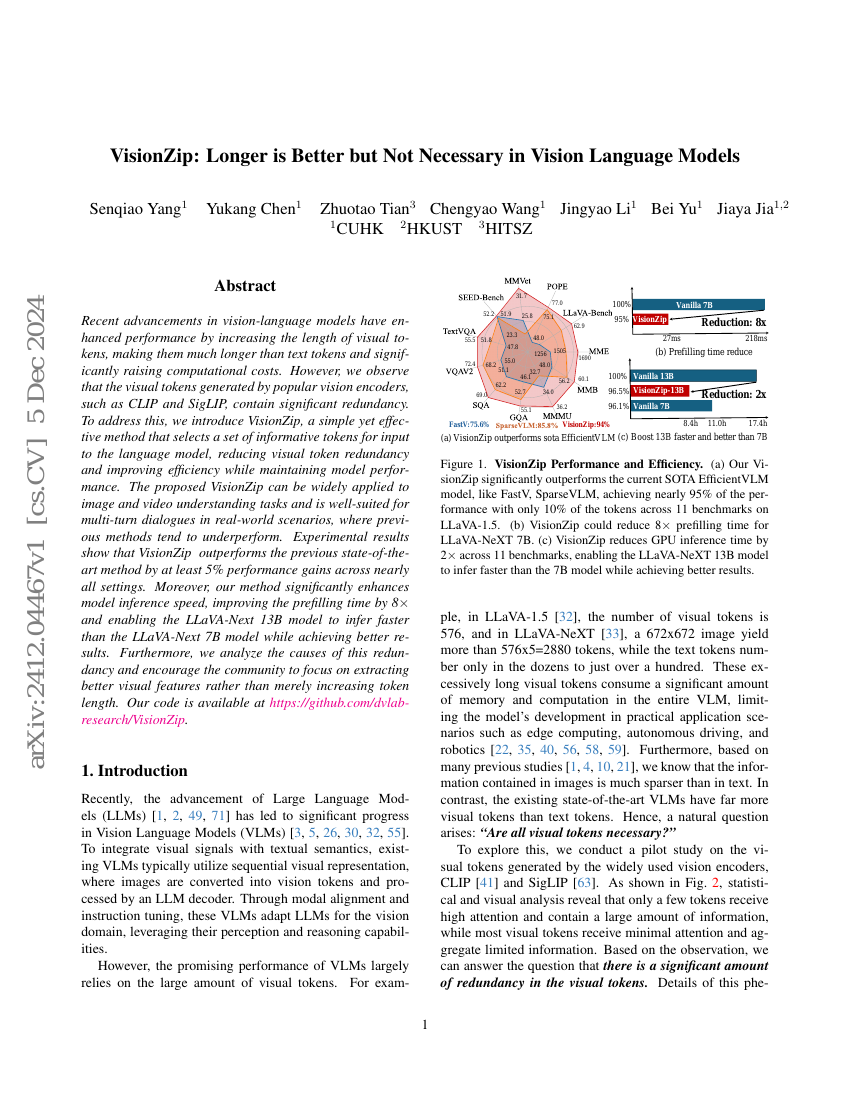
VisionZip: Longer is Better but Not Necessary in Vision Language Models
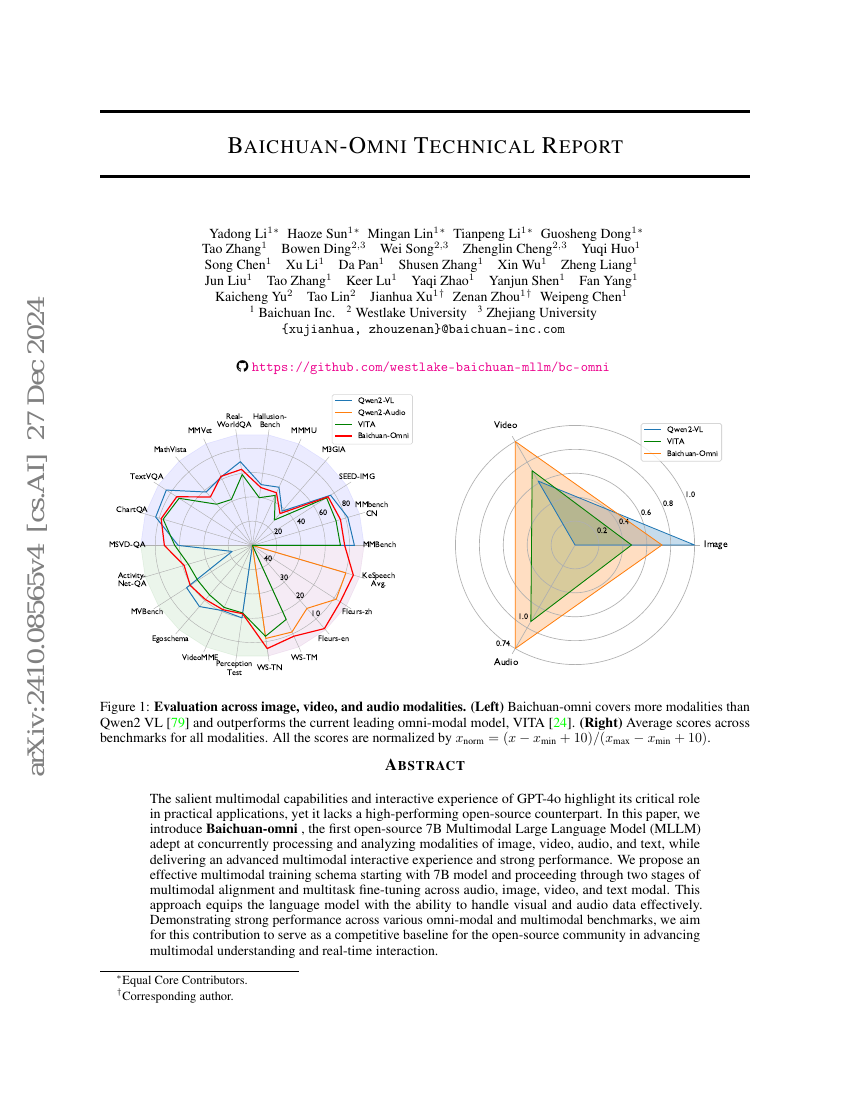
Baichuan-Omni Technical Report
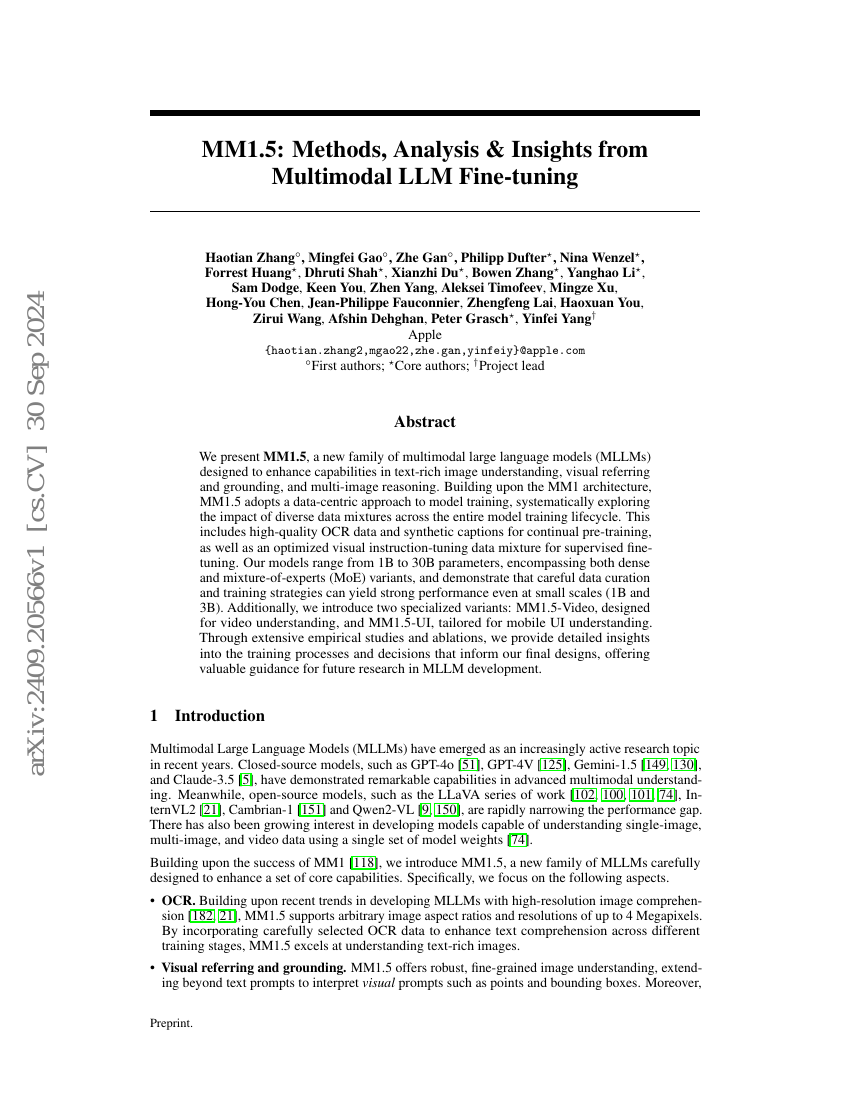
MM1.5: Methods, Analysis & Insights from Multimodal LLM Fine-tuning
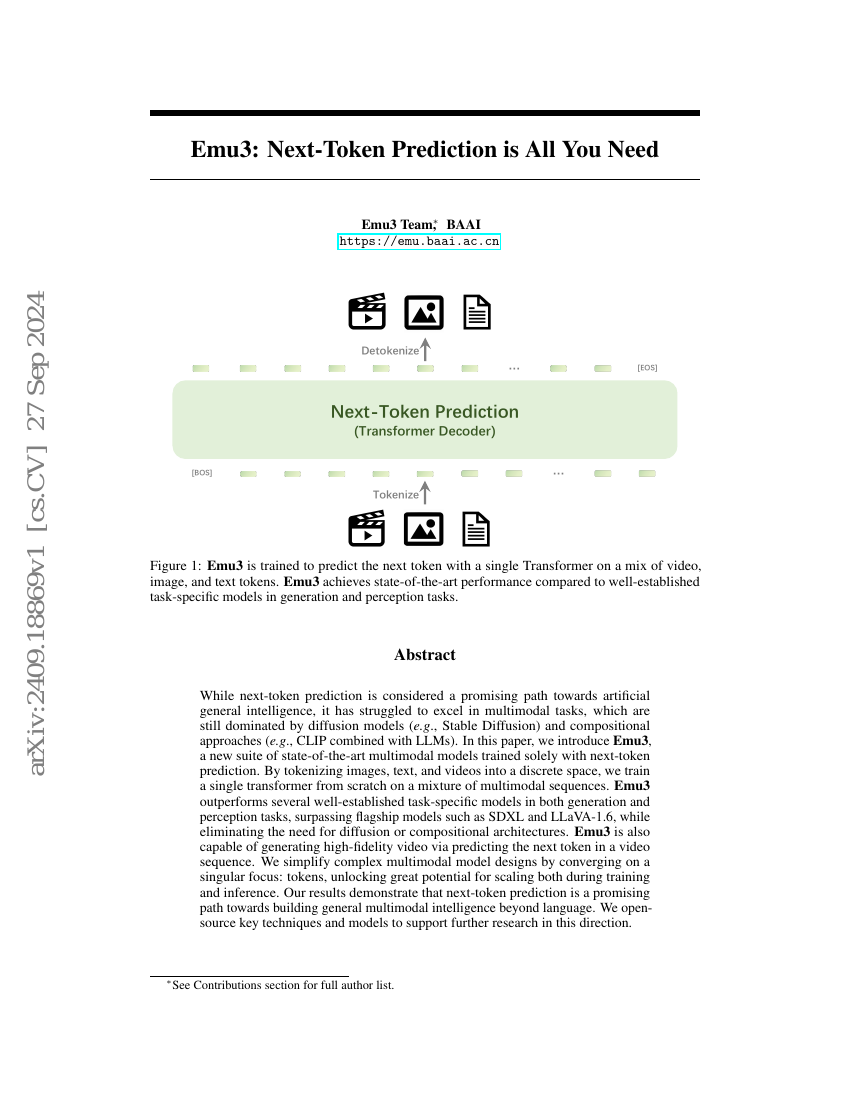
Emu3: Next-Token Prediction is All You Need