Command Palette
Search for a command to run...
Visual Autoregressive Modeling: Scalable Image Generation via Next-Scale Prediction
Visual Autoregressive Modeling: Scalable Image Generation via Next-Scale Prediction
Keyu Tian Yi Jiang Zehuan Yuan Bingyue Peng Liwei Wang
Abstract
We present Visual AutoRegressive modeling (VAR), a new generation paradigm that redefines the autoregressive learning on images as coarse-to-fine "next-scale prediction" or "next-resolution prediction", diverging from the standard raster-scan "next-token prediction". This simple, intuitive methodology allows autoregressive (AR) transformers to learn visual distributions fast and can generalize well: VAR, for the first time, makes GPT-style AR models surpass diffusion transformers in image generation. On ImageNet 256×256 benchmark, VAR significantly improve AR baseline by improving Fréchet inception distance (FID) from 18.65 to 1.73, inception score (IS) from 80.4 to 350.2, with 20× faster inference speed. It is also empirically verified that VAR outperforms the Diffusion Transformer (DiT) in multiple dimensions including image quality, inference speed, data efficiency, and scalability. Scaling up VAR models exhibits clear power-law scaling laws similar to those observed in LLMs, with linear correlation coefficients near −0.998 as solid evidence. VAR further showcases zero-shot generalization ability in downstream tasks including image in-painting, out-painting, and editing. These results suggest VAR has initially emulated the two important properties of LLMs: Scaling Laws and zero-shot generalization. We have released all models and codes to promote the exploration of AR/VAR models for visual generation and unified learning.
One-sentence Summary
Peking University and Bytedance propose Visual AutoRegressive modeling (VAR), which redefines autoregressive image generation as coarse-to-fine next-scale prediction rather than raster-scan next-token prediction, enabling GPT-style AR models to surpass diffusion transformers on ImageNet 256×256 with FID improving from 18.65 to 1.73 and 20× faster inference, while exhibiting LLM-like scaling laws and zero-shot generalization.
Key Contributions
-
The paper presents Visual AutoRegressive modeling, a GPT-style image generation framework that replaces raster-scan next-token prediction with coarse-to-fine next-scale or next-resolution prediction. This change lets autoregressive transformers learn visual distributions more efficiently while retaining strong generalization.
-
Results show that VAR makes autoregressive transformers surpass Diffusion Transformer baselines on image synthesis, improving ImageNet 256x256 FID from 18.65 to 1.73 and IS from 80.4 to 350.2 while providing about 20x faster inference. The work reports advantages over DiT in image quality, inference speed, data efficiency, and scalability.
-
The study demonstrates LLM-like properties in visual modeling, including clear power-law scaling with correlation coefficients near -0.998 and zero-shot generalization to image in-painting, out-painting, and editing. The work also releases models and code to support research on visual autoregressive learning.
Introduction
Autoregressive large language models have shown strong scalability and generalization by predicting the next token in a sequence, which makes them valuable for many AI applications. The computer vision community has tried to replicate this success with autoregressive visual models, especially for image and video generation. These models are important because they could provide language-model-like flexibility and scalability for visual creation, understanding, and multi-modal systems.
Earlier visual autoregressive models, such as VQGAN and DALL-E, convert images into discrete tokens and then flatten the 2D token grids into 1D sequences. This mirrors text modeling, but it imposes an artificial raster-scan order on images and overlooks the coarse-to-fine way humans often perceive visual structure. As a result, these models have not shown clear scaling laws comparable to language models, and their visual generation quality has often lagged behind strong diffusion models.
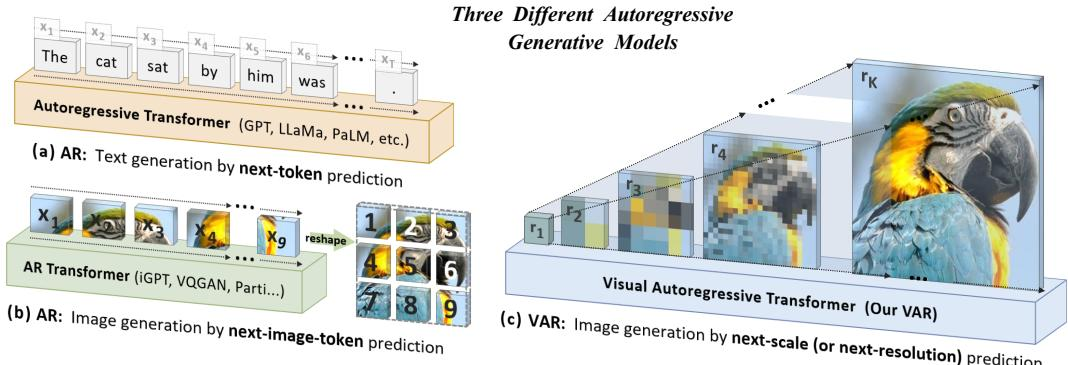
The authors introduce Visual AutoRegressive modeling, or VAR, to rethink the ordering of visual data. Instead of next-token prediction, VAR performs next-scale prediction by encoding an image into multi-scale token maps and progressively generating higher-resolution maps from lower-resolution ones. This coarse-to-fine design preserves more natural image structure while still using a GPT-style transformer. VAR achieves strong ImageNet results, faster inference, and better scaling than prior autoregressive visual models, and it is reported to surpass Diffusion Transformer baselines in image quality, data efficiency, and speed. The work also provides evidence for scaling laws and zero-shot generalization in visual autoregressive models, along with an open-source toolkit.
Method
The authors organize the method as a two-stage autoregressive image generation pipeline. Rather than treating each discrete token as the next item in a flattened one-dimensional sequence, they treat an entire resolution scale as one autoregressive step. The overall framework therefore contains a multi-scale visual tokenizer and a visual autoregressive transformer. Refer to the framework diagram.
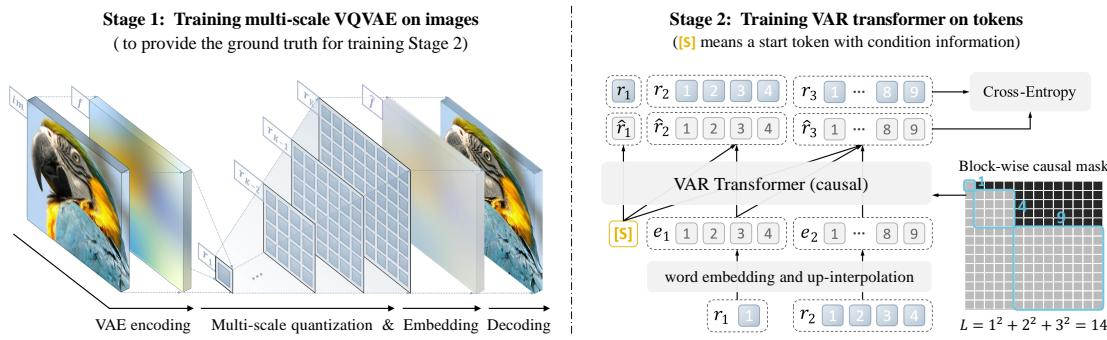
In the tokenizer stage, the authors convert a continuous image into K discrete token maps. An encoder maps the image to a feature map f, and a multi-scale quantizer converts f into R = (r_1, r_2, ..., r_K), where each r_k is a discrete map at resolution h_k x w_k and the final scale r_K matches the original feature map resolution. At each spatial location, the quantizer selects the nearest codebook vector:
q(i,j)=argv∈[V]min∥lookup(Z,v)−f(i,j)∥2.A shared codebook is used across all scales, so every scale draws tokens from the same vocabulary. The quantization pathway is residual and prefix-consistent, meaning that the representation at scale k is tied to the information accumulated from earlier scales. The tokenizer is trained with a compound objective that combines image reconstruction error, feature reconstruction error, perceptual loss, and discriminative loss. The result of this stage is a set of ground-truth multi-scale token maps used to supervise the subsequent autoregressive transformer.
In the autoregressive stage, the prediction unit becomes an entire token map rather than a single token. The authors factorize the likelihood over the K scales as:
p(r1,…,rK)=k=1∏Kp(rk∣r1,…,rk−1).For the k-th autoregressive step, the transformer conditions on the previous scale token maps r_1 through r_{k-1} and predicts all tokens in r_k in parallel. Each scale is associated with a positional embedding map, so the model can maintain spatial structure without flattening the token grid into a one-dimensional sequence. During training, a start token embedding carries the generation condition, such as a class embedding. The transformer input is ([s], r_1, ..., r_{K-1}), and the target is (r_1, ..., r_K). The predicted token distributions are optimized with cross-entropy loss.
A blockwise causal attention mask is used during transformer training. This mask restricts tokens at scale k to attend only to the start token and to tokens from scales 1 through k, preventing leakage from future scales and preserving the autoregressive factorization. During inference, the model generates scale r_1, then r_2, then r_3, and so on. Since all tokens inside a scale are generated in parallel, the number of autoregressive iterations is K rather than the total number of tokens. KV caching can be used across scales, and the causal mask is not required during inference.
The transformer backbone follows a simple decoder-only design with adaptive normalization. Class conditioning is introduced through the start token and also used as adaptive normalization conditioning. Queries and keys are normalized to unit vectors before attention to improve training stability. The authors deliberately avoid more complex language-model components such as rotary position embeddings, SwiGLU MLPs, or RMSNorm, keeping the architecture close to standard visual autoregressive transformer designs while focusing on the next-scale prediction mechanism.
The model size follows a depth-dependent scaling rule:
w=64d,h=d,dr=0.1d/24.Under this rule, the approximate parameter count is:
N(d)=18dw2=73728d3.For training, the authors use AdamW with a base learning rate of 10−4 per batch size 256, β1=0.9, β2=0.95, and weight decay 0.05. Batch sizes are typically set in the range of 768 to 1024. The tokenizer uses a shared codebook of size 4096 and a 16 times spatial downsampling ratio.
Experiment
The experiments evaluate the visual autoregressive framework on ImageNet conditional generation at multiple resolutions, comparing it against GAN, diffusion, masked-prediction, and autoregressive baselines. These comparisons show that the proposed formulation improves over conventional autoregressive modeling and competes favorably with diffusion transformers in image quality, diversity, semantic consistency, speed, and data efficiency. Additional scaling-law and ablation studies on model size, training compute, and key components confirm that VAR follows predictable performance gains with scale and derives its main advantage from coarse-to-fine autoregressive generation rather than from incidental architectural details.
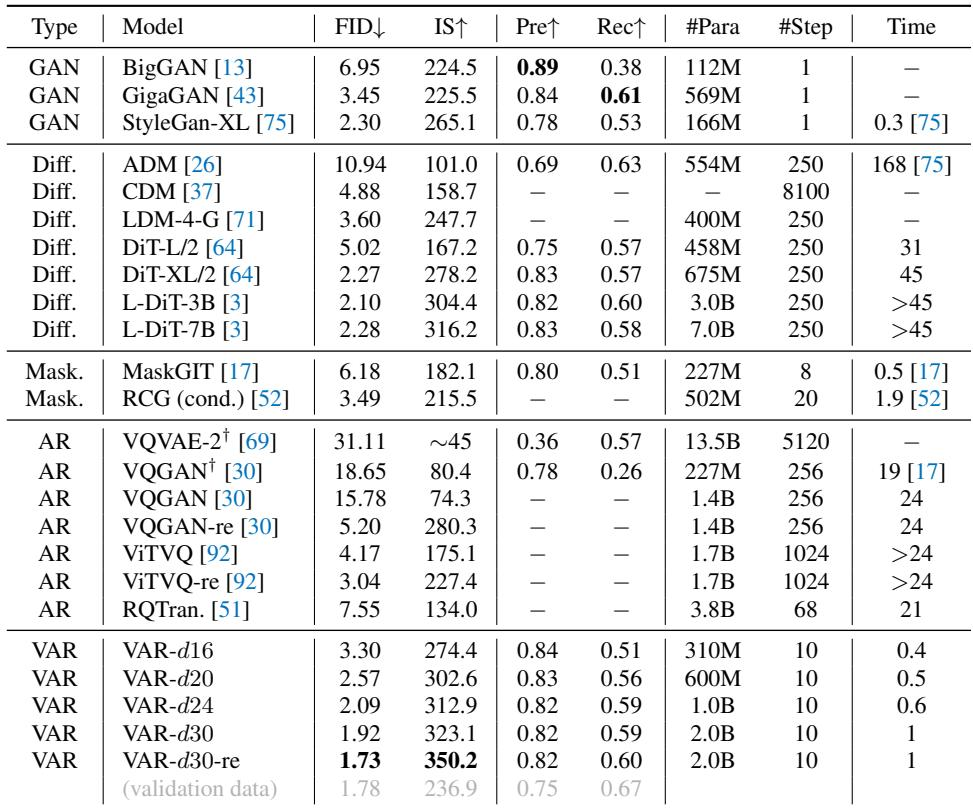
On class conditional ImageNet 256x256, VAR shows the strongest overall generation quality among compared GANs, diffusion models, masked prediction models, and autoregressive models, with better FID and IS while keeping precision and recall competitive. It also generates images with far fewer model runs and much lower wall clock time than diffusion and conventional autoregressive approaches, despite having more parameters in some settings. The comparison suggests VAR advances the autoregressive family by surpassing strong diffusion transformers in quality, speed, and scalability. VAR achieves the best FID and IS among the compared model families while maintaining decent precision and recall. VAR uses far fewer generation steps and much less wall clock time than diffusion and autoregressive baselines, approaching efficient GAN speed. VAR outperforms DiT variants in FID, IS, and scalability, with DiT showing marginal or negative gains beyond larger parameter sizes.
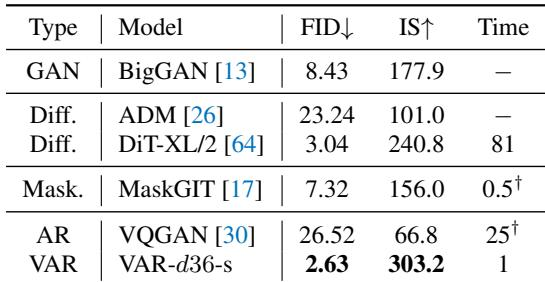
On the 512x512 conditional ImageNet benchmark, the reported VAR variant gives the best FID and IS among the compared model families. It also produces much better quality than traditional autoregressive and diffusion baselines while being substantially faster than the diffusion transformer entry. The result is notable because this VAR model uses a shared AdaLN layer due to resource limitations. VAR achieves the lowest FID and highest IS among the listed 512x512 models. VAR is much faster than DiT-XL/2 while also reporting better FID and IS.
Replacing the baseline autoregressive transformer with VAR sharply lowers FID while using only a small fraction of inference cost. Further VAR components progressively improve FID, and scaling up the model reaches the best results while remaining much faster than the baseline. VAR gives a large FID improvement over the AR baseline at very low inference cost. AdaLN, top-k sampling, CFG, and attention normalization each move FID lower with only modest cost changes. Scaling VAR produces the strongest FID while still using far less cost than the baseline.
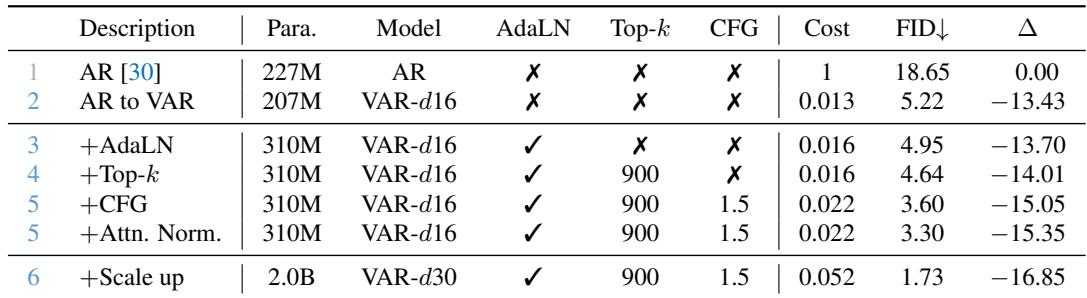
Experiments on class-conditional ImageNet at 256x256 and 512x512 evaluate VAR against GANs, diffusion models, masked prediction models, and autoregressive models, showing that VAR delivers stronger overall image quality than leading diffusion and autoregressive baselines while keeping generation efficient. Ablations confirm that the core VAR formulation greatly improves over a conventional autoregressive transformer at much lower inference cost, and additional components such as AdaLN, top k sampling, classifier-free guidance, and attention normalization further enhance quality with modest overhead. Scaling VAR yields the strongest qualitative performance while remaining substantially faster than diffusion transformer baselines, supporting its advantage in quality, efficiency, and scalability.