Command Palette
Search for a command to run...
Evaluating the Deductive Competence of Large Language Models
Evaluating the Deductive Competence of Large Language Models
Spencer M. Seals Valerie L. Shalin
Abstract
The development of highly fluent large language models (LLMs) has prompted increased interest in assessing their reasoning and problem-solving capabilities. We investigate whether several LLMs can solve a classic type of deductive reasoning problem from the cognitive science literature. The tested LLMs have limited abilities to solve these problems in their conventional form. We performed follow up experiments to investigate if changes to the presentation format and content improve model performance. We do find performance differences between conditions; however, they do not improve overall performance. Moreover, we find that performance interacts with presentation format and content in unexpected ways that differ from human performance. Overall, our results suggest that LLMs have unique reasoning biases that are only partially predicted from human reasoning performance and the humangenerated language corpora that informs them.
One-sentence Summary
Researchers at Wright State University, Oak Ridge Institute for Science and Education, AI Institute - University of South Carolina, and Air Force Research Laboratory evaluate LLMs on classic deductive reasoning tasks from cognitive science, finding that changes to presentation format and content fail to improve overall performance and that LLMs exhibit unique reasoning biases only partially predictable from human reasoning or their training corpora.
Key Contributions
-
The paper evaluates several large language models on a standardized Wason conditional reasoning task, testing modus ponens, modus tollens, denial of the antecedent, and affirmation of the consequent while controlling for prompt based confounds.
-
A controlled study varies presentation format and rule content, including familiar and unfamiliar relationships between antecedents and consequents, to test whether these changes improve deductive reasoning performance.
-
The results show that format and content alter accuracy in unexpected ways without improving overall performance, revealing LLM reasoning biases that diverge from human cognitive science patterns.
Introduction
Highly fluent large language models (LLMs) have increased interest in testing their reasoning and problem-solving abilities, especially through tasks that probe deductive competence. The Wason selection task is useful for this because it maps onto conditional reasoning patterns, such as modus ponens and modus tollens, and can be standardized to reduce superficial language cues. Prior work has found mixed results: some LLMs perform well on realistic problems but poorly on unrealistic ones, and overall performance can shift sharply with task format. A key limitation is that earlier studies may conflate reasoning ability with factors such as prompt structure and whether the problem content feels familiar to humans, particularly social-rule content that humans find especially intuitive. The authors address this by examining how specifically social-rule content affects LLM reasoning, testing alternative presentation formats, and evaluating multiple candidate models to check for algorithmic effects. They find that social content does help, but less than human-centered expectations would suggest, and that format effects interact with content in surprising, non-human ways.
Experiment
The experiments evaluate large language models on Wason-style rule reasoning using matched realistic, shuffled, and arbitrary problem content, multiple presentation formats, and domain conditional PMI metrics. The results show that models partially resemble human patterns, performing better on social and realistic rules than arbitrary or shuffled ones, but overall performance remains low and does not match the magnitude observed in human subjects. Additional analyses reveal that presentation format and antecedent selection interact with problem content in ways not predicted by human reasoning, with similar divergent patterns across models.
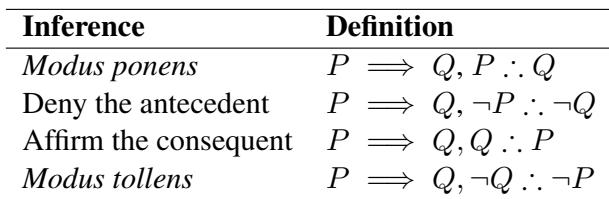
The context describes the Wason selection task as a test of deductive reasoning that distinguishes logically valid inferences from common fallacies. It notes that only modus ponens and modus tollens are valid, while denying the antecedent and affirming the consequent are not. The cited discussion also reports that LLMs show low and consistent accuracy across models, with reasoning patterns that diverge from human behavior. Only modus ponens and modus tollens are valid inference forms in the task. LLMs select antecedent cards less often than humans, especially outside social rule problems.
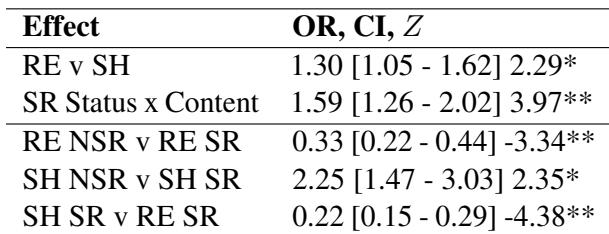
The statistical analysis evaluates social rule status and rule content using a reasoning performance metric. It finds a beneficial association for realistic rules relative to shuffled rules and a significant interaction between social status and content. The overall pattern is consistent across language models and problem familiarity, even though absolute performance remains low. Realistic rules show a beneficial effect relative to shuffled rules. Social rule status interacts with content type, and the pattern is similar across language models.
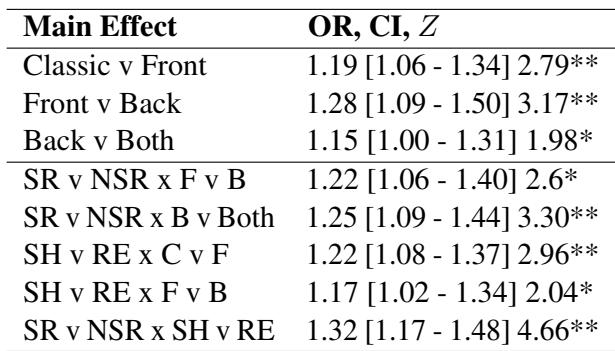
The analysis found that presentation format significantly affected performance, while social-rule status and content type did not have significant main effects on their own. Performance varied through interactions between presentation format and both social-rule status and content type, showing that the benefit of a format depended on the kind of rule and content involved. Performance was broadly consistent across language models and familiarity levels, suggesting that these differences were not mainly driven by model identity or prior exposure. Presentation-format comparisons were statistically reliable, with higher modeled odds reported for each adjacent format contrast. Social-rule status interacted with presentation format in the front-versus-back and back-versus-both comparisons. Shuffled versus realistic content interacted with presentation format in the classic-versus-front and front-versus-back comparisons. Adding model identity or problem familiarity did not improve model fit, indicating limited variation across these factors.
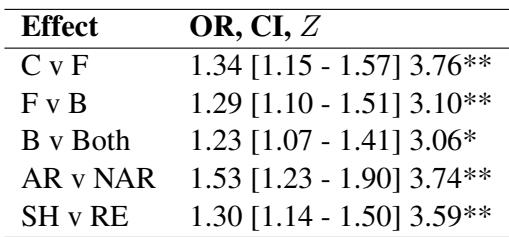
Antecedent selection varied with both presentation format and problem content. Significant differences appeared among classic, front, and back formats and between arbitrary, non-arbitrary, shuffled, and realistic problems, while the best fitting model also included an interaction between format and content. Social rule status alone was not significant, and the observed patterns were broadly consistent across models. Presentation format significantly influenced antecedent selection across classic, front, and back conditions. Content type significantly differed between arbitrary and non-arbitrary problems and between shuffled and realistic problems. Presentation format and content type interacted, so format effects depended on problem type. Social rule status alone did not show a significant main effect.
The experiments use the Wason selection task to examine language-model deductive reasoning across inference types, rule realism, social-rule status, and presentation format. They show generally low but model-consistent accuracy, with realistic content associated with better reasoning than shuffled or arbitrary content. Presentation format matters mainly through interactions with rule content, especially for antecedent selection, while social-rule status has limited independent effect. These patterns remain stable across models and familiarity, suggesting they are not driven mainly by model identity or prior exposure.