Command Palette
Search for a command to run...
A Probabilistic Earley Parser as a Psycholinguistic Model
A Probabilistic Earley Parser as a Psycholinguistic Model
John Hale
Abstract
In human sentence processing, cognitive load can be defined many ways. This report considers a definition of cognitive load in terms of the total probability of structural options that have been disconfirmed at some point in a sentence: the surprisal of word w_i given its prefix w_0...i 1 on a phrase-structural language model. These loads can be efficiently calculated using a probabilistic Earley parser (Stolcke, 1995) which is interpreted as generating predictions about reading time on a word-by-word basis. Under grammatical assumptions supported by corpus frequency data, the operation of Stolcke's probabilistic Earley parser correctly predicts processing phenomena associated with garden path structural ambiguity and with the subject/object relative asymmetry.
One-sentence Summary
Researchers at Johns Hopkins University demonstrate that Stolcke's probabilistic Earley parser, interpreted as generating word-by-word reading-time predictions from the surprisal of word wi given its prefix w0...i−1 on a phrase-structural language model, correctly predicts garden path structural ambiguity and subject/object relative asymmetry in human sentence processing.
Key Contributions
-
The paper contributes a computational definition of cognitive load in sentence processing, treating load at each word as the total probability of phrase-structural alternatives disconfirmed by the prefix. This load is computed efficiently from prefix probabilities produced by a probabilistic Earley parser.
-
The paper develops a total-parallelism language model in which hierarchical PCFG probabilities generate word-by-word processing predictions. Garden-path difficulty and subject/object relative asymmetries are explained by momentary disconfirmation rather than by the order of reanalysis.
-
Using corpus frequency data and empirically derived grammars, the model characterizes structural ambiguity and subject/object relative processing phenomena. The results support the use of phrase-level contingent frequencies to account for comprehension effects and generate testable psycholinguistic predictions.
Introduction
In human sentence comprehension and speech recognition, systems must connect a speaker’s knowledge of grammar with the incremental performance of processing sentences word by word. This matters because parsing determines how ambiguity is resolved and how difficult a sentence feels during real-time reading or listening. Prior work has often separated grammar from processing by appealing to autonomous performance principles, while traditional n-gram language models lack hierarchical syntactic structure and probabilistic context-free grammars were inconvenient for online use because they assigned probabilities mainly to complete sentences. Frequency-based models also left unresolved whether phrase-level statistics are necessary to explain comprehension effects beyond locality and other constraints.
The authors leverage Stolcke’s probabilistic Earley parser and a probabilistic context-free grammar to model sentence processing as an eager, probability-driven process. They compute prefix probabilities and word-to-word surprisal, treating processing difficulty as the online disconfirmation of less likely syntactic alternatives. Their main contribution is a total-parallelism parsing theory in which phrase-level probabilistic grammar can account for structural ambiguity and performance effects while requiring minimal extragrammatical machinery.
Method
The authors leverage a probabilistic Earley parser as the core model. The framework combines a probabilistic context-free grammar, an Earley chart that maintains active parsing hypotheses, and a probability accumulation procedure that tracks prefix probabilities over the grammar’s rules. Rule probabilities are estimated from relative frequencies in a parsed corpus, so the grammar is trained by converting observed syntactic choices into conditional probabilities over expansions of nonterminal categories.
An Earley state records the input position processed so far, the grammar rule under consideration, the dot position indicating how much of the rule has been recognized, and the left edge of the substring generated by the rule. The parser has three operations. Predict introduces new states for grammar rules that can expand the nonterminal immediately to the right of the dot. Scan advances the dot across an input word when the next required symbol matches that word. Complete propagates successful bottom-up recognitions back through states that were expecting the newly recognized constituent. These operations allow the parser to maintain all derivations compatible with the input prefix.
The probabilistic extension adds two quantities to each state. The first is α, the prefix or forward probability, which stores the total probability of derivations that are consistent with the input seen so far and that lead to that state. The second is γ, the inside probability, which stores the probability of the internal structure of a partially completed phrase. Prediction multiplies the current prefix probability by the probability of the selected grammar rule. Scanning does not change probabilities. Completion combines a top-down prediction with a bottom-up recognition by multiplying the expecting state’s α value by the γ value of the completed constituent. When several antecedent states can produce the same new state, their contributions are summed.
The prefix probability at position n is therefore the sum of the probabilities of all derivations compatible with the observed prefix. In equation form:
αn=d∈D(x1:n)∑P(d)where x1:n is the input prefix and D(x1:n) is the set of derivations compatible with that prefix. Because Earley paths correspond one-to-one to leftmost derivations, the parser can compute prefix probabilities by summing over parser operations rather than enumerating trees explicitly.
The model also defines a linking hypothesis between parser behavior and processing difficulty. The total prefix probability is interpreted as the probability mass of all analyses that remain compatible with the input. When a word reduces this probability mass, the parser must disconfirm previously compatible structures. Cognitive load is modeled as the logarithmic ratio of prefix probabilities before and after a word:
log(αnαn−1)This quantity captures the combined difficulty of disconfirming the structures that were alive before the word but incompatible afterward.
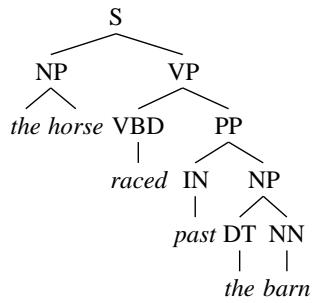
To illustrate the mechanism, the method examines a case in which a word admits two structural readings. One reading treats the relevant verb as the main predicate of the sentence. Refer to the figure below.
The competing reading treats the same word as a past participle inside a reduced relative clause. As shown in the figure below:
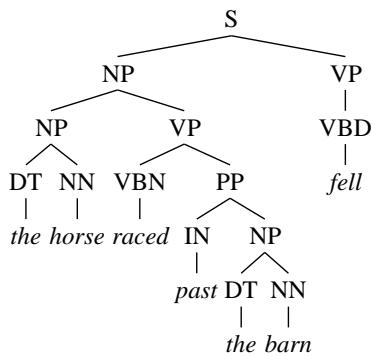
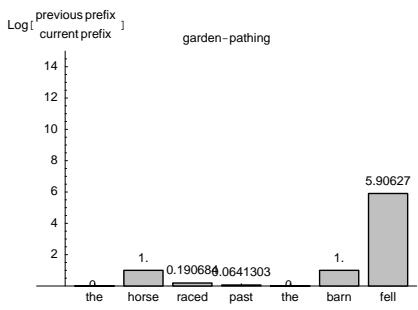
Under the simple grammar, both readings remain available until the later word makes one interpretation impossible. The main-verb structure is initially much more probable, but it cannot survive the final word, while the reduced relative structure does survive. The resulting drop in prefix probability produces a high predicted processing cost at the word that triggers the disconfirmation. The prediction profile from the simple grammar is shown below.
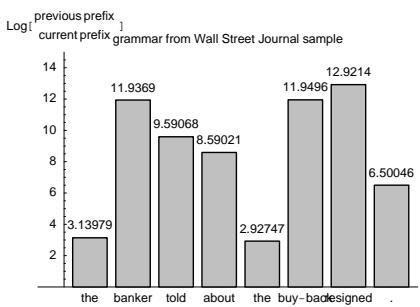
The same logic is applied when the parser uses a much richer empirical grammar. In that setting, many more grammatical alternatives can remain active at intermediate points, so the parser may disconfirm many more hypotheses at each word. Lexical context also contributes to surprisal because less predictable words carry more information. Nevertheless, the structural garden path effect remains visible as a large prefix probability drop at the word that forces rejection of the higher probability analysis. As shown in the figure below:
Experiment
The experiments evaluate a probabilistic parser's predictions for garden-path reduced relative clauses, comparing ambiguous main-verb-plus-reduced-relative sentences with unambiguous subject-relative controls. They show that inserting material such as who was suppresses the competing main-verb reading and predicts faster processing of the control, while a fully empirical grammar still predicts the garden-path effect at the final verb despite larger lexical ambiguity. Overall, the results support total parallelism by accounting for structural garden-pathing as the simultaneous availability and cancellation of competing interpretations.