Command Palette
Search for a command to run...
A Random Matrix Theory Perspective on the Consistency of Diffusion Models
A Random Matrix Theory Perspective on the Consistency of Diffusion Models
Binxu Wang Jacob A. Zavatone-Veth Cengiz Pehlevan
Abstract
Diffusion models trained on different, non-overlapping subsets of a dataset often produce strikingly similar outputs when given the same noise seed. We trace this consistency to a simple linear effect: the shared Gaussian statistics across splits already predict much of the generated images. To formalize this, we develop a random matrix theory (RMT) framework that quantifies how finite datasets shape the expectation and variance of the learned denoiser and sampling map in the linear setting. For expectations, sampling variability acts as a renormalization of the noise level through a self-consistent relation σ2↦κ(σ2), explaining why limited data overshrink low-variance directions and pull samples toward the dataset mean. For fluctuations, our variance formulas reveal three key factors behind cross-split disagreement: anisotropy across eigenmodes, inhomogeneity across inputs, and overall scaling with dataset size. Extending deterministic-equivalence tools to fractional matrix powers further allows us to analyze entire sampling trajectories. The theory sharply predicts the behavior of linear diffusion models, and we validate its predictions on UNet and DiT architectures in their non-memorization regime, identifying where and how samples deviates across training data split. This provides a principled baseline for reproducibility in diffusion training, linking spectral properties of data to the stability of generative outputs.
One-sentence Summary
Researchers at Harvard's Kempner Institute develop a random matrix theory framework that explains the striking consistency of diffusion models trained on non-overlapping data splits, formalizing finite-data effects through a self-consistent noise renormalization σ2↦κ(σ2) and identifying anisotropy, input inhomogeneity, and dataset-size scaling as spectral drivers of cross-split disagreement, with predictions validated on UNet and DiT architectures to establish a principled reproducibility baseline for generative training.
Key Contributions
- The work identifies shared Gaussian statistics and stable linear denoising maps as a concrete mechanism behind similar outputs from diffusion models trained on disjoint dataset splits with the same noise seed.
- A random matrix theory framework quantifies finite-data effects on the learned denoiser and sampling map in linear diffusion models, including self-consistent noise renormalization, eigenmode anisotropy, input inhomogeneity, and dataset-size scaling.
- The predictions are validated on linear diffusion models and on UNet and DiT architectures in the non-memorization regime, identifying spectral directions where cross-split samples deviate and establishing a reproducibility baseline for diffusion training.
Introduction
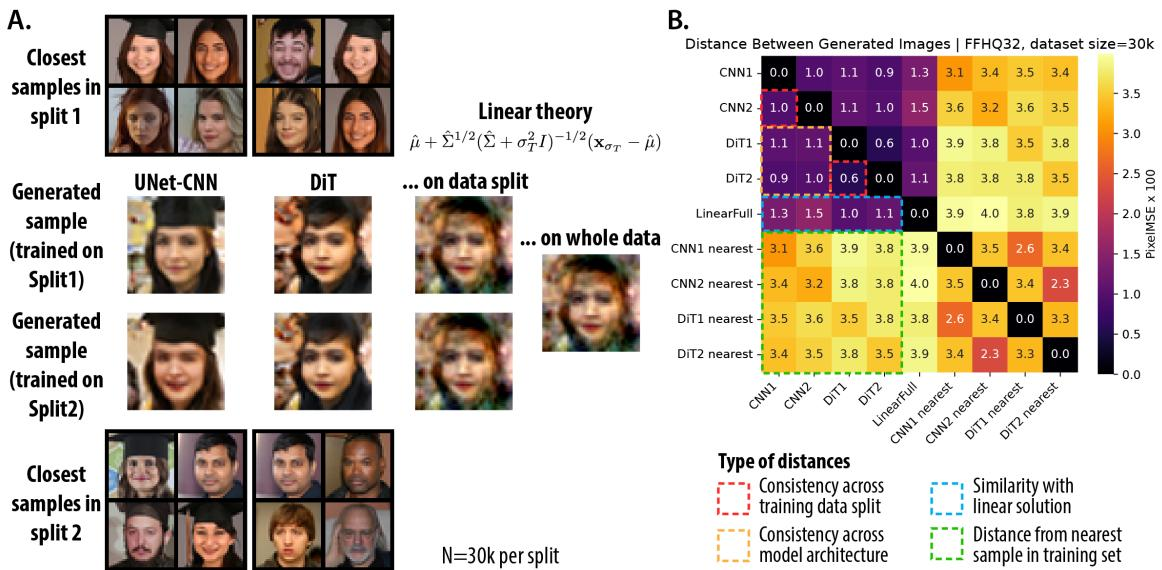
Diffusion models and flow matching now support generation in domains such as images, video, and proteins, and they show an unusual form of stability: independently trained models often map the same Gaussian noise seed to similar outputs. This run-to-run consistency matters because it suggests the learned vector fields capture stable statistical structure in the data, which affects claims about generalization, memorization, and creative variability. Prior work observed this phenomenon, but it lacked a clear finite-sample theory explaining why it occurs, while GANs and VAEs are complicated further by non-identifiable latent coordinates that can rotate across training runs. The authors leverage random matrix theory and a linear denoiser analysis to show that shared Gaussian statistics already predict cross-split agreement, and that finite data introduce deviations through a renormalized noise scale and a structured fluctuation law. They also extend deterministic equivalence to fractional matrix powers and validate the predicted effects in CNN and DiT diffusion models.
Method
The authors construct an analytical pipeline for studying how finite training data reshape score based diffusion models. The starting point is the EDM formulation, where a target data distribution p0(x) is progressively blurred by Gaussian noise. For each noise scale σ>0, the noised distribution is
pσ(x)=(p0∗N(0,σ2I))(x)=∫p0(y)N(x∣y,σ2I)dy.The central object of the diffusion model is the score function ∇xlogpσ(x). Sampling is then described by the probability flow ODE
dσdx=−σ∇xlogpσ(x).Integrating this trajectory from a large noise scale σT down to σ=0 maps Gaussian noise to clean samples. In practice, the score is not learned directly. The authors first train a denoiser Dθ by minimizing the denoising score matching objective
Lσ=Ex0∼p0,z∼N(0,I)∥Dθ(x0+σz;σ)−x0∥22.Once the denoiser is learned, Tweedie’s formula converts it into a score estimate,
sθ(x,σ)=σ2Dθ(x,σ)−x.Across practical diffusion training, the scale specific losses are combined through a weighting function w(σ), giving an overall loss of the form
L=∫σdσw(σ)Lσ.This establishes the main training process: a neural denoiser is trained to remove Gaussian perturbations, and the trained denoiser is then converted into a score function that drives deterministic sampling.
To make the finite data behavior analytically tractable, the authors replace the neural denoiser with a linear affine denoiser at each noise scale,
D(x;σ)=Wσx+bσ.In this setting, the learned denoiser depends on the training data only through its empirical mean and empirical covariance. Given an empirical covariance Σ^, the optimal linear denoiser is
DΣ^∗(x;σ)=μ^+(Σ^+σ2I)−1Σ^(x−μ^).The authors isolate the effect of covariance fluctuation by fixing the mean and studying how random realizations of Σ^ alter denoiser outputs and final samples. They also identify the sampling map induced by the optimal linear denoiser. Starting from initial noise xσT, the PF ODE gives the analytic trajectory
xΣ^(xσT,σ)=μ^+(Σ^+σ2I)1/2(Σ^+σT2I)−1/2(xσT−μ^).Taking σ→0 recovers the final sampling map. Thus, in the linear case, the entire training and sampling process reduces to how the empirical covariance fluctuates across independent dataset realizations.
The core analytical tool used by the authors is deterministic equivalence. This method replaces random matrix expressions involving Σ^ with deterministic expressions involving the population covariance Σ. The central replacement is
Σ^(Σ^+λI)−1≍Σ(Σ+κ(λ)I)−1,where the scalar κ(λ) absorbs the stochastic effect of using finite samples. It is determined by the self consistent equation
κ(λ)−λ=γκ(λ)tr[Σ(Σ+κ(λ)I)−1],γ=d/n.Here d is the data dimension and n is the number of samples. The mapping λ↦κ(λ) can be interpreted as a renormalized noise scale. For trace like quantities, finite sample noise in Σ^ is replaced by an increased effective noise level in the population denoiser. This is analogous to a self energy correction, where randomness in the empirical covariance is integrated into a scalar correction term.
The authors use this machinery to compute the expected behavior of the denoiser across dataset realizations. For a fixed probe direction v, the expectation satisfies
EΣ^[v⊤DΣ^∗(x;σ)]≍v⊤[μ+Σ(Σ+κ(σ2)I)−1(x−μ)].This result shows that finite data do not merely add noise to the denoiser. In expectation, they act by replacing the true noise scale σ2 with the renormalized scale κ(σ2). Because κ(σ2) is larger than σ2, the finite sample denoiser shrinks output components more aggressively, especially along low variance directions. This produces a bias toward the dataset mean, similar to adding an adaptive ridge penalty to the denoising objective.
The authors also derive the variance of the denoiser across independent training sets. They introduce the degrees of freedom functions
df1(λ)=Tr[Σ(Σ+λI)−1], df2(λ)=Tr[Σ2(Σ+λI)−2],and
df2(λ,λ′)=Tr[Σ2(Σ+λI)−1(Σ+λ′I)−1].The variance of the linear denoiser output along direction v at input location x can be written as
VarΣ^[v⊤DΣ^∗(x;σ)]≍n−df2(κ(σ2))κ(σ2)2◊(v,κ(σ2),Σ)◊(x−μ,κ(σ2),Σ),where the spectral kernel is
◊(u,κ,Σ)=u⊤(Σ+κI)−2Σu.This expression factorizes into three interpretable pieces. The first factor is a global scale controlled by sample size and effective noise. The second factor is an anisotropy term depending on the probe direction v. The third factor is an inhomogeneity term depending on the displacement of the input from the mean. When the probe direction aligns with an eigenvector of Σ with eigenvalue λk, the anisotropy kernel reduces to a function that is maximized when λk is comparable to κ(σ2). This means the largest denoiser disagreement occurs along modes whose data variance matches the renormalized noise scale.
The same perspective is extended from single step denoising to the full sampling map. For large terminal noise σT, the linear sampling map is approximated by
xΣ^(xσT,0)=μ+Σ^1/2(Σ^+σT2I)−1/2(xσT−μ)≈μ+Σ^1/2xˉ,where
xˉ=σTxσT−μ.The authors then use integral representations for fractional powers of covariance matrices to derive the expectation of the generated sample:
EΣ^[xΣ^(xσT,0)]≍μ+π2∫0∞Σ(Σ+κ(u2)I)−1xˉdu.Compared with the population sampling map, this expression integrates over a stronger shrinkage operator because κ(u2)>u2. Therefore finite data produce systematic overshrinkage toward the mean, particularly along lower variance eigenmodes.
The variance of the final sample is expressed as a double integral over effective noise variables. With κ=κ(u2) and κ′=κ(v2),
VarΣ^[v⊤xΣ^(xσT,0)]≍π24∫0∞∫0∞n−df2(κ,κ′)κκ′◊(v;κ,κ′,Σ)◊(xˉ;κ,κ′,Σ)dudv,where
◊(a;κ,κ′,Σ)=a⊤Σ(Σ+κI)−1(Σ+κ′I)−1a.Again, the variance factorizes into global scaling, probe direction anisotropy, and initial noise dependent inhomogeneity. The initial noise xˉ acts as a spatial probe of the sampling map. Inputs whose deviations align strongly with high variance eigendirections experience larger cross split disagreement. Directionally, the variance is governed by the same spectral kernel, so the final sampling map inherits the spectral structure of the denoiser fluctuation.
The empirical validation of this analytical scheme is summarized below. As shown in the figure below:
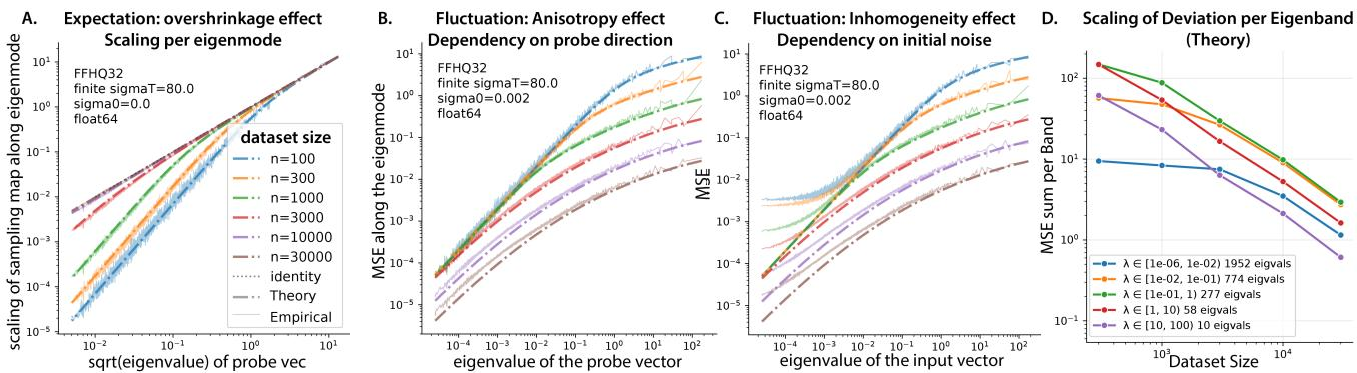
The curves compare theoretical deterministic equivalents with empirical linear diffusion computations for increasing dataset sizes. The expected scaling of the sampling map along eigenmodes shows overshrinkage toward the mean, with the strongest effect on low variance directions. The dependence of cross split mean squared error on probe eigenvalue shows that directional disagreement changes systematically across the spectrum, while the dependence on input eigenvalue shows that locations displaced along high variance modes induce larger uncertainty. The eigenband level scaling indicates that top eigenmodes can stabilize quickly with moderate data, whereas lower variance modes require substantially larger datasets before their cross split MSE decays.
Experiment
The experiments evaluate diffusion models trained on independent data splits and sampled with shared noise seeds, comparing UNet and DiT architectures, varying dataset sizes, and constructing statistically mismatched splits. These tests show that independently trained models often produce similar images, especially once training data are large enough to move beyond memorization, while deliberate mismatches in data means or variances disrupt this consistency. Numerical and network level validations further demonstrate that a Gaussian and random matrix theory framework predicts where samples vary across splits, with anisotropic and inhomogeneous deviations concentrated along data covariance eigendirections and requiring larger data sizes to resolve.