Command Palette
Search for a command to run...
LLMS GET LOST IN MULTI-TURN CONVERSATION
LLMS GET LOST IN MULTI-TURN CONVERSATION
Philippe Laban Hiroaki Hayashi Yingbo Zhou Jennifer Neville
Abstract
Large Language Models (LLMs) are conversational interfaces. As such, LLMs have the potential to assist their users not only when they can fully specify the task at hand, but also to help them define, explore, and refine what they need through multi-turn conversational exchange. Although analysis of LLM conversation logs has confirmed that underspecification occurs frequently in user instructions, LLM evaluation has predominantly focused on the single-turn, fully-specified instruction setting. In this work, we perform large-scale simulation experiments to compare LLM performance in singleand multi-turn settings. Our experiments confirm that all the top openand closed-weight LLMs we test exhibit significantly lower performance in multi-turn conversations than single-turn, with an average drop of 39% across six generation tasks. Analysis of 200,000+ simulated conversations decomposes the performance degradation into two components: a minor loss in aptitude and a significant increase in unreliability. We find that LLMs often make assumptions in early turns and prematurely attempt to generate final solutions, on which they overly rely. In simpler terms, we discover that when LLMs take a wrong turn in a conversation, they get lost and do not recover.
One-sentence Summary
Through large-scale simulations of 200,000+ conversations across six generation tasks, researchers at Microsoft Research and Salesforce Research demonstrate that all top open- and closed-weight LLMs suffer an average 39% performance drop in multi-turn settings, a degradation driven primarily by increased unreliability as models prematurely commit to early assumptions and fail to recover.
Key Contributions
-
Large-scale simulation experiments compare top open-weight and closed-weight LLMs on the same six open-ended generation tasks in single-turn and multi-turn underspecified conversations, revealing an average 39% performance drop in multi-turn interactions.
-
Analysis of 200,000+ simulated conversations separates degradation into aptitude loss and increased unreliability, identifying a "lost in conversation" pattern in which models make premature assumptions, generate verbose final attempts, and over-rely on earlier incorrect responses.
-
Additional experiments show that agent-like concatenation and lower decoding temperature do not reliably restore multi-turn robustness, supporting recommendations to prioritize multi-turn reliability alongside aptitude in LLM evaluation and development.
Introduction
Large language models increasingly serve as conversational assistants, where users often begin with vague requests and clarify their needs over multiple turns. This setting matters because many real users, especially novices, cannot fully specify their goals from the start, making multi-turn behavior a practical requirement rather than an optional feature. Prior work often evaluates multi-turn conversations as isolated subtasks, which misses underspecification and can overstate model capability. The authors leverage sharded simulation, which splits existing single-turn benchmark instructions into smaller pieces revealed gradually across conversation turns, to test the same tasks in both single-turn and multi-turn open-ended settings. Their key contribution is a large-scale evaluation showing that LLMs lose substantial reliability when instructions are revealed incrementally, revealing a gap between how models are used and how they are currently evaluated.
Dataset
-
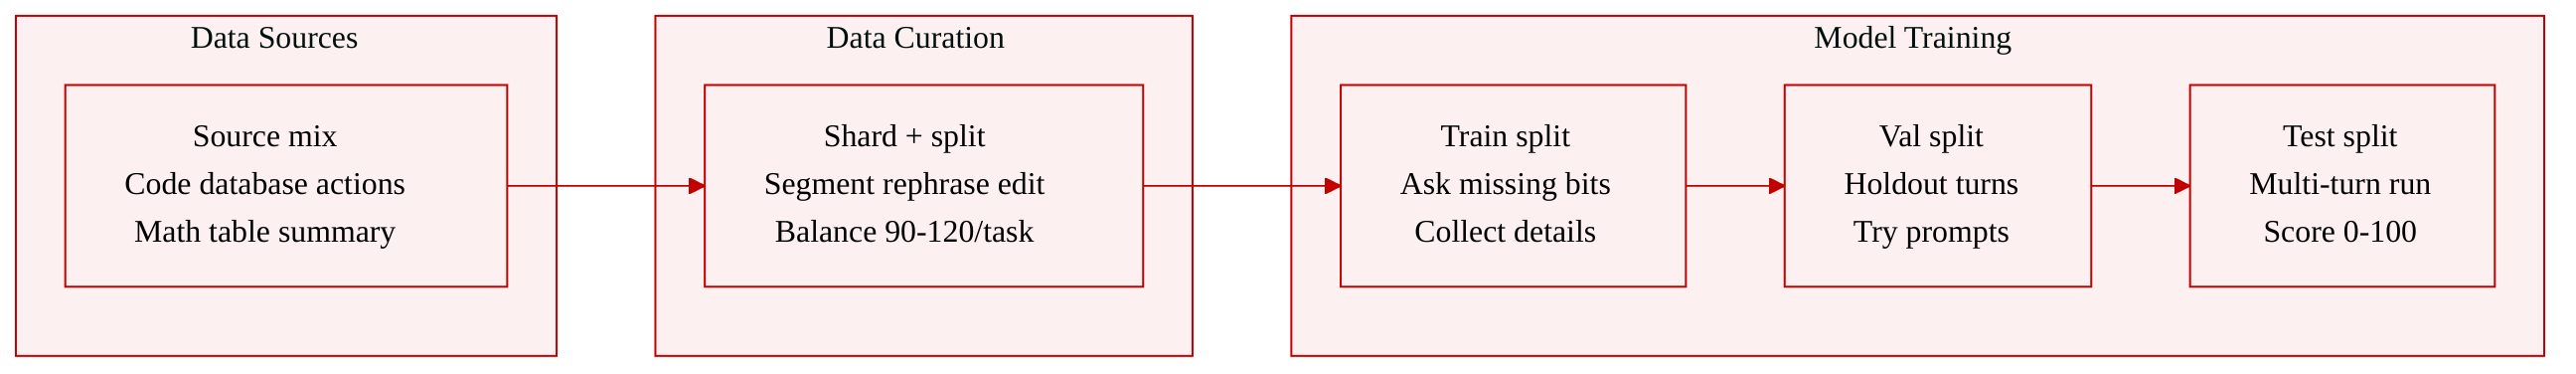
The authors construct a sharded instruction dataset for simulating underspecified, multi-turn conversations. The dataset is built by converting fully-specified single-turn instructions into multiple shards, where each shard introduces one natural information element from the original instruction.
-
The final dataset covers six generation tasks across programming and nonprogramming domains: Code, Database, Actions, Math, Data-to-text, and Summary.
-
For each task, the authors prepare 90 to 120 sharded instructions, resulting in a task-balanced experimental dataset of roughly 540 to 720 instruction examples.
-
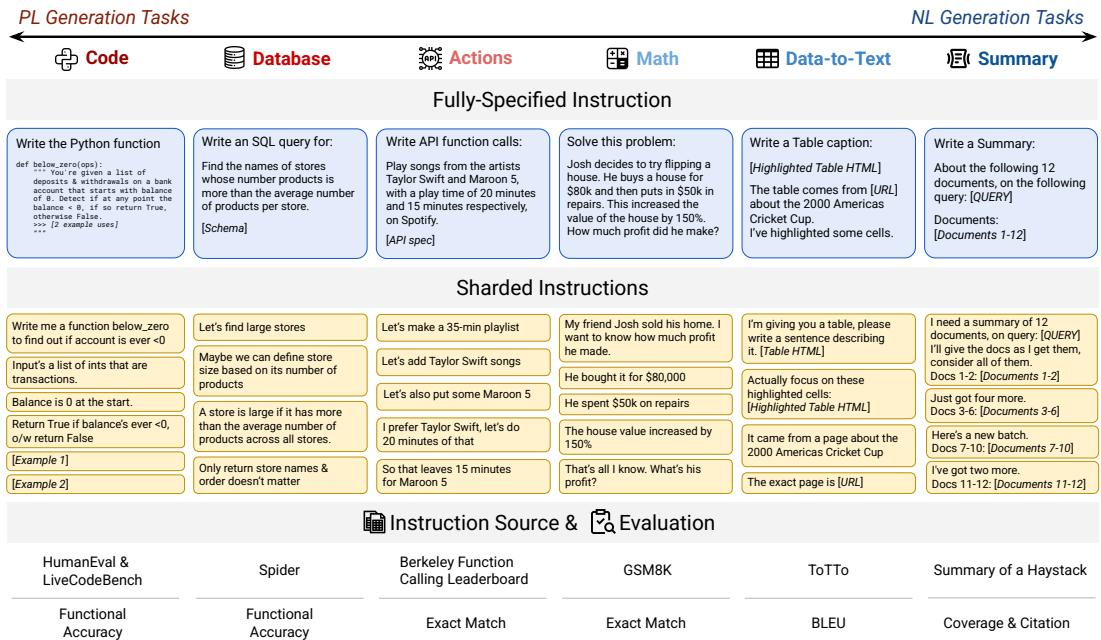
The source data come from established single-turn benchmarks:
- Code: instructions from HumanEval and LiveCodeBench.
- Database: instructions and databases from the Spider dataset.
- Actions: API schemas and user instructions from the Berkeley Function Calling Leaderboard.
- Math: elementary math word problems from GSM8K.
- Data-to-text: table-caption examples from ToTTo.
- Summary: instructions and document sets from Summary of a Haystack.
-
The sharded examples are produced through a semi-automatic process with four stages: segmentation, rephrasing, verification, and manual inspection.
-
Each sharded instruction must satisfy properties such as information preservation, clear initial intent, and order insensitivity.
-
During manual inspection, every sharded instruction is reviewed. Shards may be merged, split, reordered, or edited to improve naturalness and ensure each shard resembles information a user could reasonably provide in a single conversational turn.
-
The processing step is designed to create natural underspecified interactions rather than adversarial rewritings of the original fully-specified instructions.
-
The original instruction and its shards are kept equivalent in information, but the information is explicitly divided across shards so that the model must collect the missing details across turns.
-
The authors use the dataset in a large-scale simulation experiment to evaluate whether models can recover task-relevant information through multi-turn interaction.
-
Evaluation reuses the original benchmark metrics. Code and Database use functional accuracy, Actions and Math use semantic equivalence, Data-to-text uses BLEU, and Summary uses a custom LLM-as-a-judge Joint Score.
-
Binary correctness scores are mapped to a 0 to 100 scale so that all tasks can be compared and aggregated.
Method
The authors design a simulation pipeline that transforms fully specified single turn tasks into controlled multi turn underspecified tasks. The method has two main stages: a sharding process that constructs multi turn instruction variants, and a simulation environment that runs multi turn conversations using those variants.
The sharding process starts from an original instruction and divides it into shards, where each shard contains a small natural piece of the original task information. A valid sharded instruction must preserve the original information, present a clear initial intent, and remain robust to the order in which shards are revealed. The authors build sharded instructions through a semi automatic workflow with segmentation, rephrasing, verification, and manual inspection. During manual review, they merge, split, reorder, or rephrase shards so that each one resembles information a real user would plausibly provide in a single turn, rather than an artificial fragment of the original prompt. Examples of fully specified instructions and their sharded counterparts are shown in the figure below.
The core simulation environment implements a loop with three roles: an evaluated assistant, a user simulator, and an evaluation system. The assistant is the model under test and receives only minimal context, such as a tool list, before the conversation begins. It is not told that the task will be underspecified or multi turn, which allows the authors to measure default behavior. The user simulator has access to the full sharded instruction and the conversation history. At each turn, it reveals at most one shard and may lightly rephrase it so that the information fits the current exchange, for example by answering a clarification question with the most relevant shard.
After the assistant responds, a strategy classifier labels the reply with one of several behavioral categories, including clarification, refusal, hedging, interrogation, discussion, missing content, or answer attempt. If the reply is classified as an answer attempt, the system extracts the answer span, such as a code block, SQL query, or numeric result, so that scoring is not affected by surrounding explanatory text. The extracted answer is then passed to a task specific evaluator that produces a per turn score. Non-answer turns continue the conversation without immediate scoring.
The framework diagram below shows how turns progress through disclosure, response generation, strategy classification, optional answer extraction, and evaluation.
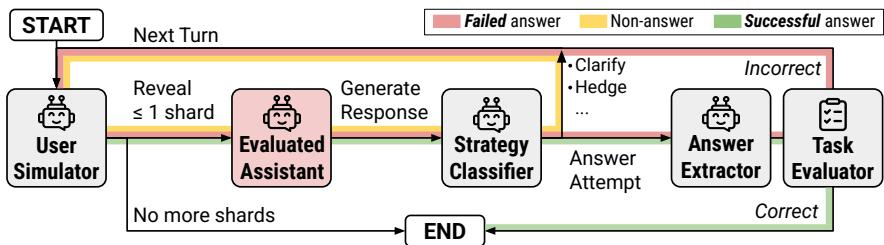
A conversation ends when the model produces a correct answer or when no shards remain. The final score is the maximum score over all answer attempts:
S=1≤i≤Nmaxsiwhere N is the number of shards and si is the score obtained at turn i. This scoring rule gives the assistant up to one answer attempt per shard, with credit for the best attempt. The authors validate the simulator through manual review of conversations and find that component errors are rare, supporting the use of the pipeline for systematic measurement.
To isolate the effect of multi turn underspecification, the authors construct five simulation types. FULL is the single turn baseline, where the original instruction is presented at once. SHARDED is the main setting, where shards are revealed gradually across turns. CONCAT places all shards into a single bullet list in the first turn, which preserves the rephrased shard form while removing the multi turn disclosure aspect. RECAP runs a SHARDED conversation and then adds a final recap turn that restates all shards, testing whether a simple summary of accumulated information restores performance. SNOWBALL reveals the next shard at each turn while also repeating all previously revealed shards, evaluating whether continuous reminders reduce memory demands during long interactions.
Experiment
The experiments simulate multi-turn conversations across six diverse generation tasks, comparing fully specified, concatenated, and sharded instruction settings across many models and repeated stochastic runs. Results show that models can perform strongly in single-turn settings yet degrade substantially when requirements are dispersed across turns, while concatenated instructions remain close to the original performance, indicating the difficulty is not simply lost information. The degradation is driven mainly by increased variability and unreliability rather than a large loss of best-case aptitude, and gradual sharding shows that even brief underspecified multi-turn exchanges can trigger it. Helper strategies such as recap, snowballing, lower temperature, or system-prompt hints only partially reduce the effect, suggesting native multi-turn reliability is needed.
Across the tested tasks, LLM performance is highest in the full specification setting, while sharded multi turn conversations cause substantial degradation. Concatenated instructions remain close to full performance overall, indicating that the drop in sharded settings is not mainly explained by missing instruction information. Sharded conversations lower averaged performance for every model and task relative to full settings. Concatenated settings generally preserve performance, although smaller models show weaker robustness to rephrasing than larger models. Performance loss in sharded conversations is not limited to weak models, as stronger systems also show large relative drops.
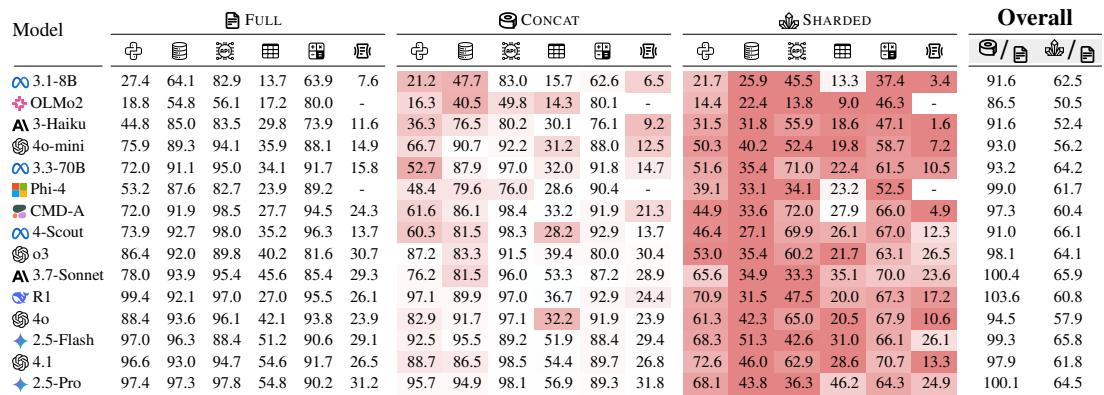
Experiments compare full, concatenated, and sharded multi-turn specification settings across LLMs. Full specifications yield the highest performance, while sharded conversations substantially degrade results for all models and tasks. Concatenated instructions largely preserve performance, suggesting the degradation arises from fragmentation rather than missing instruction content, with smaller models being less robust to rephrasing and even strong models affected.