Command Palette
Search for a command to run...
MODEL TELLS YOU WHAT TO DISCARD: ADAPTIVE KV CACHE COMPRESSION FOR LLMs
MODEL TELLS YOU WHAT TO DISCARD: ADAPTIVE KV CACHE COMPRESSION FOR LLMs
Suyu Ge Yunan Zhang Liyuan Liu Minjia Zhang Jiawei Han Jianfeng Gao
Abstract
In this study, we introduce adaptive KV cache compression, a plug-and-play method that reduces the memory footprint of generative inference for Large Language Models (LLMs). Different from the conventional KV cache that retains key and value vectors for all context tokens, we conduct targeted profiling to discern the intrinsic structure of attention modules. Based on the recognized structure, we propose FastGen, which constructs the KV cache in an adaptive manner: evicting long-range contexts on attention heads emphasizing local contexts, discarding non-special tokens on attention heads centered on special tokens, and only employing the standard KV cache for attention heads that broadly attend to all tokens. Moreover, with the lightweight attention profiling used to guide the construction of the adaptive KV cache, FastGen can be deployed without resource-intensive fine-tuning or re-training. In our experiments across various asks, FastGen demonstrates substantial reduction on GPU memory consumption with negligible generation quality loss.
One-sentence Summary
University of Illinois Urbana-Champaign and Microsoft propose FastGen, a plug-and-play adaptive KV cache compression method that profiles attention module structures to evict tokens adaptively per head type, achieving substantial GPU memory reduction during LLM generative inference without fine-tuning and with negligible quality loss.
Key Contributions
-
FastGen is introduced as a plug-and-play adaptive KV-cache compression method that reduces the memory footprint of generative inference in large language models without fine-tuning or re-training.
-
It uses lightweight attention profiling to identify intrinsic attention-head structure and applies adaptive policies: evicting long-range context for local-context heads, discarding non-special tokens for special-token-centered heads, and retaining standard KV cache only for heads that broadly attend to all tokens.
-
Experiments on Llama 1 across math, code, knowledge, and common sense reasoning benchmarks show substantial GPU memory savings with negligible quality loss, including recovering over 95% of attention scores with 35% cache compression and, for the 30B model, outperforming fixed KV compression methods at 50% compression versus their 15% compression.
Introduction
Large Transformer-based language models are increasingly used for text generation, but their autoregressive inference depends heavily on the KV cache, which accelerates generation by reusing prior attention vectors while rapidly increasing GPU memory pressure. Prior methods often require retraining, apply only to non-autoregressive models, or use fixed eviction rules, while offloading KV cache to CPU or NVMe can hurt latency because of limited PCIe bandwidth. The authors introduce FastGen, a training-free method that profiles attention patterns in each module and adaptively applies different KV cache compression strategies, such as local-context caching, special-token retention, sparse-token eviction, or full caching, thereby reducing memory use with minimal loss in generation quality.
Method
The authors formulate adaptive KV cache compression as a two-phase inference algorithm. In standard autoregressive generation, prompt encoding first computes key and value vectors for the entire prompt, and token generation appends new key and value vectors at each step. This causes the cache size to grow linearly with output length. FastGen changes this default behavior by profiling each attention head during prompt encoding and then maintaining head-specific KV caches during generation.
For a candidate compression policy C, the compressed KV cache is denoted as KC,VC=f(K,V,C). Given the attention map A=softmax(QKT), the method selects the policy that minimizes cache memory cost while keeping the reconstructed attention map close to the original one. This is written as:
C∗=C∈CargminCacheMemoryCost(C)s.t.∣A−softmax(QKCT)∣≤1−T,where C is the feasible policy set, CacheMemoryCost(C) is the memory budget of the policy, and T is a recover ratio. The profiling stage therefore searches for the lowest-memory cache policy that can preserve enough attention structure.
The core compression policies are designed around observed attention patterns. The special token policy Cspecial keeps only tokens such as begin-of-the-sentence markers or instruction tokens. The punctuation policy Cpunct keeps only punctuation tokens. The locality policy Clocal keeps recent context within a relative distance threshold controlled by a ratio rl. The frequency or heavy-hitter policy Cfrequent keeps tokens with the largest cumulative attention scores, controlled by a ratio rf. A full cache policy Cfull is also available for heads that cannot be compressed under the target recover ratio.
In practice, the method uses hybrid policies formed by union operations over these fundamental caches. The authors use a greedy shortlist of hybrid policies:
C={Cspecial,Cspecial+punct,Cspecial+punct+frequent,Cspecial+punct+frequent+local,Cfull}.Special tokens are included in most hybrid policies because they often receive high attention scores and contribute little memory cost. Punctuation tokens are also commonly retained because they are rare and can help preserve attention mass with small cache overhead.
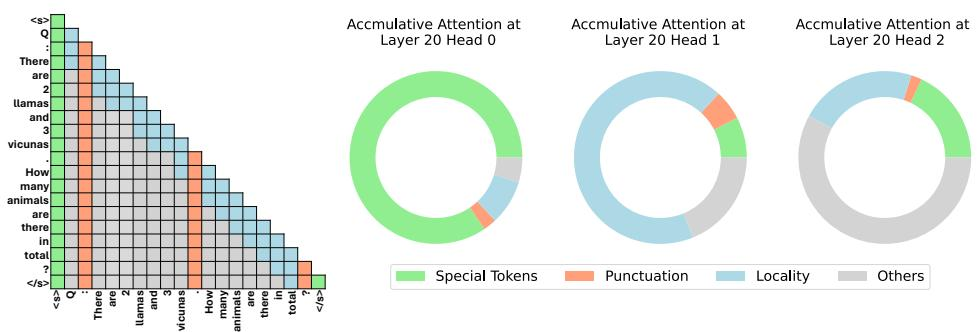
Attention heads do not share the same behavior, even within the same layer. Some heads concentrate on special tokens, some rely on punctuation, some focus on local context, and some require broader context. As shown in the figure below:
The observed patterns motivate head-level policy selection rather than a single global cache configuration. Profiling results across layers further reveal that the required policy varies with depth. Initial and final layers tend to contain more heads that need full or lightly compressed caches, while middle layers are often dominated by special-token-focused heads. The profiling distribution across layers is shown below:
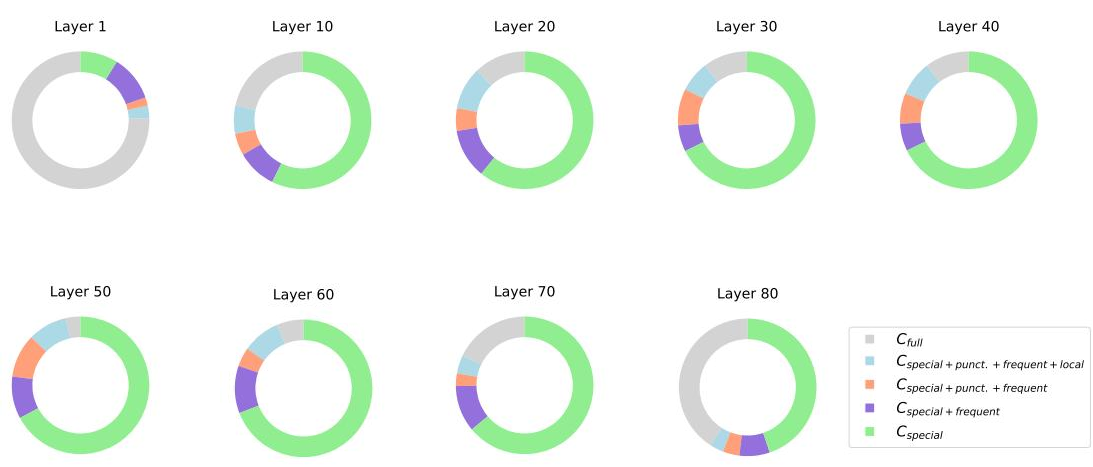
This layer- and head-dependent distribution supports the adaptive design: each attention head receives a compression policy matched to its attention structure.
The prompt-based profiling process also depends on the assumption that attention structure remains stable during decoding. The authors examine accumulated attention scores for selected heads at the prompt encoding step and later decoding steps. The resulting stability analysis is shown in the following figure:
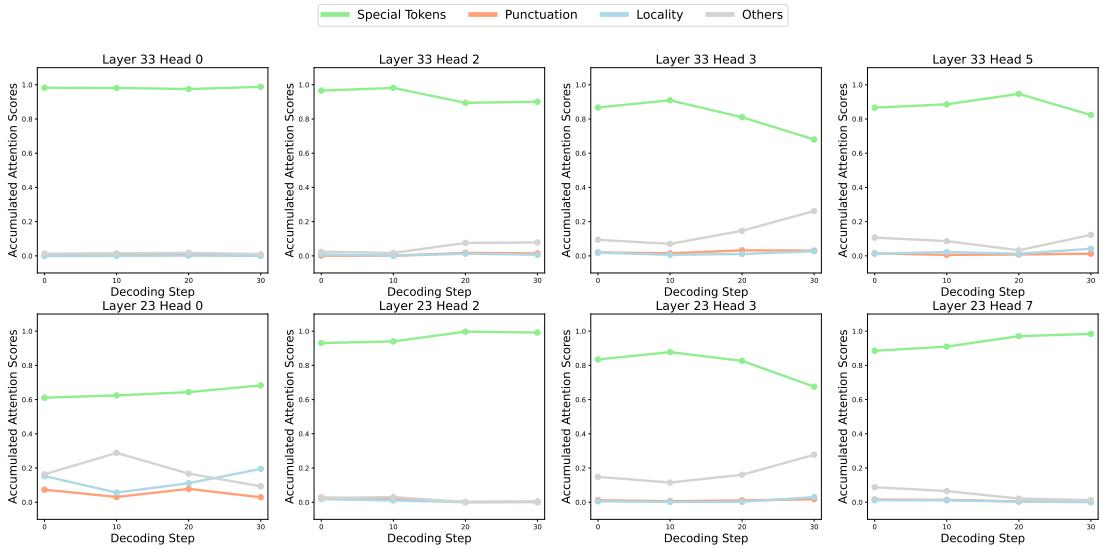
The accumulated attention patterns remain broadly consistent across decoding steps. Heads that primarily attend to special tokens continue to do so during generation, while heads with larger shares on punctuation, locality, or other context retain similar behavior. This stability allows the method to select cache policies from the prompt encoding stage and reuse them through token generation.
Experiment
The experiments first examine attention behavior in Llama models to validate the premise of adaptive KV cache compression, showing that attention heads have distinct but stable structures within a sequence. This supports using per-head profiling to select compression policies rather than applying a uniform cache strategy. Comprehensive generation evaluations across model sizes and tasks demonstrate that adaptive compression preserves quality while reducing KV cache memory and improving latency, with profiling overhead remaining negligible.
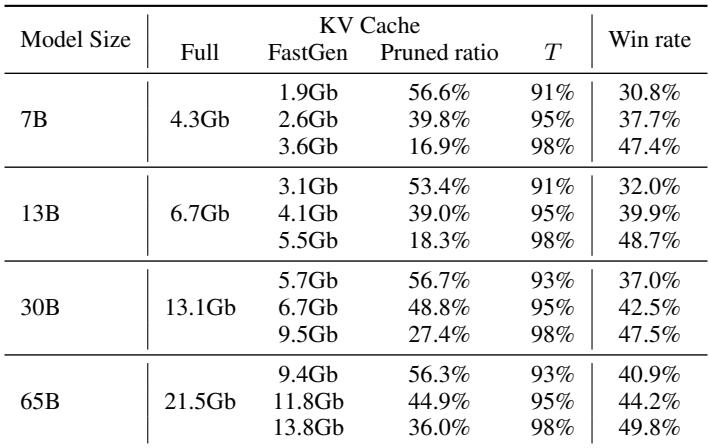
FastGen compresses the KV cache for fine-tuned Llama 1 models and lowers memory consumption relative to the full-cache baseline across the tested model sizes. The memory savings are larger for bigger models, while smaller models show more limited reduction when maintaining little-to-no quality regression. Across settings, high pruning ratios are paired with varying win rates, reflecting a tradeoff between compression strength and model behavior. Larger models benefit more from FastGen cache compression than smaller models. Smaller models achieve more modest low-regression memory savings. Aggressive KV cache pruning can lower memory usage, but win rates vary across compression levels.
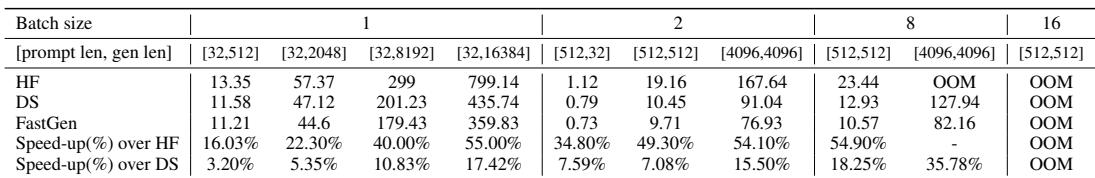
FastGen consistently reduces end-to-end latency compared with the full-cache Hugging Face baseline and the optimized DeepSpeed baseline on Llama 1-7B. The measured speedup becomes larger for longer generation settings and grows with batch size when compared with DeepSpeed. The improvement is present even in less favorable short-generation cases. FastGen lowers latency over the full-cache Hugging Face baseline across all tested prompt and generation configurations. The relative speedup increases as generation length grows. FastGen also improves over DeepSpeed, with gains becoming larger for bigger batches and longer generations.
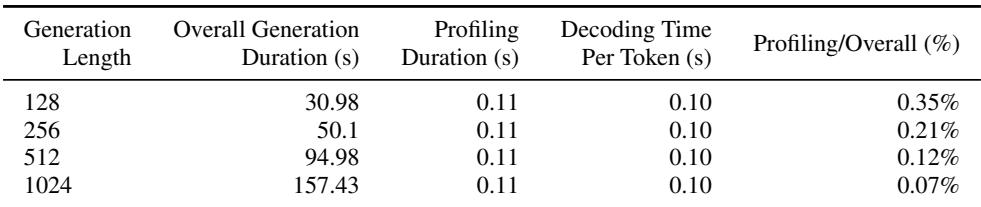
The profiling step for Llama 1-65B contributes only a small share of the overall generation time. This share becomes smaller as the generation length increases, while the measured profiling and per-token decoding times remain nearly unchanged. The associated memory overhead is also described as negligible because the extra attention-score storage is much smaller than the KV cache. Profiling duration stays roughly constant across generation lengths. The profiling overhead as a fraction of total generation time decreases with longer outputs. Extra memory for cumulative attention scores is a small cost compared with KV cache storage.
Experiments evaluate FastGen on fine-tuned Llama 1 models to validate memory reduction, generation latency, and profiling overhead. Results show cache compression lowers memory use, with larger savings for bigger models, while smaller models gain less when preserving quality and strong pruning trades memory for variable behavior. FastGen also reduces latency relative to full-cache and optimized baselines, with benefits increasing for longer generations and larger batches, while profiling adds negligible time and memory overhead.