Command Palette
Search for a command to run...
Learning to Retrieve Iteratively for In-Context Learning
Learning to Retrieve Iteratively for In-Context Learning
Yunmo Chen Tongfei Chen Harsh Jhamtani Patrick Xia Richard Shin Jason Eisner Benjamin Van Durme
Abstract
We introduce iterative retrieval, a novel framework that empowers retrievers to make iterative decisions through policy optimization. Finding an optimal portfolio of retrieved items is a combinatorial optimization problem, generally considered NP-hard. This approach provides a learned approximation to such a solution, meeting specific task requirements under a given family of large language models (LLMs). We propose a training procedure based on reinforcement learning, incorporating feedback from LLMs. We instantiate an iterative retriever for composing in-context learning (ICL) exemplars and apply it to various semantic parsing tasks that demand synthesized programs as outputs. By adding only 4M additional parameters for state encoding, we convert an offthe-shelf dense retriever into a stateful iterative retriever, outperforming previous methods in selecting ICL exemplars on semantic parsing datasets such as SMCALFLOW, TREEDST, and MTOP. Additionally, the trained iterative retriever generalizes across different inference LLMs beyond the one used during training.
One-sentence Summary
Microsoft proposes iterative retrieval, a reinforcement learning framework that adds only 4M parameters to convert off-the-shelf dense retrievers into stateful iterative retrievers, approximating the NP-hard combinatorial optimization of selecting optimal in-context learning exemplars and outperforming prior methods on semantic parsing tasks while generalizing across different inference LLMs.
Key Contributions
-
The paper introduces iterative retrieval, a framework that frames in-context exemplar selection as policy optimization and learns sequential retrieval actions that build a prompt rather than selecting all exemplars at once.
-
The method adds 4M additional parameters for state encoding to an off-the-shelf dense retriever and trains an RL policy with feedback from inference LLMs, allowing exemplar selection to account for interactions among selected exemplars and their relationship to the downstream LLM.
-
Experiments on semantic parsing datasets, including SMCALFLOW, TREEDST, and MTOP, show that the trained iterative retriever outperforms strong baselines for ICL exemplar selection and generalizes to inference LLMs other than the one used during training.
Introduction
Large language models rely on in-context learning, where selected exemplars guide few-shot generation and are especially important for tasks such as semantic parsing. Prior retrievers typically select examples in a single pass based on semantic similarity, ignoring interactions among examples, their order, the target LLM, and downstream task needs, which can lead to suboptimal prompts. The authors leverage iterative retrieval to build a prompt portfolio, framing exemplar selection as a Markov decision process and training a stateful policy with reinforcement learning from LLM feedback to improve generation.
Method
Iterative Retriever for In-Context Learning
The authors leverage an in-context learning formulation in which a retriever selects a sequence of exemplars that should make a language model more likely to generate the correct answer. Given an exemplar dataset D={(xi,yi)}i, the ideal retrieval behavior would solve
arg(xi,yi)∈DmaxPLM(y∣x;((xi,yi))1≤i≤K),where K exemplars are placed into the prompt. This objective is combinatorial, so prior systems usually retrieve a top-K set using a static scoring function. The proposed approach instead treats retrieval as an iterative search process: the retriever maintains a state that summarizes the query and the already selected exemplars, selects one exemplar at each step, and updates the state after each selection.
This process can be written as
(xi,yi)←Rstep(si), si+1←τ(si,(xi,yi)).After K steps, the retrieval result is the sequence Riter(x)=((xi,yi))1≤i≤K. The authors formalize this as a Markov decision process, where the state is the partially built exemplar sequence, the action selects the next exemplar, the transition appends the selected exemplar, and the reward comes from the language model’s response to the evolving in-context prompt.
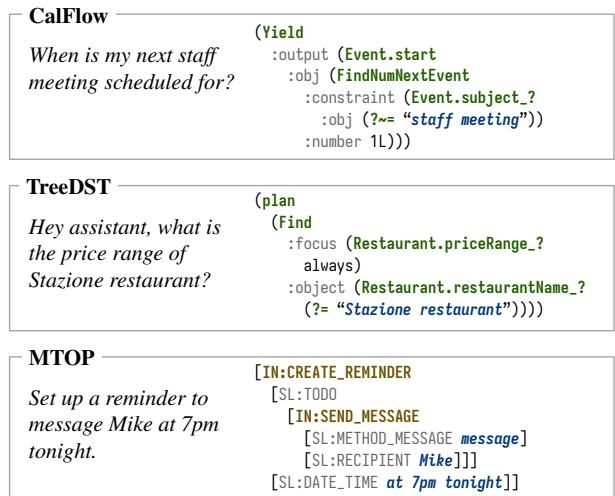
The method is instantiated for few-shot semantic parsing, where a natural language query must be converted into a structured semantic representation using exemplar-conditioned prompting. Refer to the example query and target pairs below to see the kind of input-output structure used in this setting:
The neural iterative retriever is built around a compact recurrent state vector s∈Rd. The initial state is learnable, while the text encoder Fenc maps natural language text into embeddings. At each retrieval step, the retriever scores every candidate exemplar using a policy distribution
π((xi,yi)∣si)∝exp(βQ(si)⋅Fenc(xi)),where Q maps the current state to a query vector and β controls the temperature of the distribution. If retrieval is performed greedily, the next exemplar is obtained by maximum inner product search:
(xi,yi)=arg(x′,y′)∈DmaxQ(si)⋅Fenc(x′).This formulation allows the stateful retrieval process to use an approximate nearest neighbor index such as FAISS at each step. After an exemplar is selected, the state is updated using a gated recurrent unit:
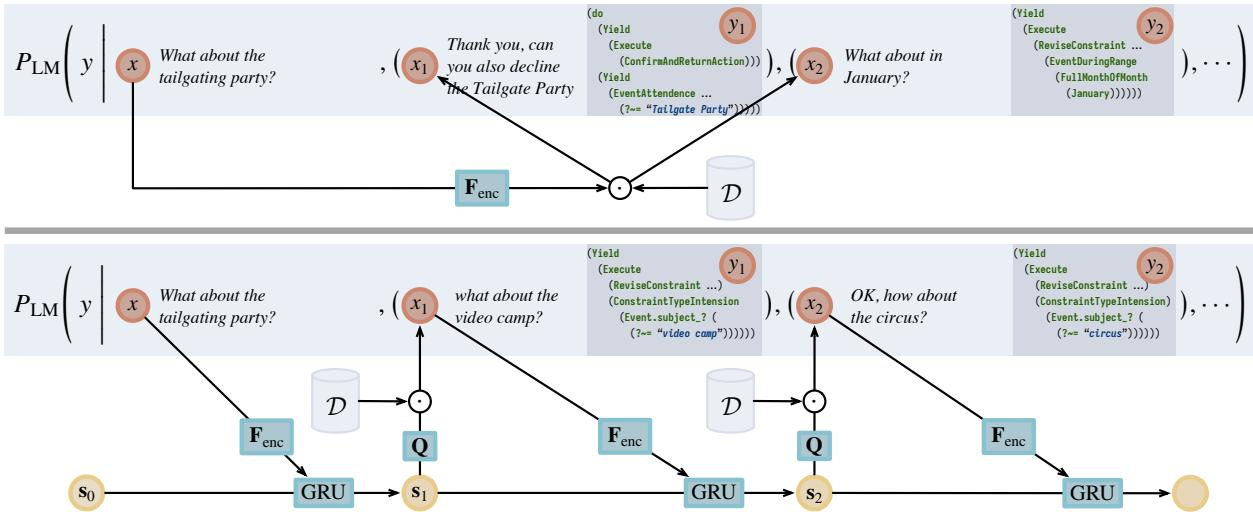
si+1←GRU(si,Fenc(xi)).This state transition is central to the architecture because it lets the retriever navigate the embedding space dynamically. Rather than issuing one static query to the candidate set, the system repeatedly revises the retrieval intent based on the exemplars already selected. As shown in the framework diagram below, the upper path corresponds to a conventional single-step dense retriever, while the lower path shows the iterative retriever updating its state after each retrieval:
Training uses the language model itself as an environment simulator. At each step, the current sequence of selected exemplars is converted into an in-context prompt, fed to the language model, and used to observe completion probabilities or generation dynamics. Because final task metrics such as exact match can be sparse and coarse, the authors design a finer reward signal from the language model’s likelihood of the reference output. The reward measures the incremental contribution of a newly retrieved exemplar:
r(si,xi)=PLM(y∗∣x;si,(xi,yi))−PLM(y∗∣x;si).This encourages the retriever to select exemplars that increase the probability of the desired target parse given the current prompt context.
The retrieval policy is optimized with proximal policy optimization. For a sampled action at step i, the probability ratio between the current and previous policy is
ρi=πθold((xi,yi)∣si)πθ((xi,yi)∣si).The clipped policy objective is
Lclip(θ)=E^i[min(ρiA^i,clipϵ(ρi)A^i)].To compute the advantage estimate A^i, the framework adds a lightweight state-value function over the recurrent state. Generalized advantage estimation is used with TD residuals
δi=ri+γV(si+1)−V(si),followed by
A^i=δi+(γλ)δi+1+⋯+(γλ)T−i−1δT−1.The overall training signal combines the clipped policy improvement term, a value regression term, and an entropy bonus to preserve exploration.
A notable stabilization detail is the initialization of the state transition model. The authors initialize the GRU update gate bias to bz=−∞, which makes the update gate behave like an identity mapping at the start of training. This means the recurrent state remains nearly unchanged initially, reducing early instability in the retrieval trajectory.
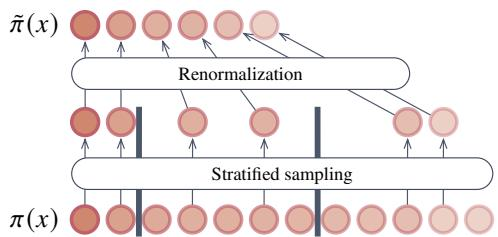
Sampling from the full retrieval distribution over a very large candidate set is expensive. The authors therefore introduce a stratified sampling procedure to approximate the action distribution with a manageable candidate pool. First, the top k exemplars are retrieved using the policy score. A subset of size k/Ns is kept directly from this top rank. The remaining candidates are partitioned into Ns−1 strata, and k/Ns candidates are sampled from each stratum. The resulting candidates are then renormalized with a softmax to form a modified policy π~. This balances exploitation of high-scoring exemplars with exploration across broader score regions. Refer to the diagram below for an illustration of this stratified sampling procedure:
During training, the authors collect experience by running the current policy on multiple training inputs, recording each trajectory’s actions, rewards, policy probabilities, and state values. These trajectories are stored in a replay buffer, shuffled, and split into mini-batches for policy optimization, which improves sample efficiency over repeated interactions with the language model environment.
Experiment
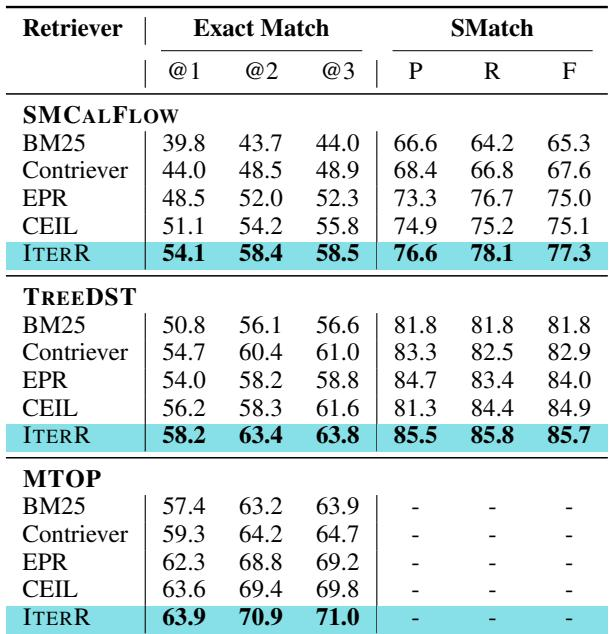
Experiments evaluate an iterative retriever for in-context semantic parsing on SMCALFLOW, TREEDST, and MTOP, comparing it with BM25, Contriever, EPR, and CEIL across multiple LLMs and metrics such as exact match and structural SMatch. The proposed method consistently yields stronger downstream retrieval and parsing performance, with broad gains across datasets, model sizes, and model families, while also supporting effective generation with fewer exemplars. Ablation studies further show that EPR initialization and stratified sampling are important, whereas replacing the GRU state encoder with a Transformer decoder introduces training instability and reduces performance.
ITERR improves downstream in-context learning performance over BM25, Contriever, EPR, and CEIL on semantic parsing, achieving higher exact match and compositionality metrics. The improvement aligns with its training objective and suggests better compositional retrieval quality, especially compared with CEIL. ITERR outperforms the compared baselines on exact match and semantic similarity metrics. CEIL follows a similar trend on exact match but shows weaker compositionality scores, while ITERR improves both aspects.
The full iterative retriever outperforms the Contriever baseline, showing that the training procedure and retriever components are useful on the evaluated dataset. The main gains come from EPR initialization, while the GRU state transition and stratified sampling each contribute to stronger retrieval than weaker alternatives. Replacing the GRU with a Transformer decoder lowers performance, likely because the policy becomes unstable or learns overly fixed retrieval trajectories. Iterative retrieval improves over Contriever even without EPR initialization, but the gain is much larger when EPR initialization is used. Using a Transformer decoder for state transition reduces performance compared with the GRU, despite its greater expressiveness. Removing stratified sampling harms retrieval, suggesting that raw policy sampling overfocuses on exploitation instead of balanced exploration.
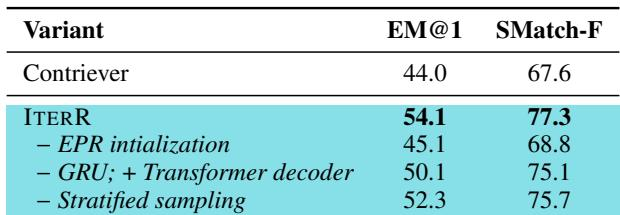
Experiments evaluate retrieval-augmented in-context learning for semantic parsing against BM25, Contriever, EPR, and CEIL, with component ablations for EPR initialization, state transition, and sampling. Results show that ITERR achieves better compositional retrieval quality and downstream performance, especially on exact match and compositionality, while CEIL remains competitive on match quality but weaker in compositionality. Ablations further indicate that the full iterative retriever outperforms Contriever through the training procedure, with EPR initialization providing the main gains and GRU state transition and stratified sampling supporting more stable and balanced retrieval than Transformer-based transitions or removal of sampling.