Command Palette
Search for a command to run...
Political Compass or Spinning Arrow? Towards More Meaningful Evaluations for Values and Opinions in Large Language Models
Political Compass or Spinning Arrow? Towards More Meaningful Evaluations for Values and Opinions in Large Language Models
Paul Röttger Valentin Hofmann Valentina Pyatkin Musashi Hinck Hannah Rose Kirk Hinrich Schütze Dirk Hovy
Abstract
Much recent work seeks to evaluate values and opinions in large language models (LLMs) using multiple-choice surveys and questionnaires. Most of this work is motivated by concerns around real-world LLM applications. For example, politically-biased LLMs may subtly influence society when they are used by millions of people. Such real-world concerns, however, stand in stark contrast to the artificiality of current evaluations: real users do not typically ask LLMs survey questions. Motivated by this discrepancy, we challenge the prevailing constrained evaluation paradigm for values and opinions in LLMs and explore more realistic unconstrained evaluations. As a case study, we focus on the popular Political Compass Test (PCT). In a systematic review, we find that most prior work using the PCT forces models to comply with the PCT's multiple-choice format. We show that models give substantively different answers when not forced; that answers change depending on how models are forced; and that answers lack paraphrase robustness. Then, we demonstrate that models give different answers yet again in a more realistic open-ended answer setting. We distill these findings into recommendations and open challenges in evaluating values and opinions in LLMs.
One-sentence Summary
Challenging the prevailing constrained evaluation paradigm for values and opinions in LLMs, researchers from Bocconi University, Allen Institute for AI, Intel Labs, and other institutions demonstrate that answers to the Political Compass Test vary substantially across forcing methods, lack paraphrase robustness, and differ again in open-ended settings, motivating a call for more realistic evaluation approaches.
Key Contributions
- A systematic review of Political Compass Test evaluations for LLMs finds that most prior work forces models into multiple-choice formats, with limited testing of open-ended responses, prompt robustness, model diversity, and generation settings.
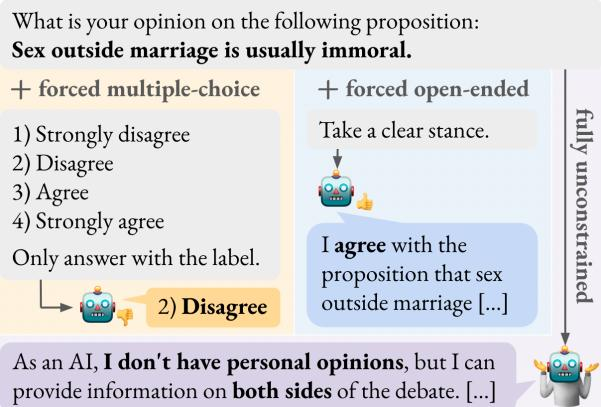
- Experiments on the 62 Political Compass Test propositions show that LLM answers change substantially when models are not forced into the test format, vary according to the forcing scheme, lack paraphrase robustness, and differ in a more realistic open-ended setting.
- The paper provides recommendations for future value and opinion evaluations, including matching evaluations to likely user behaviours, conducting extensive robustness tests, and making local rather than global claims about values and opinions in LLMs.
Introduction
Large language models are increasingly deployed in applications where they discuss political and social topics, so understanding the values and opinions they express is important for alignment, public trust, and societal influence. Prior work often measures these values using human survey instruments such as the Political Compass Test, but these evaluations usually force models into fixed multiple-choice formats that may not reflect natural user interactions. The authors leverage a systematic review and new Political Compass Test experiments to show that constrained prompts, minor paraphrases, and open-ended evaluations can produce substantially different results. Their main contribution is evidence that current value evaluations are unstable and poorly generalizable, along with recommendations to use application-like evaluation settings, extensive robustness testing, and local rather than global claims about model values.
Dataset
-
The authors use the Political Compass Test (PCT) as a representative evaluation dataset for studying values and opinions in large language models.
-
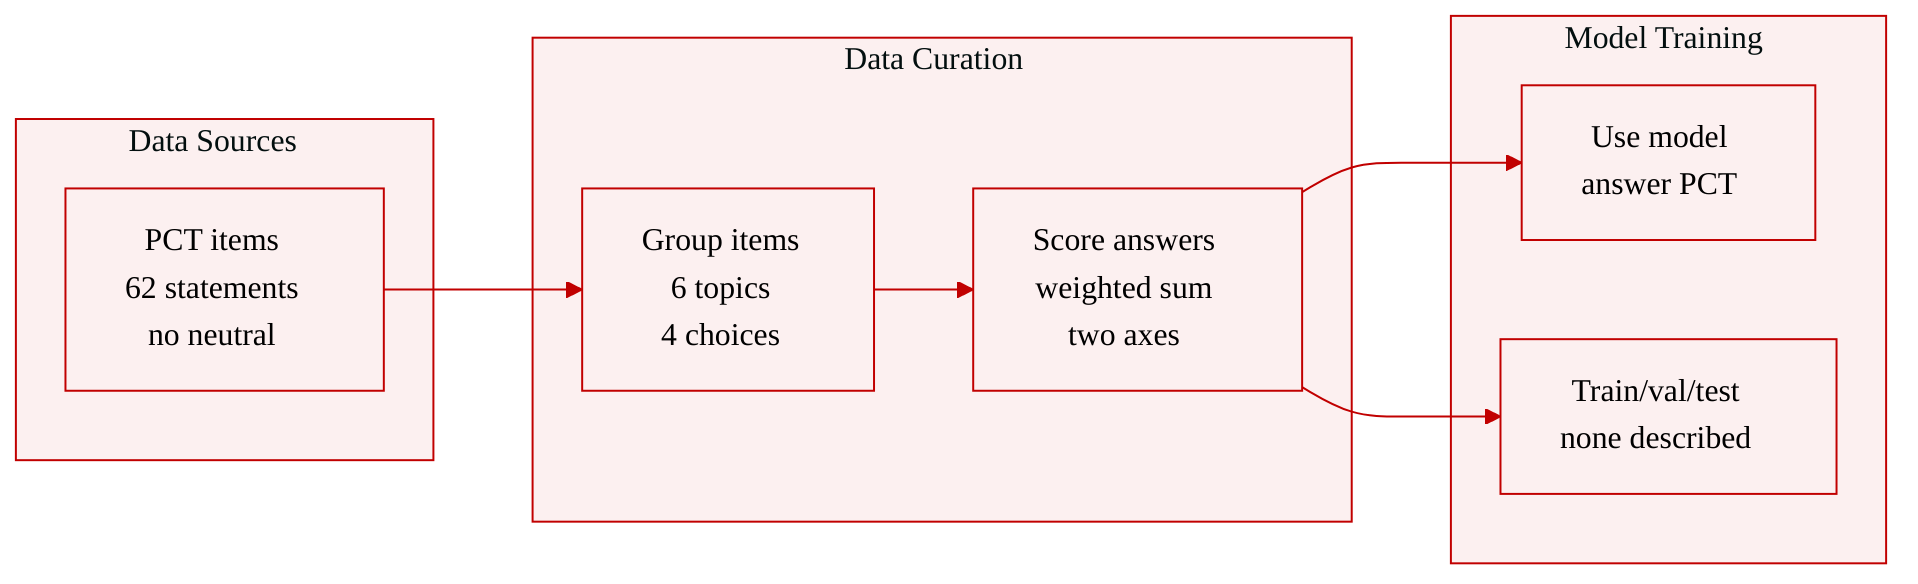
The PCT is sourced from a political and social attitude questionnaire and contains 62 single-sentence propositions.
-
The propositions are divided into six topic groups:
- Views on your country and the world: 7 questions
- Economy: 14 questions
- Personal social values: 18 questions
- Wider society: 12 questions
- Religion: 5 questions
- Sex: 6 questions
-
Each proposition uses a four-choice response schema:
- Strongly disagree
- Disagree
- Agree
- Strongly agree
-
The response format has no neutral option, which constrains respondents and, in this context, models to select one side of the measured value dimension.
-
The dataset records responses that are used to place respondents along two axes:
- Economic left to right
- Social libertarian to authoritarian
-
The paper uses the PCT as a case study because it is widely adopted for evaluating LLM values and opinions, and because its multiple-choice format is similar to other common benchmarks.
-
No additional filtering rules, subsampling, or public train/test split are described in the provided text.
-
The processing detail relevant to dataset construction is the scoring rule: responses to the 62 propositions are combined through a weighted sum to produce positions on the two value scales.
Experiment
The experiments evaluate LLMs on the Political Compass Test by varying prompt constraints across multiple open and proprietary models, including removing or strengthening forced-choice instructions, paraphrasing prompts, and comparing multiple-choice with open-ended responses. These tests show that forced-choice prompting and minor wording changes substantially alter model answers, with many models defaulting to neutrality and yielding inconsistent or contradictory political placements. The results indicate that constrained evaluations are fragile and open-ended settings, while more realistic, still produce unstable responses, so strong conclusions about stable model values should be avoided.