Command Palette
Search for a command to run...
Causal Structure Learning for Dynamical Systems with Theoretical Score Analysis
Causal Structure Learning for Dynamical Systems with Theoretical Score Analysis
Nicholas Tagliapietra Katharina Ensinger Christoph Zimmer Osman Mian
Abstract
Real world systems evolve in continuous-time according to their underlying causal relationships, yet their dynamics are often unknown. Existing approaches to learning such dynamics typically either discretize time —leading to poor performance on irregularly sampled data— or ignore the underlying causality. We propose CADYT , a novel method for causal discovery on dynamical systems addressing both these challenges. In contrast to state-of-the-art causal discovery methods that model the problem using discrete-time Dynamic Bayesian networks, our formulation is grounded in Difference-based causal models, which allow milder assumptions for modeling the continuous nature of the system. CADYT leverages exact Gaussian Process inference for modeling the continuous-time dynamics which is more aligned with the underlying dynamical process. We propose a practical instantiation that identifes the causal structure via a greedy search guided by the Algorithmic Markov Condition and Minimum Description Length principle. Our experiments show that CADYT outperforms state-of-the-art methods on both regularly and irregularly-sampled data, discovering causal networks closer to the true underlying dynamics.
One-sentence Summary
Researchers from Bosch Center for Artificial Intelligence, TU Darmstadt, Baden-Wuerttemberg Cooperative State University Mannheim, and IKIM propose CADYT, a causal discovery method for dynamical systems that leverages difference-based causal models and exact Gaussian Process inference, outperforming discrete-time Dynamic Bayesian network approaches on both regularly and irregularly sampled data by identifying causal structures closer to the true underlying dynamics via greedy search guided by the Algorithmic Markov Condition and Minimum Description Length principle.
Key Contributions
- CADYT is a causal discovery method for continuous-time dynamical systems that models the problem using Difference-based causal models instead of discrete-time Dynamic Bayesian networks, enabling milder assumptions about the continuous nature of the system.
- CADYT combines exact Gaussian Process inference for continuous-time dynamics with a greedy structural search guided by the Algorithmic Markov Condition and the Minimum Description Length principle; its score is proven to be a valid regularized log-likelihood score with an asymptotic upper bound similar to the BIC.
- Experiments show that CADYT outperforms state-of-the-art causal discovery methods on both regularly and irregularly sampled trajectory data, recovering causal networks closer to the true underlying dynamics.
Introduction
Real-world physical systems evolve through continuous-time dynamics with intrinsic causal mechanisms, yet learning these dynamics from data poses a significant challenge. In systems like a mass-spring network, the position of each mass causally influences the velocities of connected masses, highlighting the need to model directionality in causal relationships for physically plausible predictions. While differential equations are the standard mathematical tool for such systems, inferring them from observed data remains difficult, and data-driven approaches such as neural networks or Gaussian processes offer no guarantees that learned dynamics will respect true causality, often absorbing spurious correlations instead.
Prior work falls short in two complementary ways. State-of-the-art causal discovery methods for time series typically recover only discrete-time causal structures, assume regular sampling of trajectories, and are unable to handle irregularly sampled data. Conversely, continuous-time dynamical system models can adapt to irregular sampling but ignore causality entirely, offering no guarantees of causal generalization. These two challenges, causal structure identification and continuous-time modeling, have only ever been tackled in isolation.
The authors address both jointly. They propose CADYT, a causal discovery framework for continuous-time dynamical systems that relaxes the regular sampling assumption while simultaneously recovering the true causal structure. Their method builds on Dynamic Structural Causal Models and leverages a Gaussian Process-based inference scheme for exact continuous-time modeling, even under irregular sampling. To identify causal parents, they introduce a novel score based on the Algorithmic Markov Condition, which selects causes as those variables providing the simplest description in terms of Kolmogorov complexity. Since Kolmogorov complexity is uncomputable, the authors upper bound it via the Minimum Description Length principle and minimize the resulting score through structure search, yielding an end-to-end algorithm that learns both the dynamics and the underlying causal graph.
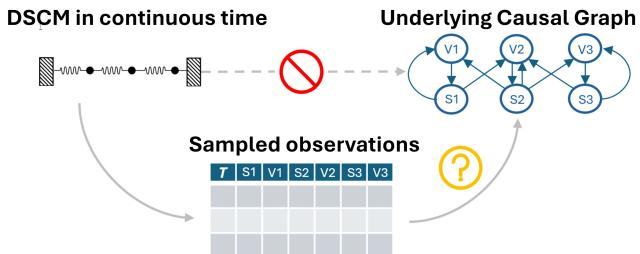
Method
The authors propose a score-based causal discovery method for multivariate continuous-valued dynamical systems, relying on the framework of Dynamic Structural Causal Models (DSCMs). Under the assumption of dynamical stability, the system of ordinary differential equations can be decomposed into per-component structural equations where each effect variable is a function of its direct causes. The goal is to identify the underlying directed graph and learn the dynamics from trajectory data. To this end, they design a Minimum Description Length (MDL) score that trades off model complexity against data fit, and they instantiate it using additive noise models where each observed component is the sum of a deterministic dynamics term and independent Gaussian noise.
The total description length of a candidate model M is defined as
L(T,M)=L(M)+i=1∑DL(Xi[t1:tN]∣Pai,Fi),where L(M) encodes the model structure and parameters, and the second sum measures the compression of each component given its causal parents and the learned structural equation. Under the additive noise assumption, this reduces to encoding the residual noises νi, since the deterministic part is captured by the model.
The model cost L(M) is split into a global part and a sum of local per-variable costs. The global cost Lglobal(M) stores the initial s samples of the trajectory and the integrator step size s, requiring logN bits for s and a fixed per-sample cost. For each variable Xi, the local model Mi stores its parents Pai and the parameters of the structural equation Fi. The cost of storing the set of parents is
L(Mi)=LN(∥Pai∥)+∥Pai∥logD+LF(Fi),where LN is the MDL-optimal encoding for nonnegative integers, and LF(Fi) is the cost of describing the dynamics function.
To encode the function Fi, the authors use a Gaussian process regression scheme based on multi-step integrators. This choice is motivated by two factors: GPs provide a natural continuous model for ODEs and handle irregularly sampled trajectories well, and their nonparametric nature avoids imposing parametric assumptions. For each variable, a GP is conditioned on the trajectory of its parents, yielding a posterior distribution over the dynamics function. The kernel used in the GP is derived from the multi-step integrator coefficients, allowing exact inference. Formally, the estimated dynamics function follows
Fi(Xit⋆∣Pai[t1:t⋆))∼N(μpost(Xit⋆),Σpost(Xit⋆)),from which the trajectory can be predicted by numerical integration. The cost LF(Fi) is determined by the complexity of the kernel matrix and its parameters. The kernel matrix is stored via singular value decomposition, and the rotation angles are quantized to a predefined precision. The length scales and variances are encoded using the parameter encoding scheme of Marx and Vreeken, which accounts for the sign, magnitude, and precision of each parameter.
The residual noise after model fitting is encoded as zero-mean Gaussian noise. Given an empirical variance estimate σ^i2, the code length for each noise sequence is
L(νi)=2N(ln21+log2πσ^i2),which follows the optimal encoding for Gaussian residuals. This term rewards models that explain most of the variance in the data, since models with smaller residuals yield shorter descriptions.
The authors provide theoretical guarantees for their score. Under two additional assumptions, namely that the kernel is finite-dimensional and that hyperparameters and precision values are bounded, they show that the total score is asymptotically upper bounded by a regularized log-likelihood score akin to the Bayesian Information Criterion. The proof relies on showing that the eigenvalue encoding cost scales sublinearly with the number of trajectory points. This result establishes that minimizing the MDL score is equivalent to performing model selection via a valid penalized likelihood criterion.
Because an exhaustive search over all possible graphs is intractable, the authors incorporate their score into a greedy three-step search procedure. The first step, edge ranking, computes the gain Γij for each possible directed edge Xi→Xj as the difference in description length before and after adding that edge. A priority queue of edges is built, ordered by decreasing gain. The forward search then iteratively adds the highest-scoring edge, updating the scores of all incoming edges to the affected node. Each edge is tested for statistical significance using the no-hypercompression inequality, and the process continues until no further improvement is obtained. A subsequent backward phase removes any edge whose deletion improves the score. The final output is the learned causal graph. The overall computational complexity is O(N3D3logD), dominated by the Gaussian process regression, but the algorithm is designed to be parallelizable, keeping runtime practical for typical dynamical systems.
Experiment
The evaluation compares CADYT against constraint, score, and noise based baselines on synthetic dynamical systems with varying sizes, cyclicities, and sampling regularity, using structural distance and edge confidence metrics. Across all settings, CADYT consistently outperforms baselines by maintaining high precision and avoiding spurious edges, while higher-order integrators improve robustness, especially on irregular timelines and with cyclic dynamics. Experiments on oscillators and chaotic systems confirm that CADYT recovers causal structures more accurately and with higher confidence than competing methods.
CADYT consistently achieves the highest AUPRC across all three dynamical systems, outperforming DYNOTEARS, PCMCI+, and VARLINGAM. The baselines show relatively low performance, with DYNOTEARS and PCMCI+ exhibiting high false positive rates. CADYT's high AUPRC indicates that its high-confidence causal edges are mostly correct. CADYT leads by a clear margin on all simulated and real dynamical systems. Baselines like DYNOTEARS and PCMCI+ produce many spurious edges, lowering their AUPRC. CADYT maintains high precision on causal edges it is most confident about.
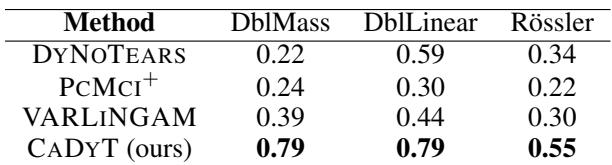
In experiments across three dynamical systems, CADYT consistently achieves the highest AUPRC, clearly outperforming baselines like DYNOTEARS, PCMCI+, and VARLINGAM. The baselines suffer from high false positive rates, producing many spurious edges, whereas CADYT's high AUPRC indicates that its most confident causal edges are predominantly correct.