Command Palette
Search for a command to run...
Probing the “Conscious” Mind: Selective Access and Global Workspace in Vision-Language Models
Probing the “Conscious” Mind: Selective Access and Global Workspace in Vision-Language Models
Jiahao Huang Jun Wang
Abstract
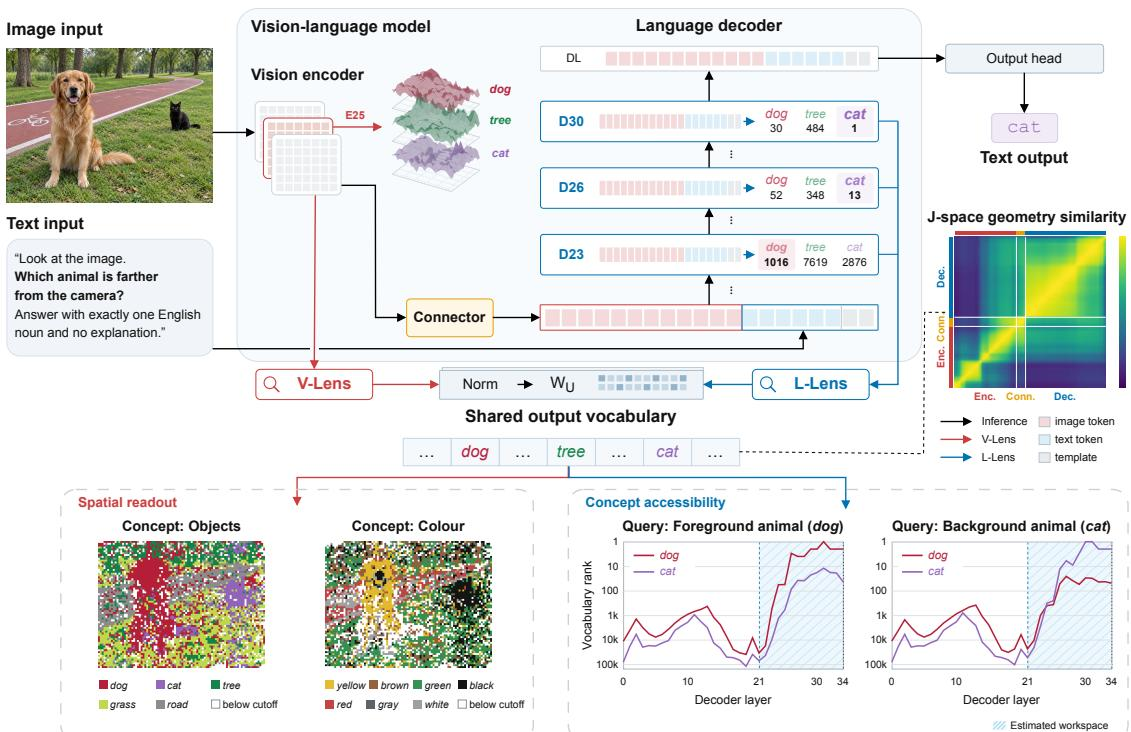
Vision-language models (VLMs) integrate visual and textual information to perform a range of multimodal tasks, but their outputs do not reveal the models’ internal concept representations. In brain science, global workspace theory (GWT) proposes that information is selected from multiple parallel brain processes, integrated in a shared workspace, and made available to diferent specialised processes. In this work, we investigate multimodal concept processing in VLMs in relation to these global workspace functions. We introduce the Multimodal Concept Lens (MC-Lens), a multimodal Jacobian lens that combines vision encoder and language decoder lenses. Both lenses map intermediate states into a shared semantic space defined by the decoder’s output vocabulary, allowing us to compare concept accessibility across visual and language processing. MC-Lens also supports internal concept interventions to examine the role of accessed concepts in downstream computation. Our experiments address four related aspects. (i) Accessibility and selective access. Multimodal concept information is readable in intermediate states and can be selectively accessed according to task demands. We extend the “readout carriers” from a single name token to a set of tokens, to better capture and express concept information and support subsequent counterfactual experiments. (ii) Concepts in downstream computation. Counterfactual experiments show that the concept information we access is not only readable, but also participates in downstream computation and reasoning. (iii) Development of cross-modal alignment and selective access. We develop two J-space based metrics to track cross-modal concept alignment. In controlled VLM training, these metrics reflect its development more clearly than hidden state cosine. The experiment also shows that reliable selective access develops later in training than concept accessibility. (iv) Shared functions across models. Across VLM families and sizes, we find shared patterns of concept accessibility, query-dependent selectivity and cross-task intervention efects, despite diferences in internal organisation. Together, these findings provide an experimental basis for studying GWT in multimodal artificial systems, and open a way to investigate how GWT can guide improvements in cross-modal alignment.
One-sentence Summary
Researchers from Imperial College London and University College London introduce the Multimodal Concept Lens (MC-Lens), a multimodal Jacobian lens that combines vision-encoder and language-decoder lenses to map intermediate states into a shared semantic space, with experiments showing selective concept access, causal roles in downstream reasoning, and shared global-workspace patterns across VLM families and sizes.
Key Contributions
- Introduces the Multimodal Concept Lens (MC-Lens), a multimodal Jacobian lens combining vision encoder and language decoder lenses to map intermediate visual and language states into a shared semantic space defined by the decoder’s output vocabulary.
- Extends concept readouts from a single name token to a set of tokens and uses counterfactual interventions to show that accessed concept information is not only readable but also participates in downstream computation and reasoning.
- Develops two J-space based metrics for tracking cross-modal concept alignment; in controlled VLM training, these metrics reflect cross-modal alignment development more clearly than hidden state cosine. The experiments also show that reliable selective access develops later than concept accessibility, and shared patterns of concept accessibility, query-dependent selectivity, and cross-task intervention effects hold across VLM families and sizes.
Introduction
Vision-language models (VLMs) integrate visual and textual information for tasks such as visual question answering, but their outputs do not expose internal concept representations, and they can make errors even when the needed visual information remains readable in intermediate states. Existing Jacobian-based methods such as J-Lens provide vocabulary readouts of intermediate language-model states and have been used to study global workspace behavior in large language models, but they focus on language-only states and often represent concepts through single name tokens, limiting multimodal analysis. The authors introduce the Multimodal Concept Lens (MC-Lens), which combines a vision encoder lens and a language decoder lens to map intermediate visual and language states into a shared semantic space defined by the decoder output vocabulary. This approach supports concept readouts, counterfactual interventions, richer multi-token concept direction sets, and the study of selective access and cross-modal alignment in VLMs.
Method
The authors develop MC-Lens, a Jacobian-based method designed to access concept information from intermediate states in Vision-Language Models (VLMs) and investigate the role of these concepts in downstream computation. Since a VLM's final output provides only a limited view of its internal processing, MC-Lens combines V-Lens and L-Lens to measure the effects of intermediate hidden states on the final-layer decoder hidden states.
For a multimodal input x, let hℓ,pm(x) denote the intermediate state at layer ℓ and position p, where m∈{E,D,C} marks the vision encoder, the language decoder, and the connector, respectively. The partial derivatives of the final decoder state hL,qD(x) with respect to the intermediate state form the Jacobian matrix Jℓ,p→qm(x), which provides a first-order Taylor approximation of how a small change in the intermediate state affects the final output.
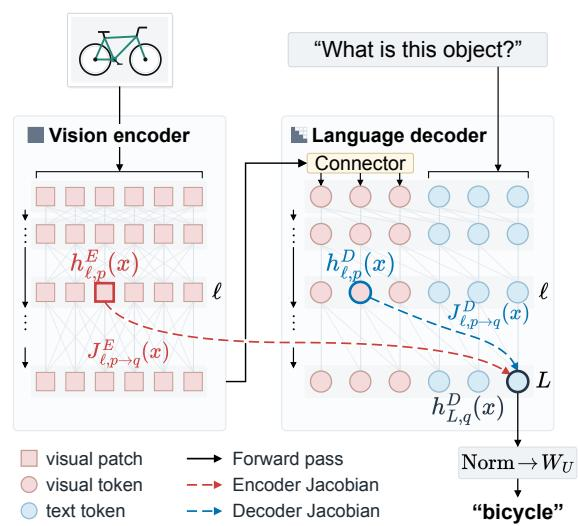
To isolate the general effect of an intermediate state across contexts, the authors average the Jacobian matrices. However, unlike pure language models, VLMs contain significantly more image tokens than text tokens. A uniform averaging strategy would disproportionately weight image positions. To address this, MC-Lens groups intermediate positions into categories (e.g., image, text, and template tokens for L-Lens; all patches for V-Lens) and averages within each category before averaging across categories. This ensures each category receives equal total weight regardless of token count. The final-layer positions are restricted to text positions in the decoder to focus on the model's textual output.
To determine where specific concepts appear within the model's internal states, the authors employ a vocabulary-based concept readout. An intermediate state h is mapped through the estimated lens Jℓ into the final-layer decoder state space. The resulting vector is processed through the decoder's final normalization and unembedding matrix WU to produce logits for every word in the vocabulary, ranking tokens by their proximity to the state.
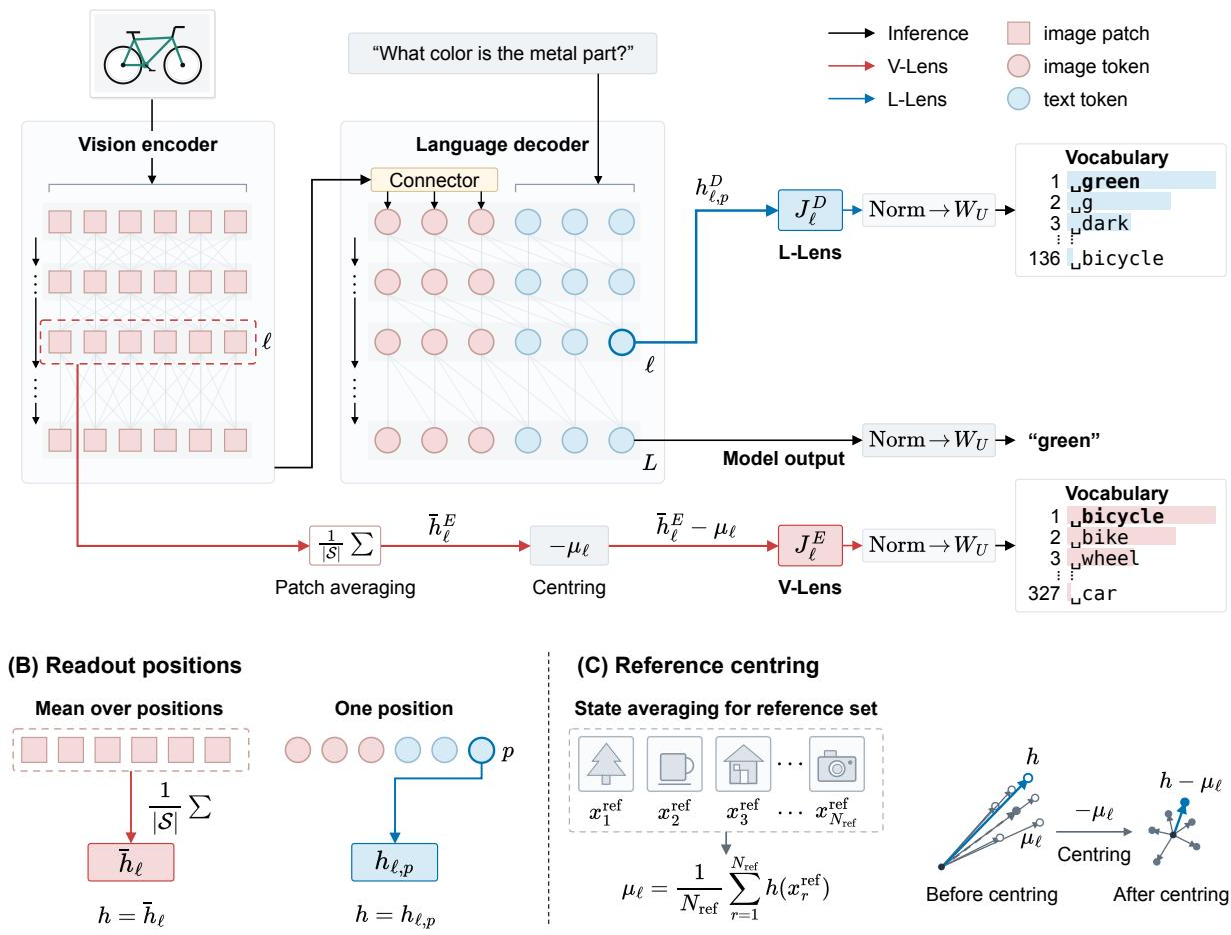
Visual states often contain a large component common to different images, which can bury the specific object name under uninformative tokens. To resolve this, the authors introduce reference centring. A reference state μℓ is computed by averaging the readout states over a set of natural reference images. Subtracting μℓ from the target state h removes this common component, allowing the readout to rank tokens based on how the specific image state differs from an average image.
Because a hidden state typically carries more information about a concept than a single name token can express, the authors describe concepts using a set of tokens rather than a single token. They construct concept direction sets using two methods: word-form selection and greedy selection.
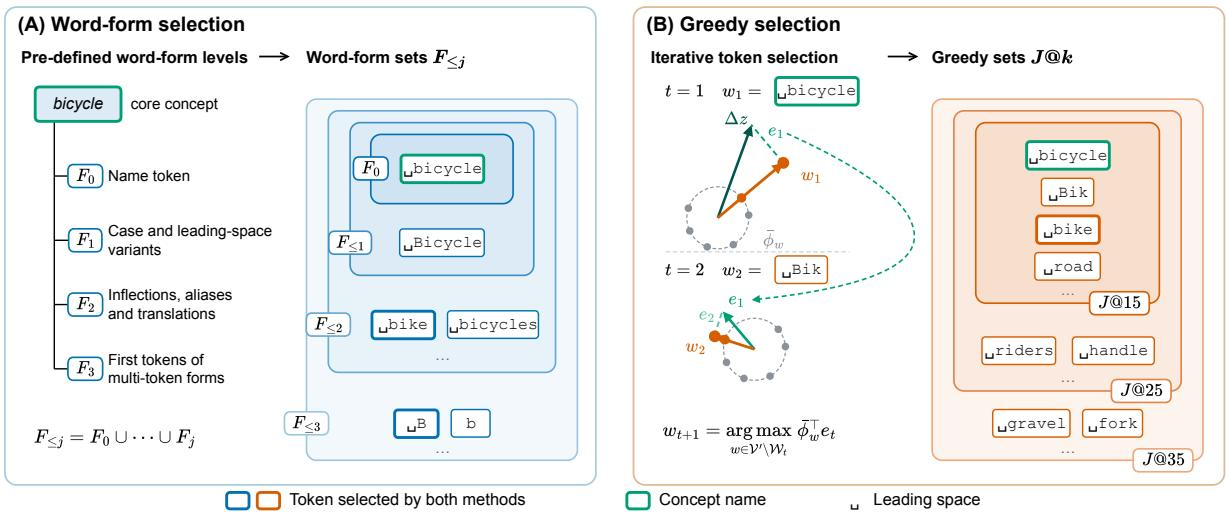
Word-form selection collects pre-defined tokens that name the concept, including its case forms, inflections, aliases, translations, and the first tokens of multi-token forms. Greedy selection, on the other hand, reconstructs the concept-specific part of the hidden state using vocabulary directions chosen from the entire vocabulary via orthogonal matching pursuit.
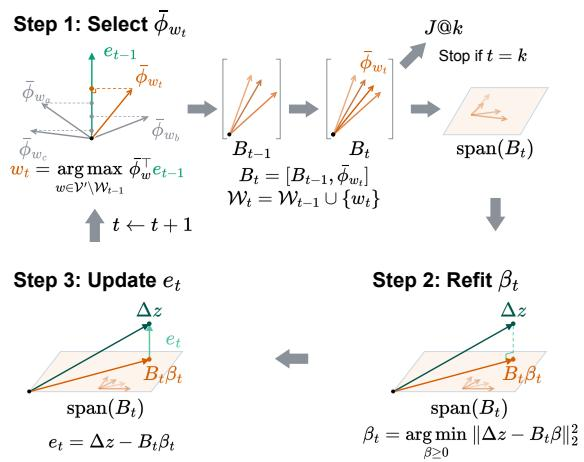
In the greedy selection process, the algorithm iteratively selects the token whose vocabulary direction has the largest inner product with the remaining state difference. It then refits the coefficients of all selected directions using non-negative least squares and updates the remaining difference. This process repeats until a specified budget of tokens is reached, capturing not only direct name forms but also related concepts that contribute to the representation.
To investigate whether the accessed concepts are actively used in downstream reasoning or merely present in the states, the authors perform counterfactual interventions. They define a source concept and a target concept, running the model on inputs for both to obtain their respective hidden states. Interventions are then applied at chosen layers during the forward pass.
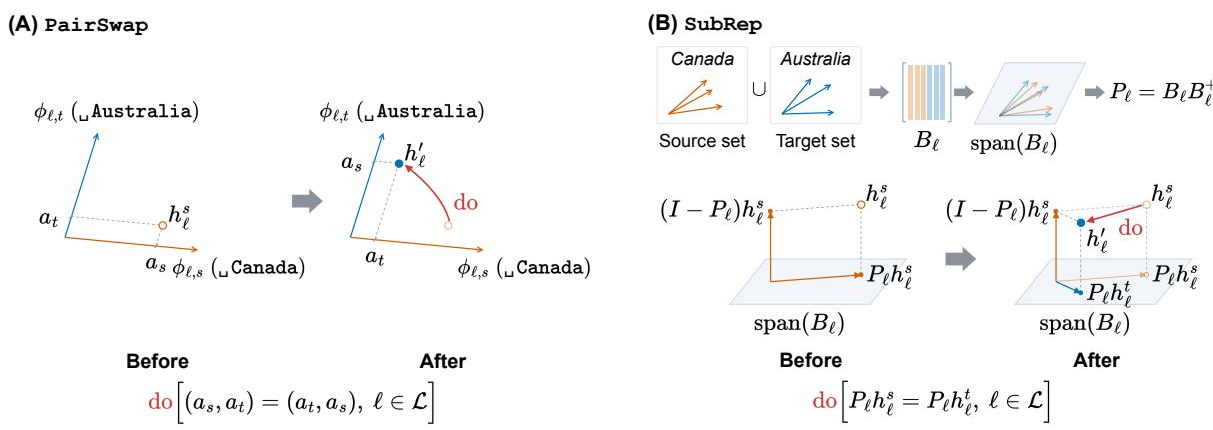
For single-token concepts, the authors utilize PairSwap, which exchanges the coordinates of the source and target states along their respective vocabulary directions. For concept direction sets, they introduce Subspace Replacement (SubRep). SubRep projects both the source and target states onto the subspace spanned by the combined concept directions of both sets. It then replaces the source state's component within this subspace with the target state's component, while retaining the orthogonal component of the source state. By comparing the model's answers before and after these interventions, the authors can verify if altering the concept representation directly influences the model's computational output.
Experiment
The paper evaluates a multimodal concept lens, MC-Lens, across VQA, object recognition, spatial readout, autoregressive generation, and counterfactual intervention settings. These experiments validate that image and text evidence improve concept readability, that expanded and greedy token sets capture broader concept-related information, and that query-dependent selective access emerges mainly within an estimated workspace. Causal interventions show that accessed concept directions influence direct, one-hop, and multi-hop reasoning, while comparisons across Qwen, DeepSeek, and Gemma models plus training checkpoints indicate shared workspace-like functions and progressive development of cross-modal alignment and selective access.
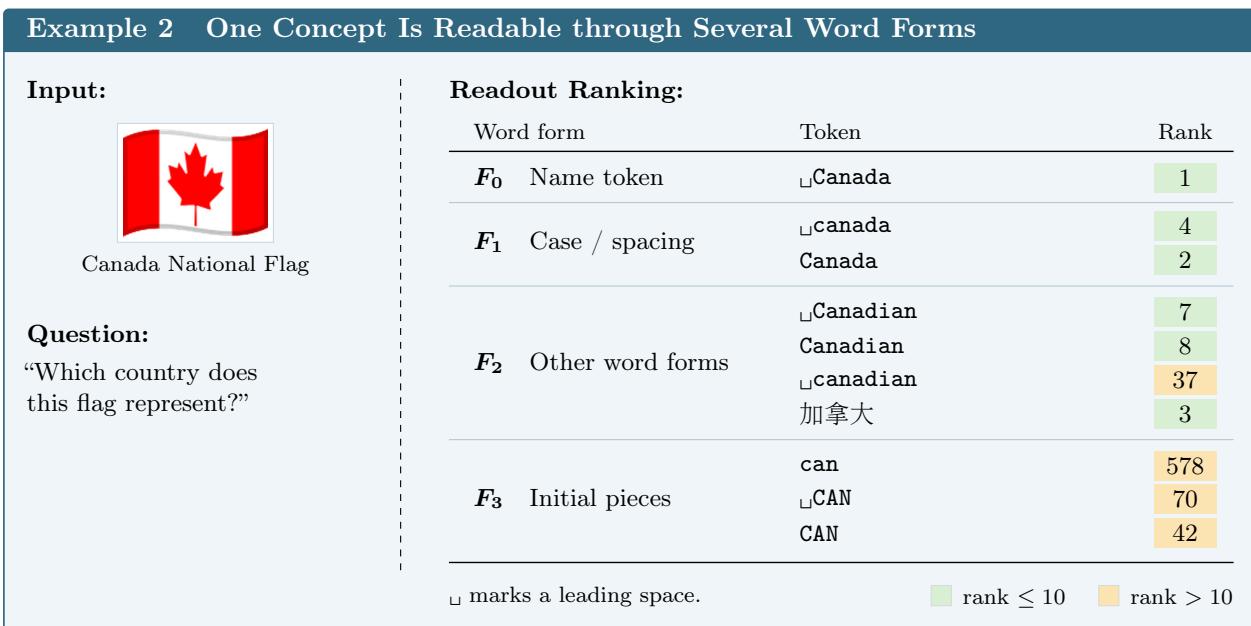
The same concept can be accessed through multiple word forms, and these forms differ in how readable they are. The canonical name form is the most readable, while case or spacing variants and related word forms rank lower. The canonical name token is the most accessible word form for the concept. Case or spacing variants and other related word forms are progressively less readable.
Greedy selection based on reconstruction weight can identify concept-related tokens outside a predefined word-form set. In the Canada flag example, out-of-set tokens such as 'maple', '.C', and 'bc' rank much lower in the readout than the word-form tokens but still show relatively large reconstruction weights. The top reconstruction-weight tokens include both word-form tokens ('Canada', 'Canadian') and tokens outside that set ('maple', '.C', 'bc'). Lower readout rank does not prevent an out-of-set token from having a relatively large reconstruction weight. The in-set tokens have the highest readout ranks, while the out-of-set tokens still appear among the largest reconstruction weights.
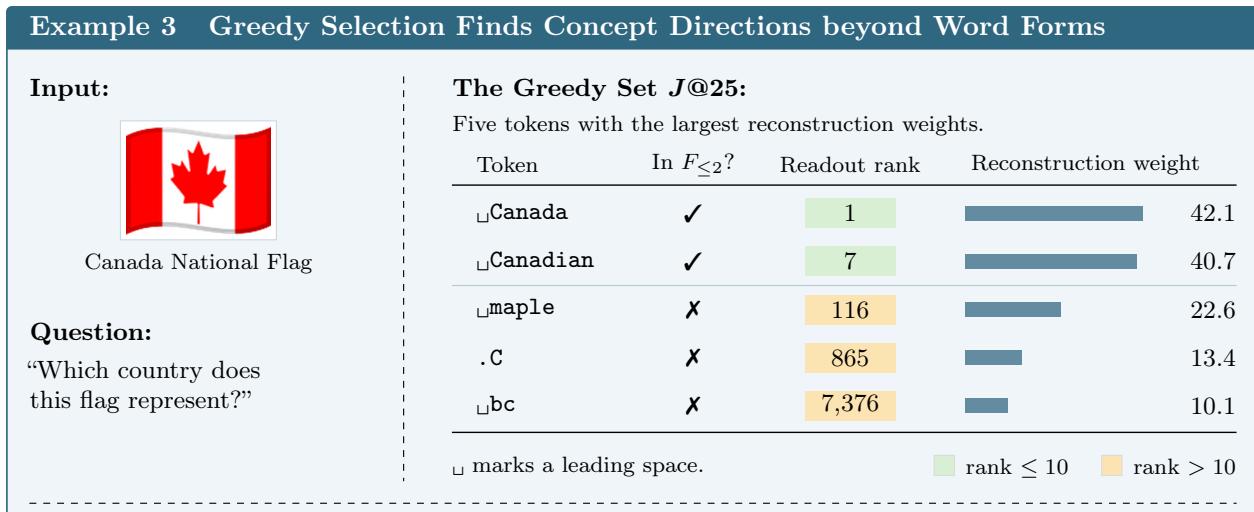
These experiments evaluate how multiple word forms affect access to a concept and how reconstruction weights reveal concept-related tokens. The canonical name form is the most readable and accessible, while case or spacing variants and related word forms are progressively less accessible. Greedy selection by reconstruction weight identifies concept-related tokens outside the predefined set, as shown by the Canada flag example where out-of-set tokens like “maple,” “.C,” and “bc” have lower readout ranks but still show relatively large reconstruction weights. Thus, reconstruction weight can surface concept-relevant tokens even when readout rank does not prioritize them.