Command Palette
Search for a command to run...
CURVDELTA: LOW-CURVATURE DELTA MODELING FOR SURGICAL LEARNING AND UNLEARNING
CURVDELTA: LOW-CURVATURE DELTA MODELING FOR SURGICAL LEARNING AND UNLEARNING
Zeguan Xiao Zhuocheng Liang Yun Chen Yong Wang Guanhua Chen Pinyan Lu
Abstract
A central challenge in adapting large language models (LLMs) is capability preservation: an adaptation can achieve its target while degrading general capabilities. We introduce CurvDelta, a scalable framework that incorporates the preservation constraint into the parameterization of the model update. By analyzing the local geometry of the preservation constraint around the pre-adaptation model, CurvDelta constructs a low-curvature space in which parameter updates leave the preservation loss nearly invariant. We make its construction practical for LLMs through Kronecker-factored approximate curvature (K-FAC) and a factorized projection. We also introduce CurvLoRA, a low-rank variant within the same preservation geometry, designed for more efficient adaptation. Both methods apply to preservation-constrained adaptation tasks such as capability learning and selective unlearning. We evaluate our methods on mathematical reasoning, code generation, and knowledge unlearning. For mathematical reasoning and code generation, our approaches achieve competitive downstream performance while better preserving general capabilities, offering a favorable acquisition–retention trade-off relative to the baselines. For knowledge unlearning, our main results on TOFU and MUSE show a better balance between targeted forgetting and knowledge retention than the baselines, with retention performance close to the from-scratch retraining reference.
One-sentence Summary
Researchers from Shanghai University of Finance and Economics, Alibaba Group, and Southern University of Science and Technology propose CurvDelta, a scalable framework that constructs a low-curvature parameter space using Kronecker-factored approximate curvature and factorized projection to preserve general capabilities during adaptation, along with its low-rank variant CurvLoRA, improving acquisition-retention trade-offs in mathematical reasoning, code generation, and knowledge unlearning.
Key Contributions
- The paper introduces CurvDelta, a scalable framework that incorporates preservation constraints into LLM update parameterization by constructing a low-curvature space around the pre-adaptation model so that updates leave preservation loss nearly invariant.
- The framework uses block-diagonal Kronecker-factored approximate curvature and factorwise spectral truncation for scalable construction, supports the low-rank CurvLoRA variant within the same preservation geometry, and derives a local preservation bound controlled by retained curvature and update magnitude.
- Evaluations on mathematical reasoning, code generation, TOFU, and MUSE show that CurvDelta and CurvLoRA achieve competitive target-task performance while better retaining general capabilities, with unlearning retention close to the retraining reference.
Introduction
Large language models must adapt after pretraining for new tasks or selective unlearning, but these updates need to preserve unrelated knowledge and capabilities. Prior methods such as replay, regularization, or constraining updates to orthogonal/null subspaces either do not guarantee the intended preservation constraint or impose indirect constraints that can harm the adaptation–preservation trade-off. The authors introduce CurvDelta, a framework that constructs a fixed low-curvature delta space from the local preservation geometry using block-diagonal K-FAC and factorwise spectral truncation, supporting both dense adaptation and a low-rank CurvLoRA variant with an explicit preservation bound.
Method
CurvDelta formulates adaptation as learning a model update Δθ around a frozen base model θ0, subject to an explicit preservation constraint. Given a task set Dtask and a preservation set Dpres, the preservation loss is defined as
Lpres(θ)=Ex∼Dpres[d(zθ(x),zθ0(x))],and the adaptation problem is
θminLtask(θ)s.t.Lpres(θ)≤ε.This formulation covers both capability learning and selective unlearning, with only the task objective changing between the two settings.
Instead of optimizing a Lagrangian penalty, CurvDelta incorporates the preservation constraint directly into the delta parameterization. The key idea is to restrict the realized update Δθ to directions in which the preservation loss has low curvature at θ0. This makes preservation a property of the update geometry rather than a post hoc regularization term. The preservation geometry is task-independent and can be reused across different task sets, task objectives, and delta parameterizations.
To justify this restriction, the method uses a second-order expansion of Lpres around θ0. Under mild conditions on the discrepancy d, the preservation Hessian reduces to a generalized Gauss-Newton matrix
Gpres=Ex∼Dpres[J0(x)⊤Hz(x)J0(x)],where J0(x) is the parameter Jacobian of the output and Hz(x) is the output-space Hessian of d. The local preservation cost is then approximated by
Lpres(θ0+Δθ)≈21Δθ⊤GpresΔθ.The preservation constraint therefore becomes
Δθ⊤GpresΔθ≤2ε.For a fixed update norm, the preservation loss is smaller when Δθ aligns with trailing eigenvectors of Gpres, which correspond to low-curvature directions of the preservation loss.
Because exact eigendecomposition is intractable at large language model scale, CurvDelta approximates Gpres with block-diagonal Kronecker-factored approximate curvature. For each adapted linear weight Wl∈Rdout×din, the corresponding block is
Gpres(l)≈Klin⊗Klout,where
Klin=E[al−1al−1⊤],Klout=E[glgl⊤],and al−1 and gl are the input activation and layer output gradient, respectively. These factors are estimated once at θ0 on Dpres using a Monte Carlo Fisher estimator.
To build a scalable low-curvature delta space, the method applies factorwise spectral truncation. For a spectral threshold γ, the leading eigenvectors of the two factors are retained in bases Uhout and Uhin. The projectors onto the complementary low-curvature directions are
Pout=I−Uhout(Uhout)⊤,Pin=I−Uhin(Uhin)⊤.A trainable pre-projection delta δ(ϕ) is then mapped to the applied delta as
ΔW:=Poutδ(ϕ)Pin.This produces a separable two-sided projection that constrains the update to the trailing eigenspaces of both K-FAC factors. The retained curvature is bounded by
κ=λrout+1outλrin+1in,where rout and rin are the ranks selected by spectral truncation. Consequently, the layerwise quadratic preservation cost satisfies
vec(ΔW)⊤(Kin⊗Kout)vec(ΔW)≤κ∥ΔW∥F2.Increasing γ reduces both κ and the dimension of the allowed update space.
The same projection supports two delta parameterizations. In the dense variant, CurvDelta parameterizes each δl as a full matrix initialized at zero, spanning the entire retained low-curvature space. In the low-rank variant, CurvLoRA uses a LoRA factorization
δl=BlAl,ΔWl=(PloutBl)(AlPlin),where Bl∈Rdout×r is initialized at zero and Al∈Rr×din. This restricts the applied update to rank at most r inside the same low-curvature space while avoiding materialization of a dense weight matrix.
During optimization, the base parameters and the estimated projectors remain fixed. The task loss is minimized over the delta parameters by differentiating through the projection. Because the projection is built into the parameterization, the realized update stays in the prescribed low-curvature space throughout training, regardless of the optimizer. This differs from post hoc gradient projection, which can be altered by adaptive optimizer rescaling.
Under the block-diagonal K-FAC model, the preservation loss decomposes over adapted layers and obeys the bound
Lpres(θ0+Δθ)≤21l∈T∑κl∥ΔWl∥F2.Thus, the update is feasible with respect to the local quadratic preservation constraint whenever
l∈T∑κl∥ΔWl∥F2≤2ε.The curvature coefficients κl are fixed by the precomputed preservation geometry, while the layer delta norms are determined by the optimization trajectory and learning-rate schedule.
Experiment
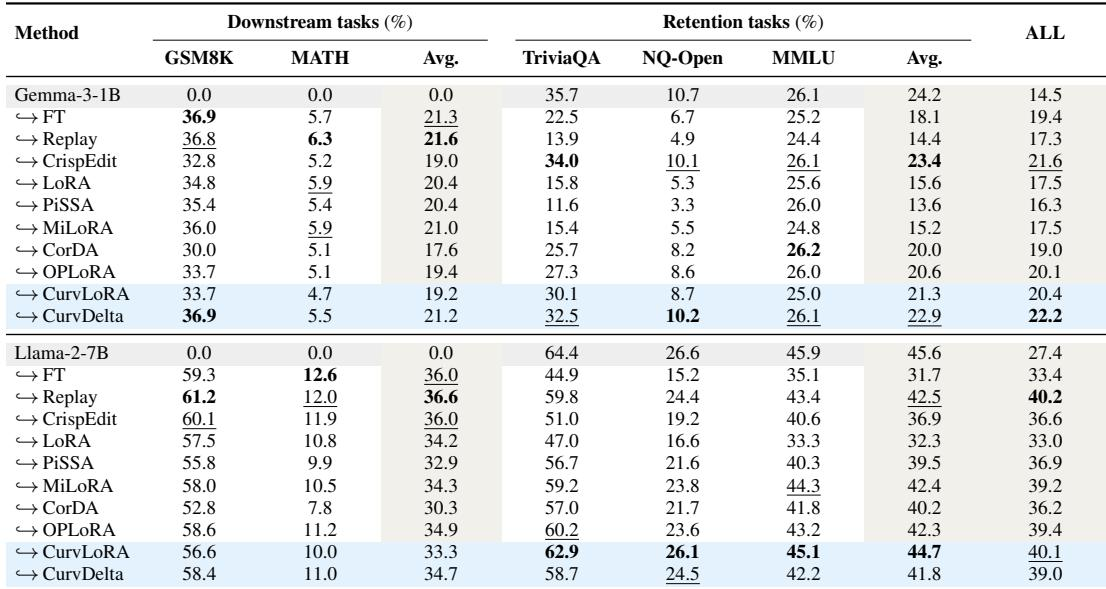
The experiments evaluate capability learning on math and code benchmarks and selective unlearning on TOFU and MUSE, comparing CurvDelta and CurvLoRA with full fine-tuning, replay, LoRA variants, and projection-based baselines across several model backbones. Across these settings, CurvDelta and CurvLoRA improve the trade-off between task adaptation or forgetting and retained knowledge, with CurvDelta generally delivering the strongest joint results and CurvLoRA remaining competitive with fewer trainable parameters. Ablations confirm that low-curvature directions, delta parameterization, and the spectral threshold support this balance, while the method is robust to preservation-data size and reduces runtime and memory relative to prior curvature-based approaches.
Full fine-tuning provides strong mathematical reasoning acquisition but consistently reduces general-knowledge retention. CurvDelta keeps downstream math performance close to full fine-tuning while substantially narrowing the retention gap, and CurvLoRA tends to preserve more general knowledge on Llama at some cost to downstream math performance. Full fine-tuning achieves strong downstream math gains but shows consistently lower retention performance than the base model. CurvDelta remains competitive with full fine-tuning on mathematical reasoning while substantially improving retention. CurvLoRA achieves the highest retention among adaptation methods on Llama, though its downstream math performance is lower.
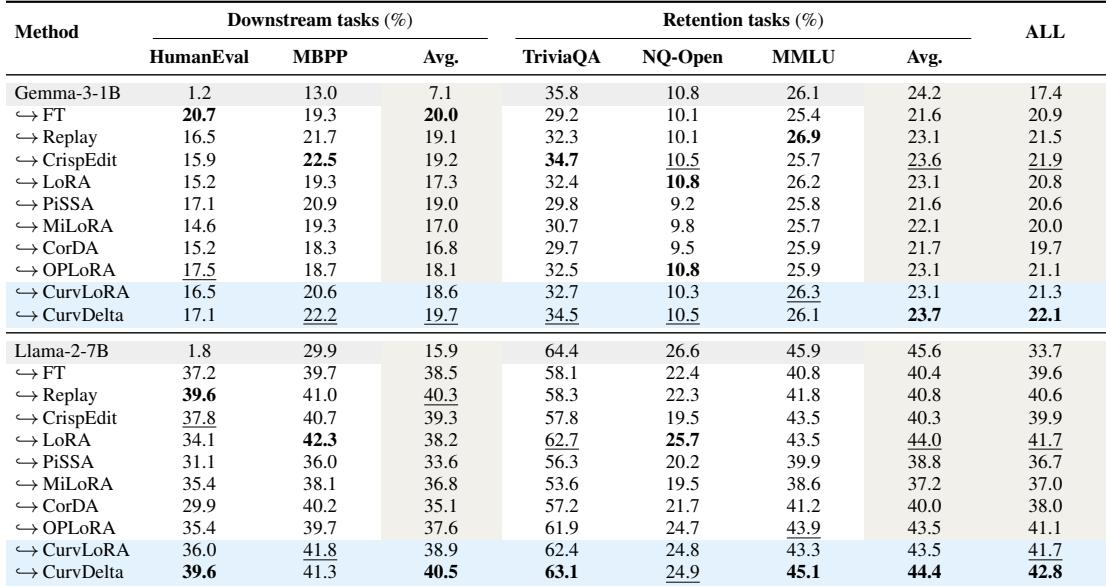
On the code generation benchmark for Gemma-3-1B, full fine-tuning produces the largest downstream gains but reduces retention relative to the base model. Replay and CrispEdit recover some retention while trailing full fine-tuning on downstream accuracy. The reported CurvDelta method yields the strongest joint downstream and retention trade-off across backbones, with downstream performance close to or above full fine-tuning and the highest average retention among adaptation methods. Full fine-tuning on Gemma-3-1B achieves the highest downstream average among the listed methods, but its retention average drops below the base model. Replay and CrispEdit improve retention over full fine-tuning while giving up some downstream code-generation accuracy. Low-rank adaptation with LoRA and PiSSA underperforms full fine-tuning on downstream code generation, with PiSSA retaining less general knowledge than LoRA. CurvDelta is reported to obtain the best joint averages on both backbones, staying close to or above full fine-tuning on downstream tasks while retaining the most general knowledge among adaptation methods.
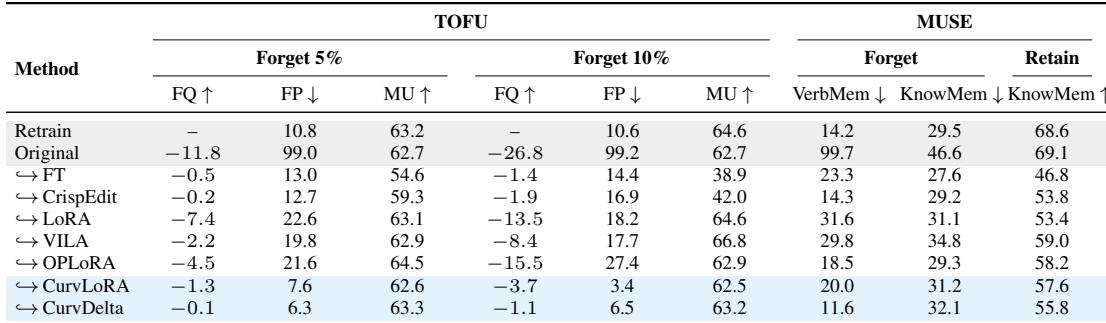
Under SimNPO, CurvDelta improves the forgetting-retention balance on both TOFU and MUSE compared with full fine-tuning, CrispEdit, and LoRA. On TOFU it achieves the strongest forget quality in both forget splits while keeping utility close to retraining, and on MUSE it most reduces verbatim memorization. Its low-rank variant further lowers forget-answer probability in the 10% TOFU split but trails the dense variant in forget quality while retaining more knowledge on MUSE. CurvDelta attains the strongest Forget Quality on both TOFU forget splits and keeps model utility close to Retrain. CurvLoRA further lowers forget-answer probability in the 10% TOFU split, but its Forget Quality is lower than dense CurvDelta. On MUSE, CurvDelta achieves the lowest verbatim memorization, while CurvLoRA retains more knowledge.
The experiments compare full fine-tuning, parameter-efficient adapters, and replay or CrispEdit methods on mathematical reasoning and code generation, then assess SimNPO unlearning on TOFU and MUSE. Full fine-tuning consistently achieves strong downstream gains but reduces general-knowledge retention, while CurvDelta provides the best overall trade-off by staying close to or above full fine-tuning on downstream tasks and retaining the most knowledge across backbones. CurvLoRA tends to preserve more general knowledge, especially on Llama and MUSE, but often yields weaker downstream or forget-quality performance. Under SimNPO, CurvDelta improves the forgetting-retention balance by achieving strong forget quality and utility close to retraining, with its low-rank variant reducing forget-answer probability in one TOFU split at some cost to forget quality.