Command Palette
Search for a command to run...
Decoupled Predictive Decision Making: A Shared Conditional Predictor for Agents
Decoupled Predictive Decision Making: A Shared Conditional Predictor for Agents
Lang Mo Xingxuan Zhang Qi Wang Mingchao Hao Hao Yuan Chunjing Gan Wang Lu Peng Cui
Abstract
Agent decisions depend on empirical relationships that deployment observations reveal and task descriptions alone may leave unresolved. Learning these relationships requires a mechanism that turns historical evidence into predictions. We formulate agent decision making through general-purpose conditional inference, introducing Decoupled Predictive Decision Making (DPDM), an architecture in which a shared pretrained learner serves heterogeneous decision roles. Language models provide semantic representations of current and historical records, while a general-purpose conditional predictor predicts task-defined targets from the represented evidence. Pretraining supplies a reusable inference capability; deployment evidence instantiates problem-specific predictions without updating either model’s neural parameters. Tool judgments, candidate preferences, and reasoning assessments thus share a common evidence-and-query interface, with predictions mapped to choices by a decision rule. This architecture establishes complementary sources of agent capability: semantic knowledge acquired through language pretraining and empirical inference acquired through structured-data pretraining. We instantiate the conditional predictor with LimiX-2, pretrained on structured data, which is shared across all evaluated decision roles. Across five task categories, DPDM accepts representations from semantic encoders such as Qwen3.5. With Qwen3.5-27B as the semantic encoder, DPDM raises mean accuracy across 50 benchmarks from 78.80% with few-shot prompting to 84.92% under their respective evaluated history budgets, and reaches 82.33% with identical histories and queries. On ToolPRMBench’s BFCL and ToolSandbox tasks, absolute accuracy gains are 34.26% and 28.87%, respectively, at the methods’ respective evaluated history budgets. Accuracy improves as history grows. With identical imbalanced histories, the absolute gain in mean balanced accuracy is 14.51% across five reasoning-step assessment tasks and four encoders. DPDM makes learning from experience an independently improvable foundation-model capability, creating a shared route for advances in conditional prediction to improve decisions across agent tasks.
One-sentence Summary
Researchers from Stable AI and Tsinghua University propose Decoupled Predictive Decision Making (DPDM), an architecture that pairs a shared LimiX-2 conditional predictor with semantic encoders such as Qwen3.5, improving mean accuracy across 50 benchmarks from 78.80% to 84.92% by enabling empirical inference without updating model parameters.
Key Contributions
- The paper presents Decoupled Predictive Decision Making (DPDM), an architecture that reformulates task-defined agent decisions as conditional prediction problems through a semantic encoder, a shared pretrained conditional predictor, and a decision rule.
- The conditional predictor is instantiated with LimiX-2, allowing heterogeneous decision roles such as tool judgments, candidate preferences, and reasoning assessments to share one evidence-and-query interface without task-specific neural-parameter updates.
- With Qwen3.5-27B as the semantic encoder, DPDM raises mean accuracy across 50 benchmarks from 78.80% with few-shot prompting to 84.92% under their respective evaluated history budgets, and achieves absolute gains of 34.26% and 28.87% on ToolPRMBench BFCL and ToolSandbox tasks; accuracy improves as history grows.
Introduction
Generalist agents need to combine semantic interpretation with learning from feedback, because the best tool choice, retrieval strategy, or reasoning allocation can depend on problem conditions. Prior language-model-centered systems often perform semantic interpretation, empirical inference, and answer generation within the same pretrained model, leaving the mechanism for learning deployment-specific relationships not separately replaceable or independently improvable. The authors introduce Decoupled Predictive Decision Making (DPDM), which reformulates task-defined agent decisions as conditional prediction problems. A language model encodes the decision context and candidates, a shared conditional predictor estimates the unknown target from historical feedback, and a decision rule converts the prediction into a choice. The approach is instantiated with LimiX 2, a structured-data foundation model, and demonstrates that a single frozen conditional predictor can improve decision accuracy across tasks and semantic encoders without task-specific neural-parameter updates.
Method
The authors propose an architecture that decouples the semantic understanding of a decision problem from the utilization of historical feedback to resolve it. The overall framework consists of a semantic encoder to represent the current context and candidate choices, a shared conditional predictor to estimate the decision target from represented historical examples, and a decision rule to select the final answer.
As shown in the figure below:
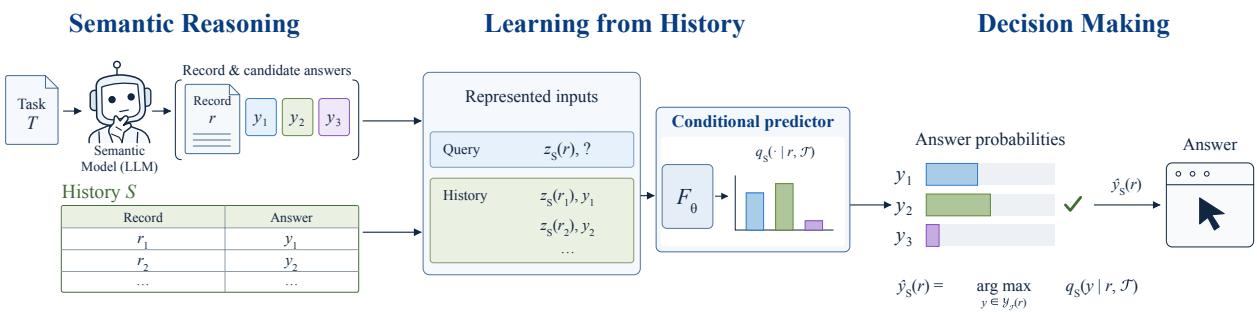
The pipeline begins by formulating decision making as a history-conditioned prediction problem. A task specification defines the observable input fields, the meaning of the prediction target, and the candidate answer set YF(r) for a given record r. The system maintains a history of records and their observed targets, denoted as S={(ri,yi)}i=1M, while a query record r describes the current decision with an unknown target y. The primary objective is to estimate the conditional probability distribution qS(y∣r,F) over the candidate answers.
To achieve this, the authors employ a shared conditional predictor Fθ that takes three inputs: represented historical records, their observed targets, and a represented query. A frozen semantic encoder Jϕ first represents each record in the context of its target question and candidate descriptions. This interface places decision-specific structure into the represented inputs and historical evidence, allowing the shared conditional predictor to infer the answer without requiring task-specific updates to its neural parameters. A feature adapter then maps these inputs into a structured representation:
zS(r)=AψS(Jϕ(r;T),bT(r))Here, ψS denotes any state fitted from historical inputs, such as a feature transformation. This same fitted mapping is applied consistently to both historical and query records. Historical targets are excluded from the semantic record encoding and supplied separately as supervision. The conditional predictor receives the represented history S~={(zS(ri),yi)}i=1M and the represented query zS(r) to compute the output probabilities:
qS(⋅∣r,T)=Fθ(S~,zS(r))The authors instantiate the conditional predictor Fθ using LimiX-2, a model pretrained for conditional prediction over structured data independently of the evaluated decision tasks. Both the semantic encoder parameters ϕ and the conditional predictor parameters θ remain fixed during deployment.
When adapting to new observations, the system updates the history supplied to the conditional predictor. Newly obtained labels or observed outcomes provide additional records ΔS, yielding an expanded history S+=S∪ΔS. The core model parameters remain unchanged, meaning ϕ+=ϕ and θ+=θ. However, the history-dependent adapter state ψS+ and the resulting prediction qS+ may change. Any required input transformations are refitted on the updated historical inputs and applied consistently, while semantic representations can be reused if the encoder and record specification remain unchanged. Finally, a decision rule selects the answer by taking the argmax over the predicted candidate probabilities.
Experiment
Across 50 benchmarks and five task categories, the experiments test a shared frozen conditional predictor (DPDM) with Qwen and Llama semantic encoders against direct zero-shot and few-shot prompting, including matched history and controlled ablation settings. The results show that DPDM improves decision accuracy for all encoders and task categories, benefits from growing histories and distinct labeled observations, and is less affected by majority-label bias than few-shot prompting. Interventions confirm that both historical input-target pairings and semantic features contribute to performance, while cost measurements show reduced repeated semantic processing of histories.
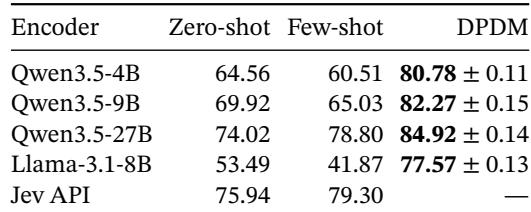
DPDM outperforms few-shot prompting for all four semantic encoders in every category, with overall accuracy rising substantially for smaller models. Gains are broad across individual benchmarks, as DPDM improves nearly all or all of the 50 datasets depending on the encoder. External API few-shot prompting reaches higher accuracy than its zero-shot setting, but no DPDM comparison is reported for that API. DPDM outperforms both zero-shot and few-shot prompting for all four semantic encoders, including cases where few-shot prompting underperforms zero-shot. DPDM improves accuracy on nearly all or all of the 50 benchmarks depending on the encoder, with the largest prompting-to-DPDM gain observed for Llama-3.1-8B.
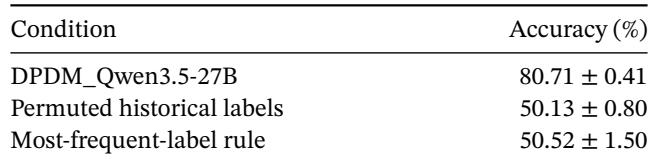
Correct historical input-target pairings substantially improve decision accuracy on the six evaluated tasks. Permuting historical labels while preserving class counts reduces performance to roughly the level of always predicting the most frequent historical class. The original pairings outperform both controls on all six tasks. Original historical input-target pairs yield a large accuracy advantage over permuted labels. Permuted labels and the most-frequent-label rule achieve similar accuracy, indicating class frequency alone explains little of the performance. The advantage of correct pairings holds across all six evaluated tasks.
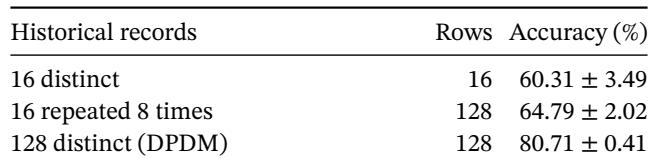
Across six tasks, using 128 distinct historical examples yields substantially higher accuracy than reusing the same 16 examples eight times. Repeating examples provides only a modest improvement over the smaller 16-row history, while expanding to distinct records offers clear gains. Distinct observations therefore contribute more useful historical evidence than repeated rows at the same total history size. Repeating 16 examples eight times improves accuracy only modestly compared with using 16 distinct examples. At the same 128-row budget, 128 distinct observations outperform repeated examples by 15.92 percentage points, with gains on all six tasks.
The full DPDM model achieves the highest accuracy across all tested history sizes and tasks. Removing semantic features lowers accuracy at every history size, while permuting historical labels causes an even larger decline. Larger histories improve all conditions, but the gains are strongest when semantic features and correct input-target pairings are preserved. DPDM outperforms both ablations at every tested history ceiling. Permuting historical labels is more damaging than removing semantic features across all history sizes. At the highest history ceiling, DPDM beats both ablations on all eight tasks. Accuracy improves with larger histories for all conditions, but the full model benefits most.
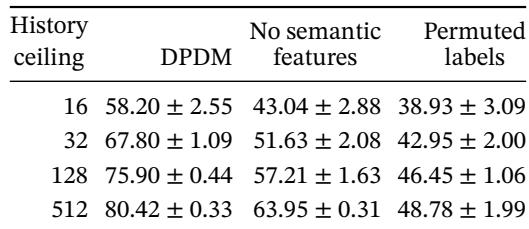
The experiments evaluate DPDM against zero-shot and few-shot prompting across four semantic encoders and many benchmarks, then probe the role of historical information through controlled ablations. DPDM consistently outperforms prompting baselines, with especially large gains for smaller encoders, and the results show that correct historical input-target pairings are essential because permuting labels reduces performance to majority-class levels. Using distinct historical examples rather than repeating a small set also yields substantial accuracy gains. Further ablations confirm that the full DPDM model with semantic features and correct pairings benefits most from larger histories, while removing semantic features lowers accuracy and permuting historical labels causes an even larger decline.