Command Palette
Search for a command to run...
DTCA: Denoising Token Credit Assignment for Reinforcement Learning in Diffusion Language Models
DTCA: Denoising Token Credit Assignment for Reinforcement Learning in Diffusion Language Models
Hongze Chen Miao Pan Lizhou Liang Qinfeng Li Xinyin Ma Yongliang Shen Weishi Wang Daniel Dahlmeier Xuhong Zhang Wenqi Zhang
Abstract
Diffusion language models (DLMs) generate text through iterative denoising, enabling bidirectional context modeling and parallel token refinement. Recent studies have applied reinforcement learning (RL) to DLMs and improved their reasoning performance. However, the iterative denoising process makes credit assignment more challenging, as final outcome rewards provide limited information about how different tokens contribute to the final output. In this paper, we propose Denoising Token Credit Assignment (DTCA), a framework for token-level credit assignment in reinforcement learning for diffusion language models. DTCA estimates token contributions by measuring the improvement in prediction confidence of remaining masked positions after token commitment and groups these signals according to part-of-speech (POS) categories. These contribution weights are used to select informative denoising timesteps and assign token-level learning signals during RL training. DTCA further calibrates these learning signals according to token-level entropy changes induced by policy updates. Experiments on LLaDA-8B-Instruct show that DTCA consistently improves mathematical reasoning performance across different generation budgets, with gains of up to 9.0 points on MATH500 and 5.3 points on GSM8K over the base model.
One-sentence Summary
Zhejiang University, National University of Singapore, and SAP propose Denoising Token Credit Assignment (DTCA), a token-level credit assignment framework for reinforcement learning in diffusion language models that weights token contributions via confidence gains after token commitment and part-of-speech (POS) grouping, calibrates learning signals by token-level entropy changes, and improves LLaDA-8B-Instruct mathematical reasoning by up to 9.0 points on MATH500 and 5.3 points on GSM8K over the base model.
Key Contributions
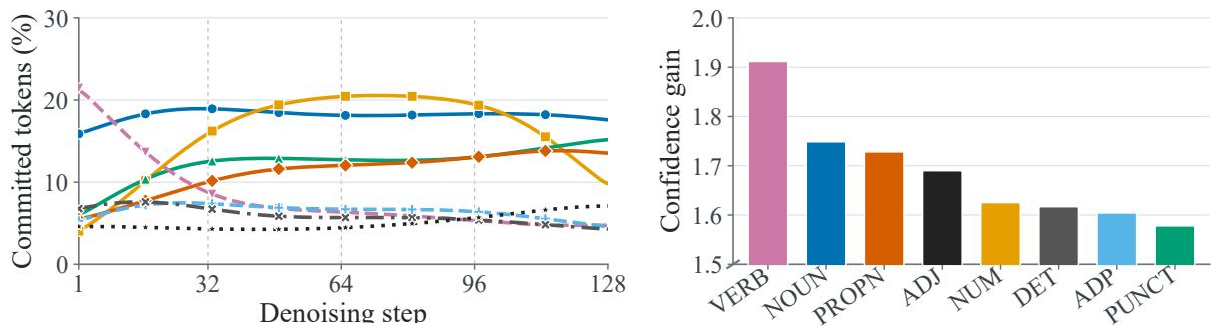
- The paper analyzes denoising behavior across part-of-speech (POS) categories in diffusion language models and proposes Denoising Token Credit Assignment (DTCA), a token-level credit assignment framework for reinforcement learning. DTCA estimates token contributions from prediction confidence improvements of remaining masked positions after token commitment and aggregates these signals by POS category.
- DTCA uses the resulting contribution weights to select informative denoising timesteps and to assign token-level learning signals. It also adapts entropy-based credit calibration from OPEFO to the diffusion language model setting for more stable policy updates.
- Experiments on LLaDA-8B-Instruct show consistent mathematical reasoning improvements across generation budgets, with gains up to 9.0 points on MATH500 and 5.3 points on GSM8K over the base model. Ablations validate the contribution-based credit assignment and entropy calibration components.
Introduction
Diffusion language models (DLMs) have emerged as an alternative to autoregressive generation because they support bidirectional context modeling and parallel token refinement. Recent reinforcement learning methods for DLMs typically derive learning signals from denoising trajectories or intermediate states, but this coarse view is insufficient because tokens are committed gradually and each committed token can affect how the remaining masked positions are refined. Estimating fine-grained token contributions is challenging because multiple tokens are committed at the same denoising step, their effects interact through the shared denoising process, and contribution estimates can vary substantially across rollouts. The authors propose Denoising Token Credit Assignment (DTCA), which estimates token contributions from confidence improvements on remaining masked positions, aggregates these signals by part-of-speech categories to obtain more stable weights, uses the weights for denoising timestep selection and token-level RL signals, and incorporates entropy-based credit calibration inspired by OPEFO. Experiments on LLaDA-8B-Instruct show that DTCA improves mathematical reasoning by up to 9.0 percentage points on MATH500 and 5.3 percentage points on GSM8K over the base model.
Method
The authors propose Denoising Token Credit Assignment (DTCA), a token credit assignment framework designed for reinforcement learning in diffusion language models. DTCA estimates token contributions from denoising refinement dynamics and leverages the resulting contribution weights for informative denoising state selection and token-level credit assignment. Furthermore, the framework calibrates the token-level learning signals according to the entropy changes induced by policy updates.
As shown in the figure below, the overall pipeline consists of contribution estimation, timestep selection, credit assignment, and entropy calibration.
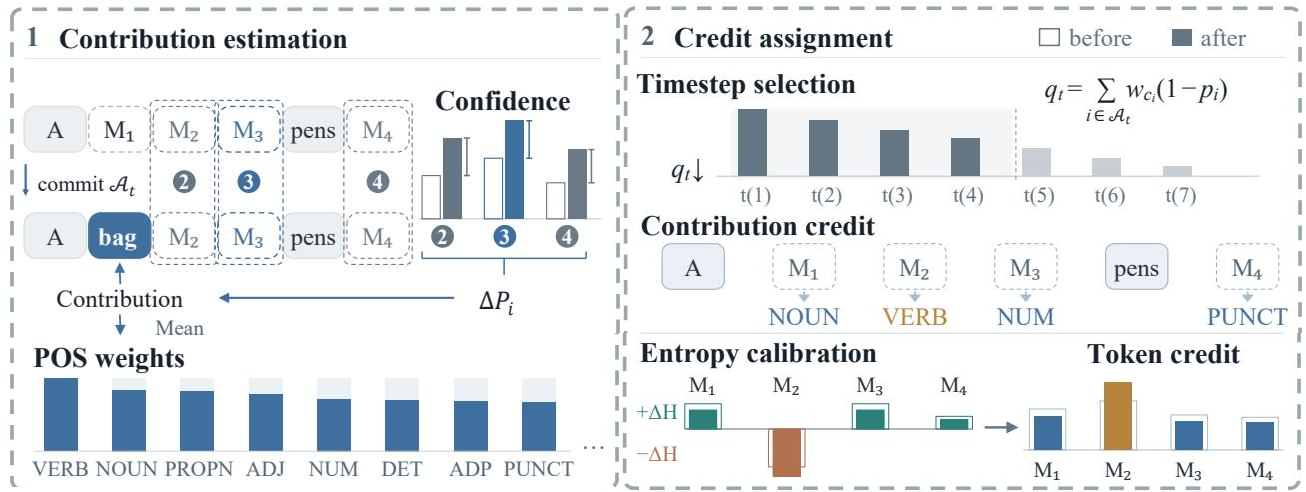
To evaluate the refinement contribution of each committed token, DTCA measures the improvement in the prediction confidence of the remaining masked positions. Given a fixed prompt and a denoising state, the aggregate prediction confidence over the remaining masked positions is defined as the sum of the maximum prediction probabilities:
F(x;M)=j∈M∑v∈Vmaxpθ,j(v∣q,x)where j indexes a masked position, V is the vocabulary, and pθ,j(v∣q,x) is the probability assigned to token v at position j. The refinement contribution estimate for a committed token is computed as:
ΔPi=max(0,F(xt(i);M)−F(xt;M))To avoid the substantial computational overhead of evaluating individual token effects during policy optimization, DTCA constructs these estimates from offline denoising rollouts. The estimates are then aggregated by part of speech categories to reduce variance. The average refinement effect for a category c is calculated as:
mc=Nc1i:ci=c∑ΔPiThese category contributions are normalized into bounded contribution weights wc within the range [0.8,1.2] to prevent excessive credit scaling while preserving the original reinforcement learning objective.
The category contribution weights are utilized to identify the most informative denoising timesteps for training. For a given timestep, the importance score is computed by combining the contribution weights with the uncertainty of the committed tokens:
qt=i∈At∑wci(1−pi)where pi denotes the confidence of the token when committed. DTCA ranks the timesteps based on this score and selects the smallest set whose cumulative score reaches a predefined fraction of the total score, ensuring stable and efficient training.
Within the selected timesteps, DTCA assigns distinct credits to tokens based on their part of speech categories. The credit weight for a specific token is determined by normalizing its category contribution weight against the average weight of all tokens in the optimization set:
at,i=∣Bt∣1∑k∈BtwckwciThis normalization ensures the average credit within each timestep remains equal to one. The final token-level learning signal is obtained by scaling the original timestep advantage:
At,i=at,iAtConsequently, tokens from categories with higher estimated refinement contributions receive stronger learning signals.
To account for varying entropy changes across different denoising states, DTCA incorporates an entropy-based credit calibration module. The entropy change induced by the policy update for a target position is estimated as:
ΔHt,i(b)=−ηAt,i(b)(1−pi(b))2(logpi(b)+Hi(b))where pi(b) is the probability assigned by the current policy and Hi(b) is the entropy of the full prediction distribution. The updates are separated into entropy-increasing and entropy-decreasing sets. A separate entropy flow balancing coefficient λb is computed for each response to balance these updates. This coefficient is then used to rescale the token-level learning signals, amplifying or attenuating the credits depending on the direction of the entropy change, thereby refining the reinforcement learning optimization process.
Experiment
The experiments evaluate DTCA by initializing RL training from LLaDA-8B-Instruct on MATH and testing on MATH500 and GSM8K under different generation budgets, comparing against supervised and diffusion language model RL baselines. DTCA consistently improves over the base model, especially at limited denoising budgets, and ablations show that both contribution-based credit assignment and entropy calibration contribute to performance. Further analyses indicate that contribution credit shapes token-level update quality while entropy calibration stabilizes later policy optimization, and the learned denoising behavior changes token commitment patterns in a category-specific rather than uniform way.
DTCA improves over the LLaDA-8B-Instruct base model on both MATH500 and GSM8K across all evaluated generation budgets. The gains are largest at the smallest budget and remain positive as budget increases. Ablating either contribution-based credit assignment or entropy calibration reduces accuracy, indicating both components contribute to DTCA performance. DTCA reports the highest accuracy in every evaluated benchmark and budget setting. Relative to the base model, DTCA gains are strongest at budget 128 and decrease but remain positive at budgets 256 and 512. Removing contribution credit or entropy calibration consistently lowers accuracy, with the entropy calibration removal showing larger drops at the 512 budget on both benchmarks.
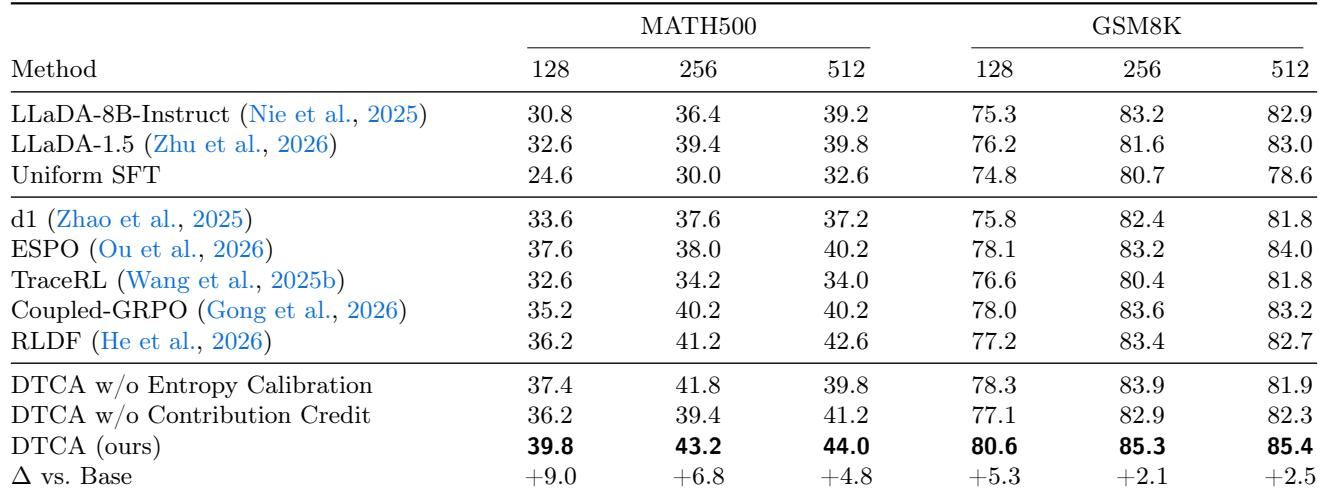
DTCA is evaluated against the LLaDA-8B-Instruct base model on MATH500 and GSM8K across multiple generation budgets, and it improves accuracy in every setting, with the largest gains at the smallest budget and smaller but still positive gains at larger budgets. Ablation studies show that removing either contribution-based credit assignment or entropy calibration reduces performance, and removing entropy calibration causes larger drops at the 512 budget, indicating that both components are important. Overall, the results validate that DTCA consistently outperforms the base model and that its credit assignment and calibration mechanisms both contribute to its accuracy.