Command Palette
Search for a command to run...
RULER: Instance-aware Rubric Rewards for SVG Generation
RULER: Instance-aware Rubric Rewards for SVG Generation
Hangyu Ran Yuhao Zheng Yingying Zhang Kevin Qinghong Lin Han Peng
Abstract
Generating Scalable Vector Graphics (SVG) code from natural-language instructions is an open-ended task without absolute visual ground truth, leaving both evaluation and policy optimization without a faithful signal. Scalar metrics (CLIP, Aesthetic) calibrated on natural images transfer poorly to stylized vector content, and reusing them as RL rewards triggers reward hacking. We address both limitations with rubric-based scoring. We first establish empirically that prompting a vision–language judge with a multi-axis rubric correlates with human judgments far better than scalar metrics, both across samples and within instructions. Building on this finding, we introduce RULER (Instance-aware Rubric Rewards for Reinforcement LEaRning), which converts each instruction into an instance-aware rubric of six items spanning semantic, visual, and stylistic axes; a judge VLM scores rendered rollouts item-by-item, and the weighted satisfactions form a fine-grained reward optimized via Group Relative Policy Optimization. Because the rubric is derived from text alone, RULER requires neither paired SVG ground truth nor human preference labels. On MMSVG-Illustration and MMSVG-Icon, RULER lifts the rubric score from 0.432/0.395 to 0.693/0.683, surpassing dedicated SVG specialists and matching the substantially larger DeepSeek-V3, with ablations identifying rubric design as the active lever for RL on open-ended SVG generation. The project page is available at https://hangyuran.github.io/RULER/.
One-sentence Summary
Researchers from Ant Group, HKUST (Guangzhou), and University of Oxford propose RULER, an instance-aware six-item rubric spanning semantic, visual, and stylistic axes that a judge VLM scores for Group Relative Policy Optimization, which avoids scalar-metric reward hacking and paired labels and lifts MMSVG-Illustration and MMSVG-Icon rubric scores from 0.432/0.395 to 0.693/0.683, surpassing dedicated SVG specialists and matching DeepSeek-V3.
Key Contributions
- A rubric-based evaluation paradigm for SVG generation is established, showing that multi-axis rubric scores from a vision-language judge correlate more strongly with human judgments than scalar metrics, both across samples and within instructions.
- RULER is introduced, generating an instance-aware six-item rubric per instruction spanning semantic, visual, and stylistic axes and using a judge VLM to score rendered SVGs item-by-item; the weighted satisfactions form a dense reward optimized via Group Relative Policy Optimization without paired SVG ground truth or human preference labels.
- On MMSVG-Illustration and MMSVG-Icon, RULER lifts rubric scores from 0.432/0.395 to 0.693/0.683, surpassing dedicated SVG specialists and matching the larger DeepSeek-V3, with ablations identifying rubric design as the active lever for reinforcement learning on open-ended SVG generation.
Introduction
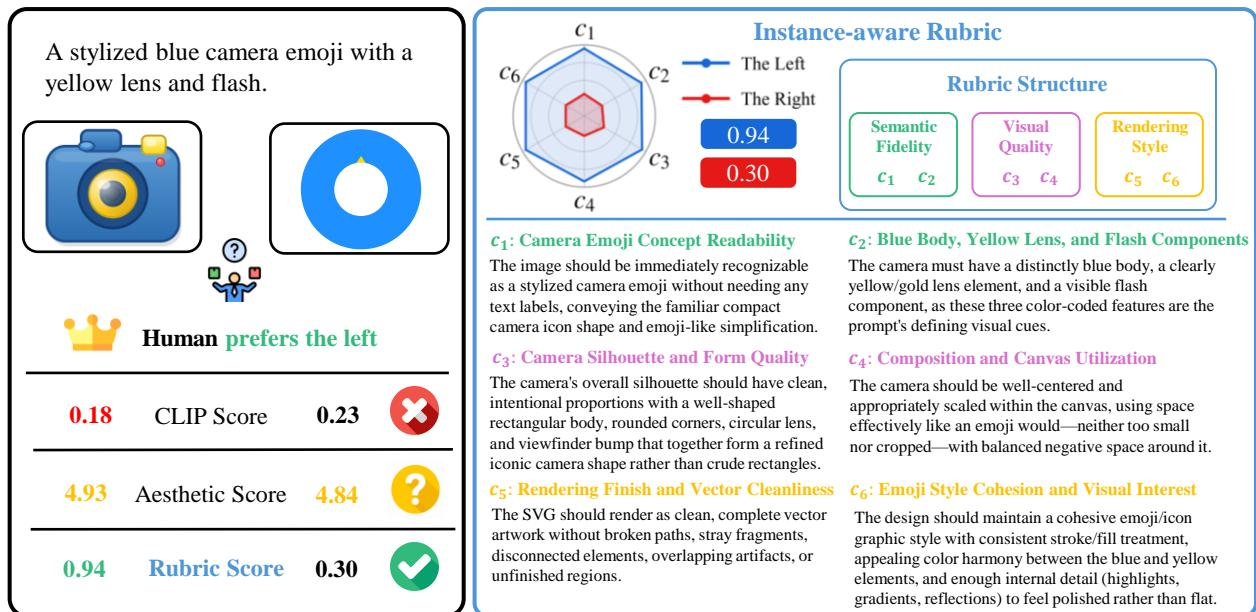
Generating Scalable Vector Graphics from natural language has become an important benchmark for visual code generation because SVG is structured, executable, and controllable, unlike descriptive text-to-image output. However, open-ended instruction-to-SVG synthesis has no single ground-truth rendering, and existing scalar metrics such as CLIPScore, aesthetic classifiers, and preference scores are calibrated mostly on photorealistic images, so they transfer poorly to stylized vector content and can reward broken SVGs over faithful ones. These unreliable signals also weaken reinforcement learning, since policies can drift toward easily inflated rewards rather than better generations. The authors address this by first showing that rubric-based evaluation with a vision-language judge correlates much more strongly with human preference, then introducing RULER, which converts each instruction into an instance-aware six-item rubric covering semantic fidelity, visual quality, and rendering style, and uses those rubric scores as dense reinforcement-learning rewards without requiring paired SVG ground truth or human labels.
Method
The authors formulate open-ended SVG generation as a token-level Markov Decision Process. Given a text instruction Q, a language model policy π autoregressively generates a structured SVG sequence Y=(y1,…,yT). At each step t, the state st=(Q,y<t) combines the instruction with the generated prefix, and the action at=yt is sampled from the policy. A deterministic rendering engine E then executes the completed code into a visual representation Tgen=E(Y). Since open-ended generation lacks absolute visual ground truth, designing a robust reward function R(⋅) is the central challenge.
To address this, the authors introduce RULER, a framework that replaces opaque scalar metrics with tailored, instance-aware evaluation criteria. The overall pipeline is illustrated below.
As shown in the figure below:
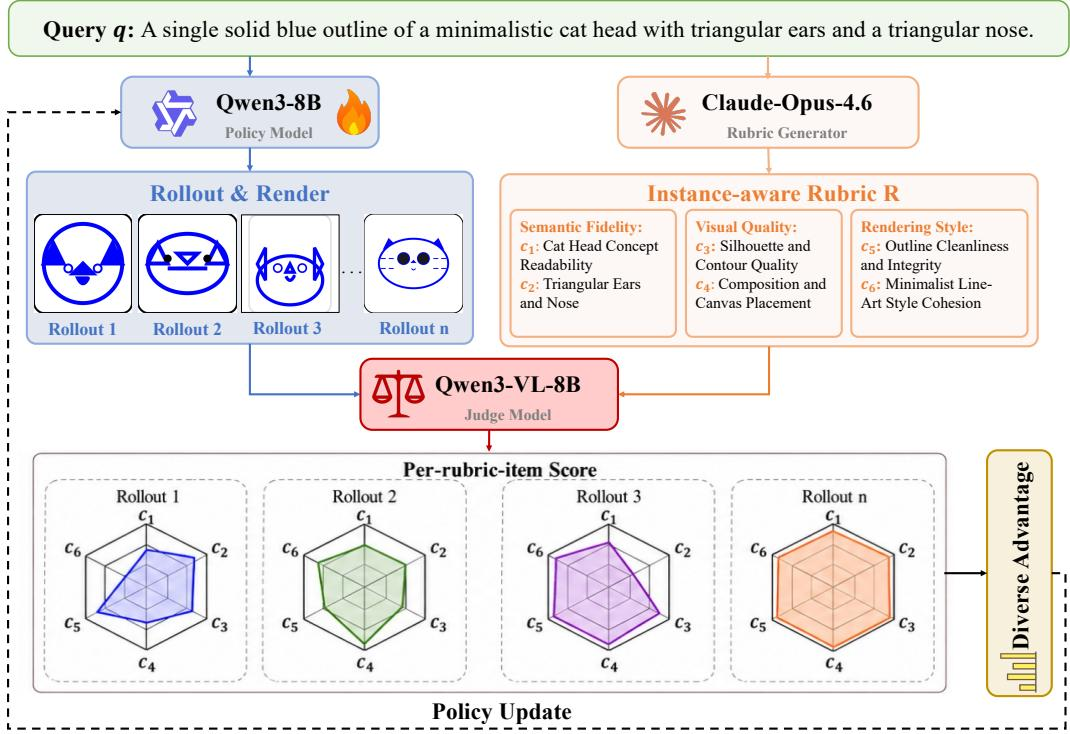
The framework begins with a scalable pipeline that constructs instance-aware rubrics directly from the unannotated text instruction. A frontier model Mrub is prompted to produce a discrete rubric consisting of six items grouped along three complementary axes: Semantic Fidelity, Visual Quality, and Rendering Style. These items are specified at the level of design intentions rather than exact pixel constraints to preserve the open-ended solution space. The rubric is formally defined as CQ={(ck,wk)}k=16, where ck encapsulates the instance-aware description and continuous scoring guide for item k, and wk is its importance weight.
During the reinforcement learning phase, the policy generates multiple SVG rollouts for a given instruction. Each rendered image is evaluated by a judge vision-language model Mjudge. Instead of querying for a holistic score, the judge follows the rubric CQ to independently rate the image on each item ck, producing a continuous satisfaction score sk. The final reward is computed as the normalized weighted average:
R(Igen)=∑k=16wk∑k=16wkskThis approach yields a dense, multi-dimensional reward signal.
To optimize the policy, the authors leverage Group Relative Policy Optimization (GRPO), which naturally exploits the diverse reward signals generated by the multi-axis rubric. For each instruction Q, the system samples G rollouts {Yi}i=1G from the old policy πθold. Each rollout is rendered and scored to obtain rewards Ri. The group-normalized advantages are then calculated as:
Ai=std({Rj}j=1G)+ϵRi−mean({Rj}j=1G)The model parameters are updated by maximizing the clipped surrogate objective:
LGRPO(θ)=EQ[G1i=1∑Gmin(ρiAi,clip(ρi,1−ϵ,1+ϵ)Ai)]where ρi=πθ(Yi∣Q)/πθold(Yi∣Q) is the sequence-level importance ratio. Through this iterative process, the policy is refined to maximize satisfaction across semantic, visual, and stylistic dimensions.
Experiment
The study evaluates RULER, an instance-aware rubric reward approach for open-ended SVG generation, on MMSVG Illustration and Icon benchmarks against diffusion-based, foundation LLM, and SVG specialist baselines. Human assessment first confirms that rubric-based scoring aligns more closely with human judgment than CLIP or aesthetic metrics. Main experiments show that RULER improves overall quality and human preference, while reward design analysis indicates that instance-aware rubrics avoid scalar reward hacking, ablations confirm all rubric axes contribute with visual quality being most influential, and robustness holds across different base models and rubric generators. Qualitative results further show that RULER preserves prompt-specific details and produces richer, more coherent compositions.
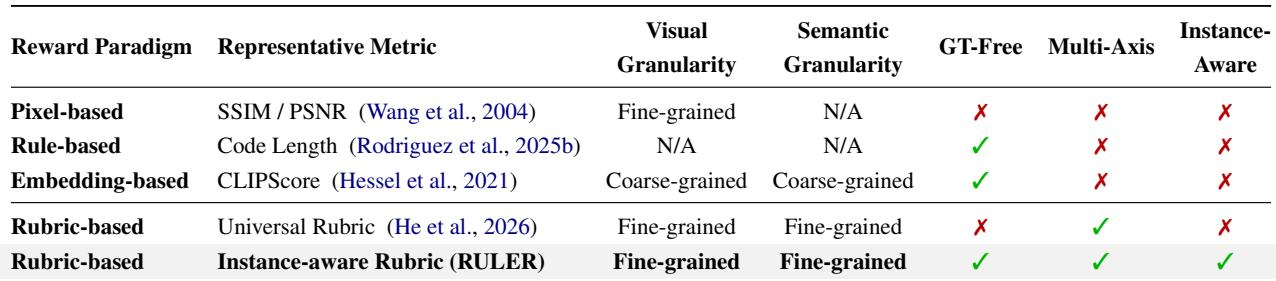
The comparison evaluates reward paradigms for SVG generation on visual granularity, semantic granularity, ground-truth-free operation, multi-axis feedback, and instance awareness. Most existing paradigms satisfy only a subset of requirements: pixel-based and universal rubric methods depend on references, while rule-based and embedding-based methods lack fine-grained or multi-axis assessment. The instance-aware rubric is the only paradigm that combines fine-grained visual and semantic feedback with ground-truth-free, multi-axis, and instance-aware scoring. Pixel-based rewards such as SSIM or PSNR are fine-grained visually but require ground-truth references and are neither multi-axis nor instance-aware. Rule-based rewards such as code length are ground-truth-free but do not inspect rendered images and provide no visual or semantic granularity. Embedding-based rewards such as CLIPScore are reference-free but only coarse-grained and not multi-axis or instance-aware. Universal rubric scoring offers fine-grained, multi-axis feedback but still requires ground-truth references and lacks instance awareness. Instance-aware rubric scoring is the only paradigm that meets all five desiderata, including fine-grained granularity and ground-truth-free operation.
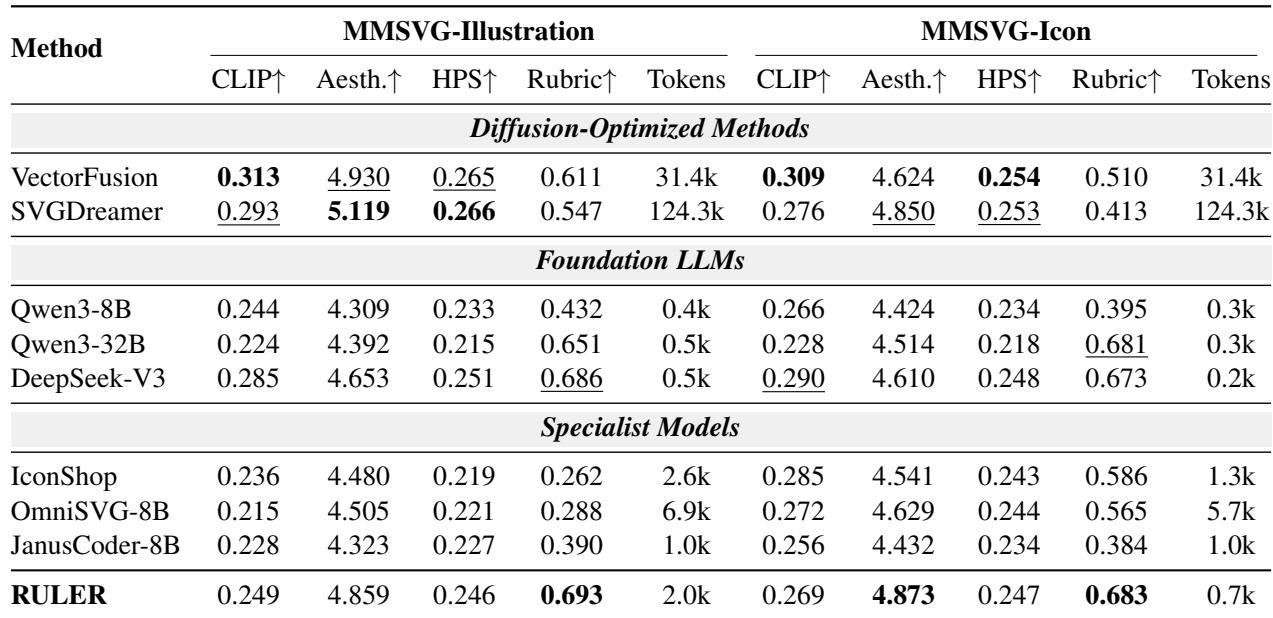
RULER attains the best universal Rubric scores on both MMSVG benchmarks while remaining competitive on CLIP, aesthetic, and HPS metrics. It outperforms diffusion-optimized, SVG-specialist, and foundation LLM baselines, including its own backbone, and reaches visual quality comparable to a much larger model. It also uses far fewer tokens than optimization-based methods. RULER improves universal Rubric scores substantially over dedicated SVG specialists and over its Qwen3-8B backbone on both Illustration and Icon benchmarks. Diffusion-optimized baselines require tens of thousands of tokens per output, while RULER achieves top rubric scores with far fewer tokens and competitive auxiliary metrics.
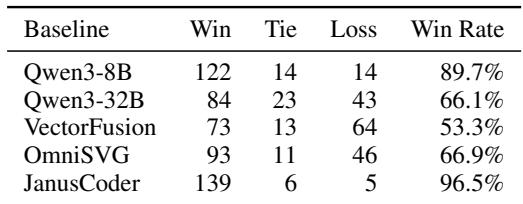
In a blinded pairwise human evaluation on 150 MMSVG-Bench prompts, RULER wins more often than every evaluated baseline once ties are excluded. Its non-tie win rates exceed 50% across all comparisons, with the largest margin over JanusCoder and the narrowest over VectorFusion. These results provide direct human evidence that RULER's gains extend beyond automated metrics. RULER achieves a non-tie win rate above 50% against all five baselines. The strongest human preference is over JanusCoder, while the closest contest is against VectorFusion.
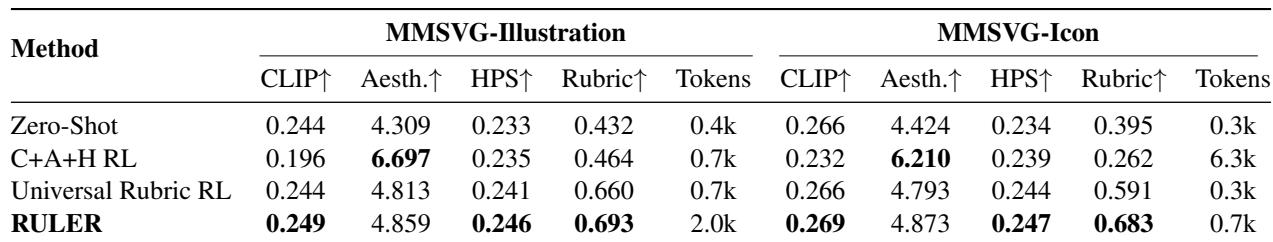
Across both MMSVG benchmarks, RULER achieves the highest rubric scores while also improving CLIP, aesthetic, and HPS over the zero-shot baseline. Universal Rubric RL substantially raises rubric scores but lacks prompt-specific granularity and remains below RULER. In contrast, the scalar C+A+H reward sharply inflates aesthetic scores while degrading CLIP and Icon rubric performance, indicating reward hacking. RULER records the best rubric scores on Illustration and Icon and delivers balanced gains over zero-shot across CLIP, aesthetic, and HPS. Universal Rubric RL improves rubric scores well above zero-shot and C+A+H RL, but the Icon rubric gap relative to RULER is larger than the Illustration gap. C+A+H RL over-optimizes aesthetic quality at the cost of CLIP and Icon rubric score, with a large token increase on Icon.
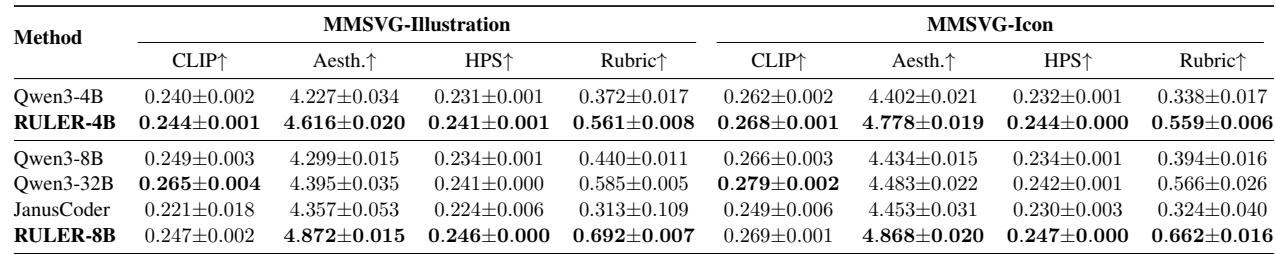
RULER improves over its base models at both 4B and 8B scales on MMSVG illustration and icon tasks. Gains appear across CLIP, aesthetics, HPS, and universal rubric scores, and the 8B variant remains ahead of the larger Qwen3-32B on rubric metrics. Repeated runs show low standard deviations, indicating stable improvements across base-model scales. RULER-4B raises the universal rubric score substantially over Qwen3-4B on both Illustration and Icon benchmarks. RULER-8B scores higher on universal rubric metrics than the larger Qwen3-32B, despite using fewer parameters. Improvements over base models are consistent across all reported metrics, including CLIP, aesthetics, HPS, and rubric scores.
The experiments first compare reward paradigms for SVG generation and find that only instance-aware rubric scoring satisfies fine-grained visual and semantic feedback, ground-truth-free operation, multi-axis assessment, and instance awareness. RULER achieves the best universal rubric results on both MMSVG benchmarks while remaining competitive on CLIP, aesthetic, and HPS metrics and using far fewer tokens than optimization-based methods. Blinded human evaluation confirms that RULER is preferred over all evaluated baselines, and ablation studies show that instance-aware rubric reinforcement learning produces balanced quality gains, whereas a scalar reward over-optimizes aesthetics and degrades other metrics. Scaling experiments further demonstrate stable improvements at 4B and 8B scales, with RULER-8B surpassing the larger Qwen3-32B on rubric metrics.