Command Palette
Search for a command to run...
An Empirical Study of Harness Design for Coding Agents
An Empirical Study of Harness Design for Coding Agents
Run-Ze Fan Zihao Zhang Simin Ma Yebowen Hu Shouju Wang Kaiqiang Song Fei Liu Hamed Zamani Xiaoyang Wang
Abstract
Coding harnesses shape how autonomous coding agents translate model capabilities into long-horizon software-engineering performance, yet existing work typically evaluates harnesses as monolithic systems, leaving the effectiveness of individual components unclear. To enable component-level comparisons, we study this question with a lightweight coding harness whose execution loop is fixed while three components are varied: planning, action space, and context management. Across four models evaluated on SWE-Bench Verified and Terminal-Bench 2.1, we evaluate 176 matched settings spanning five context-management strategies, four context-window budgets, and targeted ablations of planning and action space. We find that: (1) Context management becomes increasingly valuable as the context-window budget tightens, with most of its benefit coming from preventing context-overflow failures. (2) Staging rule-based elision before LLM-based summarization provides the strongest overall efficiency among the context-management strategies, whereas making elided content recoverable adds machinery that models rarely use and yields no accuracy gain. (3) Planning shifts from an accuracy scaffold for weaker models to a cost saver for stronger models, with little change in accuracy. (4) Predefined tools improve performance for models with weaker bash proficiency, whereas bash-capable models can operate effectively with a bash-only interface and achieve substantially lower cost, especially on command-line-centric tasks. Trajectory-level analysis explains these effects: context management extends execution trajectories without substantially altering agent behavior, planning changes where trajectories stop, and the action space changes the granularity at which code is written. These findings inform modeland budget-aware harness design and provide a modular framework for evaluating future harness components.
One-sentence Summary
In an empirical study of 176 matched harness configurations across four models evaluated on SWE-Bench Verified and Terminal-Bench 2.1, UMass Amherst et al. find that context management mainly prevents overflow failures under tight budgets, rule-based elision before LLM summarization is most efficient, planning shifts from an accuracy scaffold to a cost saver, and predefined tools help weaker bash models while bash-capable models favor cheaper bash-only operation.
Key Contributions
- A modular harness-evaluation framework fixes the execution loop and varies planning, action space, and context management, applied to 176 matched settings spanning five context-management strategies, four context-window budgets, and targeted ablations across four models on SWE-Bench Verified and Terminal-Bench 2.1.
- Context management becomes most valuable as the context-window budget tightens, with most of its benefit coming from preventing context-overflow failures. Strategy T4 achieves the lowest aggregate cost at broadly similar success rates by applying rule-based elision before selective LLM summarization, whereas making elided content recoverable adds machinery that models rarely use and yields no accuracy gain.
- Planning shifts from an accuracy scaffold for weaker models to a cost saver for stronger models with little change in accuracy. Predefined tools improve performance for models with weaker bash proficiency, while bash-capable models can operate effectively with a bash-only interface at substantially lower cost, especially on command-line-centric tasks; trajectory-level analysis links these effects to distinct behavioral changes.
Introduction
Large language models are increasingly used to autonomously resolve real software-engineering tasks such as closing GitHub issues and completing end-to-end terminal work. These results depend heavily on the coding harness, the software layer whose planning, action interface, and context-management choices can change performance even when the underlying model stays fixed. However, many earlier studies compare harnesses as complete systems, which conflates multiple mechanisms and makes it hard to tell whether performance differences come from planning, tools, context management, or their interaction with the model. The authors address this by building a modular harness with a fixed execution loop and varying only planning, action space, and context management. They evaluate three Nemotron-3 model sizes plus Mistral-Medium-3.5-128B on SWE-Bench Verified and Terminal-Bench 2.1, sweeping five context-management strategies across 32k to 128k token budgets and ablating planning and action space to characterize how each component's usefulness depends on model capability, task type, and resource budget.
Method
The authors leverage a modular and lightweight harness designed to isolate and evaluate the contribution of individual components across different models and computational budgets. The overall framework follows a ReAct loop, where each turn consists of a reasoning step, an action, and an observation. This modular design allows components to be independently configured and composed for controlled component-level analysis.
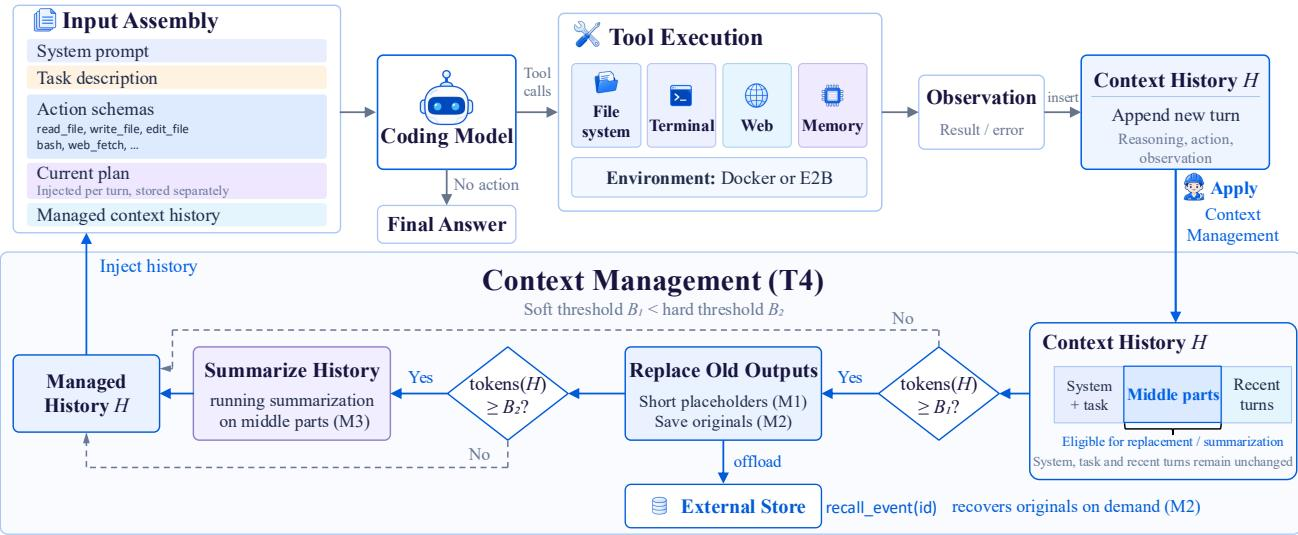
The harness varies three primary components: planning, the action space, and context management, while keeping other supporting components fixed.
Planning provides an explicit and persistent representation of task progress maintained by the model. When enabled, a system instruction defines the protocol, and a first-turn reminder requests an initial plan before any action is taken. The model maintains this plan through a dedicated tool. In subsequent turns, the plan is appended to the model input without being stored in the conversation history. This setup estimates the effect of a persistent planning scaffold rather than planning as a general reasoning strategy.
The action space defines how agents interact with the environment. In the predefined-tool setting, the harness provides a suite of tools for file manipulation, text searching, web fetching, and bash execution. Each tool features a typed argument schema and a description specifying its protocol, errors, and side effects. Web search is explicitly excluded to prevent exposure to ground-truth patches. In the bash-only setting, predefined file, search, and web tools are removed, leaving bash for general environment interaction. This intervention also alters how workspace modifications are tracked and validated, enforcing read-before-write checks and triggering automatic diagnostics.
Context management determines how the growing interaction history is represented within a bounded context window. The authors draw on both lossy and lossless methods through three composable mechanisms. Elision replaces the body of a stale tool observation with a short stub. Recall stores elided observations in the file system and exposes a tool to read them back on demand, making elision reversible. Summarization folds older messages into a running natural-language summary produced by a separate, tool-free call to the same model.
These mechanisms are combined under two token thresholds: a soft threshold B1 and a hard threshold B2. The preamble and a token-budgeted recent window of at least two turns remain verbatim. Once the history exceeds B1, the harness elides bulky tool observations in the middle region, storing the originals externally and leaving stubs in their place. If the history still exceeds B2, the harness summarizes the oldest middle events into the running summary. This full three-mechanism configuration ensures that elision reclaims tokens cheaply, recall recovers detail when needed, and summarization compresses history that is too old to keep verbatim.
Beyond these three variable components, the harness includes several fixed supporting components to ensure robust execution. A safety layer enforces workspace access controls through path resolution, read-before-write checks, and a permission layer that classifies actions. Tool errors are returned to the model as observations rather than raised exceptions, preventing loop crashes. Post-edit diagnostics run fast, read-only checks on edited Python files to surface syntax errors and undefined names immediately. Finally, a stuck detection mechanism monitors the tool log for streaks of identical calls, injecting reminders or ending the run early to prevent the agent from exhausting its step budget on repetitive failures.
Experiment
The experiments evaluate Nemotron-3 models at 30B, 120B, and 550B plus Mistral-Medium-3.5-128B on SWE-Bench Verified and Terminal-Bench 2.1, varying context-management tiers, context-window budgets, planning, and tool-space configuration. Context management is valuable mainly under tight windows because it prevents truncation failures, and T4 gives the best accuracy-cost tradeoff while recall is rarely used and adds little. Planning extends weak-model trajectories enough to attempt edits, whereas for stronger models it mostly trims post-edit verification and reduces cost. The full tool set scaffolds weaker models, but bash-only can help stronger models by enabling larger code-writing actions and fewer interactions, especially on shell-centric tasks.
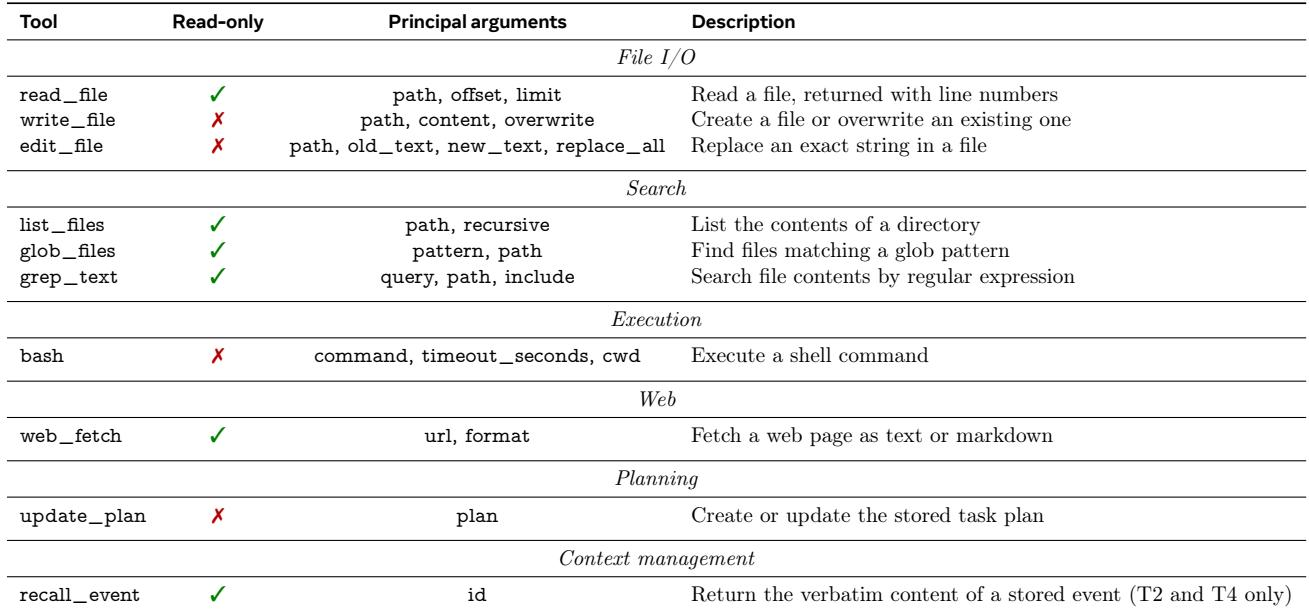
The harness exposes predefined file, search, web, and bash tools with typed schemas and either read-only or state-modifying behavior. Read-only tools may execute concurrently within a model turn; the bash-only condition removes the predefined workspace tools while retaining bash and auxiliary tools such as update_plan and recall_event. Experiments suggest planning mainly reduces redundant post-edit verification, while bash-only encourages fewer but larger code-writing and file-replacement actions. Read-only tools for file reading, listing, and globbing do not modify workspace or harness state and may run concurrently within a model turn. Bash-only removes predefined workspace tools but keeps bash and auxiliary tools, leading models to bundle operations into fewer, larger code-writing or create-or-replace actions.
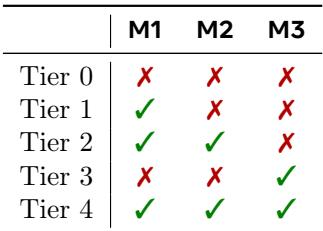
The configured tiers range from no context management to a combined approach using elision, recall, and summarization. Intermediate tiers isolate elision, elision with recall, and summarization alone. The full configuration applies elision at a soft threshold and summarization at a hard threshold, while the intermediate single-action tiers operate at the hard threshold. Tier 4 is the only tier that enables all three mechanisms: elision, recall, and summarization. Recall builds on elision by storing elided observations externally, making elision reversible. Tier 1 and Tier 3 isolate elision and summarization respectively, while Tier 0 disables context management entirely.
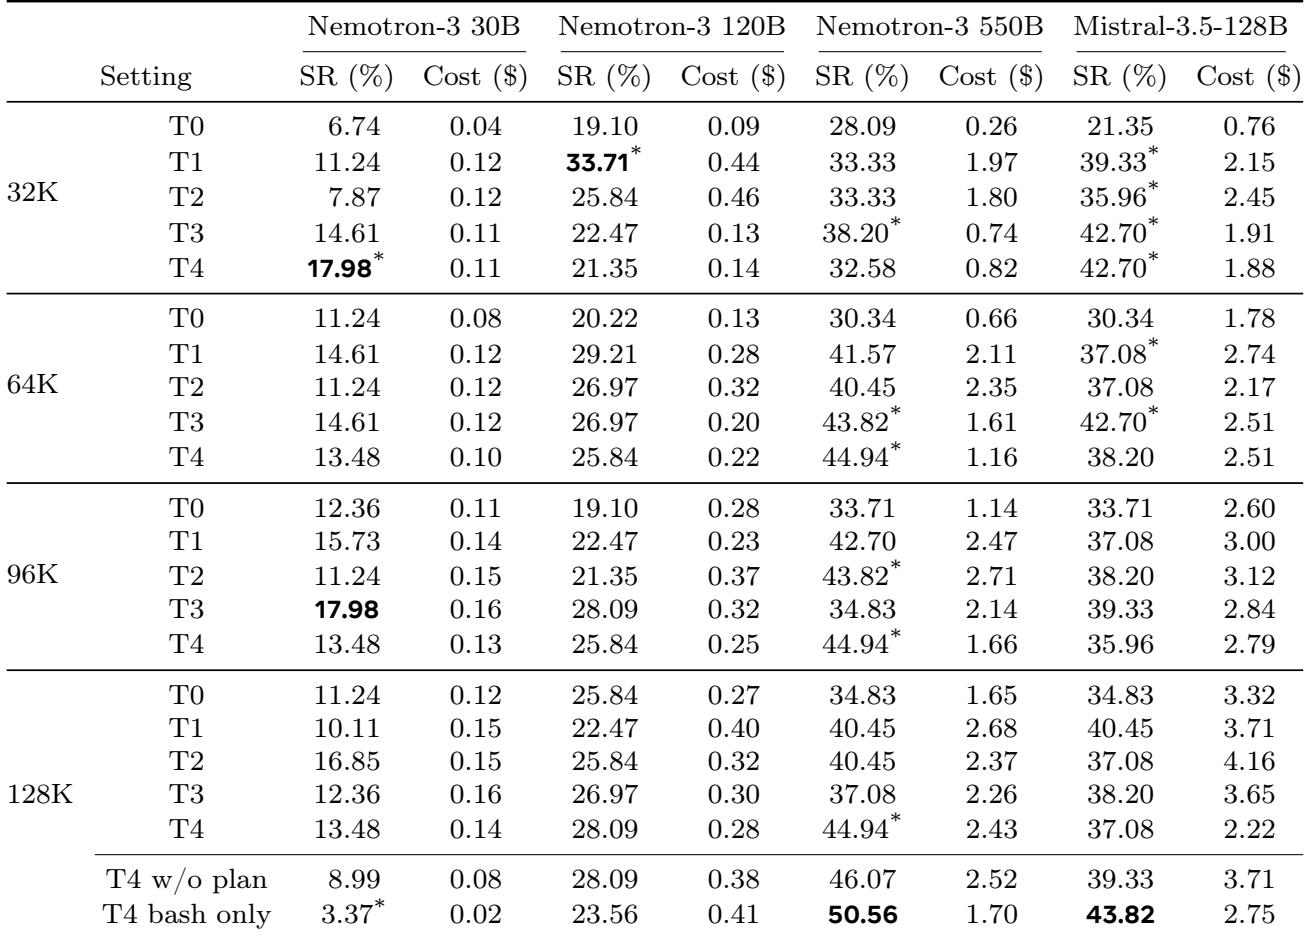
On SWE-Bench Verified, context management provides the largest success-rate gains over no management at the tightest context-window budgets, and the advantage narrows as the window grows. Among the managed tiers, the tier combining elision, recall, and summarization offers accuracy comparable to the other managed strategies while achieving the lowest mean cost per task. This cost advantage comes from keeping peak context below the nominal budget and reducing reliance on LLM summarization. The success-rate gap between managed tiers and no management is largest at the smallest context budget and shrinks steadily as the context window increases. Combining elision, recall, and summarization yields comparable success rates to other managed tiers while having the lowest mean cost per task across most settings. The combined tier keeps peak context usage substantially below the nominal window and invokes LLM summarization less often than summarization-only management.
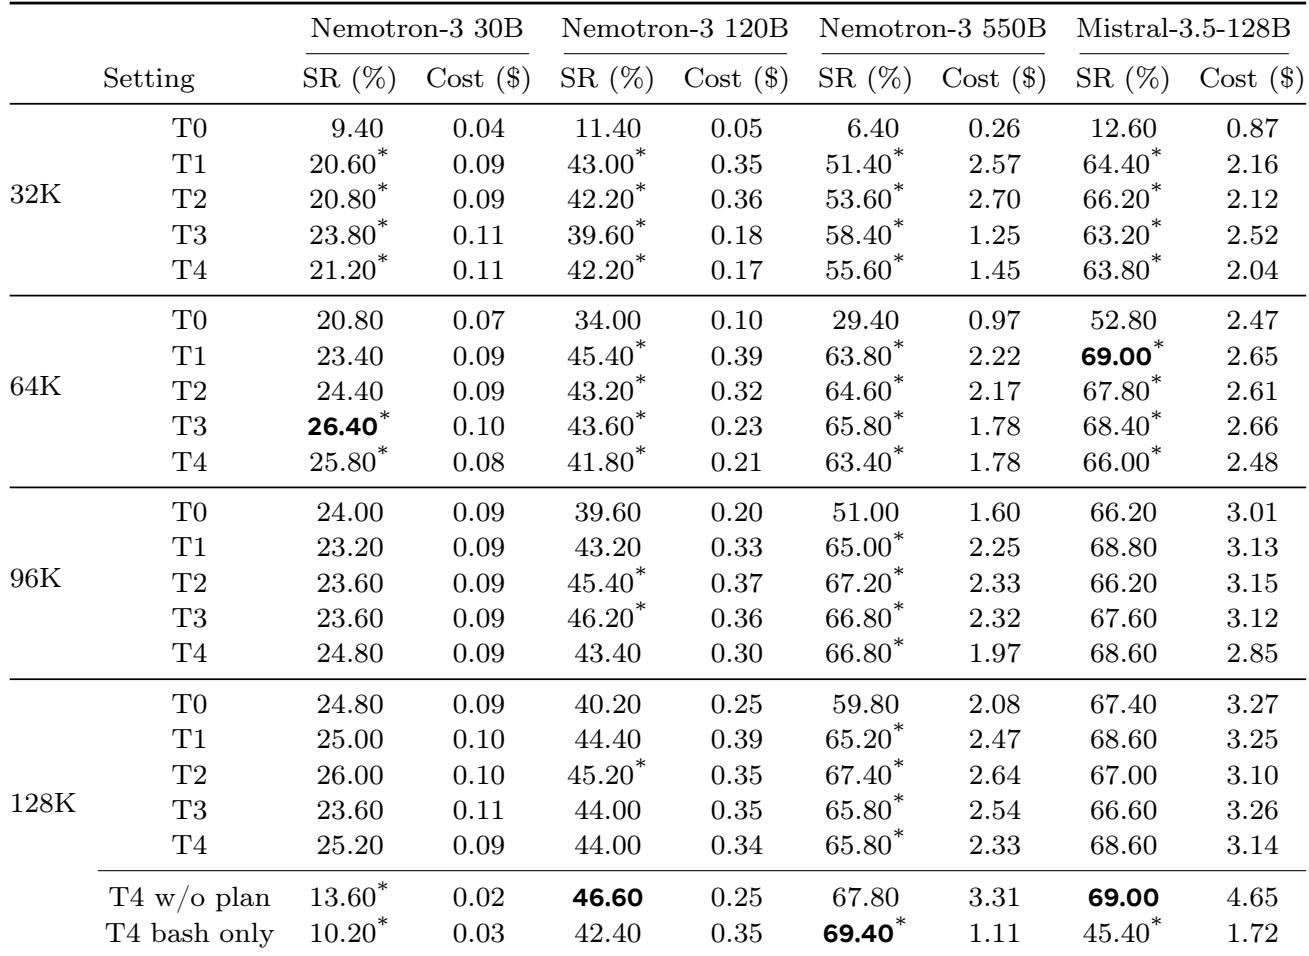
On Terminal-Bench, context management improves success rates over no management, with the largest gains under tight context budgets. T4 provides the best accuracy-cost trade-off among managed tiers, while T3 and T4 keep costs below T1 and T2 for larger models. Managed tiers avoid window-overflow failures entirely, whereas unmanaged runs are more sensitive to context-window capacity. At the 32k budget, every managed tier improves success rate over T0 for all four models, with especially large gains for Mistral-3.5-128B. T3 and T4 are substantially cheaper than T1 and T2 for the larger models, and T4 achieves the best or tied best success rate for two of the four models.
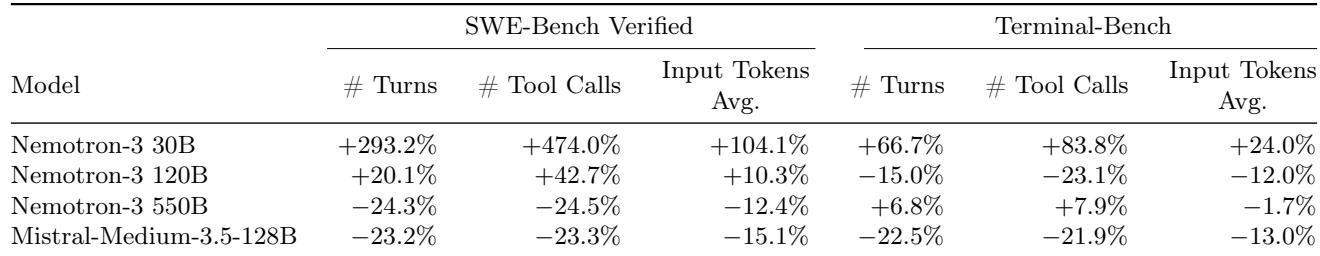
At a 128k context budget with the full tool set, planning has model-dependent effects on trajectory cost. Nemotron-3 30B shows increased turns, tool calls, and average input tokens on both benchmarks, whereas Nemotron-3 550B and Mistral-Medium-3.5-128B show reductions on SWE-Bench. Nemotron-3 120B shows a mixed pattern, with increases on SWE-Bench but decreases on Terminal-Bench. Nemotron-3 30B shows the largest planning-driven increases in SWE-Bench trajectory cost, with turns, tool calls, and input tokens all rising sharply. For Nemotron-3 550B and Mistral-Medium-3.5-128B, planning lowers SWE-Bench turns, tool calls, and average input tokens. On Terminal-Bench, planning reduces turns and tool calls for Nemotron-3 120B and Mistral-Medium-3.5-128B, while Nemotron-3 30B experiences increases.
The experiments evaluate tool configurations, planning, and context management on SWE-Bench Verified and Terminal-Bench. They show that planning mainly reduces redundant post-edit verification while a bash-only setup encourages fewer but larger code-writing or file-replacement actions. Across both benchmarks, context management improves success rates most at tight context windows, and the combined elision, recall, and summarization tier offers comparable accuracy with the lowest cost while avoiding overflow failures. Planning effects on trajectory cost are model dependent, with some models reducing turns and tool calls and others increasing them.