Command Palette
Search for a command to run...
1000-schichtige Netzwerke für selbstüberwachtes Reinforcement Learning: Skalierung der Tiefe kann neue Fähigkeiten zur Zielerreichung ermöglichen
1000-schichtige Netzwerke für selbstüberwachtes Reinforcement Learning: Skalierung der Tiefe kann neue Fähigkeiten zur Zielerreichung ermöglichen
Kevin Wang Ishaan Javali Michał Bortkiewicz Tomasz Trzciński Benjamin Eysenbach
Zusammenfassung
Die Skalierung selbstüberwachten Lernens hat Durchbrüche im Bereich Sprache und Bildverarbeitung vorangetrieben, doch vergleichbare Fortschritte blieben im Reinforcement Learning (RL) bislang aus. In dieser Arbeit untersuchen wir Bausteine für selbstüberwachtes RL, die wesentliche Verbesserungen in der Skalierbarkeit ermöglichen, wobei die Netzwerktiefe einen entscheidenden Faktor darstellt. Während sich die meisten RL-Publikationen der letzten Jahre auf flache Architekturen (etwa 2 bis 5 Schichten) stützten, zeigen wir, dass eine Erhöhung der Tiefe auf bis zu 1024 Schichten die Leistung erheblich steigern kann. Unsere Experimente werden in einem unüberwachten, zielbedingten Setting durchgeführt, in dem weder Demonstrationen noch Belohnungen bereitgestellt werden; der Agent muss daher von Grund auf explorieren und lernen, die Wahrscheinlichkeit, vorgegebene Ziele zu erreichen, zu maximieren. Auf simulierten Fortbewegungsund Manipulationsaufgaben steigert unser Ansatz die Leistung des selbstüberwachten kontrastiven RL-Algorithmus um den Faktor 2 bis 50 und übertrifft damit andere zielbedingte Baseline-Verfahren. Eine Erhöhung der Modelltiefe führt nicht nur zu höheren Erfolgsraten, sondern verändert auch die erlernten Verhaltensweisen qualitativ. Die Projektseite und der Code sind verfügbar unter: https://wang-kevin3290.github.io/scaling-crl/.
One-sentence Summary
Princeton University and Warsaw University of Technology et al. demonstrate that scaling network depth to 1024 layers in self-supervised contrastive RL, far beyond the typical 2–5 layers, improves goal-reaching performance by 2×−50× on unsupervised locomotion and manipulation tasks while qualitatively changing the behaviors the agent learns.
Key Contributions
- The paper introduces building blocks for self-supervised reinforcement learning in an unsupervised goal-conditioned setting, where an agent explores from scratch and learns to maximize the likelihood of reaching commanded goals without demonstrations or rewards.
- The approach combines an InfoNCE-trained contrastive critic whose output is the l2 norm between state-action and goal embeddings, a policy trained to maximize this critic, and residual connections that help stabilize training of networks with up to 1024 layers.
- Simulated locomotion and manipulation experiments show that increasing depth improves success rates by 2x to 50x over self-supervised contrastive RL and other goal-conditioned baselines, while producing qualitatively richer goal-reaching behaviors.
Introduction
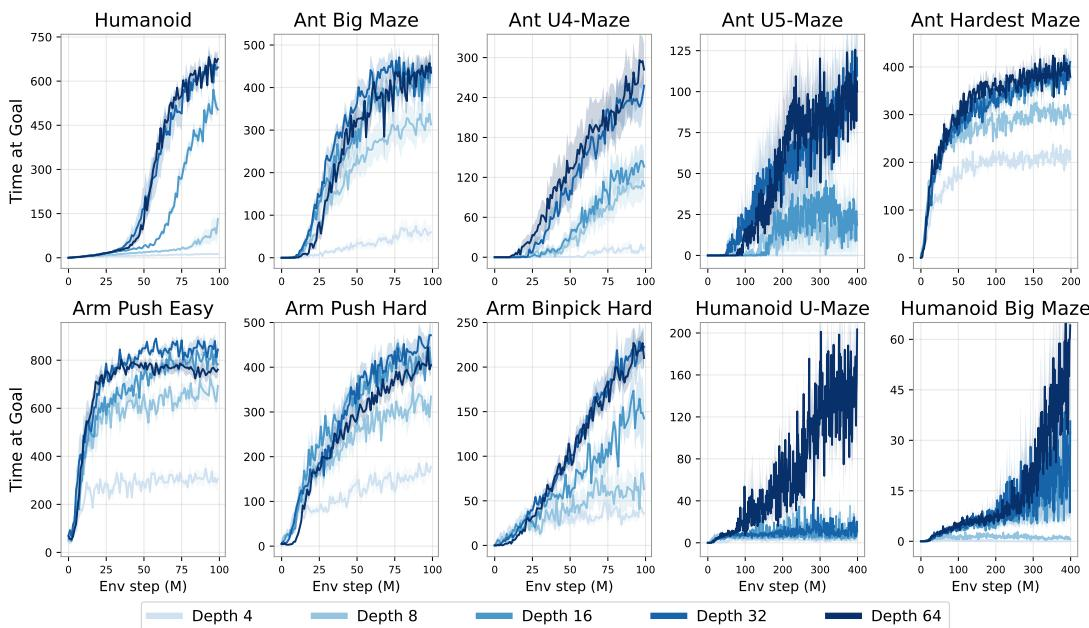
Scaling large models has produced emergent capabilities in vision and language, yet in reinforcement learning the payoff from scale remains uncertain because agents receive sparse reward signals and usually use small MLP policies of 2 to 5 layers. Prior work has struggled to match these gains, often seeing only marginal improvements, training instability, or limited and sometimes negative returns when increasing depth, while commonly treating self supervised pretraining as the main path to scale. The authors leverage contrastive reinforcement learning as a self supervised actor critic method, increase online data availability through GPU accelerated RL training, and build networks up to about 100 times deeper using residual connections, layer normalization, and Swish activations. They show that this combination enables strong RL scalability, with more than 20 times performance gains in half the environments, better results than goal conditioned baselines, and qualitatively distinct policies emerging as depth and scale increase.
Experiment
The experiments evaluate goal-conditioned contrastive RL on JaxGCRL locomotion, navigation, and manipulation tasks with sparse rewards, comparing residual actor and critic networks of increasing depth against standard shallow baselines. The results show that depth scaling yields substantial gains, especially in long-horizon and humanoid tasks, and leads to emergent navigational and locomotion skills once critical depths are reached. Ablations and mechanistic analyses indicate that depth is more useful than width, joint actor-critic scaling can help, and larger depths unlock larger batches while improving representation quality, exploration, and limited generalization, though offline results do not show the same benefit.