Command Palette
Search for a command to run...
Generative Adversarial Netze
Generative Adversarial Netze
Ian J. Goodfellow Jean Pouget-Abadie Mehdi Mirza Bing Xu David Warde-Farley Sherjil Ozair Aaron Courville Yoshua Bengio
Zusammenfassung
Wir schlagen ein neues Framework zur Schätzung generativer Modelle über einen adversarialen Prozess vor, in dem zwei Modelle gleichzeitig trainiert werden: ein generatives Modell G, das die Datenverteilung erfasst, und ein diskriminatives Modell D, das die Wahrscheinlichkeit schätzt, dass eine Stichprobe aus den Trainingsdaten und nicht von G stammt. Das Trainingsverfahren für G besteht darin, die Wahrscheinlichkeit zu maximieren, dass D einen Fehler macht. Dieses Framework entspricht einem Minimax-Zwei-Personen-Spiel. Im Raum beliebiger Funktionen G und D existiert eine eindeutige Lösung, bei der G die Trainingsdatenverteilung rekonstruiert und D überall den Wert 1 annimmt. Falls G und D durch Mehrlagen-Perzeptrons definiert sind, kann das gesamte System mit Backpropagation trainiert werden. Weder beim Training noch bei der Erzeugung von Stichproben sind Markov-Ketten oder entrollte approximative Inferenznetzwerke erforderlich. Experimente belegen das Potenzial des Frameworks durch qualitative und quantitative Bewertung der erzeugten Stichproben.
One-sentence Summary
Researchers at Université de Montréal propose Generative Adversarial Nets, a framework that simultaneously trains a generative model G and a discriminative model D via a minimax two-player game, enabling data distribution estimation without Markov chains or approximate inference networks.
Key Contributions
- The paper introduces generative adversarial networks, which jointly train a generator G to capture the data distribution and a discriminator D to estimate whether a sample came from the training data or from G. The generator is trained to maximize the probability that D misclassifies generated samples.
- The method formulates generative modeling as a minimax two-player game rather than a likelihood-based objective, with a unique solution where G recovers the training distribution and D equals 1 everywhere. When G and D are multilayer perceptrons, the full system can be trained with backpropagation without Markov chains or unrolled approximate inference networks during training or sample generation.
- Experiments evaluate the framework through qualitative and quantitative assessment of generated samples, supporting its potential for learning generative models.
Introduction
Deep learning has produced strong models for discriminative tasks, where a system maps complex sensory inputs such as images or audio to labels, but generative modeling has lagged because it requires hard probabilistic computations that are difficult to optimize. Prior approaches often depended on intractable likelihoods, approximate inference, Markov chains, or special density evaluations, which made training large deep generative models unstable or inefficient. The authors leverage an adversarial training game in which a generator produces samples and a discriminator learns to distinguish them from real data. Their main contribution is a framework that trains both networks using standard backpropagation and dropout, avoiding approximate inference and Markov chains while enabling scalable generative modeling.
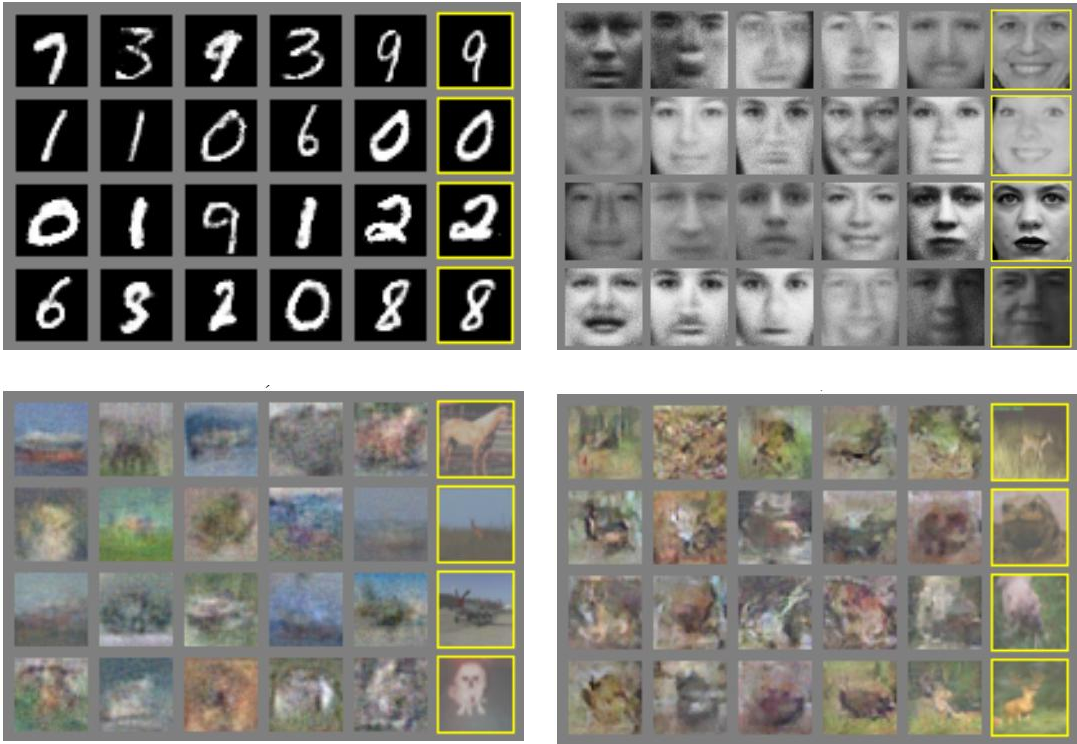
Method
The adversarial modeling framework is built from two differentiable multilayer perceptrons trained through a two-player minimax optimization. The generator G(z;θg) maps noise variables z∼pz into the data space, thereby implicitly inducing a model distribution pg. The discriminator D(x;θd) outputs a scalar score interpreted as the probability that an input x came from the real data distribution pdata rather than from the generator. The training objective for these two components is:
GminDmaxV(D,G)=Ex∼pdata(x)[logD(x)]+Ez∼pz(z)[log(1−D(G(z)))].Here, D is trained to maximize the log-probability of assigning correct labels to real samples and generated samples, while G is trained to fool D by minimizing log(1−D(G(z))). Equivalently, the generator pushes its sample distribution closer to the data distribution by reducing the discriminator’s confidence that generated samples are fake.
The optimization process can be understood as a coupling between a mapping from noise to data and a learned density-ratio estimator. Refer to the framework diagram:
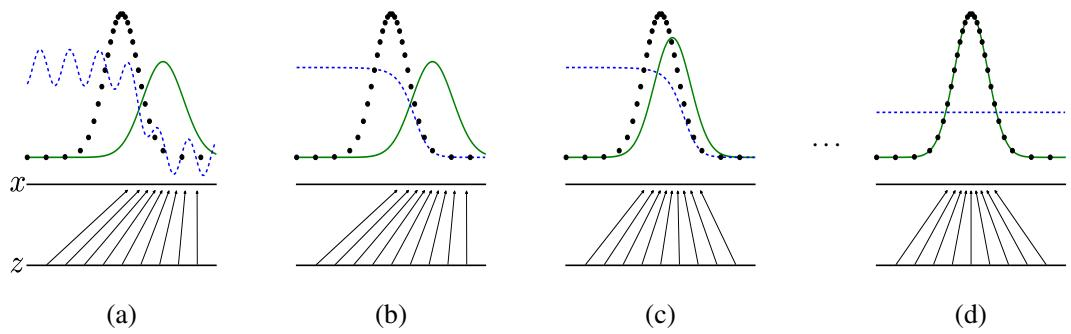
In this view, samples from a simple noise prior are transformed by G into data-like samples. The mapping G expands in regions that should receive more probability mass and contracts in regions that should receive less. Meanwhile, D adapts to separate the generated distribution pg from the true data distribution pdata. As training proceeds, G follows the gradient supplied by D, moving generated samples toward regions that are more likely to be classified as real.
In practice, the discriminator is not optimized to full convergence in every inner loop. Fully solving the inner optimization is computationally expensive and can cause overfitting on finite datasets. Instead, training alternates between k discriminator updates and one generator update. This keeps D close to its optimal solution for the current generator, provided that G changes slowly enough. The update schedule is therefore coupled: the generator depends on informative gradients from D, while D must track the changing distribution of generated samples.
The objective in the standard minimax formulation can be weak for early-stage training. When G is poor, D can reject generated samples with very high confidence, causing the term log(1−D(G(z))) to saturate and producing small gradients for the generator. To avoid this, the authors modify the generator objective to maximize logD(G(z)) instead. This revised loss has the same fixed point under the joint dynamics of G and D, but it provides much stronger gradient signals early in training.
Theoretical analysis explains why this adversarial objective targets the data distribution. For a fixed generator, the optimal discriminator has the closed form:
DG∗(x)=pdata(x)+pg(x)pdata(x).This means that D effectively estimates the posterior probability that a sample originated from real data versus generated data. Substituting this optimal discriminator back into the objective yields a quantity that can be expressed using the Jensen-Shannon divergence between pdata and pg:
C(G)=−log(4)+2JSD(pdata∥pg).Because the Jensen-Shannon divergence is nonnegative and equals zero only when the two distributions match, the global optimum of the idealized objective occurs when pg=pdata. In the nonparametric setting, this explains why the method can recover the data generating distribution when the model class has sufficient capacity and updates are made in a controlled way.
Practically, the method does not require an explicit density model for pg, Markov chain sampling, or inference during learning. Gradients are obtained through backpropagation through the discriminator, which allows flexible differentiable components to be used for both G and D. The main training design choice is synchronization between the two networks: D must remain close to optimal as G changes, while G must avoid collapsing too quickly to a limited subset of generated samples.
Experiment
The evaluation combines theoretical analysis with image-based experiments. The theory validates that the minimax objective has a global optimum when the generator matches the data distribution and that an idealized optimization procedure can converge to this optimum under strong assumptions. Empirically, adversarial networks trained on image datasets produce samples that are judged to be competitive, indicating that the framework can learn useful generative behavior despite the approximate nature of likelihood estimation.
The results compare estimated log-likelihoods of several generative models on MNIST and TFD using a Parzen window-based procedure. Adversarial nets achieve the best estimated performance on MNIST and remain competitive on TFD, where stacked CAE gives the strongest reported estimate. The comparison suggests that adversarial training produces samples with estimated likelihoods that are at least competitive with existing generative models, though the evaluation method is noted to have high variance. Adversarial nets obtain the highest estimated MNIST log-likelihood among the compared models. On TFD, adversarial nets perform close to the best model, while stacked CAE gives the strongest reported estimate. The likelihood values are estimated using Parzen windows, a procedure noted to have high variance and limited reliability in high dimensions.
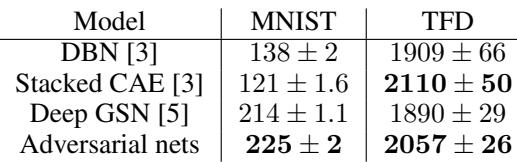
Experiments evaluate multiple generative models on MNIST and TFD by estimating log-likelihoods with a Parzen window-based procedure. The results indicate that adversarial nets achieve the strongest estimated likelihood on MNIST and remain competitive on TFD, where stacked CAE obtains the best reported estimate. Overall, adversarial training yields samples with likelihood estimates comparable to existing generative models, though the evaluation is affected by high variance and limited reliability.