Command Palette
Search for a command to run...
IrokoBench: Ein neuer Benchmark für afrikanische Sprachen im Zeitalter großer Sprachmodelle
IrokoBench: Ein neuer Benchmark für afrikanische Sprachen im Zeitalter großer Sprachmodelle
Zusammenfassung
Trotz der weiten Verbreitung großer Sprachmodelle (LLMs) bleiben deren bemerkenswerte Fähigkeiten auf wenige ressourcenreiche Sprachen beschränkt. Darüber hinaus werden viele ressourcenarme Sprachen, etwa afrikanische Sprachen, aufgrund des Fehlens geeigneter oder umfassender Benchmarks außerhalb ressourcenreicher Sprachen häufig nur auf einfachen Textklassifizierungsaufgaben evaluiert. In diesem Paper führen wir IrokoBench ein – einen menschlich übersetzten Benchmark-Datensatz für 17 typologisch diverse, ressourcenarme afrikanische Sprachen, der drei Aufgaben abdeckt: Natürliche Sprachschlussfolgerung (AfriXNLI), mathematisches Schlussfolgern (AfriMGSM) und multiple-Choice-wissensbasierte Fragebeantwortung (AfriMMLU). Wir verwenden IrokoBench zur Evaluierung von Zero-Shot-, Few-Shotund Translate-Test-Einstellungen (bei denen die Testdaten in das Englische übersetzt werden) an zehn offenen und sechs proprietären LLMs. Unsere Evaluation zeigt eine erhebliche Leistungslücke zwischen ressourcenreichen Sprachen (wie Englisch und Französisch) und ressourcenarmen afrikanischen Sprachen. Ferner beobachten wir eine deutliche Leistungsdifferenz zwischen offenen und proprietären Modellen: Das leistungsstärkste offene Modell, Gemma 2 27B, erreicht lediglich 63 % der Leistung des besten proprietären Modells GPT-4o. Darüber hinaus half die maschinelle Übersetzung der Testdaten in das Englische vor der Evaluierung dabei, die Lücke für größere, englischzentrierte Modelle wie Gemma 2 27B und LLaMA 3.1 70B zu verringern. Diese Befunde legen nahe, dass verstärkte Anstrengungen zur Entwicklung und Anpassung von LLMs für afrikanische Sprachen erforderlich sind.
One-sentence Summary
Masakhane NLP et al. introduce IrokoBench, a human-translated benchmark for 17 typologically-diverse African languages covering natural language inference, mathematical reasoning, and knowledge-based question answering, which reveals significant performance gaps between high-resource and low-resource languages and between open and proprietary LLMs, underscoring the need for greater effort in adapting LLMs to African languages.
Key Contributions
-
The paper introduces IrokoBench, a human-translated benchmark for 17 typologically diverse low-resource African languages covering natural language inference (AfriXNLI), mathematical reasoning (AfriMGSM), and multiple-choice knowledge question answering (AfriMMLU). This benchmark extends African language evaluation beyond basic text classification tasks to complex reasoning and knowledge-intensive tasks.
-
The paper evaluates 10 open and six proprietary LLMs using zero-shot, few-shot, and translate-test settings. Results show major gaps between high-resource languages and African languages, with Gemma 2 27B reaching only 63% of GPT-4o performance and AfriMGSM proving the most challenging task.
-
The paper releases IrokoBench on GitHub and Hugging Face under the CC BY-SA 4.0 license, and shows that translating test sets into English before evaluation can help close gaps for larger English-centric open models such as Gemma 2 27B and LLaMa 3.1 70B. These findings support further development and adaptation of LLMs for African languages.
Introduction
Large language models increasingly support complex reasoning tasks, but most state-of-the-art systems are trained mainly on high-resource languages, leaving African language users with weaker performance and limited evaluation. Existing African benchmarks often cover narrower or simpler tasks, and machine-translated versions of English benchmarks can introduce noise, bias, and cultural mismatch. The authors address this gap with IROKOBENCH, a human-curated benchmark for African languages that evaluates natural language inference, mathematical reasoning, and multiple-choice knowledge question answering. They also test many open and proprietary LLMs, revealing a sharp performance drop on low-resource African languages and a clear divide between open and proprietary systems.
Dataset
-
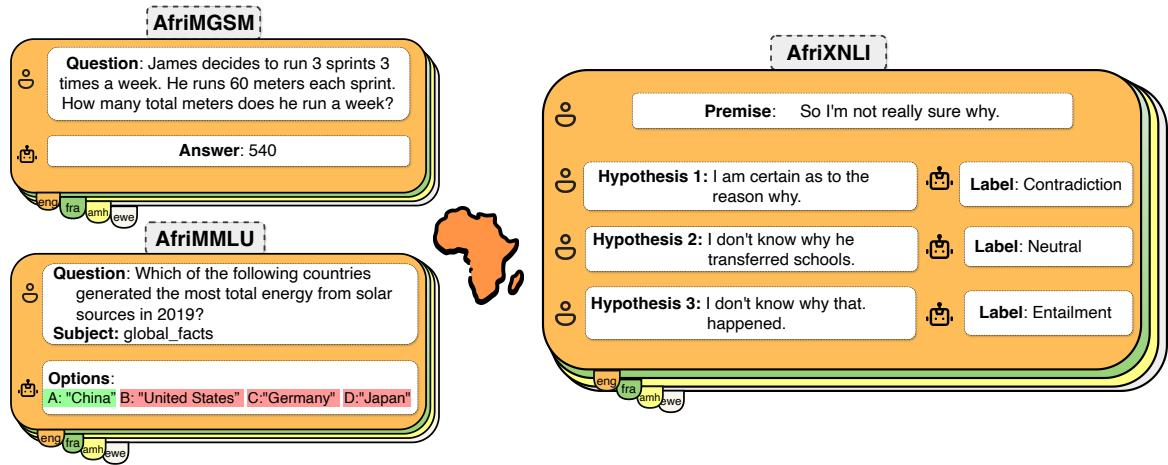
The authors introduce IROKOBENCH, a multilingual benchmark covering 19 languages: 17 native African languages plus English and French. English and French also serve as source languages for translation. The African languages span four regions and three language families, including eight Bantu languages. Language metadata includes family, region, and number of native speakers.
-
Data are collected through language coordinators who recruit professional translators. Most translations are made from English, except for Ewe, Lingala, and Wolof, which are translated from French. MMLU is translated into French first, then into those three Francophone languages. Quality control includes coordinator review and correction before translator payment. The authors also compute COMET quality scores, but they note that these scores are unreliable for Lingala, Twi, and Wolof.
-
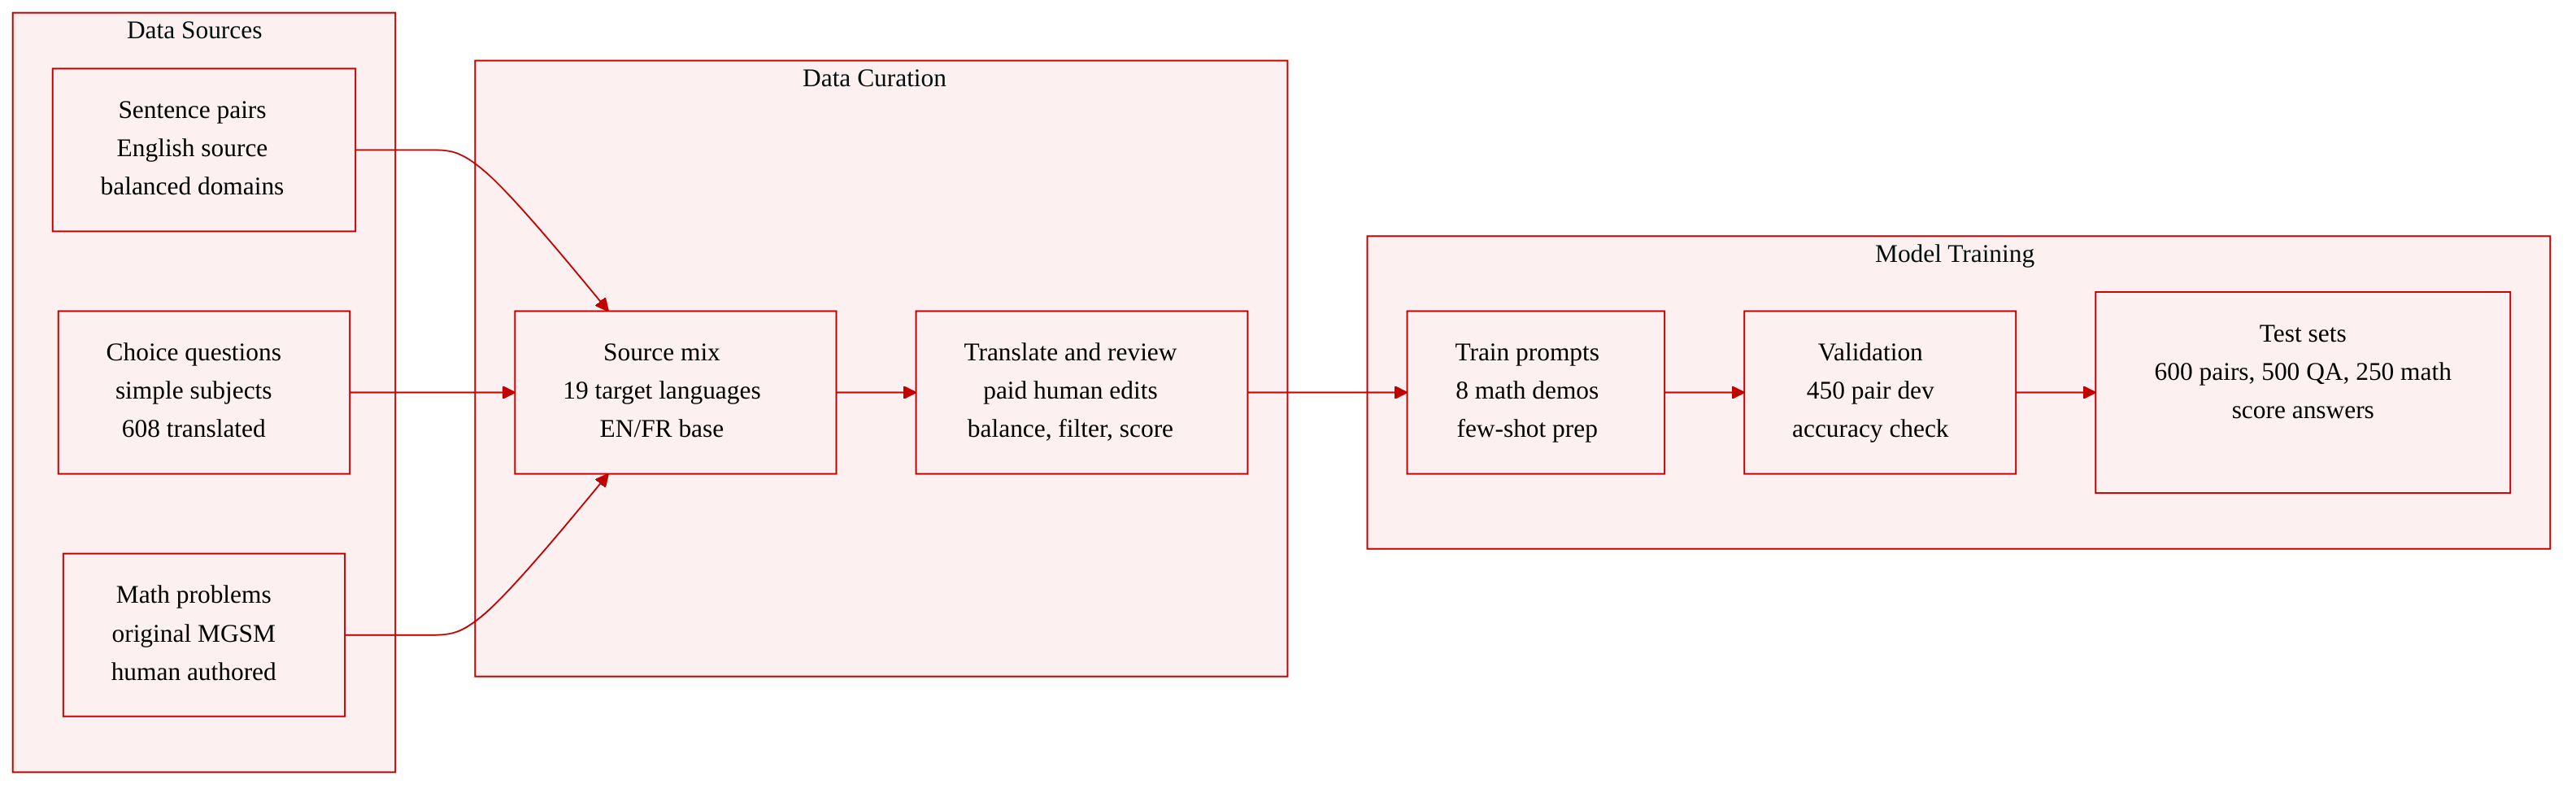
AfriXNLI contains human translations of the English portion of XNLI into 15 African languages, excluding Swahili. For each language, the authors sample equal numbers of instances across the 10 XNLI domains and use a reduced balanced split: 450 development examples and 600 test examples per language. Accuracy is the evaluation metric.
-
AfriMMLU is a multi-choice knowledge QA subset curated from freely available online sources. The authors select five subjects that are considered culturally unbiased or easier to translate: high-school geography, high-school microeconomics, elementary mathematics, international law, and global facts. They translate 608 question-answer pairs in total, with 500 test examples, 100 per subject. Option prediction accuracy is used for evaluation.
-
AfriMGSM is built from grade-school mathematical word problems from the original MGSM dataset. The authors use 8 examples as training demonstrations for few-shot and chain-of-thought prompting, and 250 examples as the test set. Exact Match is the evaluation metric.
-
The authors use these datasets primarily for LLM evaluation rather than model training. No special cropping strategy is described, and no mixture ratios are reported. The main processing steps are human translation, domain-balanced sampling for AfriXNLI, subject filtering for AfriMMLU, and translation quality control.
Method
Translation and Quality Control Workflow
The authors leverage a coordinated human translation and validation pipeline to convert benchmark sentences into African languages and French. Language coordinators are engaged for each language and are responsible for recruiting professional translators. Translators work from the original source material, with the process proceeding across task groups in a staged order: first XNLI, then MGSM, and finally MMLU. Translators are compensated for their work, which supports consistent delivery across a large multilingual set.
The pipeline also adapts the source language to linguistic context. For Ewe, Lingala, and Wolof, translators work from French rather than English because they are based in Francophone regions. For MMLU, the authors create a French translation through professional translators and then translate that French version into the three Francophone languages. Since some translators are more fluent in French than in English, the workflow allows them to use the English original as a cross-check when the French sentence is ambiguous or unclear.
Quality control is handled through a two-stage review and assessment process. First, language coordinators inspect translated outputs and correct sentences that are judged to be inaccurate, unnatural, or poorly translated. Payment is delayed until this review phase is completed, creating a quality assurance mechanism that encourages translators to correct errors before final acceptance. Second, the authors compute automatic quality estimation scores using the AfriCOMET QE metric. This metric produces a score between 0 and 1 for each translated sentence by comparing it with the original sentence. In most language pairs, the score distribution is concentrated between 0.7 and 1.0, which supports the overall translation quality. For Lingala, Twi, and Wolof, however, average scores are lower, around 0.5. The authors treat these scores cautiously for those languages because they are not covered by the pretraining data of the original AfroX-LMR encoder used by AfriCOMET, and prior analyses indicate weaker correlation between the QE score and human judgment for some of these languages. As a result, automatic COMET scores are used as diagnostic monitoring rather than as a sole quality filter for all languages.
Experiment
The experiments evaluate a broad set of open and closed language models on African-language tasks using in-language prompting, translated-English evaluation, zero-shot, few-shot, and cross-lingual transfer settings. They show that models generally perform better on high-resource languages than African languages, with closed models typically stronger than open-weight models and many English-centric models benefiting more from translate-test prompting. Task-specific and prompt-sensitivity analyses further reveal that prompting strategy and model choice matter: closed models may perform better in-language on some reasoning tasks, while Africa-centric fine-tuned models can be effective when sufficient labeled English data is available.
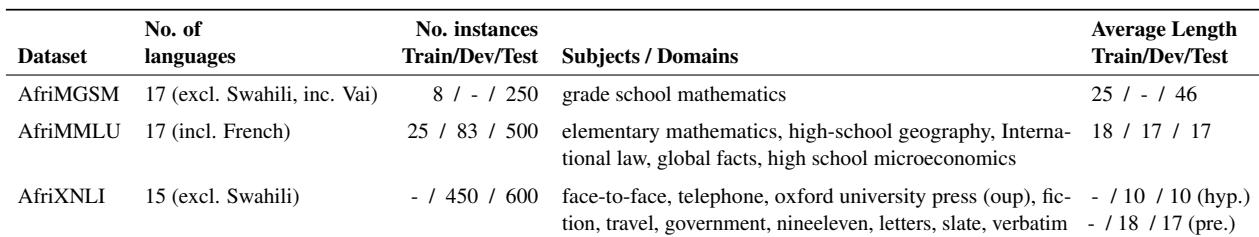
IROKOBENCH presents three benchmark datasets for African languages: AfriMGSM for grade school mathematics, AfriMMLU for multiple choice knowledge questions, and AfriXNLI for natural language inference. The datasets cover multiple African languages and a range of domains, with English, French, and Swahili included across the overall benchmark set. Related evaluation notes indicate that translate test can help open models on AfriMGSM, while in language transfer can benefit NLI when models are pretrained on the relevant languages. The benchmark includes mathematics, knowledge question answering, and sentence pair reasoning tasks. AfriMMLU focuses on a limited set of subjects that are easier to translate across African language settings. AfriXNLI uses translated NLI data from multiple English domains and is evaluated with accuracy on balanced classes.
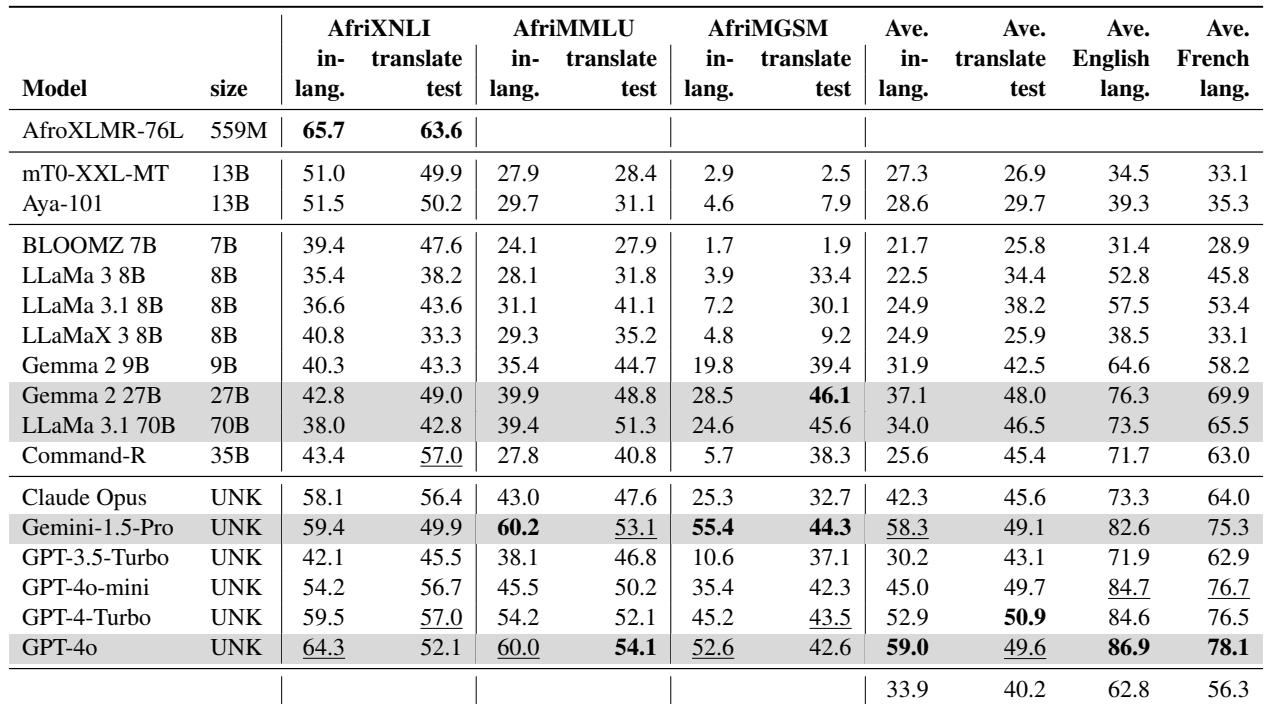
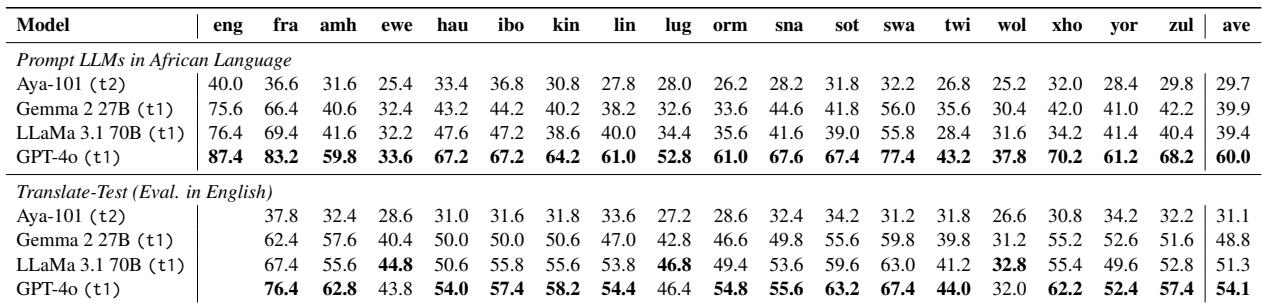
Across the benchmarked models, GPT-4o has the strongest average performance on African-language tasks, and closed-weight models consistently outperform open-weight models. Most models also score better when prompts are translated into English than when they are presented in African languages, with the largest gains seen for several open models on reasoning tasks. Closed-weight models consistently rank above open-weight models. African-language performance trails English and French, with large gaps for the best model. Most models prefer English prompts, while only a few closed models benefit from in-language prompting. Translation into English can substantially improve open-model performance on reasoning tasks.
AfriMMLU accuracy varies substantially across languages and model families, with stronger performance in higher-resource settings and weaker performance in several African languages. GPT-4o generally performs best when evaluated in-language, while open models tend to improve when questions are translated into English before evaluation. This suggests that translate-test can help English-centric models handle low-resource languages, although the benefit depends on model type and machine translation quality. GPT-4o shows the strongest in-language option prediction accuracy among the compared models. Translate-test improves open model performance for most African languages, with Wolof being a notable exception. African language scores are generally lower than English and French, and performance also varies widely by language.
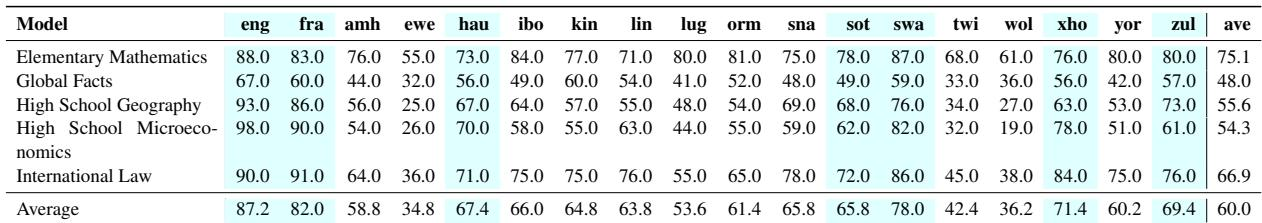
GPT-4o's accuracy varies substantially by subject and language. Elementary mathematics is generally the strongest subject, while global facts is the most difficult even for English and French. International law is relatively strong for several languages, but high-school geography and microeconomics are challenging for many African languages. Elementary mathematics shows the broadest strength across languages. Global facts is the hardest subject overall. International law performs comparatively well for many languages. High-school geography and microeconomics are particularly difficult for many African languages.
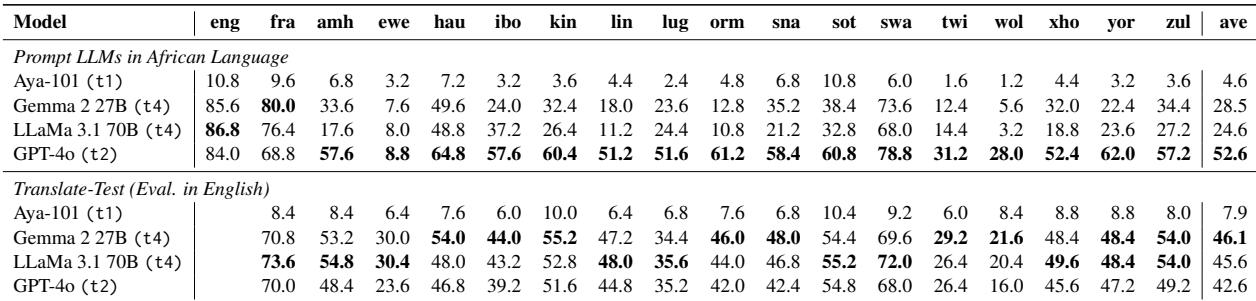
The table compares African-language and translate-test Exact Match results for math word problems across several LLMs. GPT-4o performs best when answering in African languages, while Gemma 2 27B and LLaMa 3.1 70B gain on average when questions are translated to English. Aya-101 remains weak in both settings, indicating that current models still struggle with African-language arithmetic reasoning. GPT-4o shows the strongest in-language Exact Match across African languages among the compared models. Translate-test raises average African-language performance for Gemma 2 27B and LLaMa 3.1 70B. Aya-101 scores very low in both in-language and translate-test settings.
IROKOBENCH evaluates African-language mathematics, knowledge question answering, and natural language inference across multiple languages and model families. Experiments show that closed-weight models generally outperform open-weight models, and performance in African languages often trails English and French, with substantial variation across tasks, subjects, and languages. Translate-test can substantially help open-weight models, especially on reasoning tasks, although the benefit depends on model type, language, and translation quality.