Command Palette
Search for a command to run...
Ein Leitfaden für Vortrainer zu Trainingsdaten: Messung der Auswirkungen von Datenalter, Domänenabdeckung, Qualität und Toxizität
Ein Leitfaden für Vortrainer zu Trainingsdaten: Messung der Auswirkungen von Datenalter, Domänenabdeckung, Qualität und Toxizität
Zusammenfassung
Das Design von Vortrainingsdaten ist kritisch unterdokumentiert und wird häufig von empirisch nicht gestützten Intuitionen geleitet. Wir trainieren Modelle auf Daten vor, die (1) zu unterschiedlichen Erhebungszeitpunkten gesammelt, (2) mit unterschiedlichen Toxizitätsund Qualitätsfiltern kuratiert und (3) aus unterschiedlichen Domänenzusammensetzungen zusammengestellt wurden. Erstens stellen wir fest, dass eine zeitliche Verschiebung zwischen Evaluationsdaten und Vortrainingsdaten zu einer Leistungseinbuße führt, die durch Fine-Tuning nicht ausgeglichen werden kann. Zweitens messen wir die Wirkung von Qualitätsund Toxizitätsfiltern und zeigen einen Zielkonflikt zwischen der Leistung auf Standard-Benchmarks und dem Risiko toxischer Ausgaben. Wir stellen außerdem fest, dass die Auswirkungen verschiedener Filtertypen nicht aus den Merkmalen der Textdomänen vorhergesagt werden können. Drittens validieren wir empirisch, dass heterogene Datenquellen wie Bücher und Web vorteilhaft sind und eine höhere Priorisierung verdienen. Bislang stellen diese Experimente die umfangreichste öffentlich dokumentierte empirische Studie zu den Auswirkungen von Vortrainingsdaten dar. Mit 28 einzigartigen, von Grund auf vortrainierten Modellen mit 1,5 Milliarden Parametern validieren, quantifizieren und offenbaren diese Ergebnisse viele undokumentierte Intuitionen über das Textvortraining, die letztlich fundiertere datenzentrierte Entscheidungen in der Modellentwicklung ermöglichen.
One-sentence Summary
Researchers from MIT, Cornell, Google Research, and other institutions conduct the largest publicly documented empirical study of pretraining data design, training 28 unique 1.5-billion-parameter models from scratch to quantify the effects of data age, domain coverage, quality, and toxicity filters on performance, revealing trade-offs between benchmark scores and toxic generation risk and validating long-held data-centric intuitions.
Key Contributions
-
The study provides controlled empirical evidence on pretraining data curation by training 28 unique 1.5 billion parameter models from scratch with different collection times, toxicity and quality filters, and domain compositions. It quantifies how dataset age, filtering, and source composition shape downstream performance.
-
The analysis shows that temporal shift between pretraining and evaluation data causes performance degradation that finetuning does not fully overcome. This establishes pretraining corpus age as a consequential modeling factor rather than an incidental property.
-
The experiments reveal that quality and toxicity filtering trade off standard benchmark performance against toxic generation risk, while heterogeneous sources such as books and web data provide broad benefits. The results also indicate that the effects of filtering are not reliably predictable from text domain characteristics alone.
Introduction
The authors note that modern language models depend on self supervised pretraining over large text datasets, where developers make consequential choices about collection time, quality and toxicity filtering, and domain composition. These choices strongly shape model behavior, yet many prominent models rarely document why certain curation protocols were chosen or how they affect downstream performance. This documentation gap leaves practitioners to rely on unexamined intuitions and precedents, which can weaken responsible data use, model comparison, and development efficiency.
Prior work has mostly focused on the scale of pretraining data and the number of optimization steps, treating curation policies as implicit conventions rather than measurable model design choices. Existing filtering methods are also applied without a clear understanding of their downstream consequences, while temporal mismatch between pretraining and evaluation data can distort performance comparisons, especially for newer or larger models.
The authors contribute a systematic study of pretraining data curation by analyzing dataset age, content filtering, and domain composition. They combine observational measurements on major corpora, C4 and the Pile, with controlled pretraining experiments across 28 1.5B parameter decoder models. Their results show that temporal mismatch reduces performance, quality filtering can improve capability while increasing toxic generation, toxicity filtering can reduce harmfulness but harm generalization, and diverse high quality sources such as books and web data remain important for strong downstream performance.
Dataset
-
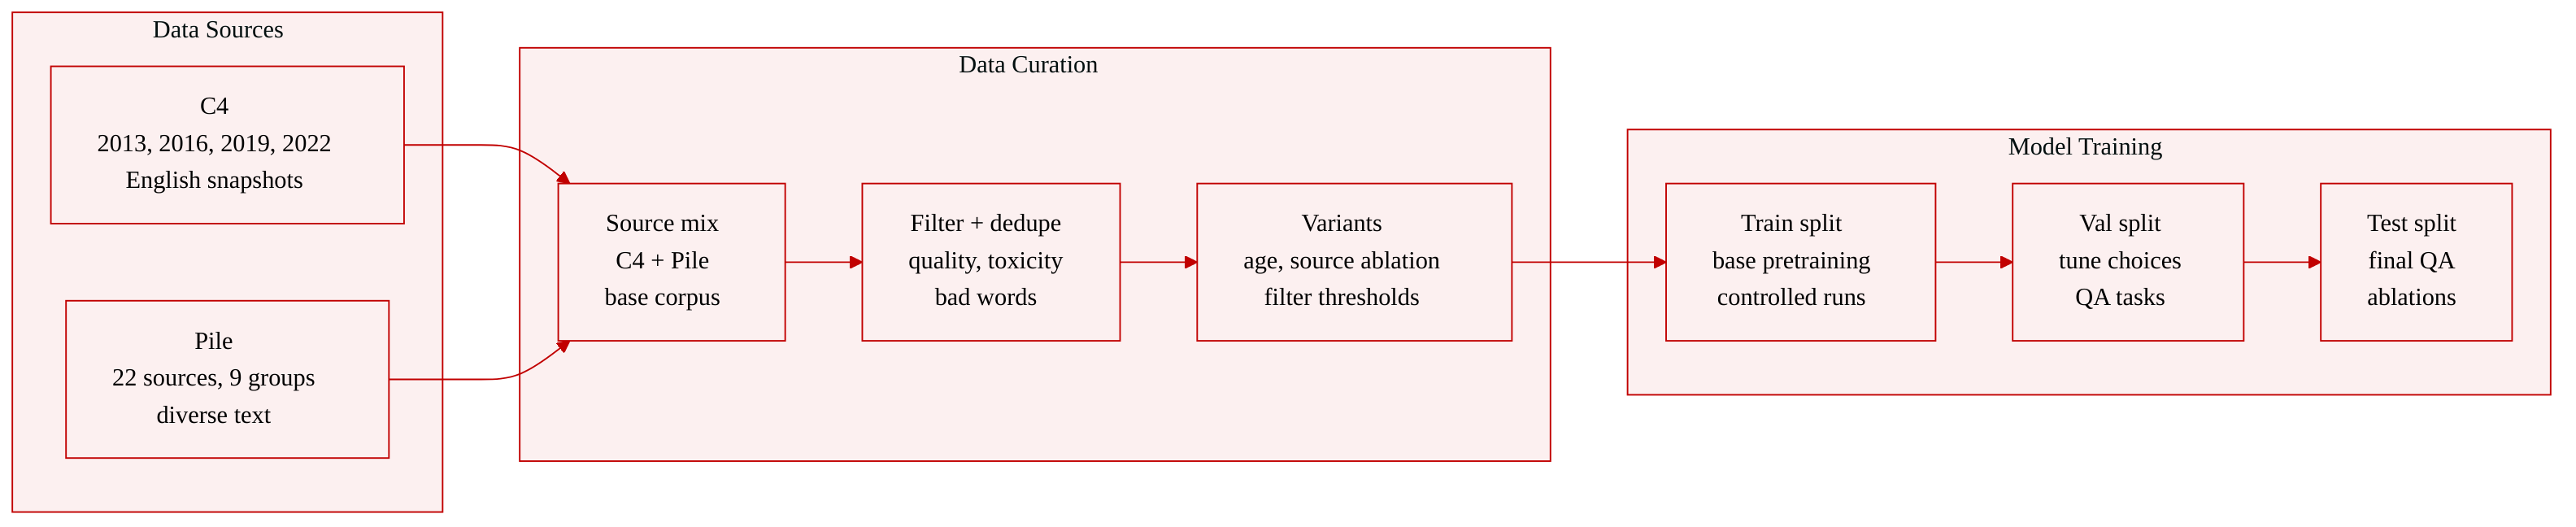
The authors use two public pretraining corpora, C4 and the Pile. Both are subjected to heuristic filtering for English language and content quality, followed by deduplication.
-
They create four C4 variants from Common Crawl snapshots taken in 2013, 2016, 2019, and 2022 to study how the age of pretraining data affects results.
-
They group the Pile's 22 original sources into 9 categories: Common Crawl, OpenWebText, books, Wikipedia, legal, social, biomedical, academic, and code. Each category is ablated one at a time to measure its impact on diverse question answering tasks.
-
They apply a document level quality filter used by PaLM and GLaM, which scores each document from 0 for high quality to 1 for low quality. Documents are filtered at thresholds of 0.975, 0.95, 0.9, and 0.7, and an inverse filter is tested to remove the highest quality documents.
-
They apply toxicity filtering using the Jigsaw Perspective API at thresholds of 0.95, 0.9, 0.7, 0.5, and 0.3, plus an inverse filter that removes the least toxic documents. They also use the original C4 bad words filter, which removes documents containing listed profanity.
-
The paper analyzes dataset characteristics and finds that quality and toxicity are not well aligned. The books subset has higher predicted quality but also more profane, toxic, and sexually explicit content. Technical domains such as PubMed, code, and academic text receive lower predicted quality scores.
-
These datasets are used as base pretraining corpora and as controlled variations for evaluating the effects of data age, source composition, and filtering choices.
Method
The authors design their experiments around a controlled data curation and evaluation pipeline. They start from a large pretraining corpus, apply a document level filter to produce a curated subset, train a language model on that subset, and then finetune and evaluate the model on downstream tasks. This setup allows them to connect specific pretraining data choices to measurable changes in final model performance.
As shown in the figure below:
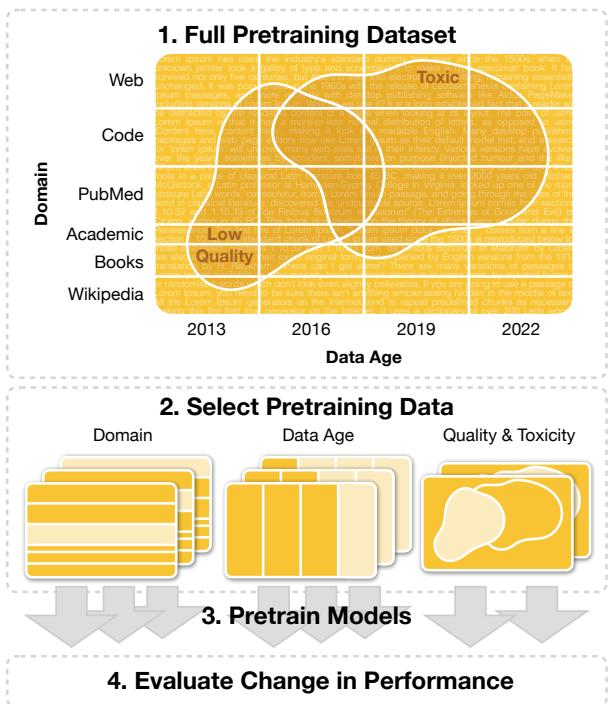
The pipeline is organized as a sequence of three main operations. First, the full pretraining dataset is represented across several axes, including data source domain, data age, and document level quality or toxicity. Second, the authors subselect data from this full pool by varying one dimension at a time. Third, the selected data variants are used to pretrain models, after which downstream performance is measured. This makes the method a causal style comparison between otherwise similar model training runs, with differences isolated to the curation of the pretraining data.
The data filtering module is central to the method. The authors consider three types of interventions: temporal variation, source composition variation, and filter based variation. For temporal variation, they create multiple snapshots of a web based corpus from different years. For source composition variation, they partition a mixed source corpus into categories such as web, books, encyclopedia, legal, social, biomedical, academic, and code, then remove one source group at a time to observe the downstream impact. This part of the pipeline treats the pretraining corpus as a structured mixture rather than a monolithic text pool.
The quality filtering module assigns each document a scalar quality score and removes documents that exceed a chosen threshold. The authors sweep multiple thresholds to create progressively stronger filtered datasets. They also experiment with the inverse of this filter, removing the highest quality documents instead, which allows them to test whether quality filtering improves performance because it removes bad documents, preserves good documents, or both.
The toxicity filtering module uses a trained classifier that predicts the likelihood that a document contains harmful or offensive content. The authors apply several confidence thresholds and also evaluate an inverse filtering variant that removes documents with the least predicted toxicity. In addition, they test a simpler n-gram based filter that removes any document containing a word from a profanity list. This gives a comparison between classifier-based filtering and rule-based filtering, both of which operate at the document level.
The model training module uses decoder-only Transformer language models. The main experiments rely on a 1.5B parameter model trained with an autoregressive next-token prediction objective. For scaling studies, they also use a much smaller 20M parameter model with the same general architecture family. Training is performed within a T5X style implementation, and all variants share the same basic model design so that differences in evaluation results can be more cleanly attributed to differences in the pretraining data rather than to model architecture or training procedure.
After pretraining, the models are evaluated through downstream finetuning and benchmarking. This evaluation stage is essential to the method because the paper’s central question is not whether filtered data improves validation loss on the pretraining corpus, but whether different curation strategies change task performance after adaptation. In this way, the full pipeline links data selection decisions, filtering thresholds, and data mixture changes directly to downstream model utility.
Experiment
The experiments pretrain models on curated variants of C4 and the Pile, then finetune and evaluate them on English toxicity, question answering, and time-sensitive tasks to study dataset age, quality filtering, toxicity filtering, and domain composition. Results show that temporal misalignment between pretraining and evaluation continues to degrade performance despite relevant finetuning, especially for larger models and when evaluation data is newer than pretraining data. Quality filters generally improve most downstream tasks, though their effects vary by domain, while toxicity filtering creates a trade-off between reducing toxic generation and preserving toxicity identification. Domain ablations indicate that diverse web and book data are particularly important for broad downstream performance, supporting the value of combining heterogeneity, quality, and scale in pretraining corpora.
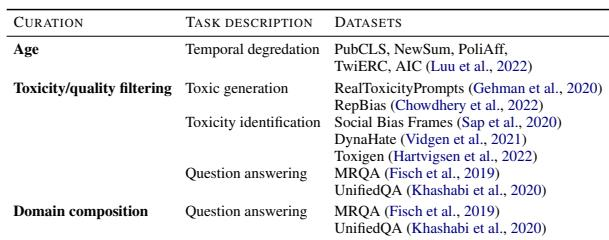
The evaluation setup examines how corpus age, toxicity and quality filtering, and domain composition affect finetuned model behavior. It links each curation choice to targeted tasks, including temporal degradation, toxic generation, toxicity identification, and question answering across varied domains. These benchmarks are chosen to capture broad dataset ablation effects while acknowledging that toxicity and quality labels remain imperfect proxies. Corpus age is evaluated through temporal datasets that measure degradation as time increases. Toxicity and quality filters are assessed using both toxic generation and toxicity identification tasks. Domain composition is evaluated through question answering benchmarks spanning multiple domains.
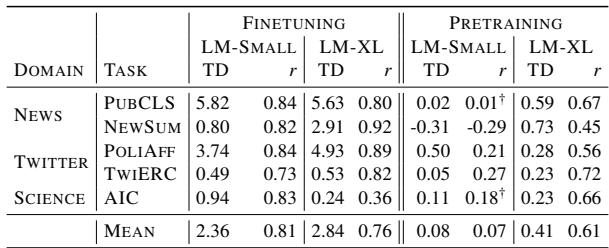
The results show that temporal misalignment degrades performance for both finetuning and pretraining, with one year of finetuning drift producing larger losses than one year of pretraining drift. Pretraining-related degradation persists after finetuning and is most visible in news and model-size-dependent settings, while correlations with time gaps are generally strong enough to support a systematic effect. Finetuning-year mismatches cause the largest degradation, while pretraining-year mismatches still lead to notable performance loss. News tasks on the larger model show strong temporal sensitivity, and most time-performance correlations are significant, with a few exceptions.
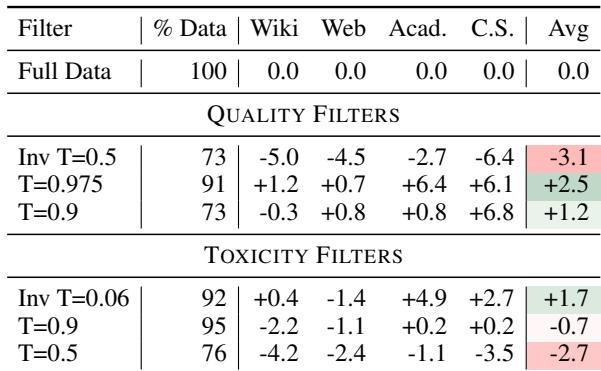
Quality filtering on C4 generally improves average QA performance, with the strongest gains on Academic and Contrast Set tasks. These gains can occur even when a substantial share of pretraining data is removed, though the effect varies by domain and source quality. Toxicity filtering creates a tradeoff: it can reduce toxic generation but may weaken toxicity identification and harm unrelated QA performance. Stronger quality filtering raises average QA performance and especially benefits lower quality source domains such as Academic. Toxicity filtering does not uniformly improve model behavior; it can hurt unrelated QA while improving only selected toxicity related outcomes.
Removing source domains from the pretraining mixture produces uneven effects across QA evaluations. Removing books yields the clearest average decline, while removing academic text leaves the average near baseline and can improve some QA scores. Web and common-sense QA are broadly sensitive to domain removal, whereas biomedical scores remain relatively stable. Books removal produces the largest overall QA drop Academic removal is the least harmful on average and raises some QA scores Web QA tends to decline after most domain removals Common-sense QA is sensitive to removing several domains Biomedical QA changes little across most removals
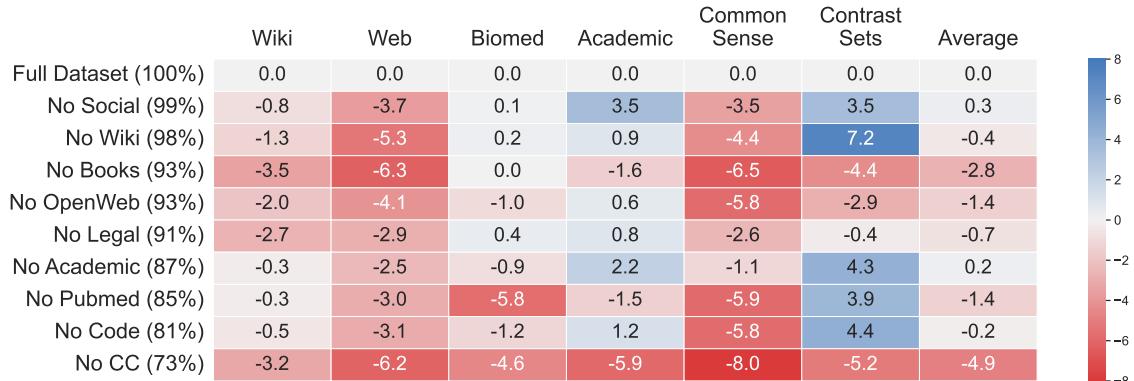
The experiments evaluate how corpus age, quality and toxicity filtering, and domain composition influence finetuned model behavior across temporal, toxicity, and question answering benchmarks. Results show that temporal misalignment systematically harms performance, especially when finetuning and pretraining years do not match, with news and larger models most sensitive. Quality filtering generally improves question answering, while toxicity filtering offers only selective benefits and can harm unrelated QA, and domain removal produces uneven effects, with books removal the most damaging and biomedical QA relatively stable.