Command Palette
Search for a command to run...
Wie viel können Sprachmodelle auswendig lernen?
Wie viel können Sprachmodelle auswendig lernen?
John X. Morris Chawin Sitawarin Chuan Guo Narine Kokhlikyan G. Edward Suh Alexander M. Rush Kamalika Chaudhuri Saeed Mahloujifar
Zusammenfassung
Aufgrund der inhärenten Struktur der Sprache hatten frühere Studien zum Auswendiglernen von Sprachmodellen Schwierigkeiten, Auswendiglernen von Generalisierung zu trennen. Wir trennen Auswendiglernen formal in zwei Komponenten: unbeabsichtigtes Auswendiglernen, die Information, die ein Modell über einen bestimmten Datensatz enthält, und Generalisierung, die Information, die ein Modell über den wahren Datengenerierungsprozess enthält. Wenn wir die Generalisierung vollständig eliminieren, können wir das gesamte Auswendiglernen berechnen, was eine Schätzung der Modellkapazität liefert: Unsere Messungen ergeben, dass GPT-ähnliche Modelle eine Kapazität von etwa 3,6 Bits pro Parameter besitzen. Wir trainieren Sprachmodelle auf Datensätzen zunehmender Größe und beobachten, dass Modelle so lange auswendig lernen, bis ihre Kapazität erschöpft ist, woraufhin das unbeabsichtigte Auswendiglernen abnimmt, da die Modelle beginnen zu generalisieren. Wir trainieren Hunderte von Transformer-Sprachmodellen mit 500K bis 1,5 Mrd. Parametern und erzeugen eine Reihe von Skalierungsgesetzen, die Modellkapazität und Datengröße mit Membership Inference in Beziehung setzen.
One-sentence Summary
This work formally decomposes language model memorization into unintended memorization and generalization, estimating that GPT-style models have a capacity of approximately 3.6 bits per parameter and deriving scaling laws that relate model capacity and data size to membership inference.
Key Contributions
-
A formal definition of memorization is introduced that separates unintended memorization from generalization and measures the number of bits a model stores about a specific dataset independently of the training algorithm. The definition is operationalized from model likelihoods using information-theoretic and Kolmogorov-complexity-based approximations for sample-level estimates.
-
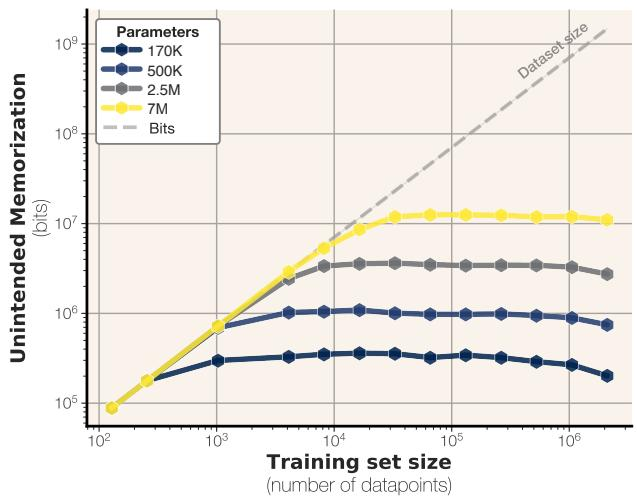
Model capacity measurements estimate GPT-style transformer language models store about 3.6 bits per parameter, with a reported range of about 3.5 to 4 bits depending on architecture and precision. Training on larger datasets is shown to fill this capacity with sample-specific storage before models substitute unintended memorization for generalization, connecting that transition to double descent.
-
Scaling laws are derived and validated for membership inference based on model capacity and dataset size, using hundreds of transformer models from 500K to 1.5B parameters. These laws predict that larger models can memorize more samples, larger datasets make inference harder, and modern language models may be trained on enough data to make reliable membership inference on average data points unlikely.
Introduction
Modern language models are increasingly trained on vast datasets while parameter counts remain comparatively small, raising questions about whether models intentionally learn general patterns or unintentionally store specific training examples. Prior studies often measure memorization by extracting full training samples or inferring dataset membership, but these methods can confuse rote memorization with generalization because language models can be prompted to generate nearly any string. The authors propose a new measure of memorization based on compression, using model likelihood to estimate how many bits a model retains about a specific datapoint. They separate unintended memorization from generalization, show that transformer language models can store roughly 3.5 to 4 bits per parameter, and derive scaling laws showing how dataset size and model capacity affect membership inference reliability.
Method
The proposed method frames memorization as an information-theoretic measurement of what a trained model encodes about its training distribution. The authors use a reference model Θ to capture the expected statistical regularities of the data distribution X, while a learning algorithm L maps samples from X to a trained model Θ^. The total information about X stored in Θ^ is defined through mutual information as
mem(X,Θ^)=I(X;Θ^)=H(X)−H(X∣Θ^).This quantity measures all information from the dataset that has been transferred into the trained model. The authors then separate useful generalization from unintended memorization by conditioning on the reference model. If the reference model already explains much of the data, then any additional uncertainty reduction provided by Θ^ is attributed to unintended memorization:
memU(X,Θ^,Θ)=I(X;Θ^∣Θ)=H(X∣Θ)−H(X∣(Θ,Θ^)).The complementary quantity, intended memorization, is the portion of stored information that can be accounted for by the total dependence between the model and the data after removing the reference model contribution:
memI(Θ^,X,Θ)=I(X;Θ^)−I(X;Θ^∣Θ).This distinction is important because some behaviors are already predictable from the underlying data distribution, while others require the trained model to encode specific details that the reference model cannot explain. For measuring dataset-level unintended memorization, the authors also use a super-additivity property. If X=(X1,…,Xn) consists of independent samples, then the sum of per-sample unintended memorization lower bounds the dataset-level quantity:
i=1∑nmemU(Xi,Θ^,Θ)≤memU(X,Θ^,Θ).The entropy of the trained model, H(Θ^), also serves as an upper bound, implying that unintended memorization scales with data volume but cannot exceed the model’s total representational capacity.
Because entropy and conditional entropy are difficult to estimate directly for a single trained model and a single dataset instance, the authors move from Shannon-based statistics to a Kolmogorov-complexity formulation. For a string x, the Kolmogorov content HK(x) is the length of the shortest program p under a fixed computational model f such that f(p)=x:
HK(x)=f(p)=xmin∣p∣.When a reference string or model θ is available, the conditional version is
HK(x∣θ)=f(p,θ)=xmin∣p∣.The corresponding mutual information becomes
IK(x,θ)=HK(x)−HK(x∣θ).Using this representation, the authors define Kolmogorov memorization and its intended and unintended variants. The key practical insight is that, although exact Kolmogorov complexity is uncomputable, its value can be approximated through compression or predictive likelihoods. For a trained target model θ^, the term HK(x∣θ^) is estimated from the likelihood p(x∣θ^). When both the target model and a reference model are available, the conditional description is estimated using the better of the two likelihoods:
max{p(x∣θ^),p(x∣θ)}.The reference model used in practice is larger than the target model but shares its architecture and is trained on a broader data distribution. This allows the method to treat the reference model as an external source of generalizable structure and to isolate information that the target model stores beyond what the reference model already explains.
The method then uses this measurement framework to estimate model capacity. The authors define capacity as the maximum total memorization that a learning algorithm can store across datasets:
Capacity(L)=Xmaxmem(X,L(X)).In practice, capacity is measured by training models on datasets of increasing size until training loss saturates. To avoid dependence on architecture-specific or hyperparameter-specific saturation schedules, the authors train configurations for a fixed number of steps, specifically 106 iterations, which is long enough for the tested models to reach saturation. This produces a measurable saturation point for each model size and hyperparameter setting.
To isolate pure memorization from generalization, the authors also use synthetic sequences in which tokens are sampled uniformly and independently from a fixed vocabulary. Since such data contains no higher-level structure that a model can generalize from, intended memorization is effectively zero. In that setting, total memorization equals unintended memorization:
memI(X,Θ^,Θ)=0,memU(X,Θ^,Θ)=mem(X,Θ^).The authors approximate the required conditional descriptions by computing entropies under the trained model and the reference model and then subtracting them. This yields an empirical estimate of how many bits of the synthetic dataset are stored in the trained model.
The framework extends from raw memorization to membership inference by treating dataset size and model capacity as the two governing variables. For a trained model θ and a dataset D, the authors model the membership inference F1 score with a sigmoidal scaling law:
MembershipF1(θ,D)=21(1+c1σ(c2∣D∣Capacity(θ)+c3)),where
σ(z)=1+e−z1.This form captures the observed behavior that membership inference is strong when a high-capacity model is trained on a small dataset, but becomes harder as the dataset grows relative to capacity. The authors reuse experimental text data to fit the constants c1, c2, and c3, finding c1=1.34, c2=−0.034, and c3=−33.14. The fitted sigmoid curves closely match observed membership scores across model capacities and dataset sizes, generally within one to two percent. As shown in the figure below:
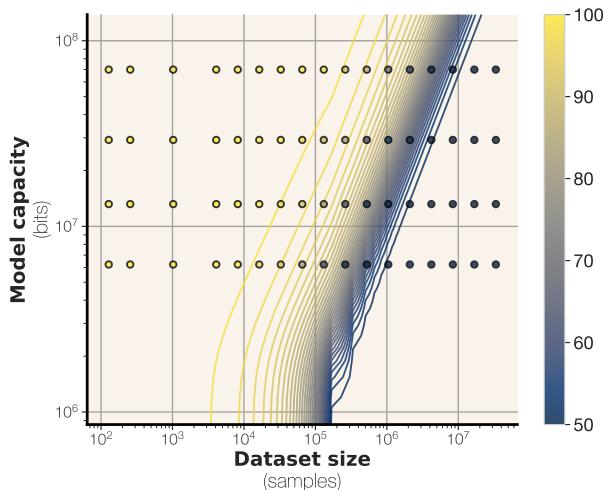
The limiting behavior follows directly from the fitted law. As ∣D∣→∞, the term Capacity(θ)/∣D∣ vanishes, and the predicted membership inference score approaches 0.5, corresponding to chance-level performance.
Experiment
Experiments use synthetic sequences and carefully deduplicated text to measure unintended memorization, extraction, and membership inference across model and dataset sizes. Synthetic data reveals a clear memorization capacity that scales roughly linearly with parameters and plateaus once exceeded, while precision has only a modest effect. Text experiments show that exceeding capacity triggers generalization and helps explain double descent, and that extraction and inference difficulty reflect the balance between memorization and generalization rather than a single failure mode.
Estimates of effective model capacity show that full precision provides only a modest gain over half precision when measured in bits per parameter. Capacity does not grow proportionally with model size across the reported widths, depths, and precisions. These results support the broader finding that membership inference depends strongly on model capacity relative to dataset size rather than parameter count alone. Half precision has per-parameter capacity estimates close to full precision. Increasing width or depth does not by itself produce large increases in bits per parameter. Membership inference becomes harder as dataset size increases relative to model capacity.
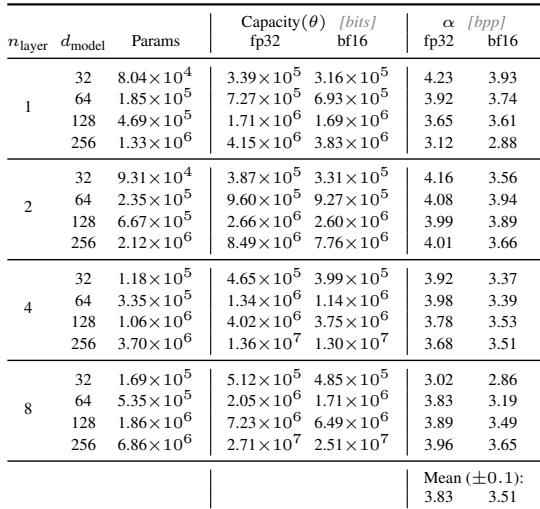
The experiments evaluate effective model capacity across different precisions, widths, and depths, measuring capacity in bits per parameter rather than relying only on parameter count. The results show that full precision offers only a small advantage over half precision, and increasing model size does not necessarily lead to proportional gains in per-parameter capacity. Overall, these findings support the conclusion that membership inference is driven more by the balance between model capacity and dataset size than by raw parameter count alone.