Command Palette
Search for a command to run...
Kontinuierliche Steuerung durch tiefes Bestärkendes Lernen
Kontinuierliche Steuerung durch tiefes Bestärkendes Lernen
Timothy P. Lillicrap Jonathan J. Hunt Alexander Pritzel Nicolas Heess Tom Erez Yuval Tassa David Silver Daan Wierstra
Zusammenfassung
Wir übertragen die Ideen, die dem Erfolg des Deep Q-Learning zugrunde liegen, auf den Bereich kontinuierlicher Aktionen. Wir präsentieren einen modellfreien Akteur-Kritiker-Algorithmus auf Basis des deterministischen Policy-Gradienten, der in kontinuierlichen Aktionsräumen operieren kann. Mit demselben Lernalgorithmus, derselben Netzwerkarchitektur und denselben Hyperparametern löst unser Algorithmus robust mehr als 20 simulierte physikalische Aufgaben, darunter klassische Probleme wie Cartpole-Swing-up, dexterer Manipulation, beinbasierte Fortbewegung und autonomen Fahren. Unser Algorithmus ist in der Lage, Politiken zu finden, deren Leistung mit jenen vergleichbar ist, die durch einen Planungsalgorithmus mit vollständigem Zugriff auf die Dynamik der Domäne und deren Ableitungen ermittelt werden. Wir zeigen ferner, dass der Algorithmus für viele der Aufgaben Politiken „End-to-End" erlernen kann: direkt aus Roh-Pixel-Eingaben.
One-sentence Summary
Google DeepMind proposes a model-free actor-critic algorithm based on the deterministic policy gradient that extends Deep Q-Learning to continuous action spaces, robustly solving more than 20 simulated physics tasks with performance competitive with full-dynamics planning and learning end-to-end policies directly from raw pixel inputs.
Key Contributions
- DDPG is an actor-critic, model-free algorithm based on the deterministic policy gradient that adapts Deep Q-Learning ideas to continuous action domains and robustly solves more than 20 simulated physics tasks, including cartpole swing-up, dexterous manipulation, legged locomotion, and car driving.
- With a single algorithm, network architecture, and hyper-parameter setting, DDPG learns policies competitive with a planning algorithm that has full access to the domain dynamics and derivatives, including policies learned end-to-end from raw pixel inputs.
- The results show stable learning without environment-specific modifications and nearly all tasks solved within 2.5 million experience steps, about 20 times fewer than Deep Q-Learning requires for good Atari solutions.
Introduction
Deep reinforcement learning enables agents to learn complex physical control tasks directly from high-dimensional observations such as pixels, which is important for robotics because it removes hand-designed state features and can handle perceptually rich environments. However, the widely used Deep Q Network (DQN) framework depends on maximizing a learned action-value function, making it best suited for discrete action spaces and difficult to apply directly to continuous, high-dimensional controls. Naively discretizing continuous actions causes an explosion in the number of possible actions, makes exploration inefficient, and ignores useful structure in the action space, while earlier actor-critic and policy gradient methods often become unstable or scale poorly when paired with deep neural networks. The authors leverage these insights to introduce Deep Deterministic Policy Gradient (DDPG), a model-free, off-policy actor-critic algorithm with deep function approximators for continuous control. Their method combines deterministic policy gradients with DQN-style stability mechanisms, including replay buffers and target networks, plus batch normalization, to learn robust physical control policies from both low-dimensional state inputs and raw pixels.
Method
The method is a deep actor-critic reinforcement learning framework for continuous action spaces. Standard Q-learning is difficult to apply directly when actions are continuous, because computing the greedy action at every time step requires solving an optimization problem over the action space. To avoid this, the authors use an actor-critic architecture in which a deterministic actor maps states to actions, while a critic estimates the value of state-action pairs and guides actor improvement.
The actor is parameterized as
μ(s∣θμ)and outputs a deterministic action for a given state. The critic is parameterized as
Q(s,a∣θQ)and is learned using a Bellman-style value update. The actor is updated by differentiating the expected return with respect to the actor parameters through the critic. Using the chain rule, the actor gradient can be written as
∇θμJ≈Est∼ρβ[∇θμQ(s,a∣θQ)s=st, a=μ(st∣θμ)]or equivalently,
∇θμJ=Est∼ρβ[∇aQ(s,a∣θQ)s=st, a=μ(st∣θμ)∇θμμ(s∣θμ)s=st].Here, the critic provides the gradient signal with respect to the action, and the actor is updated to produce actions that increase the critic’s value estimate.
The full method, referred to as deep deterministic policy gradient, extends this idea with several design choices that make neural network learning more stable in large continuous state and action spaces.
A replay buffer is used to collect transitions generated by the agent:
(st,at,rt,st+1).The buffer stores these transitions over many episodes. At each update step, the actor and critic are trained on a uniformly sampled minibatch from the buffer. This serves two purposes. First, it breaks the strong temporal correlation between consecutive environment transitions, which is useful because stochastic optimization methods typically assume that minibatch samples are approximately independent. Second, it enables efficient minibatch learning rather than fully online single-transition updates.
The critic is trained to estimate the action-value function using target values. To reduce instability, target copies of both the actor and critic are introduced:
μ′(s∣θμ′)andQ′(s,a∣θQ′).These target networks are used to compute stable targets for critic updates. Instead of copying the online network weights periodically, the target networks are updated softly by slowly tracking the online networks:
θ′←τθ+(1−τ)θ′,where 0<τ≪1. This makes the targets change gradually during training and turns value learning into a more supervised, lower-variance optimization problem. Using target copies for both actor and critic is important because the target action-value depends on both the target actor and the target critic. If either target component changes too abruptly, the critic targets can become unstable and training may diverge.
Batch normalization is also integrated into the network design. In low-dimensional continuous control tasks, state features may have different physical units and vastly different ranges, such as positions versus velocities. This can make learning sensitive to feature scaling and hyperparameters. To mitigate this, batch normalization is applied to normalize activations across the minibatch to have approximately zero mean and unit variance. Specifically, normalization is applied to the state input and to internal layers of the actor network, as well as to relevant layers of the critic network before the action input is incorporated. This reduces the need for manual feature scaling and improves generalization across tasks with different state magnitudes.
Exploration is handled separately from the deterministic policy. Since the learned actor maps each state to a single action, an exploration policy is constructed by adding stochastic noise to the actor output:
μ′(st)=μ(st∣θμ)+N,where N is sampled from a chosen noise process. This allows the agent to explore the continuous action space while still learning from a deterministic policy representation. For control problems with inertia or smooth dynamics, temporally correlated noise is preferred, because purely independent random perturbations can produce inefficient or unrealistic control signals. In such cases, an Ornstein-Uhlenbeck noise process can be used to generate smoother, autocorrelated exploration actions.
Overall, the method combines deterministic policy learning with off-policy experience replay, soft-updated target networks, batch normalization, and stochastic exploration. Together, these components allow a neural actor-critic agent to learn stable continuous control policies from sequential interactions with an environment.
Experiment
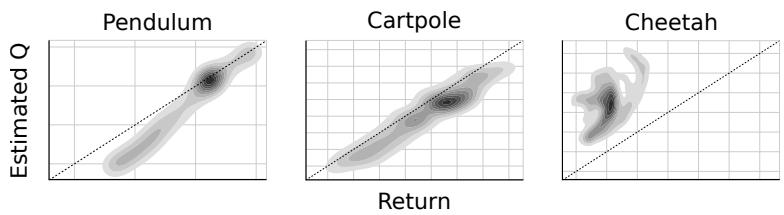
The experiments evaluate DDPG across simulated MuJoCo control tasks and a racing game, using both low-dimensional states and pixel observations, with periodic policy testing, ablations, baseline comparisons, and value-estimate analysis. The results show that algorithmic components such as the target network and batch normalization are important for stable learning, while pixel-based learning can be competitive with state-based learning on simpler tasks and can still yield useful policies in harder domains. Comparisons with naive and model-based baselines indicate that the learned controllers are broadly effective, and the Torcs experiment further demonstrates generality, though performance varies across training replicas.
Across the listed simulated tasks, DDPG often achieves positive normalized performance from both low-dimensional states and pixel observations, with best runs sometimes exceeding the planning baseline. Pixel-based learning can match or outperform low-dimensional state in some simpler tasks, but average performance is more variable across environments. The original DPG-style controller generally has weaker average performance, although some best-case runs remain competitive. Pixel observations can be competitive with, or in some cases superior to, low-dimensional state observations in simpler environments. The original DPG-style controller is less stable on average than DDPG, despite occasional strong best-case scores.
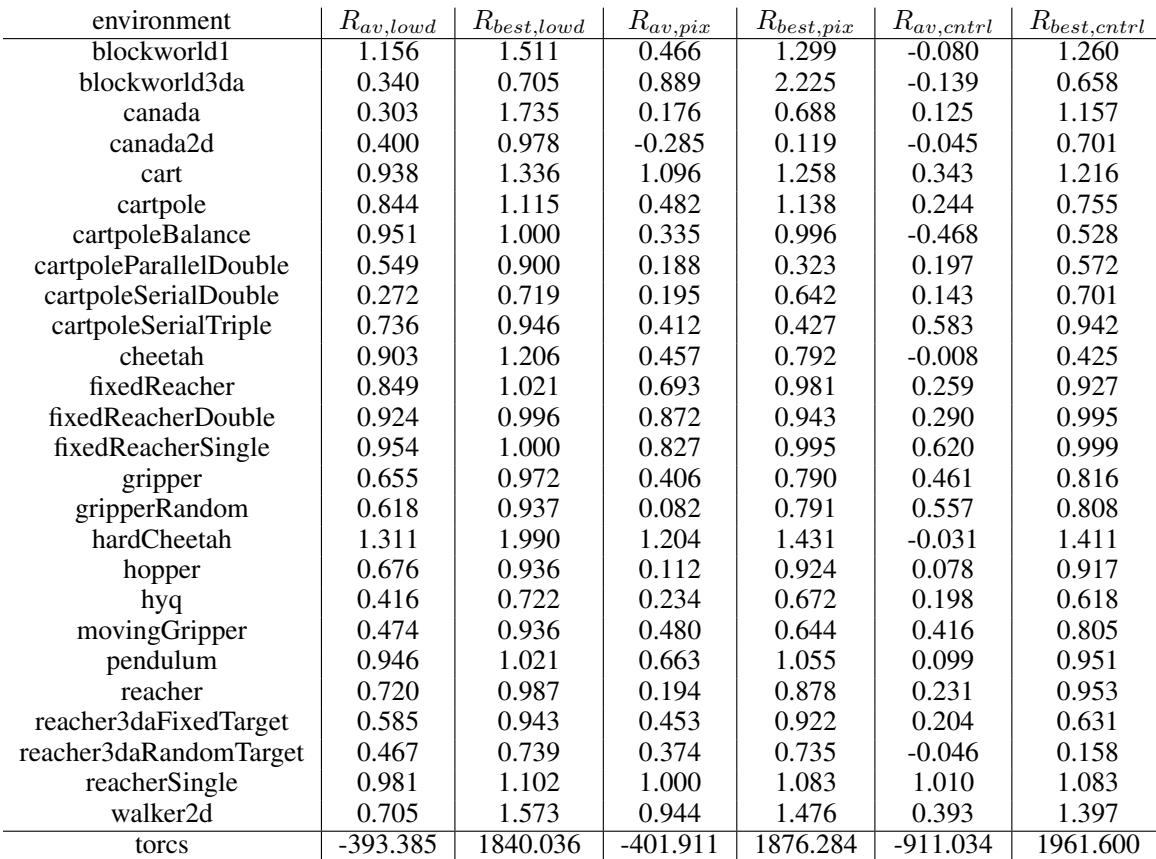
Experiments on simulated continuous-control tasks compare DDPG, pixel-based variants, and an original DPG-style controller. DDPG generally yields positive normalized performance from both low-dimensional states and pixels, occasionally surpassing a planning baseline, while pixel observations can match or outperform state inputs in simpler tasks despite greater variability. The original DPG-style controller is less stable and weaker on average than DDPG, though some best-case runs are competitive.