Command Palette
Search for a command to run...
OATH-Frames: Zur Charakterisierung von Online-Einstellungen gegenüber Wohnungslosigkeit mittels LLM-Assistenten
OATH-Frames: Zur Charakterisierung von Online-Einstellungen gegenüber Wohnungslosigkeit mittels LLM-Assistenten
Jaspreet Ranjit Brihi Joshi Rebecca Dorn Laura Petry Olga Koumoundouros Jayne Bottarini Peichen Liu Eric Rice Swabha Swayamdipta
Zusammenfassung
Warnung: Der Inhalt dieses Artikels kann verstörend wirken. Öffentliche Einstellungen zu zentralen gesellschaftlichen Themen, wie sie in Online-Medien geäußert werden, sind von enormem Wert für Politikgestaltung und Reformbemühungen, doch ihre Erfassung in großem Maßstab ist eine große Herausforderung. Wir untersuchen ein solches gesellschaftliches Thema – Wohnungslosigkeit in den USA –, indem wir die herausragenden Fähigkeiten großer Sprachmodelle nutzen, um Expertinnen und Experten der Sozialarbeit bei der Analyse von Millionen von Twitter-Beiträgen zu unterstützen. Wir führen eine Framing-Typologie ein: Online Attitudes Towards Homelessness (OATH) Frames – neun hierarchische Frames, die Kritik, Reaktionen und Wahrnehmungen abbilden. Wir veröffentlichen Annotationen mit unterschiedlichen Graden der Unterstützung durch Sprachmodelle, die erhebliche Vorteile in der Skalierung bieten: eine 6,5-fache Beschleunigung der Annotationszeit bei einem Leistungsrückgang von lediglich 3 F-Punkten im Vergleich zu den Fachexpertinnen und -experten. Unsere Experimente belegen den Mehrwert der Modellierung von OATH-Frames gegenüber bestehenden Sentimentund Toxizitätsklassifikatoren. Unsere großangelegte Analyse mit vorhergesagten OATH-Frames auf 2,4 Mio. Beiträgen zum Thema Wohnungslosigkeit deckt zentrale Trends in den Einstellungen über Bundesstaaten, Zeiträume und vulnerable Populationen hinweg auf und ermöglicht neue Erkenntnisse zu dem Thema. Unsere Arbeit bietet einen allgemeinen Rahmen zum Verständnis differenzierter öffentlicher Einstellungen in großem Maßstab, über das Thema Wohnungslosigkeit hinaus.
One-sentence Summary
University of Southern California researchers introduce OATH-Frames, a nine-frame hierarchical typology capturing online attitudes towards homelessness, in which LLM-assisted annotation achieves a 6.5× speedup with only a 3-point F1 reduction over domain experts, enabling large-scale analysis of 2.4M Twitter posts that reveals nuanced attitude trends across states, time periods, and vulnerable populations.
Key Contributions
- The paper introduces OATH-Frames, a hierarchical framing typology developed with social work experts and grounded in framing theory and grounded theory, to characterize online attitudes toward homelessness in the U.S. through three themes and nine issue-specific frames.
- The paper releases annotations for Twitter posts about homelessness, including 4.1K expert-only labels, 4.1K expert plus GPT-4 labels, and 2.4M model-predicted labels, using OATH guidelines and chain-of-thought prompts to achieve a 6.5x annotation speedup with only a 3-point reduction in F performance relative to expert-only annotation.
- The paper trains a multi-label OATH-Frames classifier and analyzes 2.4M predicted posts, showing that OATH-Frames reveal attitude trends across states, time periods, and vulnerable populations while surfacing harmful language toward people experiencing homelessness that sentiment and toxicity classifiers often misclassify.
Introduction
Public opinion on social issues is important for advocacy, policy, and social reform, and online platforms such as Twitter provide large, diverse records of public discourse that social science researchers can analyze at scale. Prior work on complex, emotionally mixed topics such as homelessness has largely relied on ethnography, surveys, and small-scale content analysis, making it difficult to capture broad online attitudes, especially when they are subtle, contradictory, or poorly represented by standard sentiment or toxicity models. The authors address this by introducing OATH-Frames, a social-science-grounded typology for characterizing online attitudes toward homelessness, and by developing a framework that combines social work expertise with LLM-assisted annotation, guided prompts, chain-of-thought reasoning, and large-scale classification models. Their approach supports scalable annotation and analysis of public discourse, including millions of posts, and reveals nuanced trends across states, time periods, and related social groups while identifying harmful language that generic classifiers often miss.
Dataset
-
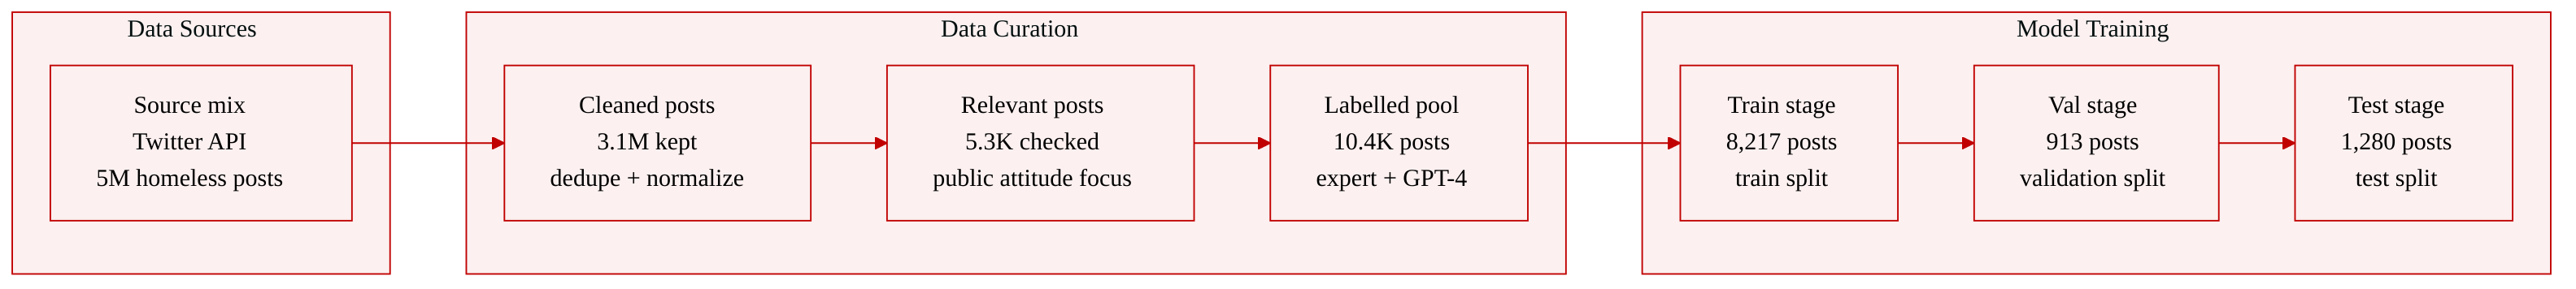
The authors build an OATH-Frames dataset from social media posts. They query the Twitter API for the keyword “homeless” and sample 5M posts.
-
The sampled posts are preprocessed by deduplicating content, replacing emojis with unicode, anonymizing user tags, and removing non-English posts. This leaves 3.1M posts from 2.1M unique users spanning 2021 to 2023.
-
The authors restrict the dataset to posts that express public attitudes and opinions about homelessness. They discard ambiguous, underspecified, or unrelated posts, such as posts about political homelessness, and also remove posts describing first-person lived experiences of people experiencing homelessness.
-
The annotation schema contains nine issue-specific OATH-Frames organized into three themes: critiques of systems and institutions, perceptions of people experiencing homelessness, and responses or proposed actions. The task is a nine-frame multilabel classification, and 54% of annotated posts receive more than one frame.
-
The expert annotation subset starts with 5.3K considered posts, from which 1.2K are filtered out, leaving 4.1K expert-annotated posts. Annotators achieve Fleiss’ kappa of 0.46 and macro F1 of 0.55. A 280-post multiply annotated subset is also used for agreement checks and standalone GPT-4 evaluation.
-
The LLM-assisted subset begins with GPT-4 predictions on 4.4K posts. Experts then validate the outputs and filter out 300 posts, leaving 4.1K Expert+GPT-4 validated posts. Expert validation removes false positive labels and improves precision.
-
The supervised training pool contains 10.4K examples: 5.3K Expert annotations, 4.1K Expert+GPT-4 annotations, and 1K filtered posts. These are split into 8,217 training, 913 validation, and 1,280 test posts.
-
The authors use the train, validation, and test split to train a classifier for a 10-way multilabel task consisting of the nine frames plus a filter label. The trained model is then used to annotate 2.4M unlabeled posts for large-scale analysis of public attitudes toward homelessness.
-
No image cropping strategy is described. The dataset metadata is built through text preprocessing and filtering, including deduplication, unicode emoji normalization, user tag anonymization, language filtering, relevance filtering, and frame label assignment by experts or LLM-assisted experts.
Method
Method and Training Pipeline
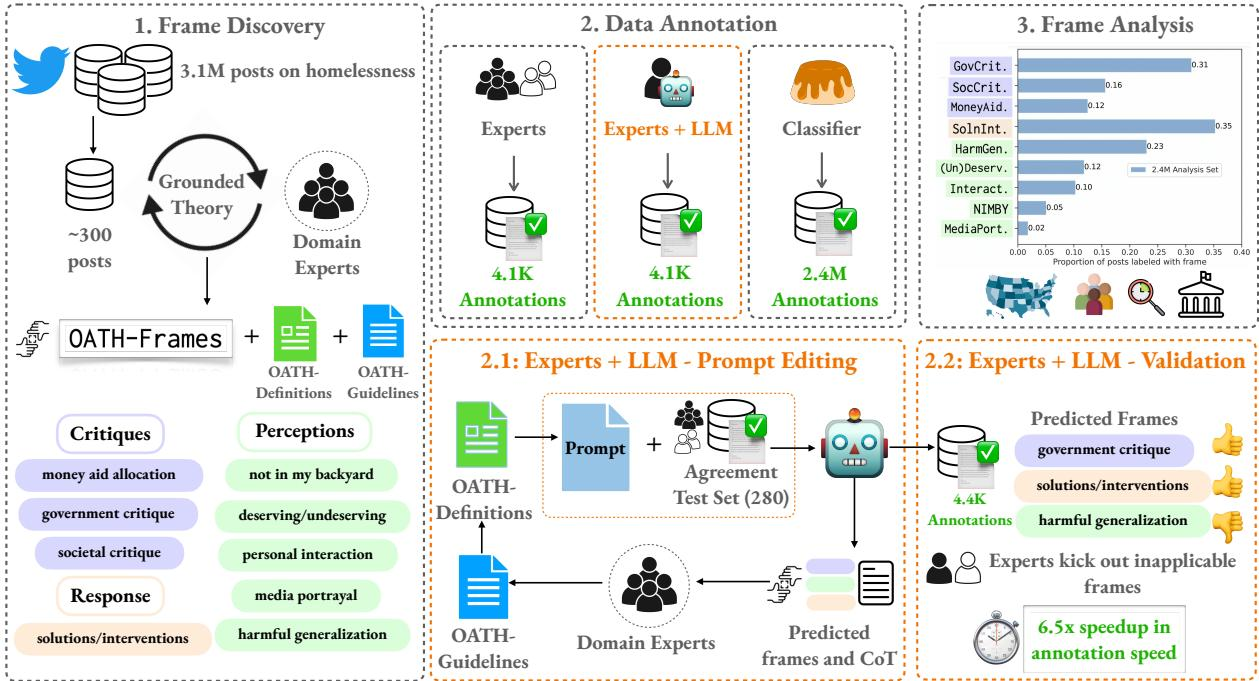
The authors leverage a three-part framework that converts raw social media discourse into frame-level annotations and then uses those annotations to study public attitudes. The pipeline begins with qualitative frame discovery, moves to a hybrid human–LLM annotation workflow, and ends with a supervised classifier that scales the typology to millions of posts. Refer to the framework diagram.
Frame Discovery Module
The first module identifies a pragmatically grounded typology of online attitudes toward homelessness. Starting from a keyword sample, the authors preprocess the corpus by removing duplicates, normalizing emojis, anonymizing user tags, and filtering out non-English posts. They then restrict the candidate set to posts that express public opinion rather than ambiguous, unrelated, or first-person lived-experience content.
Domain experts apply grounded theory through an iterative coding process. In each round, experts independently examine sampled posts, propose short descriptive codes, discuss edge cases, and merge similar categories until they reach consensus. This cycle is repeated on refreshed samples until thematic saturation is reached. The output is a structured typology of Issue-specific frames organized under three broader themes: critiques of systems and actors, perceptions of people experiencing homelessness, and responses or proposed solutions. The discovery process also produces formal frame definitions and annotation guidelines, which become central resources for later machine-assisted annotation.
LLM-Assisted Expert Annotation Module
To reduce the manual and emotional burden of annotating sensitive discourse, the authors build a collaborative annotation workflow that combines expert oversight with GPT-4 assistance. The design has two interacting submodules: prompt editing and prediction validation. As shown in the figure below:
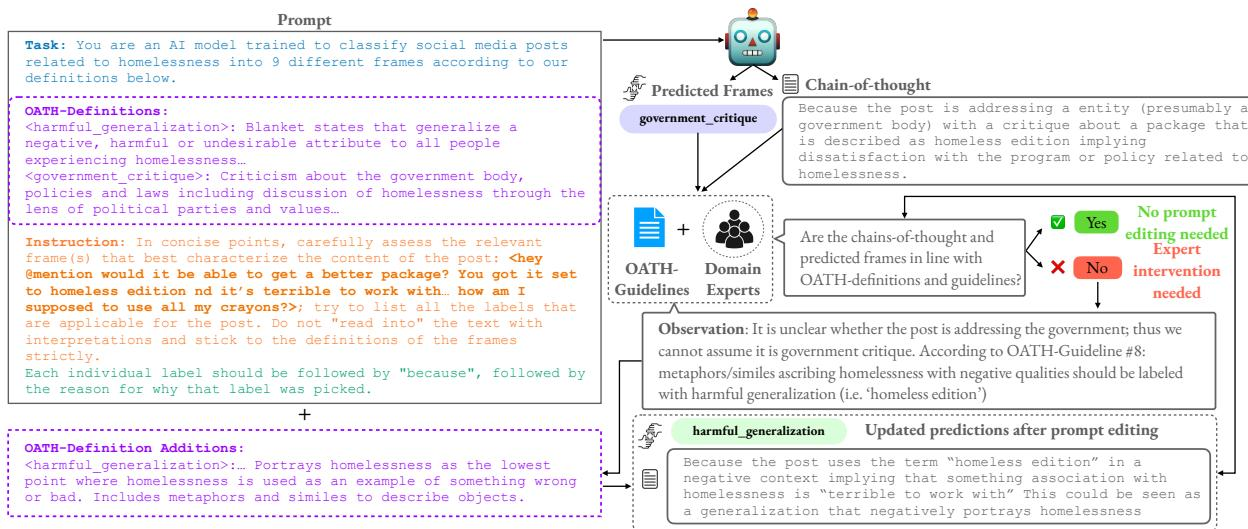
In the prompt-editing loop, GPT-4 is instructed to assign posts to the discovered frame set using task descriptions, frame definitions, concise labeling instructions, and expert-authored annotation guidelines. The model is also asked to generate chain-of-thought reasoning that explains each predicted label. On a shared evaluation subset of multiply annotated posts, denoted ∣Dagreement∣=280, domain experts inspect whether the predicted frames and rationales align with the definitions and guidelines. If not, they update the prompt with clarified definitions or additional guideline examples. This creates an iterative refinement pipeline in which expert knowledge is injected into the model prompt, and model-generated rationales help experts diagnose systematic misinterpretations.
The authors evaluate GPT-4 in a standalone setting on this subset and report precision of 0.39±0.05 and recall of 0.64±0.05. These results show reasonable label coverage but also a high rate of false positives, especially when posts contain indirect political references or domain-specific meanings that are easier for human experts to resolve. This motivates the second submodule, expert validation, in which annotators review the model’s predicted frames, remove inapplicable labels, and retain only reliable annotations. The hybrid design produces expert-guided annotations more efficiently than fully manual labeling, with a reported 6.5× speedup in annotation speed.
Scaling with a Supervised Multi-Label Classifier
Because expert and LLM-assisted annotation remain expensive at very large scale, the authors distill these higher-quality labels into a trainable multi-label classification model. They construct a training set from expert-only and expert-plus-LLM annotations, together with examples of posts that should be filtered out, yielding 10.4K supervised examples. These are split into train, validation, and test sets of 8217, 913, and 1280 posts respectively. The model is trained as a 10-way multi-label classifier, where the 10 target outputs correspond to the nine Issue-specific frames plus one filter label for posts that do not warrant frame annotation.
The authors use Flan-T5-Large as the supervised backbone, formulating annotation as label generation over social media posts. In their evaluation, this trained classifier outperforms the standalone GPT-4 prompt setup, achieving a Macro F1 of 0.51. The trained model is then used to assign frame predictions to a much larger unlabeled corpus. To assess whether scaling changes the qualitative signal, the authors compare frame distributions across expert, LLM-assisted, and model-predicted annotation sets. As shown in the figure below:
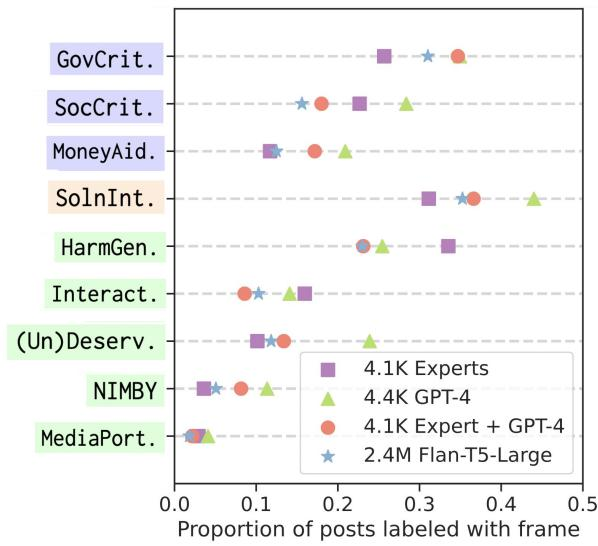
The distributional similarity across annotation strategies supports the use of the supervised classifier for large-scale socio-political analysis of public attitudes.
Experiment
Experiments validate an Expert+GPT-4 annotation workflow and demonstrate that OATH-Frames capture homelessness-related attitudes more effectively than sentiment and toxicity classifiers. The results show that expert review of GPT-4 outputs improves annotation quality and efficiency, while fine-tuned models provide competitive but less specialized baselines. Further analyses reveal that OATH-Frames distinguish region-specific attitudes, differences across vulnerable groups, and temporal shifts tied to public policy events, offering more targeted insight into harmful stereotyping and opinions about people experiencing homelessness.
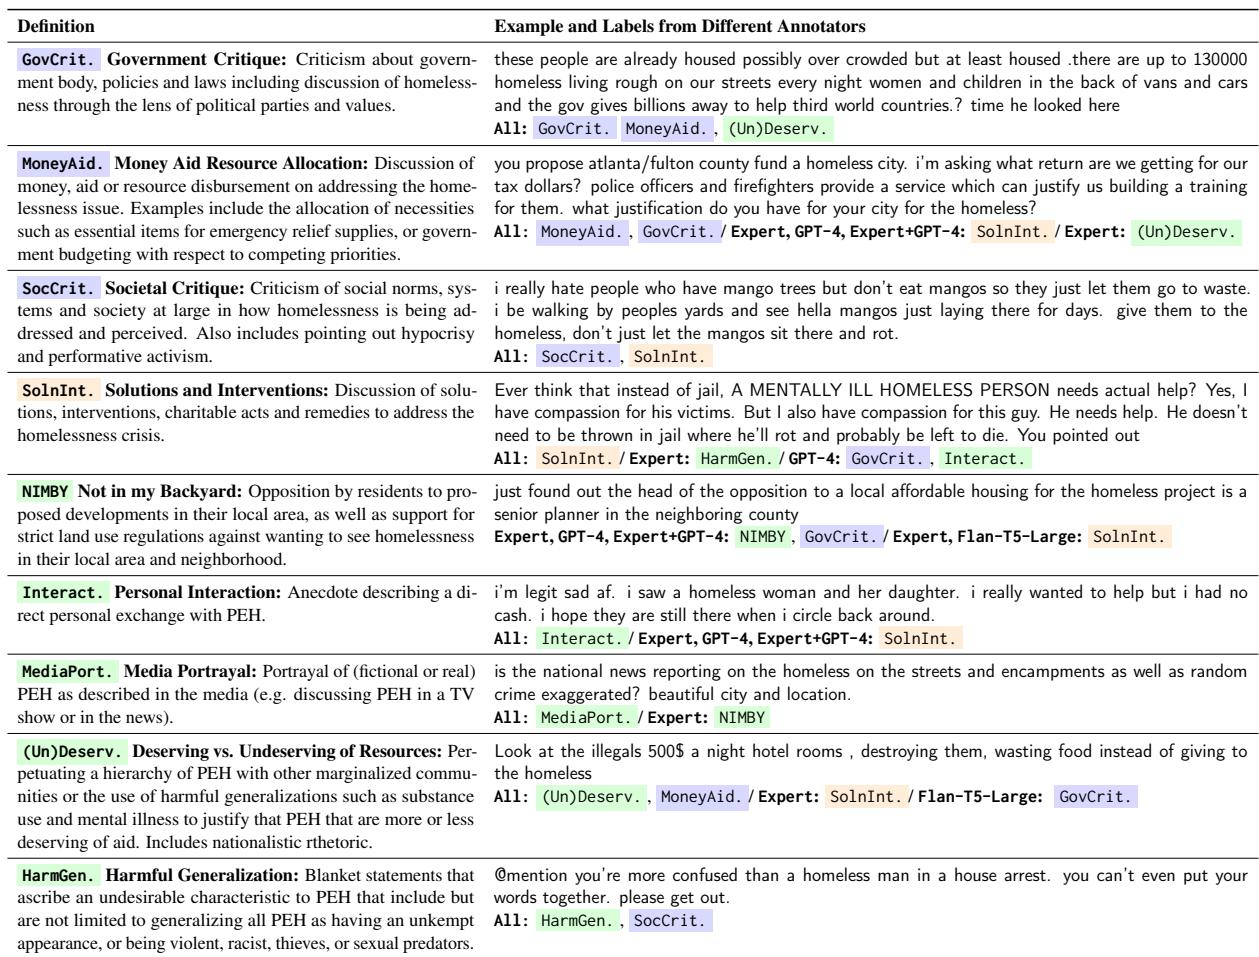
The table presents an OATH-Frames typology for public attitudes about homelessness, organized into critiques, perceptions, and responses. Its definitions and example posts show that a single post can support several issue-specific frames at once, and that expert labels and model predictions often overlap on broad frames while differing on finer distinctions. Definitions and examples map several issue-specific frames within three overarching themes Experts and models frequently assign multiple labels to the same post Agreement is common on major frames, but predictions diverge on adjacent categories
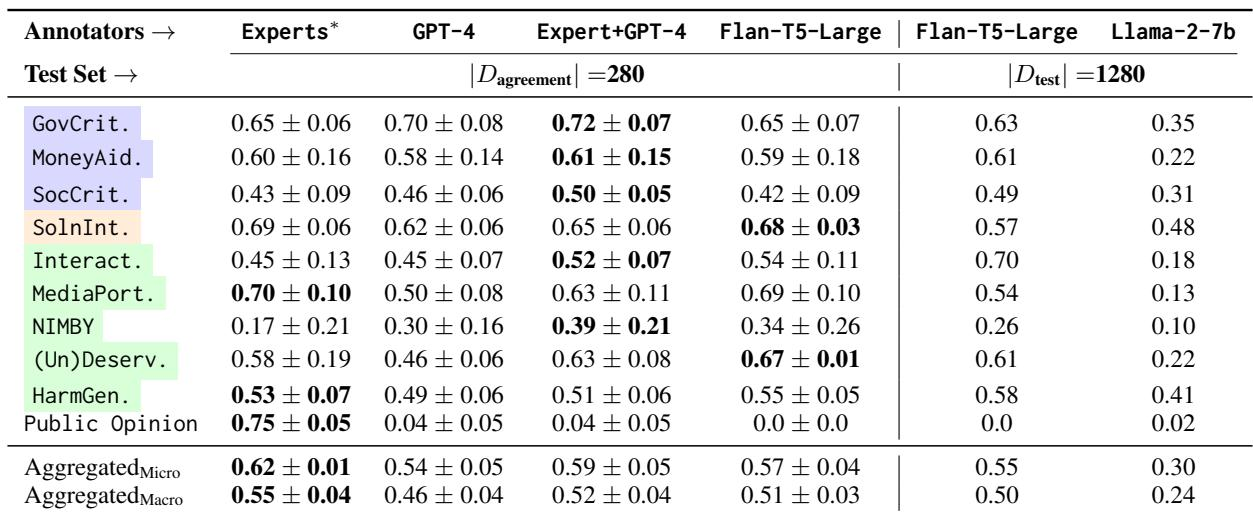
The annotation results compare expert labeling, standalone GPT-4, collaborative expert plus GPT-4 validation, and smaller trained or zero-shot models on multilabel frame prediction. Across the reported frames, Expert+GPT-4 and Flan-T5-Large generally achieve better F1 than standalone GPT-4, while expert-derived reference performance remains stronger overall. Frame-level performance varies widely, with zero-shot Llama showing especially weaker scores on several frames. Expert validation of GPT-4 output improves precision and overall F1 by removing false positives, with only a small recall trade-off. The collaborative annotation workflow greatly reduces the time experts need per post while producing stronger frame predictions than standalone GPT-4.
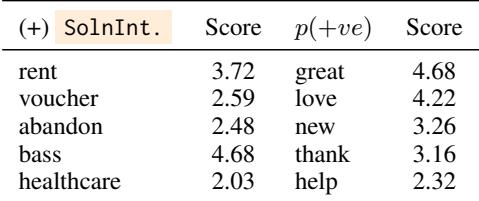
In California related posts, terms associated with solutions and interventions are tied to concrete homelessness issues, such as housing vouchers, rent, healthcare, and local shelter initiatives. Terms associated with positive sentiment are more general expressions of gratitude or approval, rather than specific policy or intervention topics. This suggests that OATH-Frames can surface targeted, domain-specific insights that generic positive sentiment may obscure. Posts labeled with solutions and interventions emphasize rent, vouchers, healthcare, abandonment, and the Bass initiative as likely topics. Posts with positive sentiment emphasize broad supportive words such as great, love, new, thank, and help. The difference supports targeted framing analysis for homelessness in California instead of relying on coarse sentiment labels.
The experiments evaluate OATH-Frames through typology development, annotation comparisons, and thematic analysis of California posts. Expert labeling and collaborative expert–GPT-4 validation produce stronger frame predictions than standalone GPT-4, especially by reducing false positives and saving expert time, while smaller zero-shot models show more inconsistent performance. Qualitative term analysis further shows that OATH-Frames can reveal concrete policy and intervention issues that generic sentiment labels tend to obscure.