Command Palette
Search for a command to run...
GeoRA: Geometriebewusste Low-Rank Adaptation für RLVR
GeoRA: Geometriebewusste Low-Rank Adaptation für RLVR
Jiaying Zhang Lei Shi Jiguo Li Jun Xu Jiuchong Gao Jinghua Hao Renqing He
Zusammenfassung
Reinforcement Learning mit verifizierbaren Belohnungen (RLVR) ist ein zentrales Paradigma zur Verbesserung großskaliger Reasoning-Modelle. Im Gegensatz zum überwachten Fine-Tuning (SFT) weist RLVR eigenständige Optimierungsdynamiken auf und ist besonders empfindlich gegenüber der Erhaltung vortrainierter geometrischer Strukturen. Bestehende parameter-effiziente Verfahren stoßen in diesem Regime jedoch auf wesentliche Einschränkungen. Low-Rank-Adaptation-Verfahren wie PiSSA sind primär für überwachtes Fine-Tuning konzipiert und berücksichtigen weder die spezifischen Optimierungsdynamiken noch die geometrischen Strukturen von RLVR. Umgekehrt führt die direkte Feinabstimmung des unstrukturierten, dünn besetzten Parameter-Unterraums, der für RLVR bevorzugt wird, auf moderner Hardware zu Effizienzengpässen. Zur Bewältigung dieser Herausforderungen schlagen wir GeoRA (Geometriebewusste Low-Rank Adaptation) vor, ein Low-Rank-Adaptationsverfahren, das gezielt für RLVR entwickelt wurde. GeoRA nutzt die anisotrope und komprimierbare Struktur des RL-Update-Unterraums und extrahiert dessen Hauptkomponenten mittels Singulärwertzerlegung (SVD) zur Initialisierung von Low-Rank-Adaptern, während die Residualkomponenten während des Trainings als struktureller Anker eingefroren werden. Dieses Design bewahrt die vortrainierte Struktur und ermöglicht gleichzeitig effiziente dichte Berechnungen. Experimente mit Qwenund Llama-Modellen von 1,5 Milliarden bis 32 Milliarden Parametern zeigen, dass GeoRA starke Low-Rank-Baselines in RLVR-Einstellungen für Mathematik, Medizin und Programmierung durchgängig übertrifft und zugleich eine bessere Generalisierung sowie weniger Vergessen auf domänenübergreifenden Aufgaben aufweist.
One-sentence Summary
Meituan and Peking University propose GeoRA, a geometry-aware low-rank adaptation method for RLVR that exploits the anisotropic, compressible structure of RL update subspaces via SVD to initialize low-rank adapters while freezing residual components as structural anchors, preserving pre-trained geometry and enabling efficient dense computation across mathematics, medicine, and coding tasks.
Key Contributions
-
The paper introduces GeoRA, a geometry-aware low-rank adaptation method for Reinforcement Learning with Verifiable Rewards that aligns parameter-efficient training with the optimization structure of RL updates.
-
GeoRA extracts principal directions from the anisotropic and compressible RL update subspace via Singular Value Decomposition for adapter initialization, and freezes residual components as a structural anchor to preserve pre-trained structure while enabling efficient dense computation.
-
Experiments on Qwen and Llama models from 1.5B to 32B parameters in mathematics, medicine, and coding show that GeoRA improves training stability, outperforms strong low-rank baselines, and shows stronger generalization with less forgetting on out-of-domain tasks.
Introduction
Large reasoning models use Reinforcement Learning with Verifiable Rewards to strengthen mathematical and coding reasoning, but RLVR works by amplifying existing latent behaviors rather than injecting new knowledge, so updates must stay stable and aligned with pre-trained model geometry. This matters because overly aggressive fine-tuning can collapse reasoning, degrade general abilities, or cause forgetting. Prior parameter-efficient methods struggle in this setting: SFT-oriented low-rank adaptation biases updates toward principal components that may conflict with RLVR's preferred directions, while sparse fine-tuning can match RLVR behavior but often lacks hardware efficiency. The authors leverage this insight to introduce GeoRA, a geometry-aware low-rank adaptation framework that uses SVD to extract dominant trainable directions from a geometry-constrained subspace, freezes residual components as structural anchors, and preserves dense computation for stable, hardware-efficient RLVR training.
Method
The authors leverage a low-rank adaptation framework for reinforcement learning with verifiable rewards, named GeoRA. Their design is motivated by the observation that reinforcement fine-tuning should not overwrite the pre-trained model globally, but instead should concentrate updates in stable yet plastic parameter regions. GeoRA therefore introduces an RL-native, structured low-rank parameterization together with a residual anchor that preserves the original function at initialization and restricts optimization to a geometry-aligned subspace. Unlike standard low-rank adaptation, which typically starts from random adapter parameters, GeoRA initializes the adapter from a geometry-constrained view of the pre-trained weight matrix. Refer to the framework diagram. As shown in the figure below:
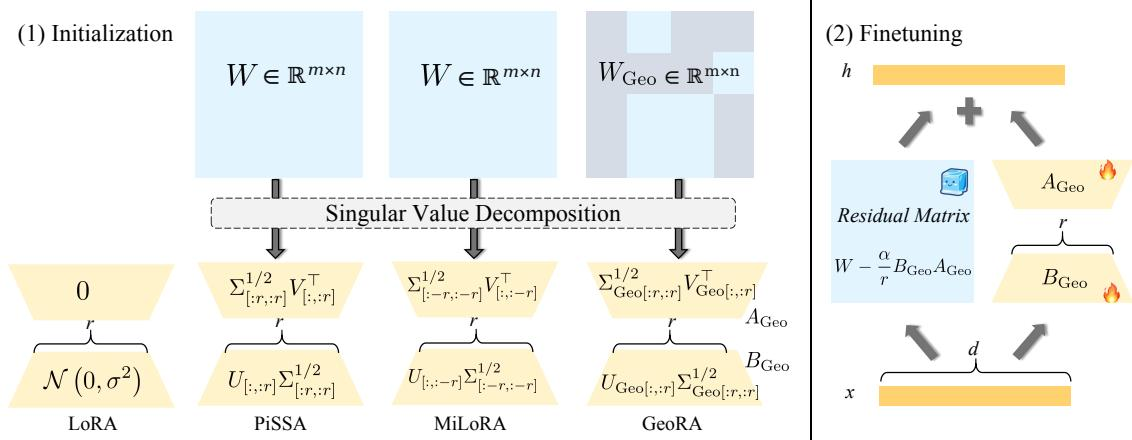
Let W denote a pre-trained weight matrix and let WGeo denote its geometry-constrained view. The authors perform singular value decomposition on this matrix,
WGeo=UGeoΣGeoVGeo⊤.They then keep only the leading rank r directions. If Ur and Vr denote the first r columns of UGeo and VGeo, and Σr denotes the leading r×r block of ΣGeo, the trainable adapters are initialized as
AGeo=Σr1/2Vr⊤,BGeo=UrΣr1/2.With this construction, the product BGeoAGeo approximates the rank r geometry captured by WGeo. To preserve the original model output at initialization, the authors compute a residual matrix
Wres=W−rαBGeoAGeo.During the forward pass, Wres remains frozen while the adapter branch is trainable,
h=Wresx+rαBGeoAGeox.At initialization, the two branches sum to Wx, so the model is function preserving. During optimization, gradient updates can only act on the low-rank adapter, forcing adaptation to remain inside the geometry aligned manifold while the frozen residual matrix protects the pre-trained representation.
The geometry constrained matrix WGeo is obtained through a lightweight masking process. The authors construct two complementary priors. The spectral prior selects low magnitude entries from the rank r approximation W^r:
(MSpec)i,j=I(∣(W^r)i,j∣≤τSpec(ρ)),where τSpec(ρ) is the ρth quantile of the absolute values in W^r. This mask suppresses dominant high energy directions and focuses adaptation on a more stable spectral region. The Euclidean prior selects low magnitude weights from the original matrix:
(MEuc)i,j=I(∣Wi,j∣≤τEuc(ρ)).The final mask is the union of the two regions, and the geometry constrained matrix is formed by masked weighting:
WGeo=W⊙(MSpec∪MEuc).Refer to the masking workflow diagram. As shown in the figure below:
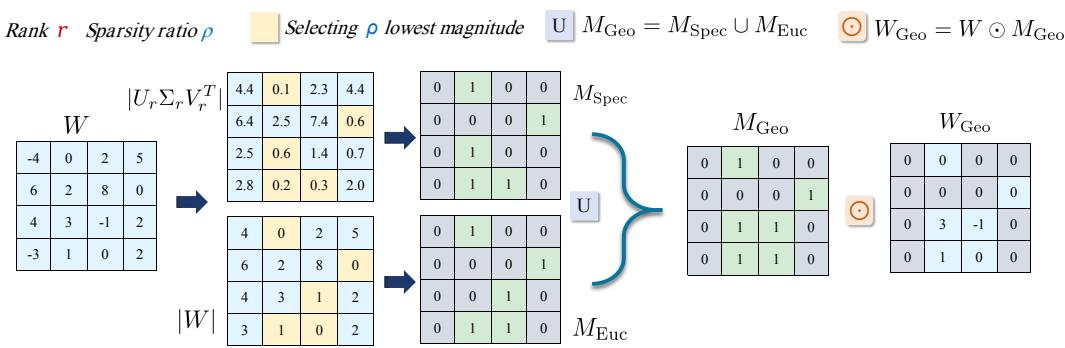
This masking strategy defines the update locus before adapter initialization. The spectral component protects the principal subspace by choosing the low tail of the rank r geometry, while the Euclidean component exposes near zero weights that can absorb reward driven perturbations. The union yields a region that is stable under reinforcement learning updates but still expressive enough for adaptation. The resulting WGeo then supplies the singular structure used to initialize the trainable low rank adapter, linking prior construction, adapter parameterization, and frozen residual computation into one training architecture.
Experiment
Experiments compare GeoRA with LoRA variants and full or sparse fine-tuning across mathematical, medical, and coding RLVR tasks, using multiple backbones, in-domain and out-of-domain benchmarks, training dynamics, ablations, and spectral analyses. GeoRA consistently improves mathematical reasoning, preserves broader general capabilities, transfers to other domains, converges faster, remains stable under challenging optimization settings, and greatly reduces trainable parameters. The analyses show that its geometry-aware initialization, spectral and Euclidean masks, and alignment with RLVR update geometry are key, while the learned subspace captures compressible low-rank structure and minimizes distortion of pre-trained features.
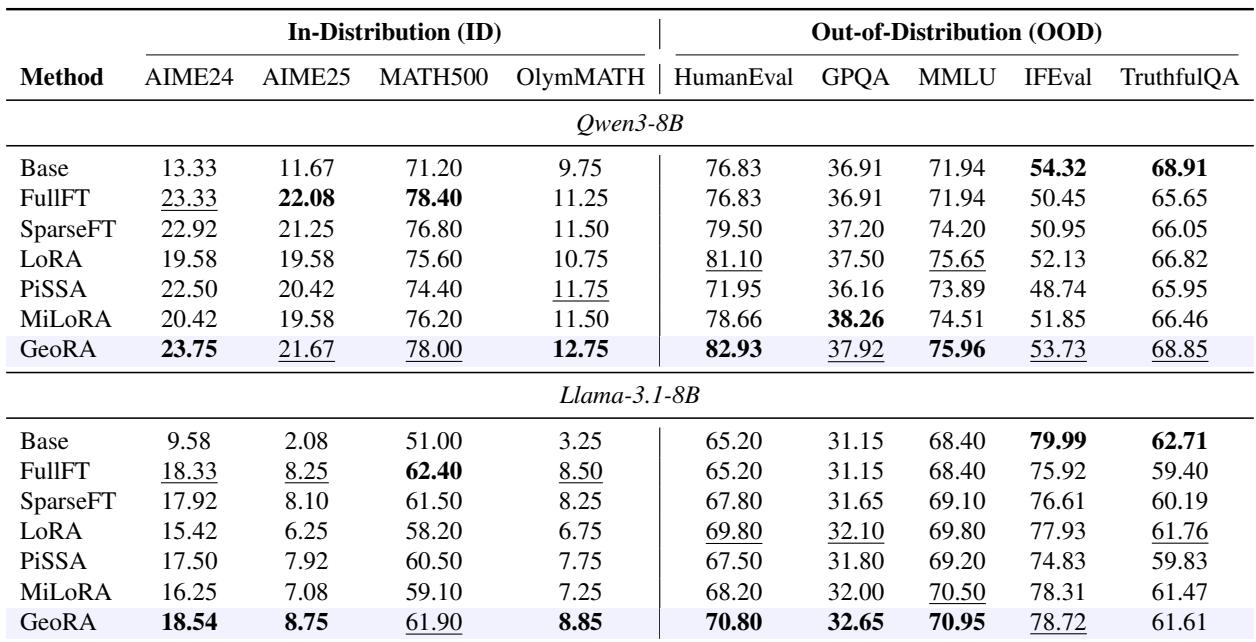
GeoRA shows the strongest overall gain on mathematical reasoning benchmarks, with clear advantages on harder competition-style tasks and competitive performance on broader math evaluation. It also maintains strong out-of-distribution capability, improving over the low-rank baselines on coding, scientific knowledge, and general QA-related metrics while avoiding large losses on instruction following and truthfulness. GeoRA outperforms LoRA, PiSSA, and other compared variants on most math reasoning settings, indicating geometry-aware initialization helps RLVR. The method transfers well beyond math, giving the best or near-best out-of-distribution results and better retention of general capabilities than several fine-tuning baselines.
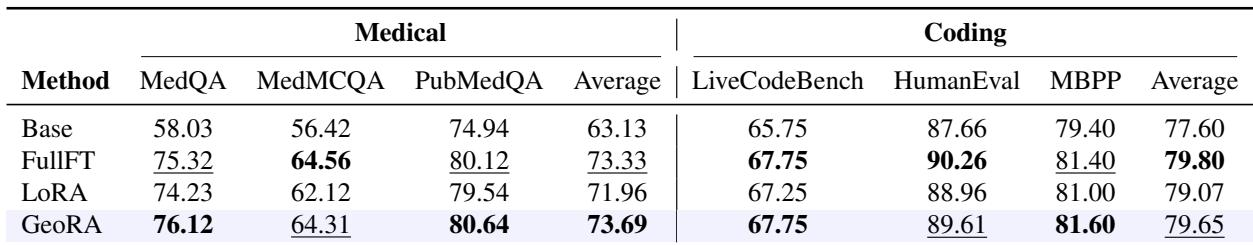
The method performs strongly on additional medical and coding RLVR tasks, improving over the base model and outperforming LoRA on the average scores for both domains. It also remains close to full fine-tuning, leading on the medical average and trailing only slightly on the coding average. These results support the claim that the method generalizes beyond mathematical reasoning tasks. It outperforms LoRA across all medical tasks and all coding tasks shown. It achieves the best overall medical average among the compared methods, while nearly matching full fine-tuning on coding.
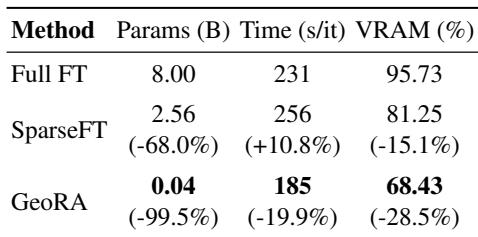
GeoRA is the most efficient among the compared methods, updating a tiny fraction of Full FT parameters while also lowering VRAM and per-iteration training time. SparseFT reduces parameters and memory use relative to Full FT but is slower, whereas GeoRA converts strong parameter efficiency into practical hardware efficiency by avoiding the overhead of unstructured sparse computation. GeoRA achieves very large reductions in trainable parameters relative to Full FT while also improving memory usage and speed. SparseFT lowers parameters and VRAM compared with Full FT but does not reduce per-iteration training time. GeoRA is more efficient than SparseFT in both speed and memory use, with its one-time initialization cost described as negligible relative to training.
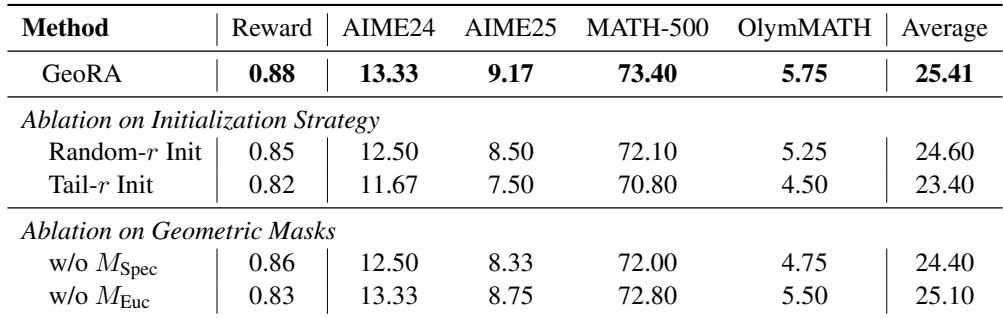
Ablation results for Qwen3-4B show that GeoRA performs best when geometry-aware initialization and both geometric masks are retained. Replacing the proposed initialization with random or tail-only variants reduces reward and mathematical reasoning accuracy, while removing either the spectral or Euclidean mask causes a consistent decline. Full GeoRA achieves the highest reward and average mathematical reasoning score among the ablated variants. Tail-r initialization gives the weakest performance, showing that low-energy direction selection alone is insufficient. Both spectral and Euclidean masks are needed, with each removal reducing average performance.
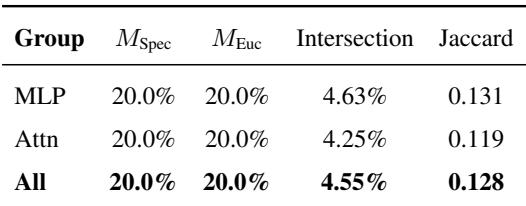
The spectral and Euclidean priors each select about 20% of parameters on the tested 8B model, but they overlap only slightly. The small overall intersection and low Jaccard similarity indicate that the masks identify largely different parameter subsets. The same pattern appears in both MLP and attention groups, supporting the view that the two geometric priors play complementary roles. Each prior covers a similar fraction of parameters while sharing only a small subset. The limited overlap across MLP and attention layers suggests the priors are complementary rather than redundant.
The experiments evaluate GeoRA on mathematical reasoning benchmarks, out-of-distribution tasks, and specialized medical and coding RLVR settings. Results show that geometry-aware initialization consistently improves math reasoning and transfers well to other domains while better preserving general capabilities than several fine-tuning baselines. Ablations and mask analyses show that both spectral and Euclidean masks are necessary and complementary, while efficiency tests show that GeoRA achieves strong hardware efficiency with far fewer trainable parameters.