Command Palette
Search for a command to run...
Capability Salience Vector: Feingranulare Abstimmung von Verlust und Fähigkeiten für das Skalierungsgesetz nachgelagerter Aufgaben
Capability Salience Vector: Feingranulare Abstimmung von Verlust und Fähigkeiten für das Skalierungsgesetz nachgelagerter Aufgaben
Zusammenfassung
Das Skalierungsgesetz stellt die Beziehung zwischen Trainingsrechenaufwand und Validierungsverlust her und ermöglicht es Forschenden, den Verlustverlauf von Modellen über verschiedene Berechnungsstufen hinweg effektiv vorherzusagen. Allerdings besteht weiterhin eine Lücke zwischen dem Validierungsverlust und den Fähigkeiten des Modells bei nachgelagerten Aufgaben, was die Anwendung des Skalierungsgesetzes zur direkten Leistungsvorhersage für diese Aufgaben erschwert. Der Verlust repräsentiert typischerweise eine kumulative Bestrafung für vorhergesagte Tokens, denen implizit eine gleich hohe Bedeutung beigemessen wird. Unsere Untersuchungen haben jedoch gezeigt, dass bei unterschiedlichen Trainingsdatenverteilungen der Zusammenhang zwischen der Fähigkeit bei nachgelagerten Aufgaben und dem Rechenaufwand bzw. Token-Verlust nicht direkt modelliert werden kann. Um die Lücke zwischen Validierungsverlust und Fähigkeiten bei nachgelagerten Aufgaben zu schließen, führen wir in dieser Arbeit den Capability Salience Vector ein, der den Gesamtverlust aufspaltet und Tokens unterschiedliche Bedeutungsgrade zuweist, um eine bestimmte Meta-Fähigkeit zu bewerten. Dabei wird der Validierungsverlust hinsichtlich der Modellfähigkeiten mit der Leistung bei nachgelagerten Aufgaben in Einklang gebracht. Experimente auf verschiedenen gängigen Benchmarks zeigen, dass der vorgeschlagene Capability Salience Vector die Vorhersagbarkeit der Leistung von Sprachmodellen bei nachgelagerten Aufgaben erheblich verbessert.
One-sentence Summary
Researchers from Shanghai AI Laboratory and Fudan University propose the Capability Salience Vector, which decomposes overall training loss into token-level importance weights aligned with specific meta-capabilities, bridging the gap between validation loss and downstream task performance to enable direct capability prediction via scaling law.
Key Contributions
- Introduces a Capability Salience Vector that decomposes overall token-level loss and assigns learned importance weights to tokens, linking validation loss to specific meta-capabilities and downstream task performance.
- Develops an automatic optimization method to construct this vector over text segments, using token-level weighting to capture reasoning-related capabilities and model scaling relationships between language-model cross-entropy loss and downstream outcomes.
- Evaluates the method on popular benchmarks, including a BBH visualization, showing that capability-weighted loss identifies reasoning-relevant tokens and significantly improves predictability of language-model performance on downstream tasks.
Introduction
Large language models use scaling laws to predict validation loss from model size, training data, and compute, reducing costly trial-and-error during pretraining. This matters because validation loss is a practical proxy for progress, but it does not always predict performance on downstream benchmarks, where real task capabilities matter. Prior work either tried to model downstream performance directly from compute, often ignoring the effect of changing pretraining data distributions, or built benchmark-derived proxies that require costly evaluation across many models and datasets. The authors show that neither compute nor raw validation loss alone is a reliable predictor, then introduce the Capability Salience Vector, a token-weighted loss metric with an automatic optimization method that emphasizes tokens relevant to downstream capabilities. Across six benchmarks and different model families, this weighted validation loss produces much stronger correlations with downstream scores, keeping predicted mean squared error below 0.001.
Method
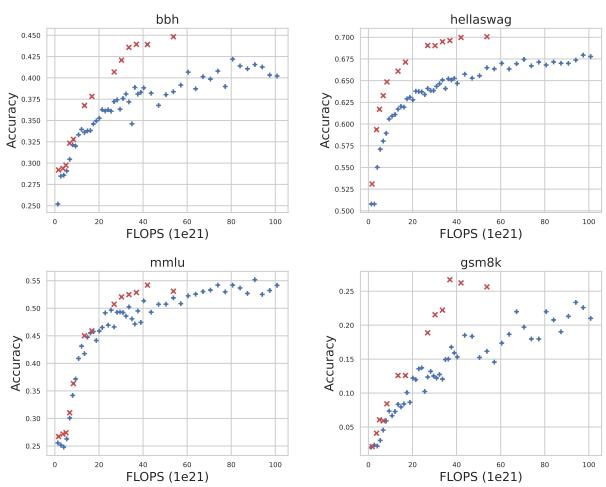
The authors design a downstream scaling-law prediction framework around a token-weighted validation-loss metric rather than raw computation. They first test whether total FLOPs can directly predict downstream accuracy. To this end, they train model series with different mixing ratios over the same pretraining data pool and evaluate checkpoints at varying computational budgets. The resulting plots show that models trained under identical compute can differ substantially on downstream tasks, especially for benchmarks such as BBH and HellaSwag. This indicates that computation alone cannot serve as a stable predictor when pretraining data distributions change. As shown in the figure below:
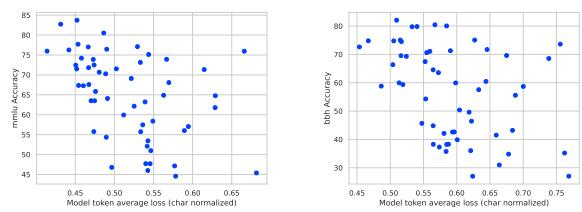
The framework then tests a second candidate signal: average validation token loss. To reduce tokenizer-induced distortion, the authors normalize loss at the character level before aggregating results across models. Even with this normalization, models with similar average token loss can still achieve different downstream accuracies, revealing that uniform averaging collapses information about which tokens are most informative for a given capability. The figure below:
The main method introduces a Capability Salience Vector (CSV), which assigns learned weights to token-level validation losses. The intuition is that different token fragments test different meta-capabilities, so some tokens should contribute more to the prediction of a target downstream task. Given a validation set
S={Xs}s=1∣S∣and a sample Xs=(x1,x2,…,x∣Xs∣), the capability score of model m is computed as
Cm=−Nc1s=1∑∣S∣i=1∑∣Xs∣ws,ilogp(xi∣x<i),where ws,i is the salience weight for token xi in sample Xs, and Nc denotes the number of validation-text characters. This capability score replaces the standard uniform average loss with a weighted summary of validation difficulty.
To map this capability score to downstream performance, the authors use a sigmoidal function:
At,m=γ+1+exp(−α(Cm−β))1−γ,where At,m is the predicted accuracy for task t and model m, α and β are fitted parameters, and γ represents the expected accuracy under random guessing. This formulation allows the model to capture nonlinear relationships between validation difficulty and downstream success, including threshold-like behavior.
The optimization of the Capability Salience Vector is organized as a three-stage procedure. First, the authors extract token weights using a language model with an attached scoring head. Before weight assignment, token losses are aligned across different vocabulary spaces by averaging token-level losses over corresponding characters to obtain character-level losses, then aggregating those losses according to the target tokenizer. The scoring head, implemented as a linear layer on the final hidden states, produces
ws,i=fθ(xs,i∣xs,<i),where θ contains the scoring-head parameters. During this stage, the rest of the language model parameters remain frozen, so the model focuses on learning which tokens carry the most capability-related signal.
Second, with the scoring-head parameters fixed, the authors collect token losses and observed downstream accuracies from multiple models and fit the downstream scaling-law function by estimating α and β. They minimize the squared error between predicted and observed performance using the Levenberg-Marquardt algorithm:
α,βminm∑(At,m−A^t,m)2.Third, the fitted downstream scaling-law function is used as a learning signal to optimize the salience vector. The authors minimize the same prediction error with respect to θ using stochastic gradient descent:
θminm∑(At,m−A^t,m)2.These three stages are iterated multiple times. The overall workflow therefore learns a validation loss representation that is both tokenizer-normalized and capability-aware, and then uses that representation to predict downstream task performance under a fitted nonlinear law.
Experiment
Experiments evaluated whether downstream scaling laws can be predicted from computational cost or validation loss across models trained with different pretraining data distributions. The results show that computational cost alone and uniformly weighted validation loss are insufficient, while a Capability Salience Vector that assigns token-level importance weights better aligns model capability with downstream performance. Validated on diverse open-source and self-trained models across benchmarks, the approach predicts downstream capabilities across model families and data distributions, with more diverse validation samples yielding more accurate predictions.
Across most evaluated tasks, the Capability Salience Vector produces lower downstream-performance prediction MSE than both all-token loss and label-token loss, indicating more reliable prediction. Label-token loss consistently has the largest errors, while all-token loss is sometimes competitive but less robust across benchmarks. These results support using weighted token losses as a practical proxy for tracking model capabilities. Capability Salience Vector generally yields lower prediction error than all-token and label-token losses. Label-token loss is the weakest proxy across the reported benchmarks. All-token loss can be close on some tasks but is less consistently predictive than the weighted approach.
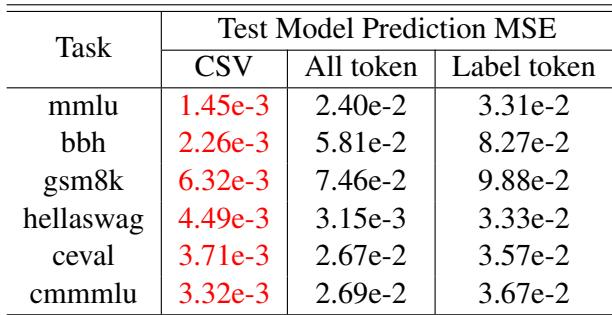
The experiments compare Capability Salience Vector with all-token and label-token losses as proxies for predicting downstream model performance. The results indicate that Capability Salience Vector is generally more reliable and produces lower prediction error, while label-token loss is consistently the weakest proxy. All-token loss can perform well on some tasks but is less robust overall, supporting the use of weighted token losses as a practical capability-tracking signal.