Command Palette
Search for a command to run...
Weight-Space-Programmierung braucht keine Transformer
Weight-Space-Programmierung braucht keine Transformer
Hyunjong Ok Jaeho Lee
Zusammenfassung
Standardarchitekturen neuronaler Netze wie der Transformer wurden gewählt, weil sie mit Gradientenabstieg gut trainieren und auf GPUs schnell ausgeführt werden können. Bei der Weight-Space-Programmierung schreibt ein großes Sprachmodell (LLM) Zielgewichte von Hand, ohne gradientenbasiertes Training, sodass diese Gründe nicht mehr gelten. Sollten wir den Transformer beibehalten? Mit minimaler Anleitung, zehn beschrifteten Beispielen und einer Sandbox, hauptsächlich bei Multiple-Choice-Fragen, beauftragen wir drei führende LLMs damit, entweder die Gewichte einer festen Architektur zu erzeugen oder die Architektur selbst zu entwerfen. Wenn sie frei entwerfen dürfen, kompilieren alle drei Klartext-Fakten in eine dünn besetzte Tabelle, die von einer festen Prozedur abgefragt wird, und erreichen bis zu 54,4 % Testgenauigkeit. Ein von einem LLM entworfenes Modell erzielt eine höhere Testgenauigkeit als der genaueste veröffentlichte Transformer, den dasselbe LLM geschrieben hat, und verwendet dabei etwa 1.800 Parameter weniger. Ohne Gradienten wählen sie eine Tabelle, in der das LLM angeben kann, was jedes Gewicht bedeutet, und ein falsches finden und neu schreiben kann. Jede falsche Antwort verweist auf eine Zeile, und das Entfernen einer Zeile ändert etwa eine andere Antwort. Daraus schlagen wir ein auf assoziativem Speicher basierendes Modell vor, das auf GPUs bis zu 17-mal schneller ist als ein gleich großer Transformer. Wir testen außerdem vortrainierte Gewichte, andere Benchmarks und Aufgaben, bei denen Modelle Antworten generieren. Vortrainierte LLMs bleiben genauer; die Behauptung betrifft die Frage, welche Struktur beim Schreiben von Gewichten aufgebaut werden soll.
One-sentence Summary
Researchers at Pohang University of Science and Technology (POSTECH) show that in weight-space programming without gradients, frontier LLMs favor sparse associative-memory tables over Transformers, with an LLM-designed model reaching up to 54.4% test accuracy and using about 1,800 fewer parameters than the most accurate released Transformer it wrote, while a proposed associative-memory model runs up to 17 times faster on GPUs than a same-sized Transformer.
Key Contributions
- Frontier LLMs allowed to design models without gradient training converge on sparse tables queried by a fixed procedure, reaching up to 54.4% test accuracy; an LLM-designed table outperforms the most accurate released Transformer written by the same LLM while using about 1,800 fewer parameters.
- The observed table structure motivates an associative-memory-based model that runs up to 17 times faster on GPUs than a same-sized Transformer, with row-wise interpretability where each wrong answer points to one row and removing a row changes about one other answer.
- Additional evaluations with pretrained weights, other benchmarks, answer-generation tasks, and low-label warm-starting show that a written network initialized with 100 labeled AG News articles reaches up to 84.7% accuracy versus 63.6% from random initialization, while pretrained LLMs remain more accurate overall.
Introduction
The authors study weight-space programming (WSP), where a large language model writes the weights of a separate model directly, without gradient-based training or data fitting. This matters because Transformers are highly effective for gradient optimization on GPUs, but that advantage may not transfer when weights must be written explicitly. Prior work on writing or compiling weights typically fixes a target architecture and asks what can be written into it, leaving open whether the Transformer is the right structure for WSP. The authors let frontier LLMs either write weights for released architectures or design a target architecture from scratch. They find that LLMs consistently avoid Transformers and instead build sparse table lookup models that store facts as rows and score answers through fixed retrieval. The authors analyze why this design is easier to write without gradients, and they introduce an associative-memory-based variant that reads only a fixed number of rows per question, retaining accuracy while improving GPU inference speed.
Method
The authors investigate Weight-Space Programming (WSP), a paradigm where Large Language Models (LLMs) write model weights directly without gradient descent. In this setup, the LLM operates in a loop: it creates practice questions, runs the model, inspects failures, and adds rules or fact rows. This process requires traceable answers and local edits, properties naturally satisfied by sparse structures rather than dense neural networks.
When allowed to design architectures from scratch, the LLMs converge on a specific design: a sparse fact table queried by a fixed procedure. This model maps words into concepts and matches the question and each candidate option against a sparse fact table. It retains the top-matching rows per option, runs a second pass expanded with concepts from the top facts, and applies rules for negation and word order.
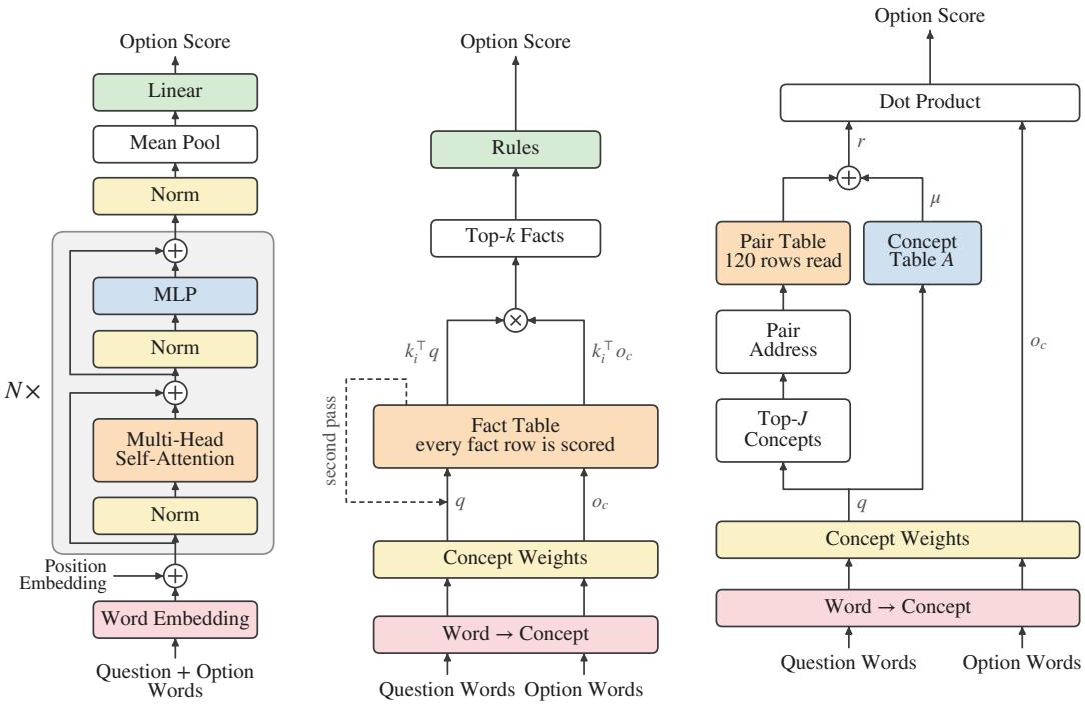
As shown in the figure above, the authors compare a standard two-layer Transformer, the LLM-designed model, and their proposed associative-memory-based model. While the Transformer relies on dense matrices in its attention and MLP stacks, the LLM-designed model utilizes sparse concept vectors. The authors frame this through the lens of associative memory. A Transformer recalls values vi whose keys ki resemble a query x via:
f(x)=i=1∑Mviσ(ki⊤x)where σ is a selection function like softmax. In contrast, the LLM-designed model instantiates this memory with sparser choices. Each memory i is a written fact with a sparse concept vector ki serving as both key and value. The score for an option c is computed by matching the option concepts oc against the best-supported fact:
sc=imax(ki⊤q)(ki⊤oc)where q is the question's concept vector.
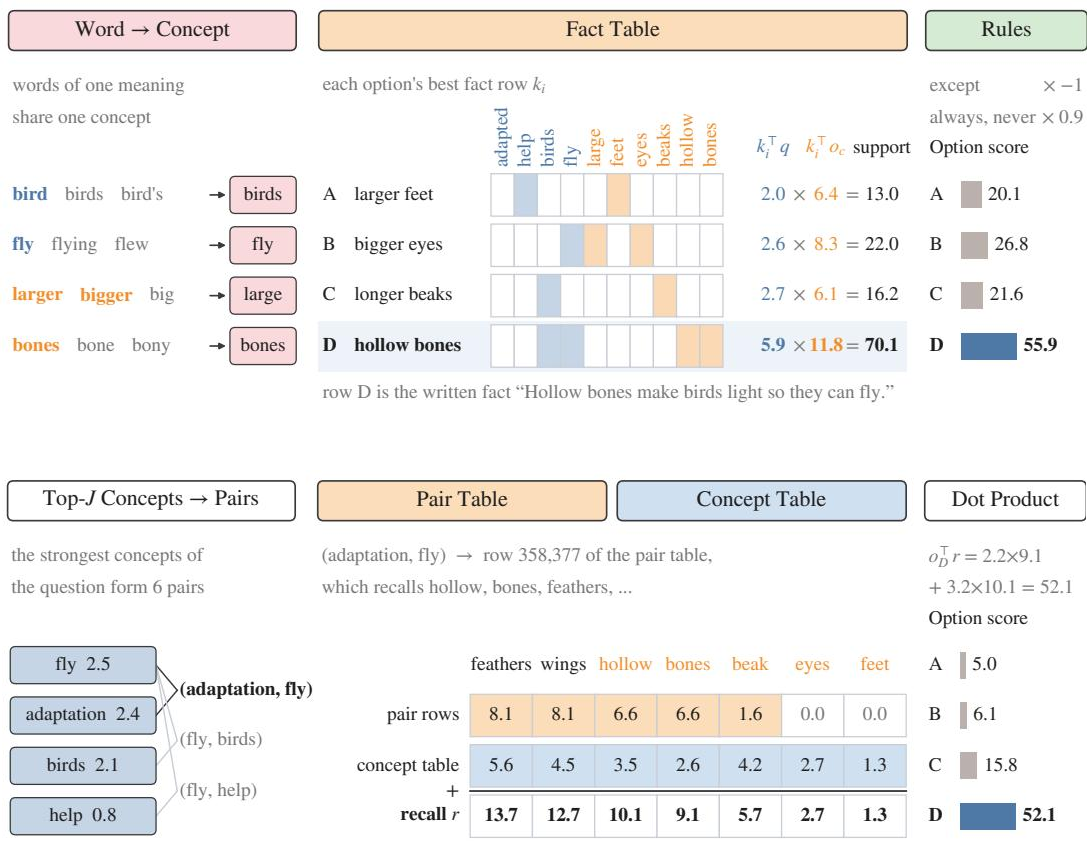
The figure above illustrates this process with an example question. In the LLM-designed model, the answer traces directly to specific written facts, such as "Hollow bones make birds light so they can fly," which yields a high support score. However, this design scores every stored fact for every question, causing inference time to grow with the number of facts and launching many GPU kernels.
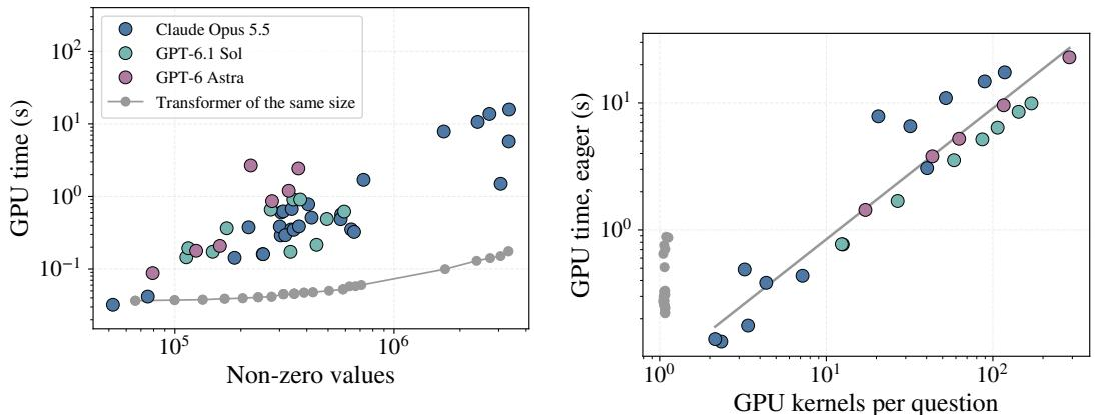
As demonstrated in the figure above, most LLM-designed models run slower on a GPU than a same-sized Transformer due to the high number of kernel launches per question. To address this, the authors propose an associative-memory-based model that preserves line-by-line writing while fixing the forward pass to read only a fixed number of rows per question.
This model compiles written lines into two tables: a Concept Table A (first-order memory) and a Pair Table (second-order memory). The Pair Table stores concepts recalled by a pair of concepts (a,b), mapping directly to a row address h(a,b)=(ap+b)(modH) for a fixed prime p and table height H. From the question's concept vector q, the J=16 strongest concepts form a set of 120 pairs. The recall vector r and option score sc are computed as:
r=(a,b)∈P(q)∑qaqbth(a,b)+μA⊤q,sc=oc⊤rwhere th is the row of the pair table and μ is a mixing weight. This design keeps the per-question cost independent of the fact count, allowing the model to answer significantly faster than a same-sized Transformer while maintaining high accuracy.
Experiment
The experiments evaluate weight-space programming on 3,530 ARC multiple-choice science questions, where three frontier LLMs write models under either fixed architectures or LLM-designed structures, with lineage refinement in some runs. Across all three LLMs, LLM-designed models outperform fixed architectures and gradient descent from random initialization, and they rely on interpretable key-value lookup or associative-memory tables whose predictions trace mainly to single facts and whose edits remain local. Further tests show these written models transfer to similar science questions, text generation, classification, and multi-task settings, while associative-memory designs improve GPU efficiency and pretrained checkpoints are usually edited lightly or overwritten only when near chance. Pretrained fine-tuning still remains far more accurate, and LLM-designed models are generally slower than same-sized Transformers.
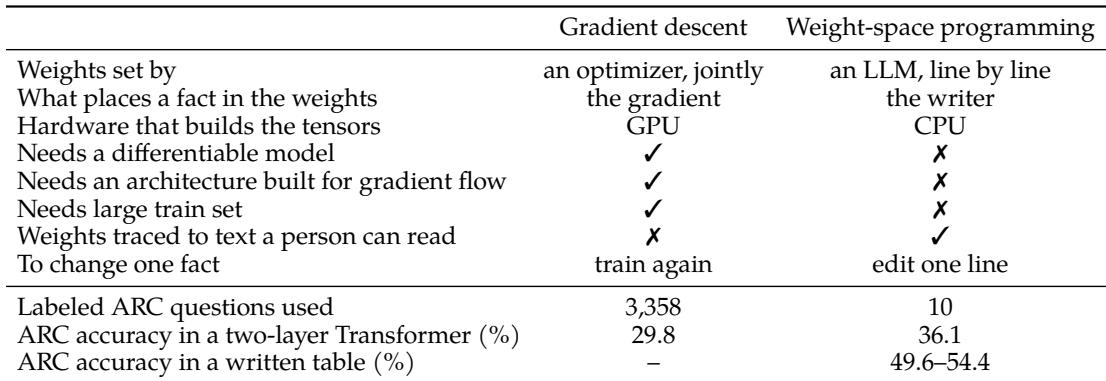
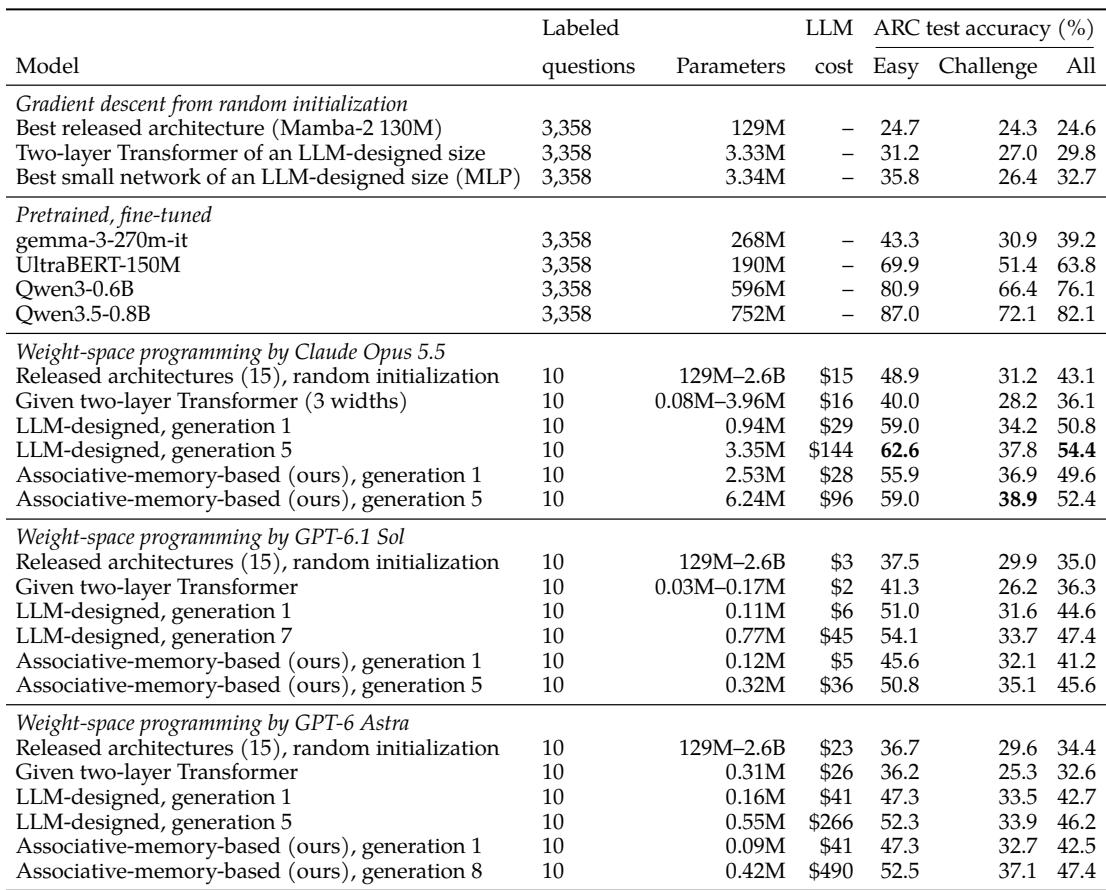
Gradient descent sets weights jointly with an optimizer on a GPU, requiring a differentiable model, an architecture built for gradient flow, and a large training set, while weight-space programming writes weights line by line on a CPU using an LLM and none of those requirements. The written weights are traceable to readable text, and the reported LLM-written ARC accuracies are around 50 to 54 percent across generations and designs. Results on other tasks show similar mid-range performance on SciQ, near chance on raw-pixel CIFAR-10, and stronger performance when meaningful semantic token features are available. Weight-space programming removes the need for differentiability, gradient-flow architectures, and large training sets, and it makes weights traceable to human-readable text. LLM-written models reach ARC accuracy around 50 to 54 percent and stay near chance on raw-pixel CIFAR-10, but improve sharply when using semantic token features.
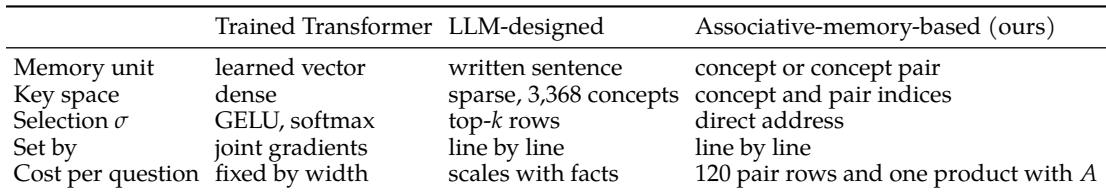
The comparison frames trained Transformers, LLM-designed models, and the associative-memory-based model as different instantiations of the same associative memory equation. They differ mainly in memory unit, key space, selection mechanism, how memory is set, and per-question cost. The written models use sparser and more interpretable memory units than the dense learned vectors of a trained Transformer. The trained Transformer uses dense learned vectors and smooth selection, with per-question cost fixed by model width. The LLM-designed model uses written sentences as sparse memories with top-k row selection, while the associative-memory-based model uses concept and pair indices with direct addressing.
On ARC, letting the LLM design the model in weight space yields better accuracy than writing a fixed Transformer or released architecture, while using far fewer parameters. The associative-memory-based model also outperforms fixed architectures, and iterative refinement improves accuracy further. Pretrained fine-tuned models remain substantially more accurate, leaving a wide gap for weight-space programming. LLM-designed models achieve higher ARC accuracy than fixed architectures written from random initialization, despite having far fewer parameters. Gradient descent from random initialization leaves released architectures near random guessing, while pretrained fine-tuned models remain far ahead.
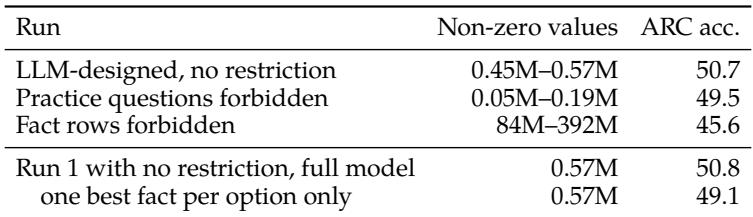
Forbidding practice questions costs only about one point of ARC accuracy, so the models are not relying heavily on self-written test-like questions. Forbidding fact rows costs about five points and forces over 100 times more non-zero values, showing the row-table structure is more important. Scoring each option from its single best-matching fact nearly reproduces full accuracy, indicating answers trace mainly to one stored fact. Practice questions forbidden: accuracy drops only about one point. Fact rows forbidden: accuracy drops about five points while non-zero values increase by over 100 times. Using only the single best-matching fact per option nearly matches the full model.
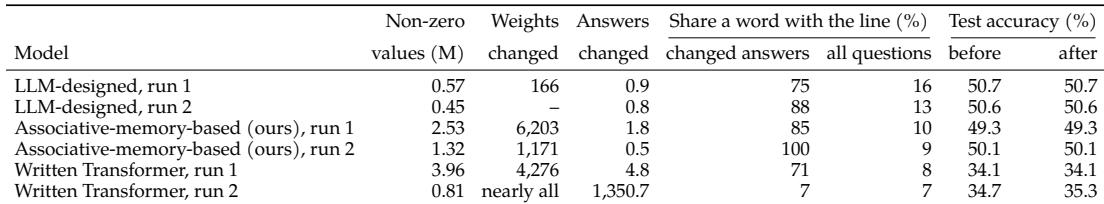
Removing one written line causes only small, localized answer changes in the table-style models, averaging roughly 0.5 to 1.8 changed answers across the LLM-designed and associative-memory-based runs. Written Transformer runs are more sensitive, with one run changing several times more answers and another changing nearly all weights and a large share of answers because its vector codes draw from one random stream. Test accuracy remains largely stable after line removal, and changed answers in the table-style models tend to share wording with the removed line. LLM-designed and associative-memory-based table models remain relatively stable after a line is removed, with only about 0.5 to 1.8 answers changing on average. Written Transformer runs show much larger disruption, including one run where a removed line changes nearly all weights and a large fraction of answers. In table-style models, most changed answers share a word with the removed line, while written Transformer changed answers share wording less consistently. Overall test accuracy before and after line removal stays essentially unchanged across most runs.
The paper evaluates weight-space programming, where an LLM writes model weights directly, against gradient-trained and fixed architectures on ARC and auxiliary tasks. LLM-written and associative-memory table models reach mid-range ARC accuracy with far fewer parameters and interpretable sparse memories, while raw-pixel CIFAR-10 stays near chance unless semantic token features are available. Ablations show performance depends primarily on stored fact rows rather than practice questions or multi-fact scoring, and removing individual lines causes only small localized answer changes in table models, unlike more brittle written Transformers. Pretrained fine-tuned models remain substantially ahead, leaving a wide gap for weight-space programming.