Command Palette
Search for a command to run...
Tree-Ising: Reparatur von Sprachmodellen durch Ising-Edits auf Bitebene
Tree-Ising: Reparatur von Sprachmodellen durch Ising-Edits auf Bitebene
Hadi Salloum Ammar Ali
Zusammenfassung
Das in jüngeren MIT-Arbeiten von Takehi et al. eingeführte Weight-Space Programming ermöglicht es einem Frontier-LLM-Agenten, die Gewichte eines Netzwerks zu lesen und eine Reparatur zu schreiben. Ihr GPT-6-Astra-Agent korrigierte die Reasoning-Schleifen von Qwen3.5-0.8B ohne Gradienten und benötigte dafür 158 Agenten-Turns, 89,7 Millionen Token und 50 Forward-Pass-Anfragen. Unsere Methode TREE-ISING formuliert diese Reparatur als spärliches diskretes Optimierungsproblem über den nativen BF16-Gewichten des Modells. Wir nutzen Vorwärtsstatistiken, um eine Zielfunktion zu definieren, die eine Schleifenrichtung abschwächt, eine Abschlussrichtung stärkt und die Ausgabe der Schicht bei produktiven Token erhält. Innerhalb einer Zustandsbaum-Repräsentation, in der die verlustfreie BF16-Speicherung einen Spezialfall darstellt, bestehen die zulässigen Edits aus Vorzeichenwechseln und Exponentenverschiebungen, die alle gemeinsam genutzten Gruppenexponenten und Mantissen erhalten. Wir zerlegen diese Zielfunktion exakt in unabhängige QUBO-Probleme (Ising-Probleme), eines pro Ausgabezeile, die wir auf einer GPU mittels simulierter Abkühlung (Simulated Annealing) oder der quanteninspirierten Simulated-Bifurcation-Methode lösen. Ausgewertet auf den beiden vom Agenten adressierten Schichten erreicht TREE-ISING 54,6 % auf MATH-500 und übertrifft damit den Edit des Agenten (51,7 %) unter demselben Evaluierungsprotokoll, während das Basismodell nur 7,9 % erzielt. Darüber hinaus liefert der Simulated-Bifurcation-Solver eine statistisch nicht unterscheidbare Reparatur mit 55,1 %. Entscheidend ist, dass beide Solver den Agenten-Edit über alle fünf Mathematik-Benchmarks hinweg übertreffen, mit statistisch signifikanten Verbesserungen bei MATH-500 und GSM8K nach Korrektur für multiple Vergleiche. Zudem modifiziert unser Ansatz 13 % bis 17 % weniger Gewichte und reduziert die BF16-Bitflips um den Faktor 2,2 bis 2,3. Er benötigt nur vier Forward-Pass-Anfragen und keine LLM-Token; das Annealing-Rezept verursacht etwa 0,90 US-Dollar an GPU-Zeit. Bei der Übertragung auf Qwen3.5-2B, wobei Schichten und Dosis ausschließlich anhand des Basismodells ausgewählt werden, erhöht dasselbe Rezept die Greedy-Genauigkeit auf GSM8K von 21,6 % auf 69,4 %. Schließlich führen wir als Machbarkeitsnachweis ein Reparatur-Teilproblem mit acht Variablen mittels QAOA auf einem IBM-Heron-Prozessor aus.
One-sentence Summary
Researchers from QDeep, LEAD, and ITMO University propose TREE-ISING, which repairs language models by casting sparse discrete BF16 weight edits as row-wise QUBO (Ising) problems solved with simulated annealing or simulated bifurcation, achieving 54.6% on MATH-500 compared with 51.7% for the agent edit under the same evaluation protocol, using 13% to 17% fewer weights and zero LLM tokens, and lifting Qwen3.5-2B greedy GSM8K accuracy from 21.6% to 69.4%.
Key Contributions
- TREE-ISING formulates LLM weight repair as a gradient-free, sparse discrete optimization over the model’s native BF16 weights, using a state-tree representation that restricts admissible edits to sign flips and exponent shifts preserving shared group exponents and mantissas. The forward-statistics objective is decomposed exactly into independent QUBO/Ising problems, one per output row, solved on a GPU via simulated annealing or simulated bifurcation.
- On Qwen3.5-0.8B, TREE-ISING repairs the two layers targeted by the earlier GPT-6 Astra agent edit and reaches 54.6% on MATH-500 with simulated annealing; simulated bifurcation reaches a statistically indistinguishable 55.1%, versus 51.7% for the agent edit and 7.9% for the base model. Across all five math benchmarks, it outperforms the agent edit, modifies 13% to 17% fewer weights, reduces BF16 bit flips by a factor of 2.2 to 2.3, and requires only four forward-pass requests and zero LLM tokens at roughly $0.90 per run.
- The same recipe is extended to Qwen3.5-2B, where selecting target layers and dose from the base model alone raises greedy GSM8K accuracy from 21.6% to 69.4%. A proof-of-concept QAOA experiment on an IBM Heron processor executes an eight-variable repair-derived Ising subproblem, indicating preliminary feasibility on quantum hardware.
Introduction
Weight-space programming has recently shown that a frontier LLM agent can directly edit another model’s weights to fix a common failure in small reasoning models: looping behavior that exhausts the token budget and sharply limits accuracy on benchmarks such as MATH-500. This matters because such failures are frequent in long reasoning traces, but the prior agent-based repair is expensive, heuristic, and provides no guarantee that the chosen edit is optimal. The authors formalize the repair as sparse discrete optimization over stored BF16 weights, representing the network with state trees and decomposing the problem into independent row-wise Ising models. Their method, TREE-ISING, uses forward statistics to select layers and define an objective, then solves the resulting Ising problems with GPU annealers or quantum-inspired solvers, producing a more accurate and substantially cheaper repair than the agent baseline.
Method
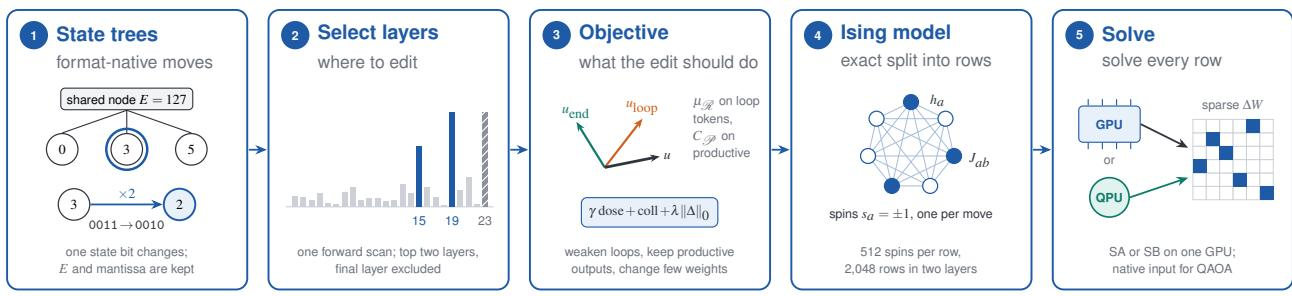
The authors propose TREE-ISING, a method that edits frozen MLP output projections W∈Rd×n to correct reasoning loops in language models. They cast this weight-space programming task as a discrete optimization problem comprising five key steps.
As shown in the figure below:
Step 1: QUBO-friendly representation of the weights The authors represent the weights using state trees, which unify low-bit compression and exact storage. For lossless BF16 storage, 64 consecutive weights in a row share a maximum exponent E. Each weight stores a 4-bit state D=E−e and a leaf containing its sign and mantissa. Edits are restricted to a set of admissible moves F={−1,2,21,4,−2,−4,−21,41}. These moves preserve the shared exponent and avoid escapes, ensuring that an edit only alters the sign bit and the 4-bit state of a single weight. By preselecting one admissible move per candidate weight, the edit becomes a binary decision, conforming to the Quadratic Unconstrained Binary Optimization (QUBO) format.
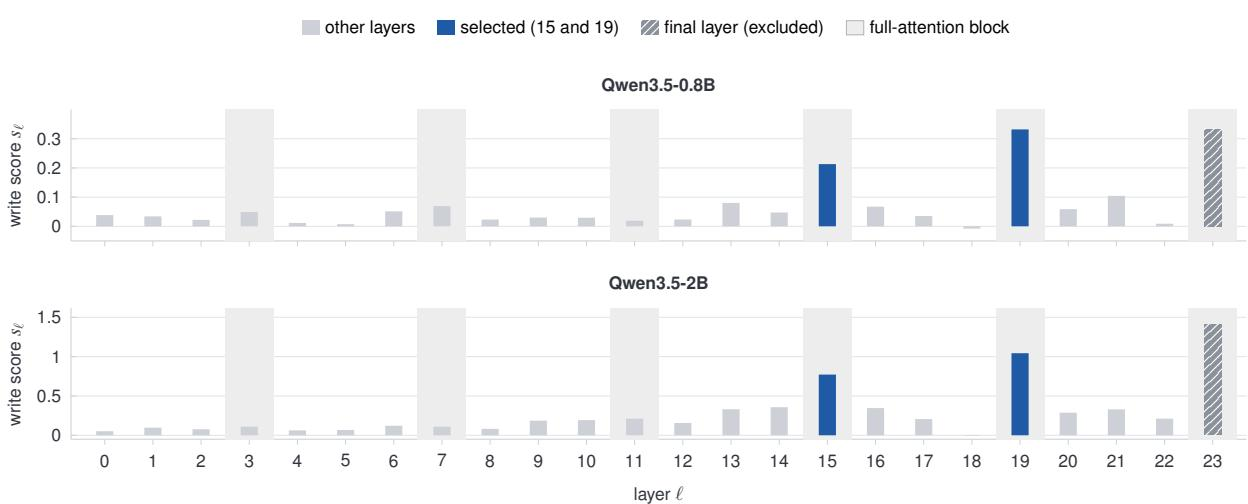
Step 2: Selecting the layers To identify which layers to edit, the authors perform a forward layer scan. The base model generates answers, and teacher-forced passes record the residual stream, MLP output, and output projection input. They compute a target direction uℓ combining a loop direction and an end direction:
uℓ,loop∝hˉℓ,R−hˉℓ,P,uℓ,end∝hˉℓ,Z−hˉℓ,M,uℓ∝uℓ,loop−βuℓ,endwhere β=0.5. The write score of layer ℓ measures how much its MLP pushes the residual stream along uℓ on loop tokens compared to productive ones:
sℓ=uℓ⊤(mˉℓ,R−mˉℓ,P)The selection rule targets the two highest-scoring layers, excluding the final layer.
As illustrated in the figure below:
Step 3: Defining the objective For a given edited layer, the objective minimizes the edit's dose (its effect along u on loop tokens) and collateral (its perturbation on protected tokens), plus a sparsity penalty:
E(Δ)=γdose(Δ)+coll(Δ)+λ∥Δ∥0where dose(Δ)=u⊤ΔμR and coll(Δ)=∑r=1dΔr:CPΔr:⊤. The parameter γ ensures the edit achieves a target dose, while λ restricts the edit to a specific budget of changed weights.
Step 4: Exact decomposition into row Ising models The objective decomposes exactly into independent problems per output row. The authors retain the K columns with the largest scores and preselect the best admissible factor for each. The row problem is formulated as a QUBO:
Er(x)=a=1∑Khaxa+a=b∑Jabxaxbwhere ha aggregates the dose, self-collateral, and sparsity cost, and Jab represents the joint collateral. Substituting spins s=2x−1 transforms this energy into an Ising model.
Step 5: Solving the Ising models The authors solve the row problems using GPU simulated annealing or discrete simulated bifurcation (dSB). Prior to solving, they calibrate the sparsity weight λ and perform a geometric bisection to find the smallest γ that reaches the target dose. The formulation remains solver-agnostic, allowing seamless integration with quantum annealers or QAOA.
Experiment
The experiments evaluate a discrete, low-footprint repair method applied to Qwen3.5 models: for Qwen3.5-0.8B, the recipe targets down_proj matrices in layers 15 and 19 and is compared with an LLM agent edit under a shared math-benchmark harness, showing that the repair improves accuracy and termination across benchmarks while reducing compute cost and weight-level changes. Ablations indicate that the directional objective, especially the concluding-direction term, drives most gains, and the discrete solver matches a continuous rank-one solution with far fewer modified weights. A transfer experiment on Qwen3.5-2B, with layers and dose selected autonomously from base-model statistics, substantially improves greedy GSM8K accuracy and reduces loop-driven truncation, confirming the recipe can operate without a reference edit. A quantum-hardware proof of concept shows a small repair-derived Ising instance can be encoded and sampled on an IBM Heron processor but does not demonstrate quantum advantage, while the stated limitations highlight the narrow failure-mode scope, surrogate-objective heuristics, and partial reliance on prior agent insights for the smaller model.
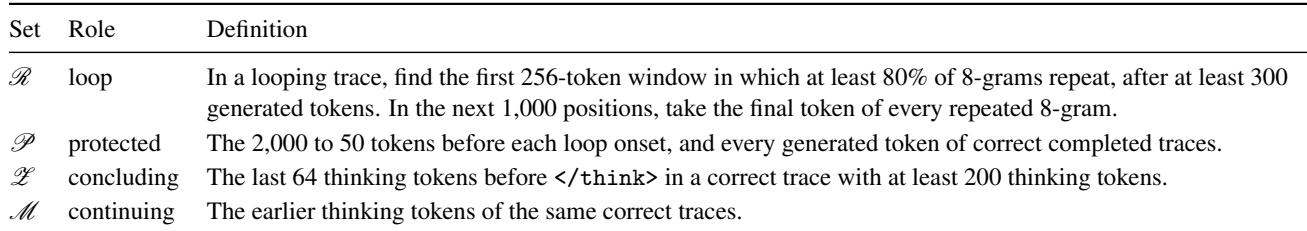
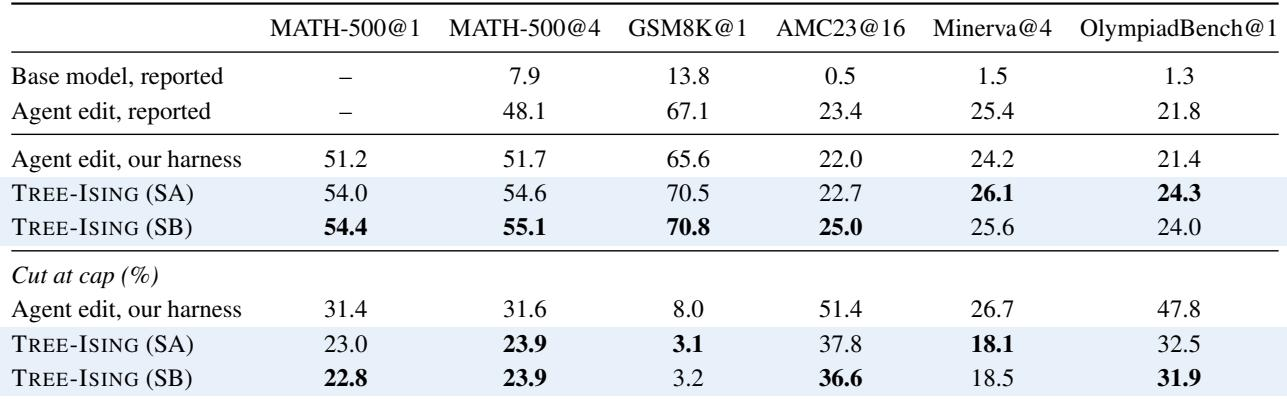
TREE-ISING improves MATH-500 accuracy over the LLM agent edit while reducing the share of answers truncated at the token cap. It also leads on benchmark comparisons and achieves large cost reductions, using no LLM tokens and requiring far fewer forward-pass requests, much less GPU time, and shorter wall-clock time. TREE-ISING attains a statistically significant accuracy gain over the agent edit on MATH-500. It leads on all five benchmarks, with two leads remaining significant after correction. It reduces truncated MATH-500 answers relative to the agent edit and needs no LLM tokens, while using far less compute and wall-clock time.
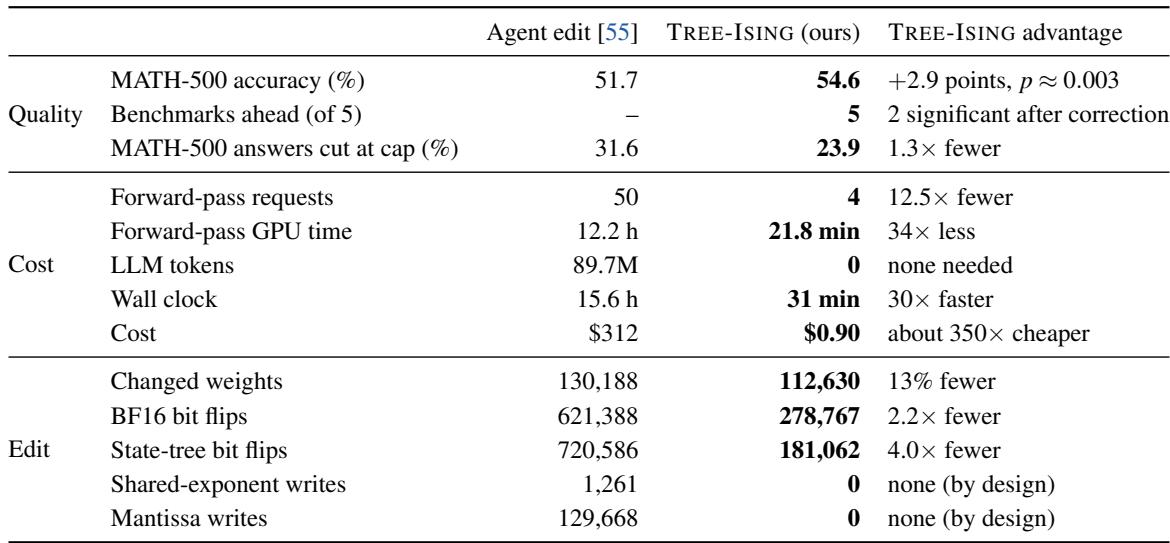
The repair procedure defines four token sets drawn entirely from the base model's own practice answers. A loop set captures positions after repeated 8-grams emerge, while protected, concluding, and continuing sets mark non-loop, completion-related, and earlier reasoning tokens. Contrasting mean residual directions across these sets yields a combined direction that suppresses looping and encourages the model to conclude. Loop tokens are collected only after a repetition onset, whereas protected tokens include pre-onset positions and all generated tokens from correct completed traces. Concluding tokens select the final reasoning positions before a correct end, while continuing tokens cover earlier reasoning positions in the same correct traces.
TREE-ISING edits outperform the agent edit across the evaluated benchmarks on Qwen3.5-0.8B, with the strongest and statistically robust gains on MATH-500 and GSM8K. The improvements are accompanied by lower token-cap cut rates, indicating that the edited model more often finishes reasoning within budget. The results also exceed the originally reported agent scores on four of five benchmark families. TREE-ISING with either solver achieves higher accuracy than the agent edit across all five benchmark families, with statistically significant gains on MATH-500 at four completions and GSM8K after correction. The TREE-ISING edits reach the token cap less often across every benchmark, with cut rates falling sharply on GSM8K and OlympiadBench and driving much of the accuracy improvement.
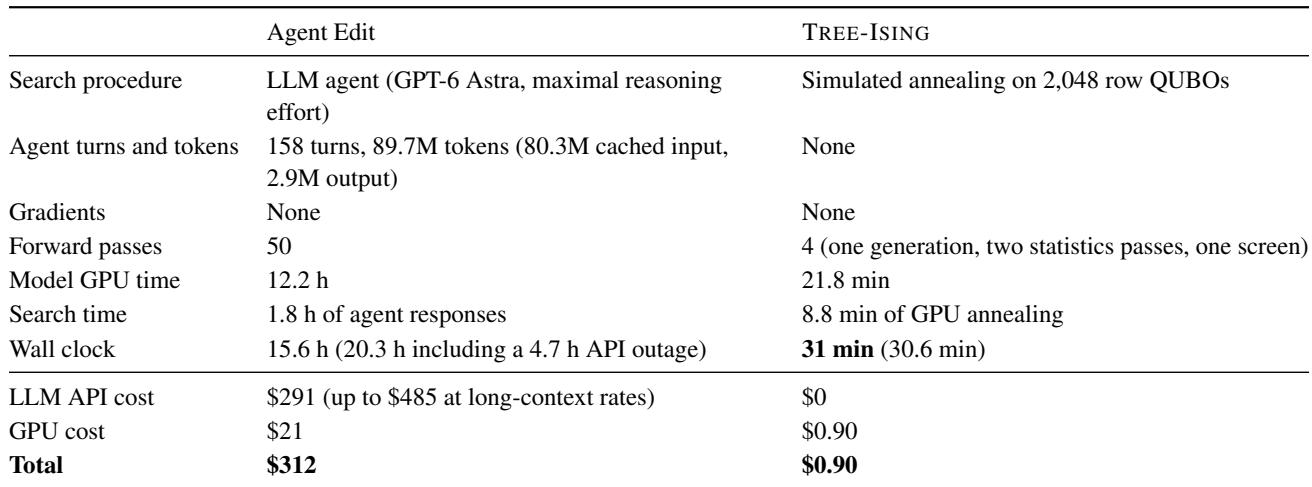
The fixed repair recipe uses far less computation than the agent's exhaustive discovery run, requiring four forward passes and no LLM tokens while the agent uses fifty forward passes and tens of millions of tokens. Forward-pass GPU time drops from over twelve hours to about twenty-two minutes, and overall wall-clock time drops from over fifteen hours to about half an hour. The comparison excludes method development costs and reflects efficient application of a known repair rather than the original discovery process. The fixed recipe reduces forward-pass GPU compute by 34-fold compared to the agent's discovery run. The fixed recipe completes in roughly half an hour of wall-clock time and requires zero LLM tokens, whereas the agent takes over fifteen hours and consumes nearly ninety million tokens.
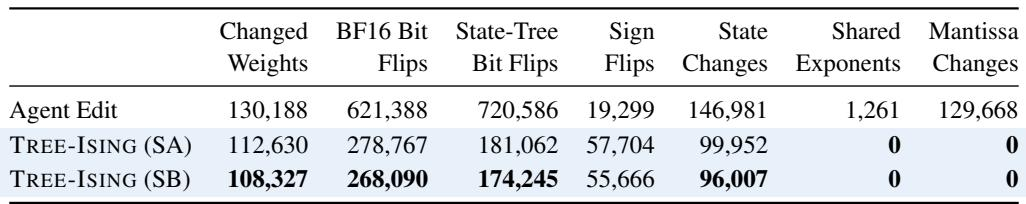
Across both edited matrices, TREE-ISING edits have a smaller structural footprint than the agent edit. They change fewer weights, produce fewer BF16 and state-tree bit flips, and leave shared exponents and mantissas untouched. The stochastic-branch variant is slightly more compact than simulated annealing, while the agent edit performs many mantissa rewrites and shared-exponent shifts. TREE-ISING modifies fewer weights, with the stochastic-branch variant showing the smallest changed-weight count among the three edits. BF16 bit flips are reduced by more than half and state-tree bit flips by about fourfold relative to the agent edit. TREE-ISING makes no shared-exponent or mantissa changes, whereas the agent edit rewrites mantissas for nearly all touched weights and shifts over a thousand shared exponents. Sign flips are substantially more frequent under TREE-ISING, consistent with scaling and sign moves being part of its typical edits.
The experiments evaluate TREE-ISING against an LLM agent edit across several benchmarks, showing improved MATH-500 and GSM8K accuracy, fewer truncated answers, and stronger overall benchmark performance. A repair procedure built from the base model's own correct and looping traces produces a direction that suppresses repetition and encourages completion. The fixed repair recipe is substantially cheaper than the agent discovery run, requiring no LLM tokens and far less GPU and wall-clock time, while the resulting edits have a smaller structural footprint with fewer weight and bit flips and no shared-exponent or mantissa changes.