Command Palette
Search for a command to run...
LONGBANANA: Ein von Experten verifizierter Benchmark für die Bildsynthese mit langem Kontext und mehreren Referenzen
LONGBANANA: Ein von Experten verifizierter Benchmark für die Bildsynthese mit langem Kontext und mehreren Referenzen
Zusammenfassung
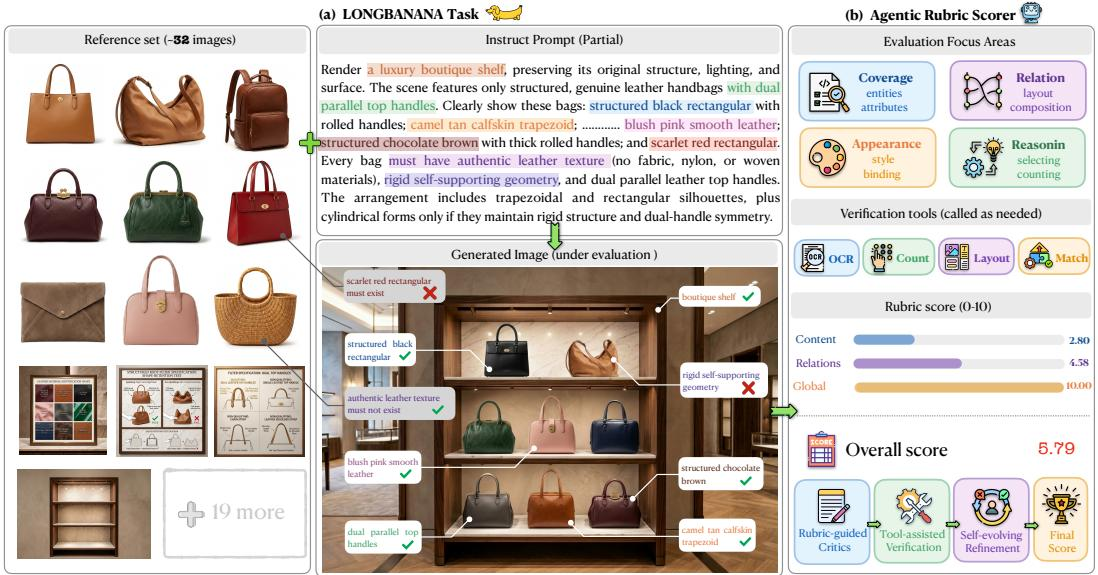
Wir stellen LONGBANANA vor, unseres Wissens der erste von Experten entworfene und verifizierte Benchmark für die Bildsynthese mit langem Kontext und mehreren Referenzen im Zeitalter der agentengesteuerten Bildgenerierung. Die Aufgabe erfordert das Auffinden verteilter visueller Evidenz, das Zurückweisen von Distraktoren, das Binden von Entitäten und Relationen sowie das Komponieren eines kohärenten Endbildes aus mehreren Referenzen. LONGBANANA umfasst 90 sorgfältig gestaltete Aufgaben, die nach einer 3×3-Taxonomie organisiert sind; jede Aufgabe enthält etwa 32 Referenzbilder, 20 Randbedingungen und 50 Bewertungselemente, was insgesamt 4.670 von Experten spezifizierte atomare Bewertungselemente ergibt. Das graphbasierte Evaluationsdesign instanziiert jede Aufgabe mit Referenzbildern und einem Entität-Relation-Graph und überführt Anforderungen auf Knoten-, Kantenund Gesamtgraphenebene in Checklistenelemente für Content Fidelity (Inhaltstreue), Relational Binding (relationale Bindung) und Global Constraint Satisfaction (globale Constraint-Erfüllung). Die überprüften Expertenannotationen umfassen eine zu 15 % doppelt annotierte Teilmenge mit 89,4 % exakter Übereinstimmung und einem quadratisch gewichteten Kappa von 0,83. Darüber hinaus stellen wir LONGBANANA-Gen vor, ein Framework zur Einbindung von Agenten für die Bildgenerierung über lange Horizonte; Experimente zeigen, dass minimale Agenteneinbindungen die direkte Generierung übertreffen, während ein ReAct–Plan–Exec–Reflect-Arbeitsablauf (RPR) durch stärkere Evidenzverankerung und Reparatur einbindungsabhängige Gewinne erzielt. Insgesamt bietet LONGBANANA ein überprüfbares Testfeld zur Messung der Nutzung dichter visueller Evidenz und ein gemeinsames Ziel für die Entwicklung leistungsfähigerer agentengesteuerter Bildgenerierungssysteme. Code und Daten sind auf der Projektseite verfügbar: https://long-banana.com/.
One-sentence Summary
Researchers from South China Normal University, University of British Columbia, and other institutions introduce LONGBANANA, the first expert-designed and expert-verified benchmark for long-context multi-reference image synthesis, comprising 90 tasks organized by a 3-by-3 taxonomy with about 32 reference images, 20 constraints, and 50 evaluation items per task for 4,670 expert-specified atomic evaluation items, using graph-grounded evaluation that converts node, edge, and whole-graph obligations into checklist items for Content Fidelity, Relational Binding, and Global Constraint Satisfaction, with reviewed labels showing 89.4% exact agreement and 0.83 quadratic weighted kappa on a 15% double-labeled subset, and also introduce LONGBANANA-Gen, an agent-harness framework in which minimal agent harnesses improve over direct generation and a ReAct–Plan–Exec–Reflect (RPR) workflow yields harness-dependent gains by strengthening evidence grounding and repair, providing an auditable testbed and shared target for agent-driven image-generation systems, with code and data available at https://long-banana.com/.
Key Contributions
- Introduces LONGBANANA-Bench, the first expert-designed and expert-verified benchmark for long-context multi-reference image synthesis, with 90 tasks across a 3-by-3 taxonomy, about 32 reference images and 20 constraints per task, and 4,670 expert-specified atomic evaluation items.
- Presents LONGBANANA-Eval, a graph-grounded checklist evaluation pipeline that maps entity-relation graphs to atomic checklist items for Content Fidelity, Relational Binding, and Global Constraint Satisfaction, routing items to rubric-guided critics and deterministic tools; it is validated against expert labels with 89.4% exact agreement and 0.83 quadratic weighted kappa on the double-labeled subset.
- Introduces LONGBANANA-Gen, an agent-harness framework for long-horizon image generation, and shows that minimal agent harnesses improve over direct generation while a ReAct-Plan-Exec-Reflect workflow yields harness-dependent gains by strengthening evidence grounding and repair.
Introduction
The authors address long-context, multi-reference image synthesis, where a model must generate an image from evidence spread across many reference images and instructions. This matters because realistic outputs can still be wrong if the model selects the wrong reference, copies appearance from a distractor, binds attributes or relations to the wrong entity, or adds unsupported content. Prior benchmarks cover editing, personalization, prompt following, and some reference-based synthesis, but they under-specify dense evidence use and often rely on holistic scoring rather than localizing provenance errors. To close this gap, the authors introduce LONGBANANA-Bench and LONGBANANA-Eval, modeling each task as an entity-relation graph and scoring atomic checklist items across Content Fidelity, Relational Binding, and Global Constraint Satisfaction.
Dataset
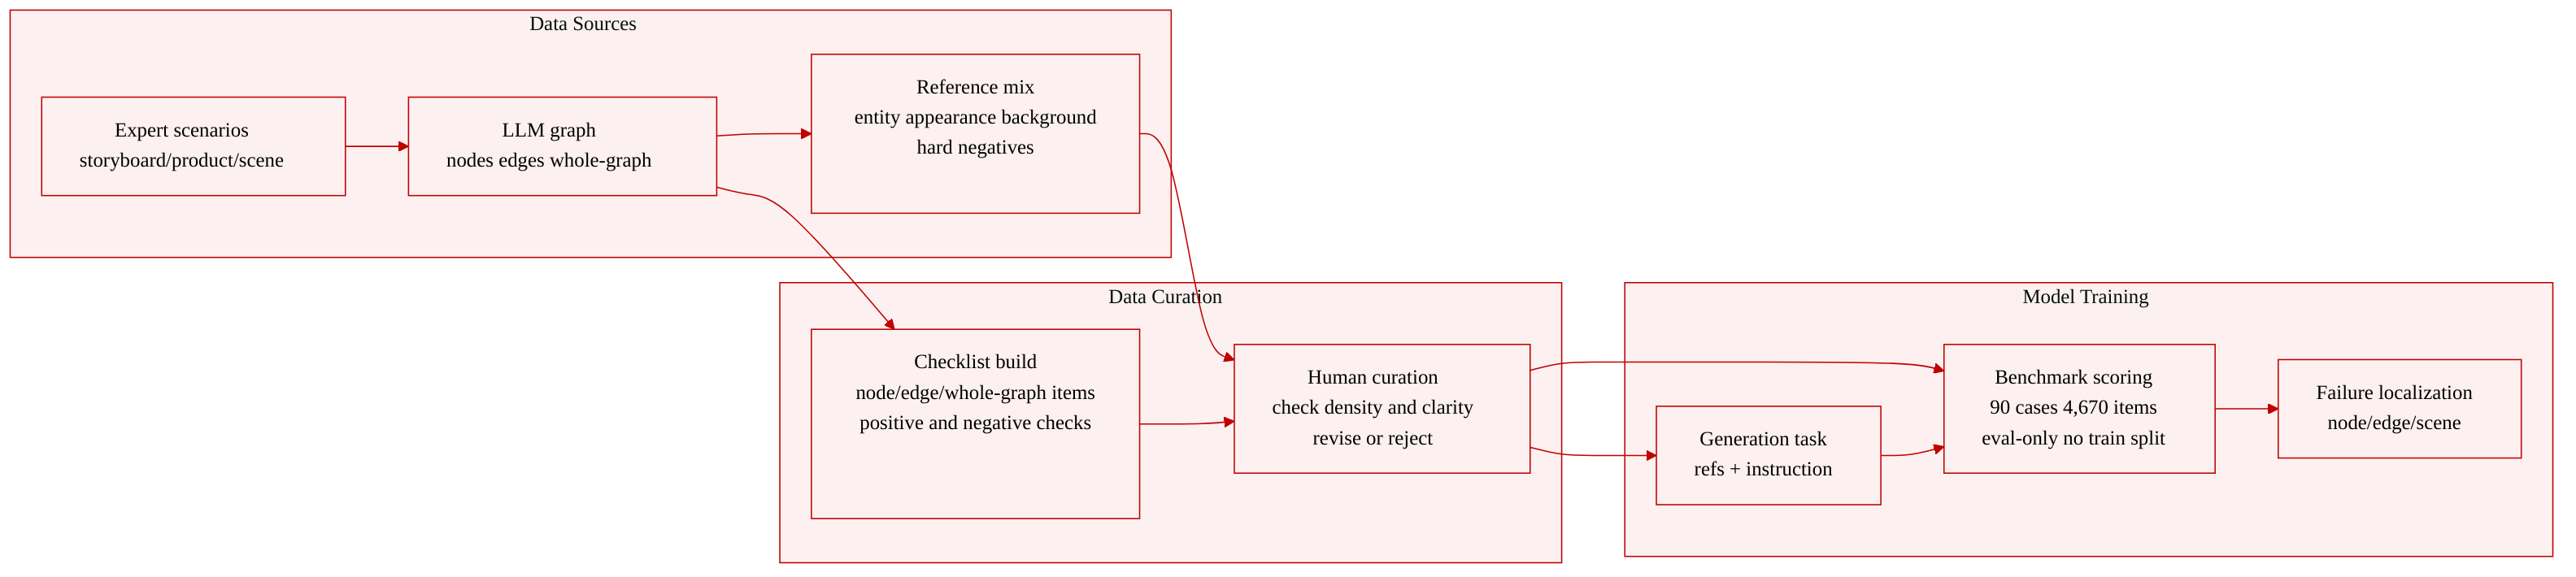
The authors use LONGBANANA as an evaluation benchmark for long-horizon multi-reference image synthesis, not as a training set. A generation system receives a heterogeneous reference set and a structured instruction, then must produce one coherent image that satisfies the case’s entity-relation graph.
Dataset composition and scale
- 90 total cases.
- 10 cases per subclass in a 3 × 3 taxonomy.
- Roughly 32 reference images per typical case.
- More than 20 cross-reference constraints per typical case.
- 4,670 atomic checklist items across the benchmark.
Subsets and task taxonomy
- Scene Composition: tests semantic coverage, relational graph consistency, and layout arrangement.
- Visual Appearance: tests global appearance conditioning, local appearance binding, and appearance harmonization.
- Reference Reasoning: tests selection and retrieval, temporal/state reasoning, and counting/aggregation.
Sources and reference construction
- Expert authors design scenarios based on storyboard, product, and scene-composition use cases.
- An LLM structures each scenario into an entity-relation graph.
- Reference images include entity, appearance, and optional background references.
- At least 30 cases include two or more hard-negative references that are visually plausible but irrelevant to the requested output.
Graph, metadata, and checklist construction
- Graph nodes represent entities and attributes.
- Graph edges encode spatial relations, interactions, and local appearance bindings such as texture, material, color, pose, or state.
- Whole-graph constraints encode composition, layout, counts, and scene-level requirements.
- Checklist items derive from graph constraints at node level, edge level, and whole-graph level.
- Each item records the observable condition, the graph unit being evaluated, relevant reference images, and scoring criteria.
- Positive items check required conditions; negative items check that distractor or unsupported content is absent.
- Human curators review the instruction, references, and checklist together. They reject or revise requirements that cannot be judged, and they check reference density, constraint coverage, and ambiguous or overlapping items.
- The provided text does not report a specific image-cropping strategy.
How the benchmark is used
- LONGBANANA is used to evaluate image generation systems.
- Correctness is measured by the graph-derived checklist rather than by a single holistic quality score.
- Because each checklist item is tied to a graph unit, failures are localized to specific content, relations, or scene-level obligations.
- No training split or mixture ratio is reported, since LONGBANANA is designed as an evaluation benchmark.
Method
The authors construct each case around a shared entity-relation graph that connects the synthesis instruction, reference images, and evaluation checklist. The construction pipeline proceeds from a scenario description to structured constraints, then to visual references and instructions, and finally to the checklist used for evaluation, as shown in the figure below:
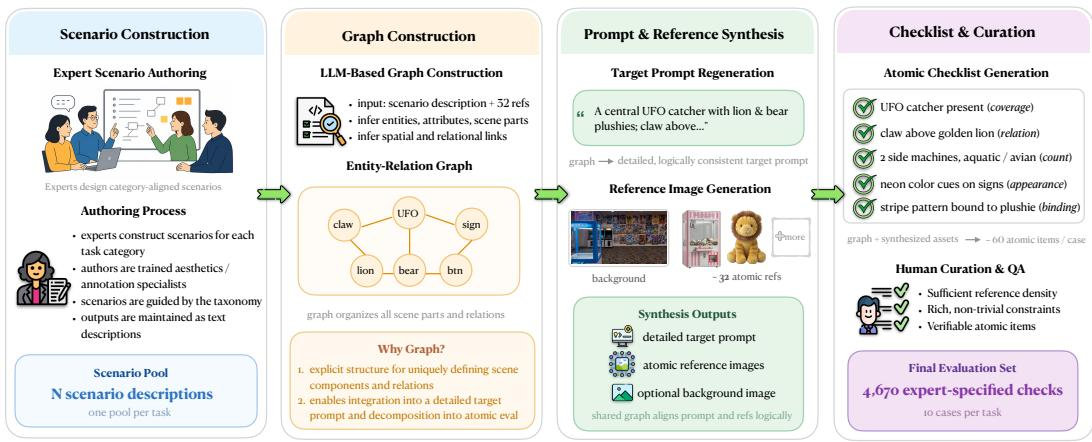
Expert authors first design scenarios aligned with the task taxonomy, specifying what the final image should depict and which entities, visual attributes, and interactions must be preserved. An LLM then structures the scenario into an entity-relation graph. Nodes represent entities and their attributes, edges encode spatial relations, interactions, and local appearance bindings, and whole-graph constraints specify requirements such as composition and counts. This representation makes dependencies explicit, guiding both task synthesis and checklist derivation.
The graph subsequently guides the creation of the target instruction and reference images, including entity, appearance, and optional background references. The instruction expresses the requested composition and relationships, while the references supply visual identities, local details, and appearance cues. Discriminative visual attributes are retained in the references and omitted from text where possible. To assess distractor leakage, at least 30 cases include hard-negative references that are visually plausible but irrelevant to the requested output.
Graph constraints are then translated into atomic checklist items. Node-level items check required entities and attributes, edge-level items check relations and appearance bindings, and whole-graph items check scene-wide requirements like layout and counts. Each item records an observable condition, the graph unit it evaluates, relevant reference images, and scoring criteria. Positive items test whether a required condition is satisfied, while negative items check for the absence of distractor content. Human curators review the instruction, reference images, and checklist together to ensure correspondence to the task graph, visual feasibility, and verifiability before inclusion.
For evaluation, the authors introduce LONGBANANA-Eval, which assesses a generated image against the graph-derived checklist. The agentic checklist judge prepares item-specific reference evidence, routes each check to a dimension-specific critic, and combines the judgments into dimension-level and overall scores, as shown in the figure below:
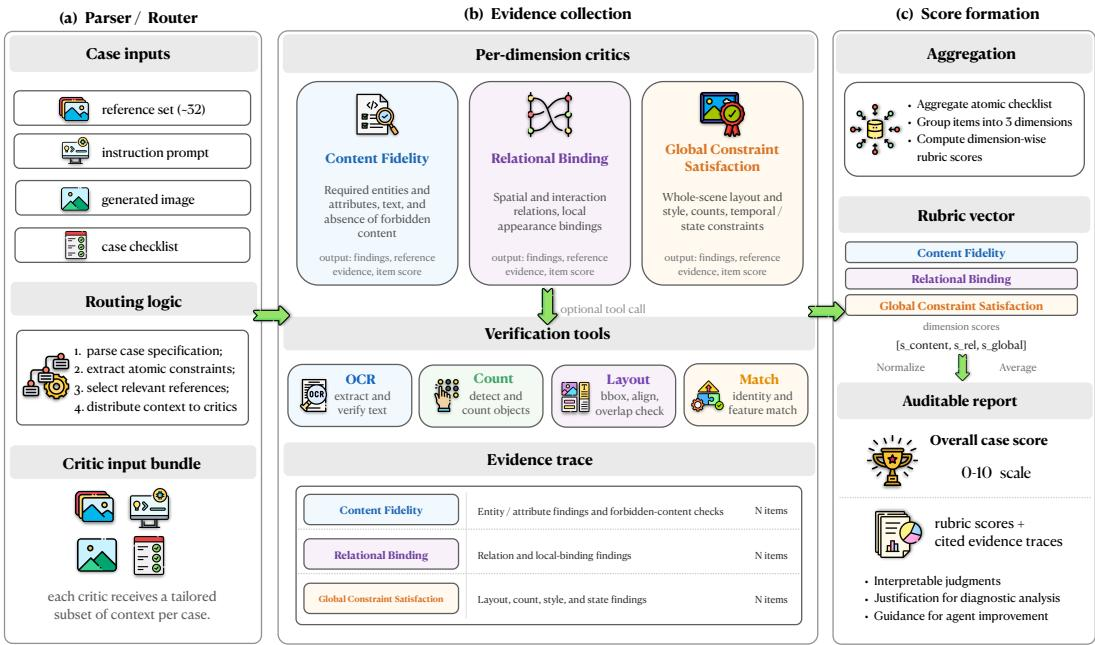
The evaluation pipeline begins with a parser that reads the condition to verify, its rubric dimension, reference identifiers, and scoring criteria. It assembles the generated image and relevant reference images into an evidence packet, with optional crops to localize the region under inspection. Negative-content checks additionally receive identifiers and roles of applicable hard-negative references. A router assigns the packet to the critic corresponding to the item's rubric dimension.
Three dimension-specific critics perform the checks. The Content Fidelity critic checks required entities, attributes, and text, along with the absence of forbidden content. The Relational Binding critic checks spatial and interaction relations and the assignment of local appearance cues. The Global Constraint Satisfaction critic checks scene-wide requirements, including layout, global style, counts, and temporal or state constraints. Each critic compares the output with the item's reference evidence and may invoke verification tools such as OCR for readable text, detection or counting for multiplicity, layout routines for spatial constraints, and identity or feature matching for consistency.
Each check produces a label sj∈{0,1,2}, where 2 indicates a satisfied requirement, 1 indicates partial satisfaction or uncertain evidence, and 0 indicates an unsatisfied requirement. For negative items, complete absence of forbidden content scores 2, ambiguous leakage scores 1, and clear erroneous appearance scores 0. The evidence trace associates the label with relevant references, critic findings, and tool observations.
Finally, the scores are aggregated. For a generated image with N checklist items, the overall score is the mean item label scaled to 0-10. Dimension scores apply the same calculation to the item set Jd assigned to dimension d:
Soverall=N5j=1∑Nsj,Sd=∣Jd∣5j∈Jd∑sj.The dimension scores provide a diagnostic profile, while the overall score summarizes the full checklist.
Experiment
The experiments evaluate long-horizon multi-reference image synthesis using LONGBANANA, a 90-case benchmark with graph-derived checklists, and first validate an agentic checklist judge against reviewed human labels across 900 outputs. The agentic judge tracks expert scores and item-level decisions better than a single-pass VLM judge. Generation results show that a graph-informed direct baseline is competitive, but adaptive agentic workflows produce broader gains, with retrieval, planning, and reflection combined yielding the strongest overall configuration and Nano Banana 2 leading across image backends. The findings suggest that static task structure helps, while inspecting intermediate images and revising evidence use is central to reliable reference-grounded synthesis.
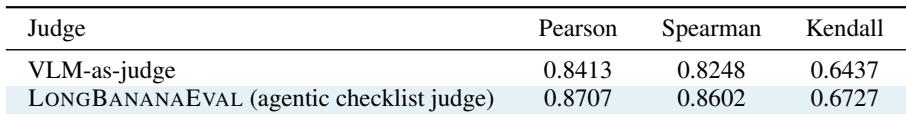
An agentic checklist judge aligns more closely with reviewed human overall scores than a single-pass VLM-as-judge on the fully covered audit pool. It improves all reported output-level correlation measures and also strengthens item-level decisions. These results support its use for machine-scored evaluation and diagnostic reporting. The agentic checklist judge outperforms the single-pass VLM-as-judge across Pearson, Spearman, and Kendall correlations with reviewed human overall scores. Item-level agreement improves as well, with higher exact ternary agreement and fewer opposite-end errors than the baseline judge.
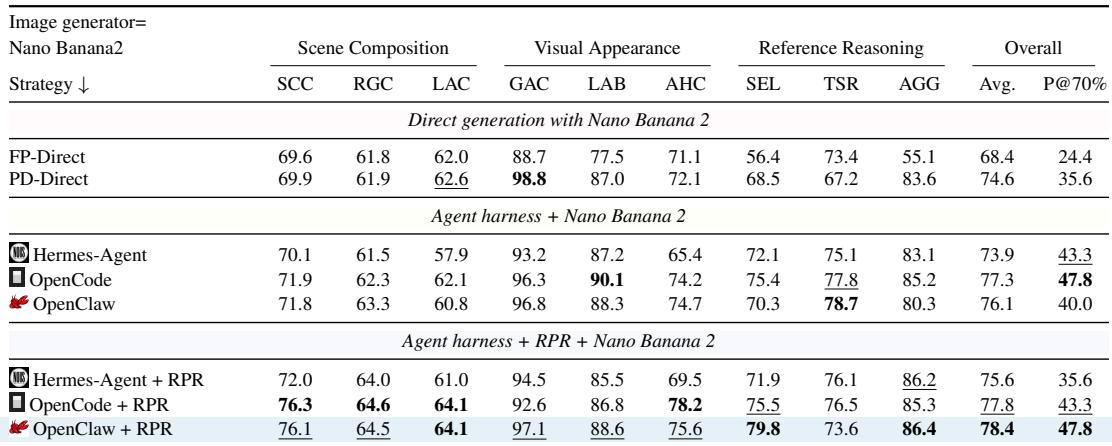
With Nano Banana 2 fixed, PD-Direct is a strong non-agentic baseline that improves on FP-Direct in overall average and most subclasses, recording the best global appearance conditioning and second-best layout arrangement consistency among compared systems. Agentic workflows generally exceed PD-Direct in overall average, and OpenClaw + RPR is stronger on eight of nine subclasses, with the strongest overall average and a joint-best task pass rate. RPR also raises average scores for OpenCode and Hermes-Agent, though their task pass rates decline. PD-Direct substantially improves over FP-Direct in overall average and most subclasses, with the best global appearance conditioning and second-best layout arrangement consistency across compared systems. OpenClaw + RPR surpasses PD-Direct on eight of nine subclasses and leads agentic configurations in overall average and joint-best task pass rate. RPR gives OpenClaw clearest gains in scene composition, reference selection, and aggregation, while the minimal OpenClaw harness remains stronger on temporal and state reasoning. OpenCode and Hermes-Agent improve their average scores with RPR but show lower task pass rates.
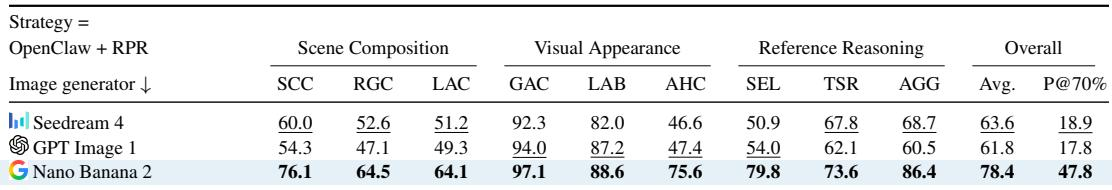
With the OpenClaw + RPR workflow fixed, Nano Banana 2 is the strongest image backend on the LONGBANANA benchmark, achieving the best overall average, task pass rate, and every reported subclass metric. Seedream 4 and GPT Image 1 score substantially lower overall and on task pass rate, and they show different secondary strengths, but neither approaches the leading model's breadth. Nano Banana 2 leads all reported metrics, including scene composition, visual appearance, reference reasoning, overall average, and task pass rate. Seedream 4 and GPT Image 1 perform closer to each other, with GPT Image 1 relatively stronger on global appearance and Seedream 4 relatively stronger on temporal state reasoning and aggregation. The image backend choice creates a large gap in task pass rate, with Nano Banana 2 far ahead of both alternatives under the same workflow.
The experiments evaluate three components of the evaluation and generation pipeline. First, an agentic checklist judge aligns more closely with reviewed human scores than a single-pass VLM-as-judge, improving both output-level correlations and item-level agreement. Second, with the Nano Banana 2 image backend fixed, agentic workflows generally outperform the strong non-agentic PD-Direct baseline, and OpenClaw with RPR achieves the best overall average and task pass rate, while RPR also raises average scores for other agents despite lower task pass rates. Third, with the OpenClaw plus RPR workflow fixed, Nano Banana 2 is the strongest image backend across all metrics, far ahead of Seedream 4 and GPT Image 1, which show different secondary strengths but lower overall performance.