Command Palette
Search for a command to run...
AesCode: Ästhetische Codegenerierung mit entkoppelten modalitätsübergreifenden Belohnungen
AesCode: Ästhetische Codegenerierung mit entkoppelten modalitätsübergreifenden Belohnungen
Zusammenfassung
Die Erzeugung informationsreicher visueller Artefakte wie Folien, Poster und Dashboards als Code ist attraktiv, weil die Ausgaben strukturiert, editierbar und verifizierbar sind. Doch Code-Modelle können nicht sehen, wie ihre Layoutund Farbentscheidungen auf der Leinwand zusammenwirken, was die räumliche Planung und die ästhetische Qualität häufig einschränkt. Bildgeneratoren sind im visuellen Design versiert, können angeforderte Inhalte jedoch fehlerhaft wiedergeben, wodurch ihre Ausgaben als direkte Reproduktionsziele unzuverlässig sind. Daher stellen wir AesCode vor, das Code auf der Grundlage des Inhalts-Prompts erzeugt und dabei ein aus demselben Prompt generiertes Bild als ästhetische Orientierung nutzt. Dazu repräsentiert AesCode das Ziel als Design-Graphen, der die gesamte Leinwand beschreibt und jede Eigenschaft zurechenbar macht. Aus diesem Graphen leiten wir komplementäre modalitätsübergreifende Belohnungen ab: Deterministische Verifizierer bewerten Eigenschaften, die sich aus Code und Rendering parsen lassen, während ein VLM-Judge die nicht parsebaren Eigenschaften anhand einer beispielspezifischen Visual Graph Rubric (VGR) beurteilt, die an Graphelemente und -relationen gebunden ist. Wir optimieren diese entkoppelten Belohnungen durch Reinforcement Learning mit kanalweiser Normalisierung, um gemeinsam räumliche Planung, ästhetische Qualität und verifizierbare Korrektheit zu verbessern. Zur Evaluierung dieses Szenarios erstellen wir einen Benchmark, der verifizierbare Korrektheit und visuelle Qualität getrennt bewertet; die visuellen Bewertungen stimmen stark mit menschlichen Urteilen überein. Wir stellen fest, dass Referenzbilder die visuelle Qualität des von bestehenden Modellen generierten Codes erheblich verbessern, und Ablationsstudien zeigen, dass AesCode von Referenzen sowohl als Modelleingabe als auch als Quelle visueller Belohnungen profitiert. Im Vergleich zu gleich großen Qwen3-VL-Baselines mit denselben Referenzen verbessern AesCode-8B und AesCode-32B die visuelle Qualität um 31,1 bzw. 22,4 Prozentpunkte und erreichen Werte, die mit denen proprietärer Frontier-Modelle wie GPT-5.5 und Claude Opus 4.8 vergleichbar sind.
One-sentence Summary
Researchers from Microsoft, Yale University, et al. introduce AesCode, a code generation model for visual artifacts that uses a same-prompt image as aesthetic guidance, derives decoupled cross-modal rewards from a design graph, optimizes them via reinforcement learning with per-channel normalization, and improves visual quality and verifiable correctness by up to 31.1 percentage points over Qwen3-VL baselines while rivaling frontier models.
Key Contributions
- AesCode generates code grounded in the content prompt while using a prompt-generated reference image as aesthetic guidance, representing the target as a design graph that describes the whole canvas and makes each property attributable.
- From this graph, AesCode derives complementary cross-modal rewards. Deterministic verifiers score properties parsable from code and rendering, while a VLM judge evaluates non-parsable aesthetic properties with a sample-specific Visual Graph Rubric tied to graph elements and relations; these decoupled rewards are optimized through reinforcement learning with per-channel normalization.
- The paper introduces an infographic benchmark that separately scores verifiable correctness and visual quality with human-aligned visual judgments. Reference images substantially improve visual quality across existing models, ablations show that AesCode benefits from references both as model input and as a source of visual rewards, and AesCode-8B and AesCode-32B improve visual quality by 31.1 and 22.4 percentage points over same-scale Qwen3-VL baselines given the same references, reaching scores comparable to frontier closed-source models such as GPT-5.5 and Claude Opus 4.8.
Introduction
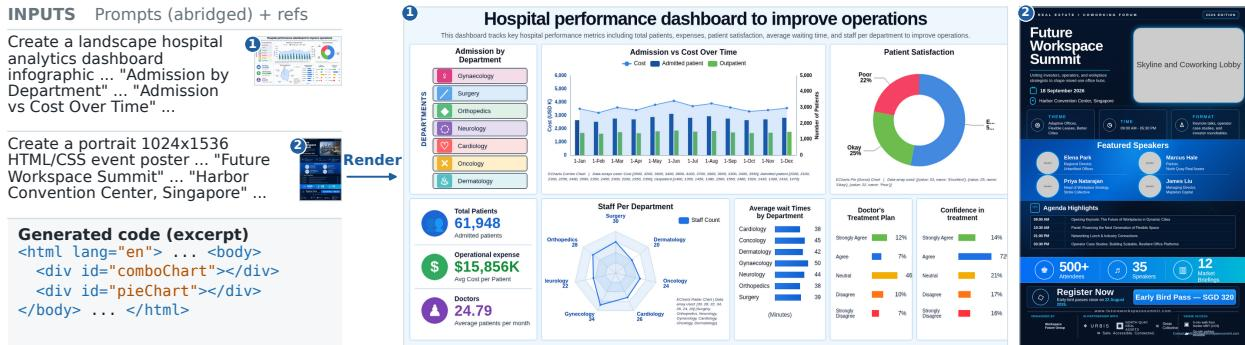
Information-rich visual artifacts such as slides, posters, and dashboards pack dense content into a single canvas, and generating them as code is valuable because the output remains structured, editable, and verifiable. However, prior approaches face a trade-off: code models cannot see the canvas and often produce visually dated layouts, while image generators create striking but non-editable raster outputs that frequently misrender text and data. Existing image-to-code methods treat reference images as ground truth for pixel-level reconstruction, which is unsuitable when the image is a noisy generated prior because it encourages copying hallucinated content and penalizes valid design variations. The authors propose AesCode, which represents the target as a design graph that explicitly separates required content from visual properties and structural relations. This enables decoupled rewards, with deterministic verifiers for correctness and a graph-based VLM rubric for aesthetic quality, balanced through Group reward-Decoupled Normalization Policy Optimization. The approach lets a prompt-generated reference image guide layout and style while the code model still strictly follows the prompt’s content.
Method
The authors leverage graph-structured supervision to learn visual design generation. The framework first constructs a target design graph that combines prompt-required content with non-authoritative reference cues. It then routes different graph properties to deterministic and perceptual reward channels. Finally, the model is optimized with cold-start supervised fine-tuning and a group-normalized reinforcement learning objective.
Design Graph as a Supervision Target
The prompt specifies required information, but visual design admits many valid solutions. Because learning needs a concrete signal, an image generator supplies one plausible reference image Iref, which may still be factually or structurally wrong. To avoid treating this reference as a monolithic target, the authors organize supervision as a design graph.
The supervision target is defined as
Gtgt=(V,E,XV,r)=Φ(p,Iref),where the canvas root r holds page-level attributes and contains every top-level element. The remaining nodes come from a closed vocabulary of atomic elements, including text, images, charts, tables, and badges, and containers such as regions, cards, panels, lists, and groups. Three or more interchangeable siblings collapse into one group node with a count attribute. Attributes XV record content, geometry, and appearance, including structured chart and table data. Each edge (u,τ,v) carries a relation type τ covering containment, alignment, order, adjacency, and semantic connection.
This decomposition lets prompt requirements and reference cues constrain complementary properties independently. From the generated code c and its rendering I^, the authors jointly parse candidate visual elements into a candidate graph:
G^=Ψ(c,I^).Code, DOM, and computed styles expose structured content and implementation details, while the rendering provides pixel geometry and visual evidence. The candidate graph is compared with Gtgt property by property to derive reward signals.
From Design Graphs to Multi-Objective Rewards
Graph properties are divided by how they can be assessed. Properties with structured evidence in code or measurable evidence in the rendering are handled by deterministic verifiers. Appearance and higher-order relations require visual judgment and are handled by a sample-specific VLM-as-judge channel.
Six deterministic verifiers compute scores from code, the DOM, OCR, and rendered pixels. Execution verifies renderability and fatal errors. Text verifies required strings. Boundary measures canvas containment and aspect-ratio agreement. Table and chart parsing checks the structure, subtype, and data of HTML tables and ECharts charts, preventing static substitutes from receiving credit. Semantic layout matches OCR text blocks between the reference and candidate and scores their normalized positional agreement. Whitespace compares non-background occupancy at coarse and fine scales, capturing how whitespace is distributed.
For the remaining properties, the authors introduce the Visual Graph Rubric. They derive a sample-specific list of Boolean questions Qtrain from Gtgt. Each question binds to a node, attribute, relation, or subgraph, so the graph scaffolds rubric construction rather than serving as a policy input. A VLM answers the fixed questions from the candidate rendering, and the pass rate defines
svgr=∣Qtrain∣1q∈Qtrain∑1[I^ satisfies q].Reference cues enter only through fixed questions, and the Visual Graph Rubric is used only for training.
Training Pipeline
Cold-start supervised fine-tuning first establishes reliable prompt-and-image-to-code generation from filtered teacher demonstrations paired with collected images. Reinforcement learning then switches to image-generator references and optimizes the seven reward channels.
Because these channels differ in applicability, scale, sparsity, saturation, and learning difficulty, aggregating raw rewards can obscure useful signals. The authors therefore use Group reward-Decoupled Normalization Policy Optimization, or GDPO.
For each (p,Iref), the model samples code rollouts B={ci}i=1B, renders I^i=render(ci), and parses G^i=Ψ(ci,I^i). Comparing G^i with Gtgt produces the seven rewards as a vector si. A mask mi(v)∈{0,1} indicates whether channel v applies to rollout i. Let μv and σv denote the mean and standard deviation over the applicable subset Bv={i∣mi(v)=1}. GDPO normalizes each channel before averaging the applicable advantages:
Ai(v)=σv+ϵsi(v)−μv,Ai=∑vmi(v)∑vmi(v)Ai(v).With
ρi(θ)=πold(ci∣p,Iref)πθ(ci∣p,Iref),GDPO maximizes the clipped group objective
LGDPO(θ)=B1i=1∑Bmin(ρi(θ)Ai,clip(ρi(θ),1−ε,1+ε)Ai).Applicability masks exclude irrelevant checks, so all valid objectives contribute to one policy update without first collapsing the raw rewards into a scalar.
Final Evaluation Protocol
Training requires a concrete reference, but evaluation must accept multiple valid designs. The authors therefore assess the generated artifact itself through Rule, Visual, and their mean Overall. Rule averages the deterministic Text, Boundary, and Table/Chart checks, which verify exact content, canvas containment, and structured data from code and rendering.
Visual converts open-ended, sample-specific quality into a checklist derived from prompt requirements. Content checks required-element presence and completeness. Layout covers organization, relations, and collisions. Style judges hierarchy, typography, color, and component finish against a production-ready standard. A VLM answers fixed yes/no questions from the candidate rendering, and Visual averages the three dimensions. These are absolute criteria for the artifact rather than pairwise comparisons. The question-generation pipeline is developed on a separate set, filtered for ambiguous, non-visual, and implementation-specific criteria, and then frozen and applied unchanged to the evaluation benchmark.
Experiment
The evaluation setup combines rule-based verification of text, boundaries, and tables/charts with a frozen visual checklist derived from each prompt, while training uses supervised fine-tuning on curated human designs and reinforcement learning with code and visual rewards. Main results show that reference conditioning improves visual presentation for all models but style remains a bottleneck, and AesCode training raises overall performance from 51.93 to 82.94 at 8B and from 61.10 to 85.89 at 32B, with transfer gains across external benchmarks. Ablations confirm that reinforcement learning and decomposed visual-graph rewards drive most visual improvement, and human evaluation aligns with the automatic visual score, while remaining failures center on canvas overflow, relational structure, and generic icon rendering.
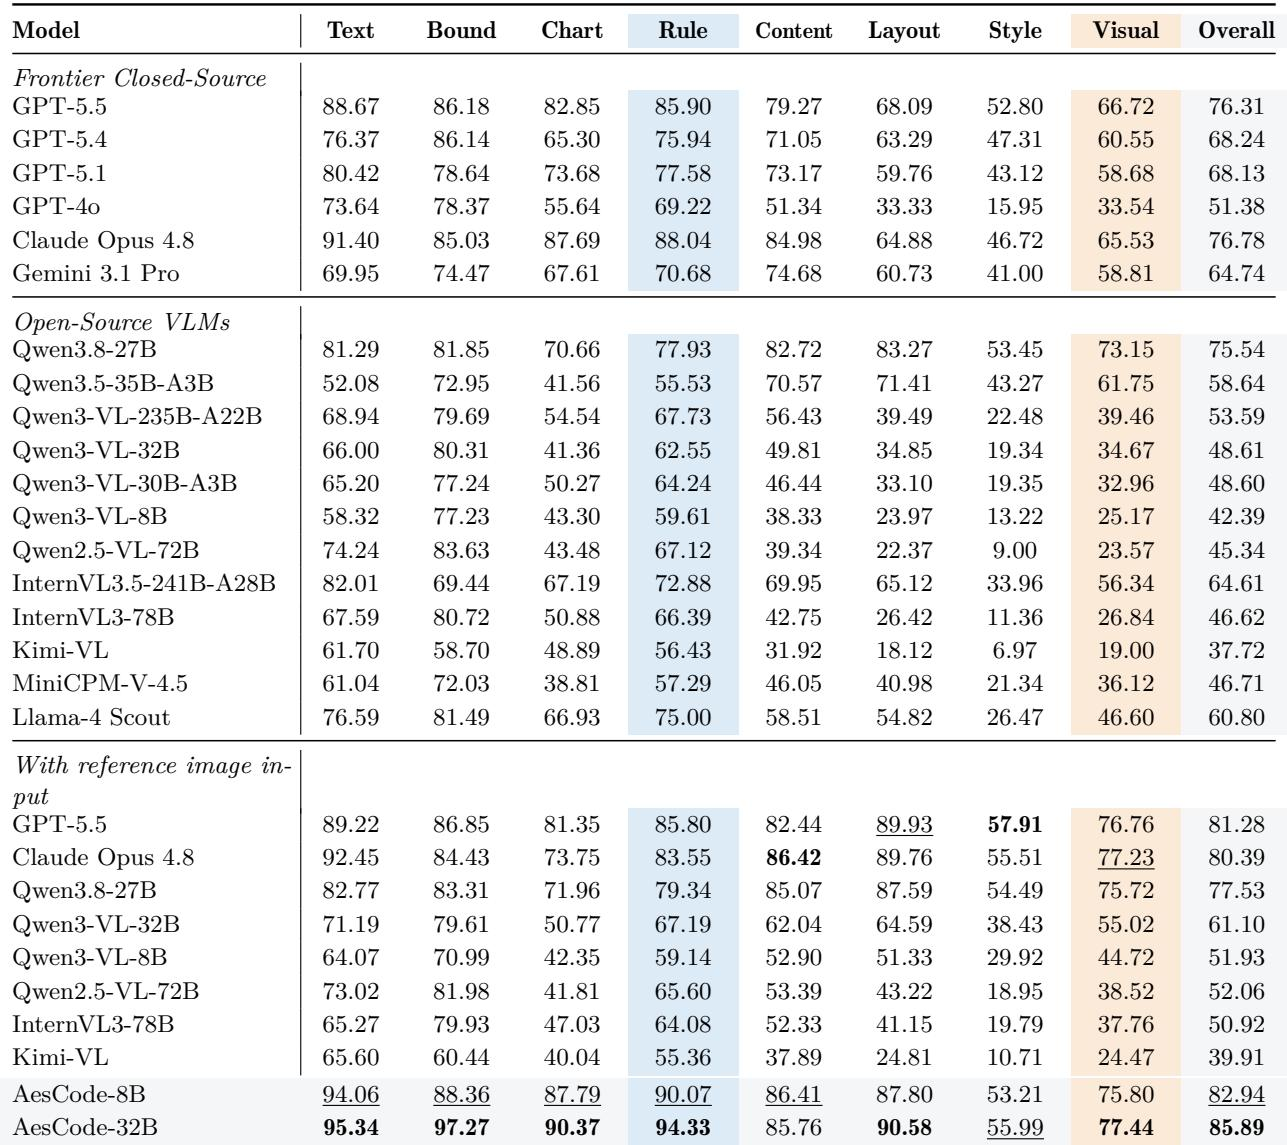
On the 300-instance infographic benchmark, rule-based scores are consistently higher and more stable than visual scores for the listed closed-source models. Claude Opus 4.8 achieves the highest overall score, while GPT-5.5 has the strongest visual score. Style is the weakest metric across these models, remaining below 60% for all listed systems. Claude Opus 4.8 leads the listed models in content fidelity and overall score, while GPT-5.5 leads in visual and style scores. Visual quality declines more sharply than rule compliance for weaker models, such as GPT-4o, whose visual and style scores fall far below its rule score.
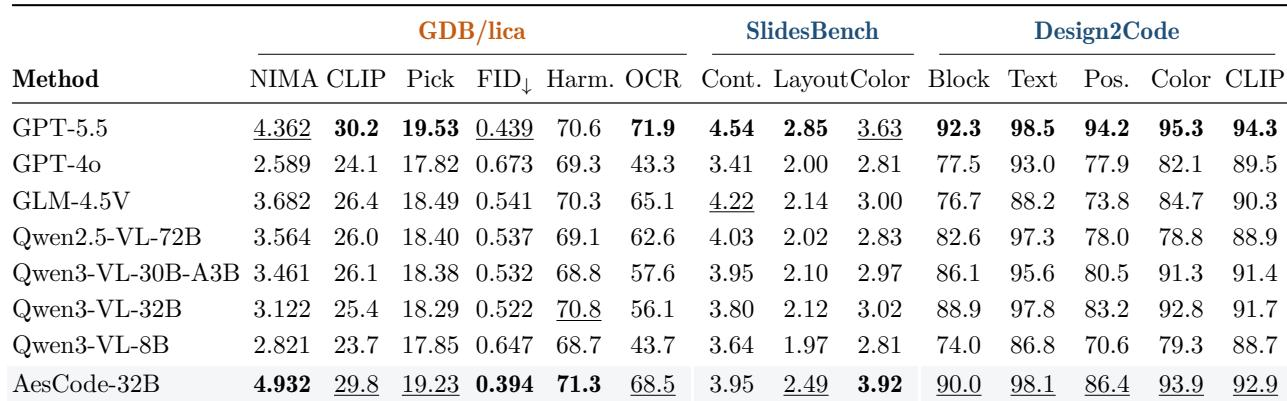
Across external transfer benchmarks, GPT-5.5 leads most design-sensitive measures, especially layout and color, while Qwen3-VL-32B is closest among open models on several visual and reconstruction-oriented scores. Design2Code similarity metrics are near saturation and align less well with human aesthetic judgment, reducing their ability to separate models. The surrounding analysis indicates GPT-5.5 remains stronger in exact screenshot fidelity, while AesCode's transferable gains concentrate in layout and visual design. GPT-5.5 records the highest transfer performance on most design-sensitive metrics, including layout and color, with GPT-4o and GLM-4.5V often trailing by wider margins. Qwen3-VL-32B is the strongest open-weight model on several layout and color dimensions, while Design2Code similarity metrics are near saturation and less sensitive to aesthetic differences. GPT-5.5 remains stronger in exact screenshot fidelity, whereas AesCode's transferable gains lie in layout and visual design rather than reconstruction-specific similarity.
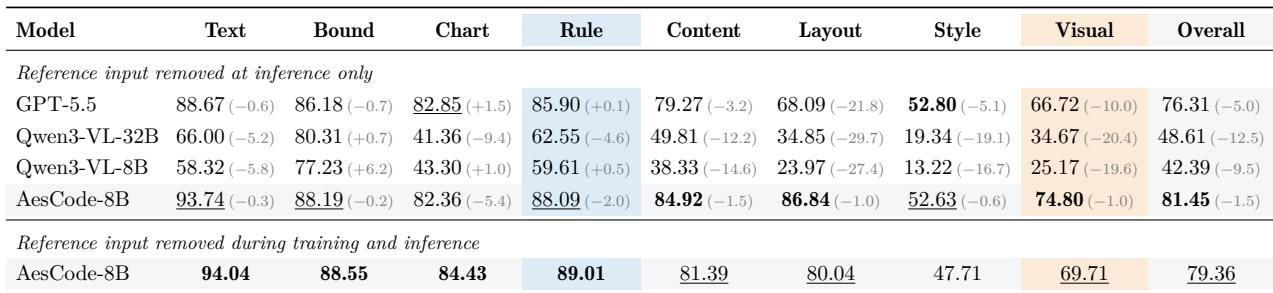
Reference-conditioned training makes AesCode-8B substantially more robust to reference removal at inference than GPT-5.5 and Qwen3-VL baselines, with only a small drop in Visual performance. When reference inputs are also removed during training, reference-based rewards still produce strong Visual gains over prompt-only training, though performance remains below the reference-conditioned setting. This suggests references help both as direct input conditions and as indirect supervision through rewards. AesCode-8B is far less sensitive to reference removal at inference than GPT-5.5 and Qwen3-VL baselines, with only a small Visual decline. Qwen3-VL models show large drops in layout, style, content, and visual scores when reference inputs are removed at inference. Removing reference inputs during training but keeping reference-based rewards raises Visual well above the prompt-only baseline, yet still trails the reference-conditioned policy.
The full configuration combining SFT, RL, GDPO, Layout/Whitespace, and VGR attains the highest Overall and Visual scores. RL contributes the largest gains, while SFT provides a stronger initialization; design supervision then drives visual quality, with VGR outperforming scalar GRPO, CLIP, and holistic VLM alternatives without sacrificing Rule. Replacing GDPO with scalar GRPO reduces Visual by 5.12 points while Rule stays similar, showing the benefit of channel-independent normalization for perceptual objectives. Replacing VGR with CLIP or a holistic VLM lowers Visual by about 5 to 7 points, and adding Layout/Whitespace alone improves Visual only modestly over code-correctness-only supervision.
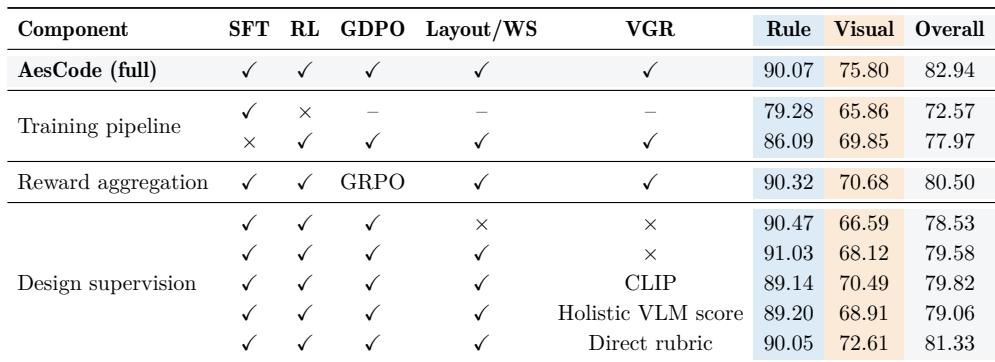
The experiments evaluate infographic generation quality, external transfer to design-sensitive benchmarks, robustness to reference removal, and component ablations. Closed-source models generally score higher on rule-based metrics than visual ones, with style being the weakest dimension, while GPT-5.5 leads on visual and layout/color transfer and Qwen3-VL-32B is the strongest open-weight model. Reference-conditioned training makes AesCode substantially more robust to missing references at inference, showing that references help both as direct input conditions and as indirect reward supervision. Ablations indicate RL contributes the largest gains, while design supervision such as VGR and GDPO improves visual quality more than scalar or holistic alternatives without sacrificing rule compliance.