Command Palette
Search for a command to run...
Long-WAM: Skalierung des Kontexts von World-Action-Modellen
Long-WAM: Skalierung des Kontexts von World-Action-Modellen
Zusammenfassung
Echtzeit-Robotersteuerung erfordert ausreichend visuelle Historie, um auf Bewegung und Aufgabenfortschritt zu schließen, doch die Verarbeitung dieser Historie kann die Aktion verzögern. Wir stellen Long-WAM vor, ein Modell-System-Framework zur Skalierung des Kontexts kausaler World-Action-Modelle unter Echtzeitsteuerungsbeschränkungen. Unser zentraler Befund ist, dass der Zugriff auf Historie nicht gleichbedeutend mit deren Nutzung ist: Längere Historien zahlen sich deutlich stärker aus, wenn das Video-Foundation-Modell autoregressiv (AR) vortrainiert wurde. Wir lernen zunächst kausale Prädiktion aus Roboterund egozentrischen Videos ohne Aktionslabels und erhalten dann diese Struktur von der Historie zur Zukunft während der World-Action-Adaption. Auf RoboCasa GR-1 erhöht eine Vergrößerung des Kontexts von 0,0 auf 19,2 Sekunden die Erfolgsquote von 63,3 % auf 78,7 %, während eine bidirektional vortrainierte Initialisierung keinen Nettogewinn zeigt; AR-Vortraining in der Roboterdomäne steigert die Spitzenerfolgsquote auf GR-1 und LIBERO-Long weiter. Long-WAM erzielt außerdem die besten Ergebnisse unter den verglichenen Methoden auf LIBERO-Long, RoboTwin 2.0 und DOMINO. Streaming-Beobachtungskodierung, asynchrone Ausführung und hardwarespezifische Beschleunigung ermöglichen den Einsatz auf RTX 5090, DGX Spark und Jetson AGX Thor ohne Einbußen bei der Zukunftsvorhersage; auf RTX 5090 benötigt jeder Aktions-Chunk einschließlich der latenten Vorhersage zukünftiger Videos 107,4 ms. Der Echtzeiteinsatz auf Unitree G1 und YAM unterstützt dynamische und langhorizontige Manipulation, darunter 95 % Erfolg beim dynamischen Becherstapeln, wobei π0.5 und Fast-WAM in keinem von 20 Versuchen erfolgreich sind. Als gedächtnisinformierter Executor ergänzt Long-WAM auch übergeordnete Planung in zusammengesetzten Aufgaben.
One-sentence Summary
NVIDIA, MIT, HKU, and UCSD propose Long-WAM, a model-system framework for scaling the context of causal world-action models under real-time control constraints by using autoregressively pretrained video foundations and preserving history-to-future structure, which raises RoboCasa GR-1 success from 63.3% to 78.7%, achieves the best results among compared methods on LIBERO-Long, RoboTwin 2.0, and DOMINO, and deploys on RTX 5090, DGX Spark, and Jetson AGX Thor to reach 95% success on dynamic cup stacking, where π0.5 and Fast-WAM succeed in none of 20 trials.
Key Contributions
- Long-WAM is a model-system framework that scales the context of causal world-action models under real-time control constraints by first learning causal prediction from robot and egocentric videos without action labels, then preserving this history-to-future structure during world-action adaptation.
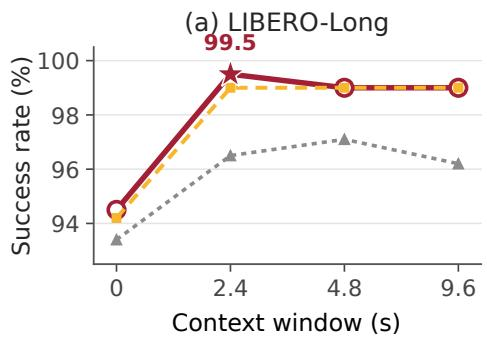
- The central finding is that access to history is not the same as using it: longer observation histories improve success mainly when the video foundation is autoregressively pretrained. On RoboCasa GR-1, increasing context from 0.0 to 19.2 seconds raises success from 63.3% to 78.7%, while a bidirectionally pretrained initialization shows no net gain, and robot-domain AR pretraining further improves peak success on GR-1 and LIBERO-Long.
- Long-WAM enables real-time deployment on RTX 5090, DGX Spark, and Jetson AGX Thor via streaming observation encoding, asynchronous execution, and hardware-specific acceleration, with 107.4 ms per action chunk including future-video latent prediction on RTX 5090. Long-WAM achieves the best results among compared methods on LIBERO-Long, RoboTwin 2.0, and DOMINO, reaches 95% success on dynamic cup stacking on Unitree G1 and 81.7% success on YAM tasks lasting over 40 seconds, and raises RoboCasa365 success from 31.4% to 54.4% when paired with GPT-6 Astra.
Introduction
Fast robot control depends on understanding temporal scene changes, since a single image cannot specify motion or interaction progress. World-action models bring video prediction into closed-loop control, making visual history a natural conditioning signal, but longer history can delay the very response it should improve. Recent WAMs provide memory through caches or retrieval, yet access to history is not the same as learning to predict from it, and bidirectional video pretraining may not yield scalable control benefits. The authors introduce Long-WAM, a model and system framework that first learns autoregressive video prediction and then adapts to actions while preserving the causal history-to-future structure. Their key finding is that longer visual context improves control mainly when the video foundation is autoregressively pretrained; they further co-design asynchronous execution, streaming observation encoding, and edge-device quantization to retain these gains under real-time constraints.
Dataset
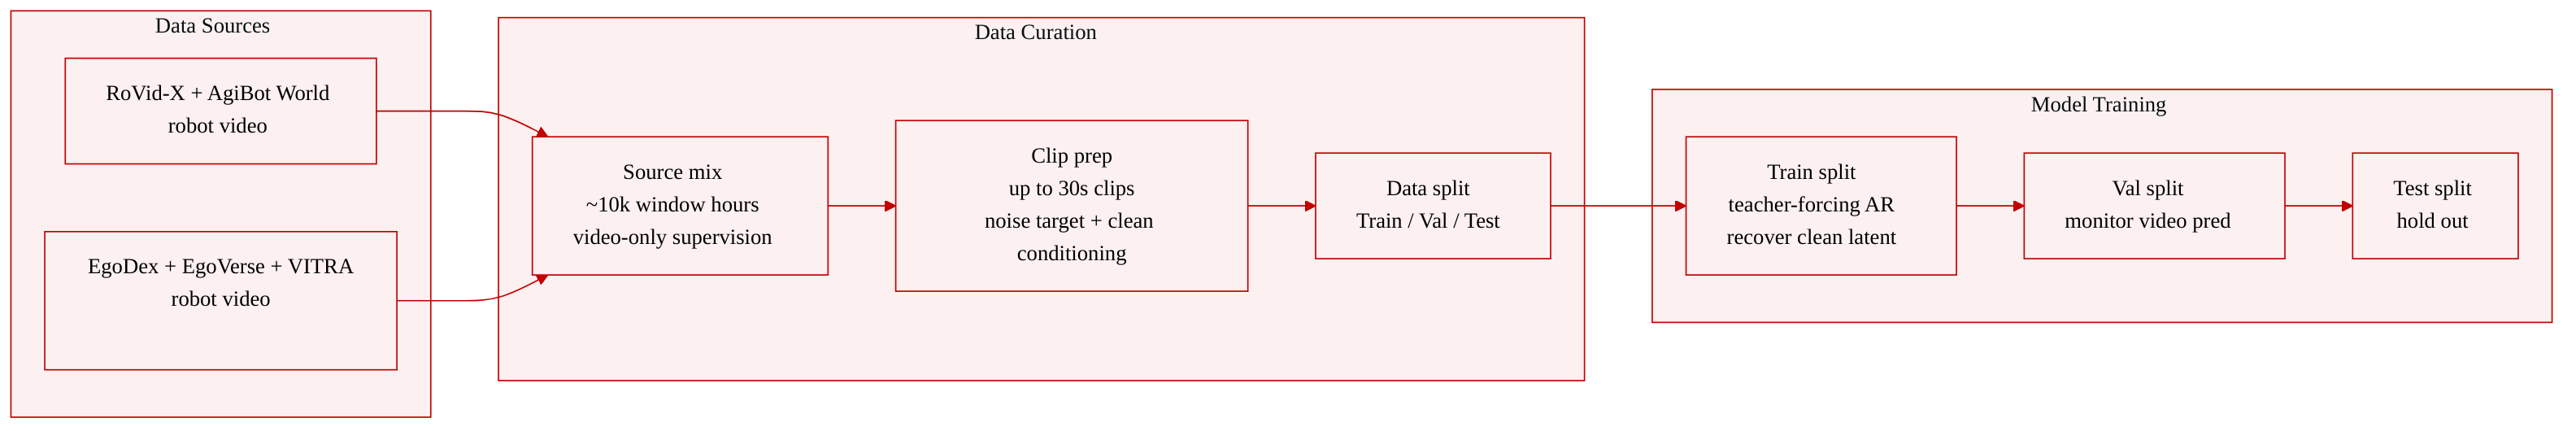
- Composition and sources: The dataset consists of about 10,000 window-equivalent hours of robot video drawn from five sources: RoVid-X, AgiBot World, EgoDex, EgoVerse, and VITRA.
- Supervision and embodiment coverage: Pretraining uses video-only supervision, so the data can combine multiple robot embodiments without requiring a shared action space.
- Temporal format and scale: The model is initialized from LongLive-2.0’s 16-second AR checkpoint and then trained on robot-video sequences up to 30 seconds long, exposing it to longer motion and interaction histories.
- Processing and usage: Each robot-video sequence is used for autoregressive video generation. Target chunks are noised, and each noisy chunk is supervised from its ground-truth prefix. The conditioning image stays clean and outside the loss, and the target is to recover the original clean latent from the noisy input.
- Subset details and filtering: The excerpt does not specify individual subset sizes, filtering rules, or mixture ratios across the five sources. It refers to Appendix B.1 for detailed data accounting.
- Role in the model: Given one image and a language prompt, the pretrained model predicts coherent robot motion and object interactions, providing a predictive prior for downstream action adaptation.
Method
The authors first establish a predictive foundation through long-sequence autoregressive video pretraining, specifically LongLive2.0-Robot. This phase exposes the model to extended motion and interaction histories up to 30 seconds. Using a teacher-forcing formulation, the model learns to predict coherent robot motion and object interactions from a clean conditioning image and language prompt. The noisy input and teacher-forcing objective are defined as:
xiσi=(1−σi)zˉi+σiϵˉi,σi∈[0,1] LTF−AR=E[w(σi)∥vθ(xiσi,σi∣h<i,c)−(ϵˉi−zi)∥22].Here, σi is the sampled noise level, vθ is the video velocity predictor, and the recovery target retains the original zi to teach correction of rollout-like errors.
To transfer this predictive foundation to action generation, the authors employ a causal-to-causal world-action adaptation. They couple video and action experts through an asymmetric interface where video queries read only their own and earlier visual blocks, while action queries read observed history, partially denoised futures, and the entire noisy action chunk. This preserves pretrained causal visual dependencies while grounding actions in both past and anticipated interaction.
As shown in the figure below:
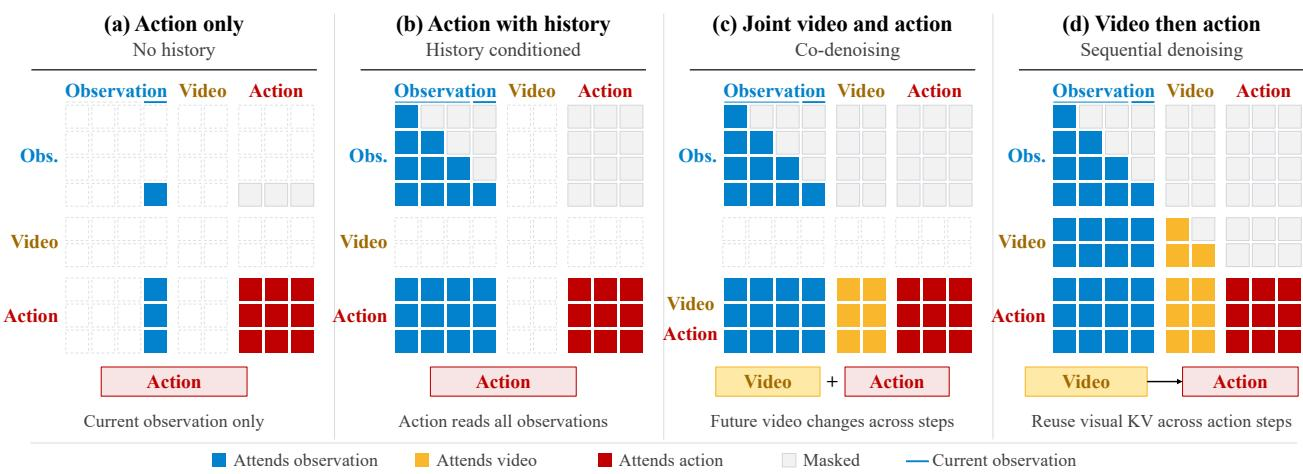
At a decision made at control step t, let Zt− denote observed video latents, qt the robot state, c the language instruction, and At=at:t+H−1 an H-step action chunk. The video expert predicts Kv future latent steps Zt+ to noise level σ⋆∈(0,1), then supplies their joint visual cache Kt to the action expert:
Zt+=Rolloutθ,σ⋆(ϵv∣Zt−,c,qt),Kt=Prefillθ(Zt−,Zt+;c,qt,σ⋆),At=Denoiseψ(ϵa∣Kt,c,qt).This predict-then-act mode is referred to as inverse dynamics modeling. Training utilizes two passes: video flow matching conditioned on clean history, followed by action flow matching conditioned on history and a forward-noised ground-truth future. The second pass detaches the visual cache, ensuring action loss updates only the action expert and proprioceptive adapter. The weighted objective is L=λvLvideo+λaLaction.
To support real-time deployment, the authors co-design asynchronous execution and edge acceleration. Asynchronous scheduling overlaps model inference with robot execution. At decision tk, the predicted chunk Atk has a nominal stride S and an overlap of O=R−S steps. At the handoff, the controller discards the elapsed prefix and executes the new chunk's aligned suffix. To meet the tighter handoff deadline required by shorter overlaps, streaming causal VAE encoding processes incoming frame groups ahead of the inference trigger.
Refer to the framework diagram:
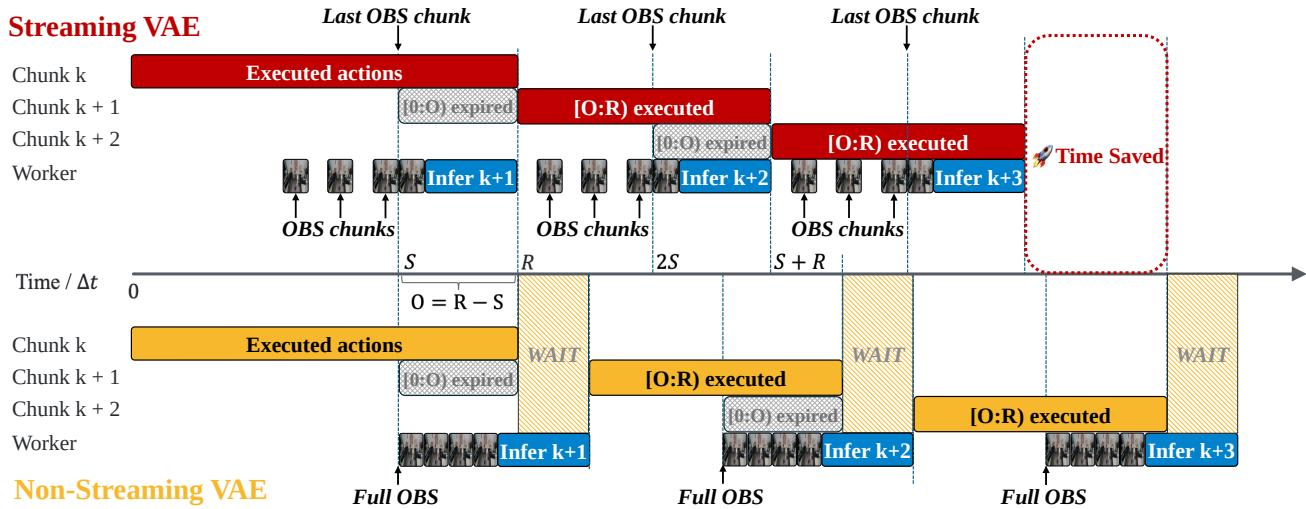
The handoff deadline is constrained by Tready≤OΔt=(R−S)Δt, where Δt is the control interval. Streaming VAE avoids full-window encoding's repeated waits, allowing later triggers and shorter overlap while retaining the latest observation.
Local inference is accelerated on edge devices to support short-overlap execution while preserving visual imagination.
As shown in the figure below:
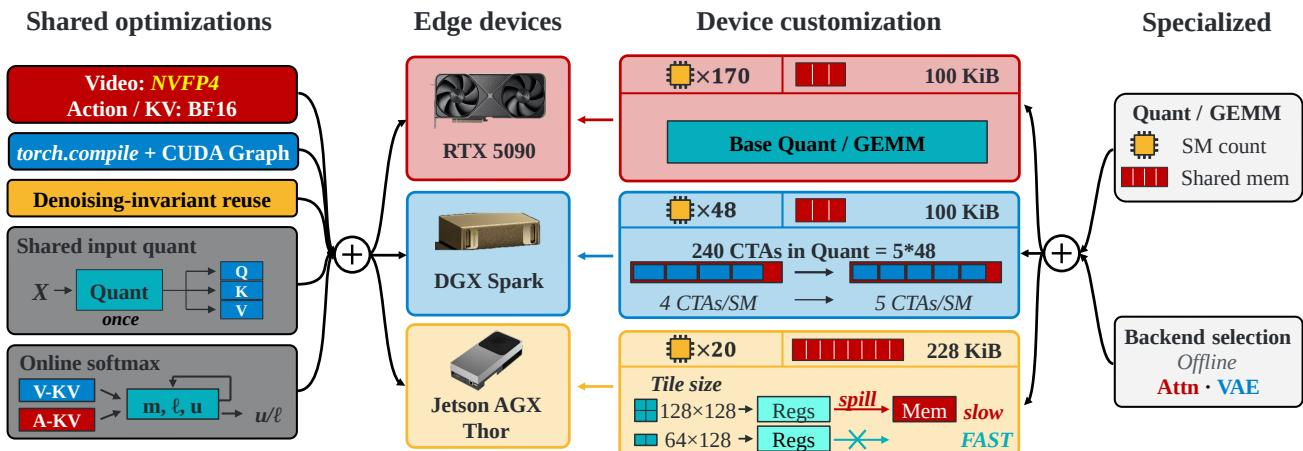
Shared optimizations include using W4A4 NVFP4 for video-expert linear layers during generation and KV prefill, while action compute and KV storage remain in BF16 to maintain control precision. NVFP4 is combined with CUDA Graph replay and PyTorch compilation to reduce launch overhead. The system also reuses denoising-invariant text and state KV, observed-video KV, and FP32 RoPE tables within each inference call. Shared input quantization quantizes the input to Q, K, and V projections once, reusing quantized activations across separate GEMMs. Furthermore, attention over separate video and action KV buffers is combined using online softmax with a shared normalization:
m=max(mv,ma),Attn=emv−mℓv+ema−mℓaemv−muv+ema−mua.Device-specific tuning adjusts tile sizes, warps per block, and pipeline stages to balance portability and hardware efficiency across platforms like RTX 5090, DGX Spark, and Jetson AGX Thor.
Experiment
The paper evaluates Long-WAM, a video prediction-conditioned action denoising policy, on simulation benchmarks including LIBERO, RoboTwin 2.0, DOMINO, and RoboCasa GR-1, with real-robot tests on a Unitree G1 and YAM manipulator. Results show that Long-WAM leads on long-horizon and dynamic manipulation benchmarks, while ablations indicate that longer visual context, autoregressive robot-video pretraining, and the IDM video-action denoising strategy all contribute to the gains. Adding a high-level planner further improves composite and unseen task success, and real-world trials demonstrate sustained grasping on a moving conveyor and reliable long-horizon manipulation. Efficiency optimizations reduce inference latency to about 107 ms on an RTX 5090 while largely preserving success and supporting asynchronous execution.
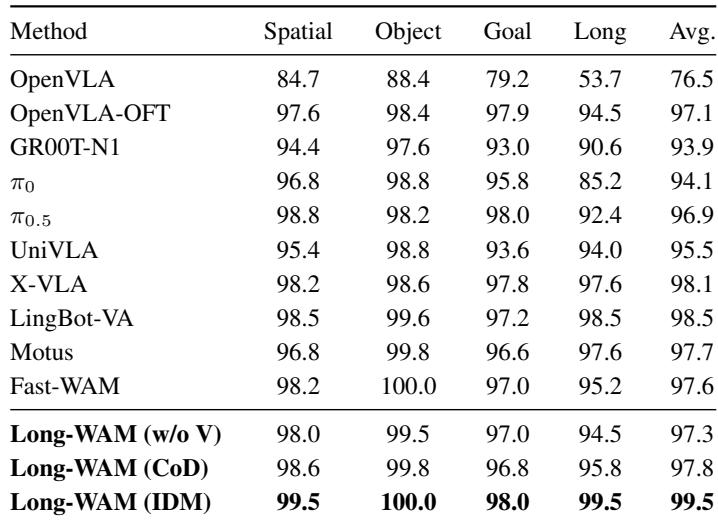
On LIBERO, Long-WAM with inverse dynamics modeling achieves the highest average success and the highest long-horizon success among reported methods. Its advantage is largest on the long split, where future-video prediction before action denoising outperforms both omitting future-video prediction and joint video-action co-denoising. Strong baselines such as OpenVLA-OFT and X-VLA improve substantially over OpenVLA, but remain below Long-WAM. Long-WAM (IDM) leads average LIBERO success and performs best on the long-horizon split. The largest gains from inverse dynamics modeling appear on long tasks, surpassing no future-video denoising and joint video-action co-denoising by clear margins. OpenVLA is weakest on long-horizon success, while OpenVLA-OFT and X-VLA are the strongest baseline alternatives.
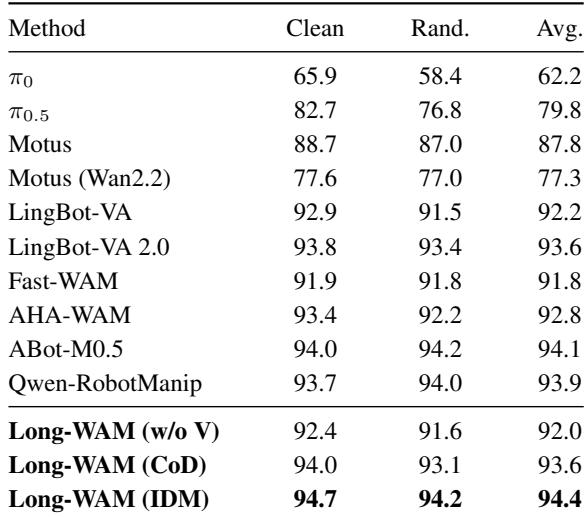
On RoboTwin 2.0, Long-WAM with IDM leads overall, achieving the highest average and clean success rates and matching the best randomized score. It holds a modest edge over LingBot-VA 2.0 and a clearer advantage over Fast-WAM and earlier baselines. Long-WAM (IDM) achieves the highest average and clean success rates on RoboTwin 2.0 and ties the best randomized score. Its average leads LingBot-VA 2.0 by 0.8 points and is further ahead of Fast-WAM, Motus, and the π baselines.
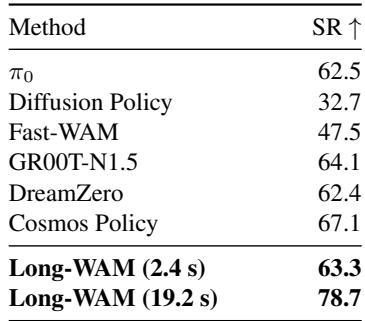
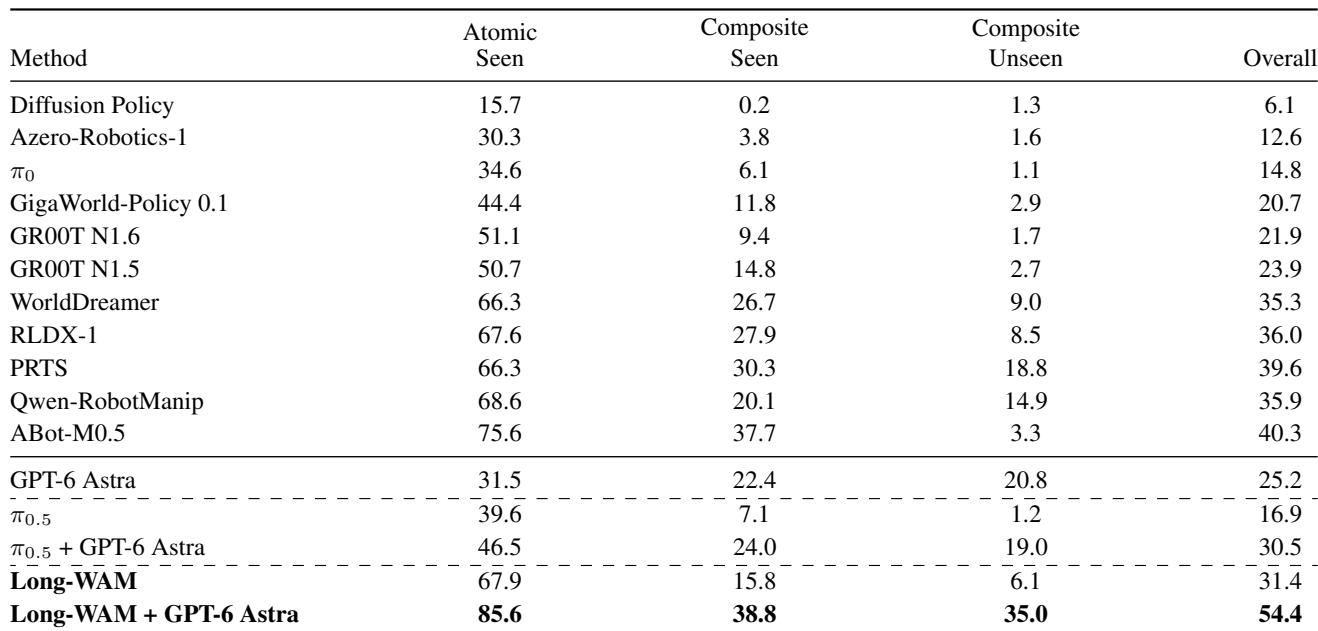
On the RoboCasa365 compositional benchmark, Long-WAM with a 2.4-second context reaches a success rate in the low sixties, placing it well above Diffusion Policy and Fast-WAM while slightly below the best reported method, Cosmos Policy. Planner augmentation with GPT-6 Astra gives Long-WAM a larger overall gain than the π0.5 hierarchy, indicating that execution quality complements high-level planning for longer-horizon compositions. Long-WAM outperforms Diffusion Policy and Fast-WAM by wide margins and is competitive with the strongest baselines, trailing Cosmos Policy by only a few points. Adding a high-level planner improves Long-WAM more than the π0.5 hierarchy, supporting a division of labor between planning and execution.
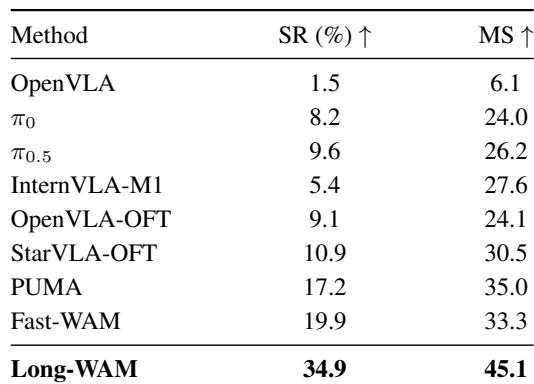
After dynamic-data fine-tuning on DOMINO, Long-WAM achieves the highest success rate and manipulation score among reported methods. Its success rate is nearly double the best listed baseline, and its manipulation score is also substantially ahead. Most other models remain far behind, indicating the benchmark's difficulty. Long-WAM leads with a 34.9% success rate and a 45.1 manipulation score after dynamic-data fine-tuning. Long-WAM surpasses the strongest success-rate baseline by 15.0 points and the strongest manipulation-score baseline by 10.1 points. Listed baselines show much lower success rates, mostly clustering in the single-digit to upper-teens range.
On RoboCasa365, Long-WAM alone provides strong atomic-task execution and outperforms GPT-6 Astra alone and the listed reference policies on atomic success. Adding a high-level planner without further policy training substantially improves both composite-seen and composite-unseen success, lifting overall performance well above the strongest reference baseline. Shorter 15-step execution alone achieves much lower composite success, so planning appears to be the key factor for unseen composition generalization. Long-WAM alone is a strong execution foundation: it achieves markedly higher atomic-seen success than GPT-6 Astra alone, and more frequent 15-step querying without a planner nearly closes the gap to the hierarchical system. Planner augmentation more than doubles composite-seen success and raises composite-unseen success more than fivefold, while 15-step control alone remains near or below 11 percent on both composite splits. The planner-augmented policy reaches the highest overall success among reported methods, exceeding the strongest reference baseline by a large margin.
The evaluation spans LIBERO, RoboTwin 2.0, RoboCasa365, and DOMINO, covering long-horizon manipulation, bimanual control, compositional generalization, and dynamic-data fine-tuning. Long-WAM with inverse dynamics modeling consistently leads or is competitive, with the largest gains on long-horizon and compositional tasks. Future-video prediction before action denoising and planner augmentation improve execution and unseen composition generalization, while dynamic-data fine-tuning strongly raises DOMINO performance over baselines. Overall, Long-WAM outperforms or matches the strongest reported baselines across most settings.