Command Palette
Search for a command to run...
EVISKILL: Verankerung der Skill-Evolution in wieder abspielbarer Evidenz
EVISKILL: Verankerung der Skill-Evolution in wieder abspielbarer Evidenz
Yan Zhou Yili Wang Yiwei Dai Qinggang Zhang Xin Wang
Zusammenfassung
Die kontinuierliche Skill-Evolution ermöglicht es LLM-Agenten, wiederverwendbares prozedurales Wissen aus Interaktionserfahrung zu akkumulieren und zu verfeinern, ohne die Modellparameter zu aktualisieren. Ihre Wirksamkeit hängt davon ab, nicht nur zu bestimmen, was geändert werden soll, sondern auch, warum eine Änderung gerechtfertigt ist und wann sie zu einer dauerhaften Leitlinie werden sollte. Bestehende erfahrungsgetriebene Methoden können jedoch die Verhaltensevidenz und die Aufgabenkontexte verlieren, die Änderungen stützen. Darüber hinaus liefert ein globales Validierungsergebnis nur eine unvollständige Beurteilung der darin enthaltenen Änderungen: Lokal gestützte Korrekturen können mit einer abgelehnten Überarbeitung verworfen werden, während Evidenz möglicherweise weiterer Erfahrung bedarf, um nützliche Aktualisierungen zu ermöglichen. Zu diesem Zweck stellen wir EVISKILL vor, ein evidenzgetriebenes Framework, das Ausführungsbeobachtungen in Replayable Evidence Cards (wieder abspielbare Evidenzkarten) organisiert und Änderungen mit expliziten Verknüpfungen zu ihren stützenden Kontexten synthetisiert. Gezieltes Replay überprüft diese Änderungen durch erneute Ausführung und liefert Feedback zur Korrektur. Über Epochen hinweg bewahrt EVISKILL Evidenz und behält gestützte Änderungen vorläufig für die weitere Verfeinerung bei, während die globale Validierung ihre Übernahme in den endgültigen Skill steuert. Experimente mit drei interaktiven Benchmarks über sechs LLM-Backbones hinweg belegen die Wirksamkeit dieses Ansatzes. Unser Code und die Implementierungsdetails sind unter https://github.com/Zhouyaner/eviskill verfügbar.
One-sentence Summary
Researchers at Jilin University propose EVISKILL, an evidence-driven framework for continual LLM skill evolution that stores execution observations as Replayable Evidence Cards, synthesizes edits explicitly linked to supporting contexts, verifies those edits through targeted replay, and provisionally retains supported edits for further refinement before global validation incorporates them into final skills, with effectiveness demonstrated on three interactive benchmarks across six LLM backbones.
Key Contributions
- EVISKILL is an evidence-driven skill evolution framework that organizes execution observations into Replayable Evidence Cards and links skill edits to their supporting behavioral contexts.
- Replay-guided edit verification tests whether edits produce their intended behavioral effects through re-execution, while cross-epoch evidence propagation retains and refines supported edits even when the overall revision is rejected.
- Experiments on three interactive benchmarks across six LLM backbones show consistent improvements over strong skill evolution baselines, with analyses indicating that evidence-grounded replay filters unsupported revisions and cross-epoch propagation enables prior evidence to support continued refinement.
Introduction
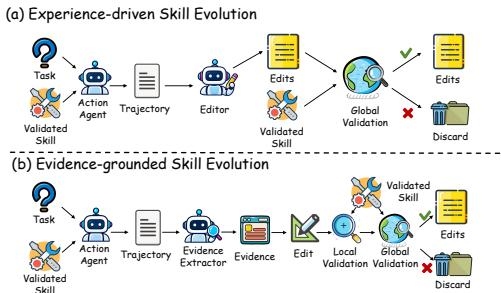
LLM agents increasingly handle interactive tasks such as tool use, web navigation, and long-horizon decision making, where reusable external skills provide procedural guidance without changing model parameters. Prior experience-driven skill evolution methods extract updates directly from execution trajectories, but execution experience is local and context-dependent, so edits can overfit observed cases or capture incidental behavior. Rejected revisions may also contain useful edits that are discarded. The authors introduce EVISKILL, an evidence-driven framework that organizes continual skill evolution into evidence construction, behavioral verification, and cross-epoch refinement. EVISKILL grounds candidate edits in replayable execution evidence, re-executes referenced behaviors to verify intended effects, and preserves uncertain or unresolved evidence for reconsideration across future epochs. Experiments on three interactive benchmarks across multiple LLM backbones show consistent improvements over strong skill evolution baselines.
Method
The authors introduce EVISKILL, a framework that organizes skill evolution around Replayable Evidence Cards. These cards record proposed skill corrections alongside their supporting execution evidence, enabling a structured pipeline for continuous improvement. The overall architecture consists of three interconnected phases: Evidence-Grounded Edit Synthesis, Replay-Guided Edit Verification, and Cross-Epoch Evidence Propagation.
As shown in the figure below:
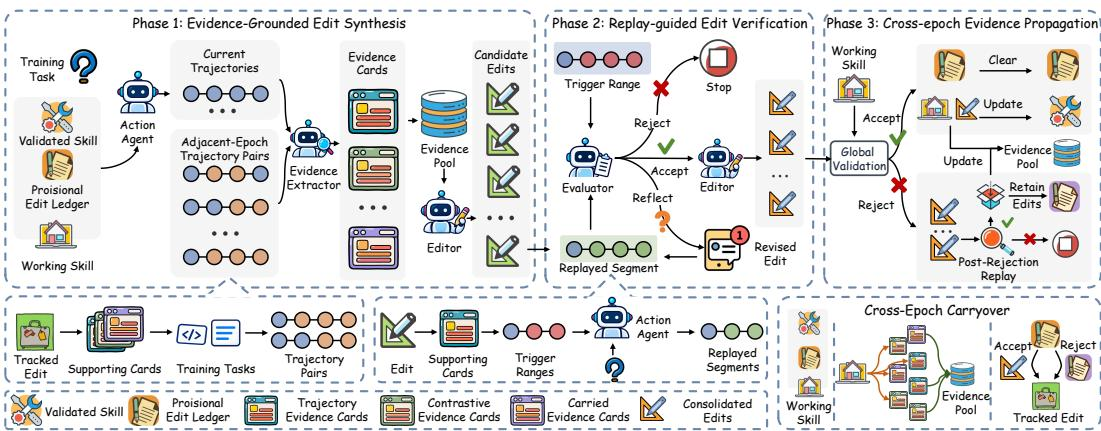
In the first phase, Evidence-Grounded Edit Synthesis, the system distinguishes between the Validated Skill, which is updated only upon successful global validation, and the Working Skill used for ongoing interactions. At epoch e, the Working Skill SeW combines the latest Validated Skill SeV with a Provisional Edit Ledger Pe, which contains replay-supported edits retained for further refinement:
SeW=SeV⊕Pewhere ⊕ applies the edits sequentially. The Action Agent collects trajectories using SeW, providing the foundational evidence for skill revision. An LLM evidence extractor analyzes the Working Skill and its trajectories to propose corrections, recording each proposal as a Replayable Evidence Card. A card Ci is formally defined as:
Ci=⟨i,Gi,di⟩where i is a persistent identifier, Gi represents supporting trigger ranges from trajectories, and di is the proposed correction. The framework extracts Trajectory Evidence Cards from current interactions and Contrastive Evidence Cards from adjacent-epoch trajectory comparisons to identify persistent deficiencies. These cards are combined into an Evidence Pool, grouped into Evidence Windows based on compatible contexts, and processed by an LLM editor to synthesize a candidate edit set Ue.
The second phase, Replay-Guided Edit Verification, ensures that synthesized edits produce their intended behavioral effects. For each candidate edit u∈Ue, the system retrieves its supporting cards and replays the associated trigger ranges. By reproducing the prefix of the source trajectory, the framework reconstructs the execution state and re-executes the segment under the modified skill SeW⊕u. An LLM evaluator assesses the source and replayed segments, returning a decision to accept, reflect, or reject the edit. If the decision is to reflect, the editor generates a revised edit u′ based on the feedback, which then undergoes another round of replay and evaluation. Successfully verified edits are consolidated into an ordered collection, yielding a candidate revision Se for global validation.
The final phase, Cross-Epoch Evidence Propagation, governs how skills and evidence are updated across epochs. Global validation compares the candidate revision Se against the current Validated Skill SeV on a validation set. If Se demonstrates superior performance, it replaces SeV, the Provisional Edit Ledger is cleared, and the incorporated edits become the new Tracked Edits for future cross-epoch comparisons.
If the candidate revision is globally rejected, the framework employs post-rejection replay to salvage effective edits. Each consolidated edit is replayed independently under the original Validated Skill SeV⊕v to determine if it remains effective without the provisional edits. Edits that pass this isolated evaluation are retained in the updated Provisional Edit Ledger for the next epoch, ensuring that locally beneficial corrections are not discarded due to global incompatibilities. Furthermore, the lifecycle of the Evidence Cards is dynamically managed. Cards supporting accepted edits are archived, while those supporting rejected edits may be marked as stale or protected for future cross-epoch comparisons. After E evolution epochs, the final Validated Skill is frozen for inference, ensuring that only thoroughly validated and replay-supported skills are deployed.
Experiment
The preliminary study identifies two weaknesses in existing skill evolution: edits based on experience often fail to produce intended execution effects, and globally rejected revisions may still contain useful constituent edits. The main experiments evaluate EVISKILL across App-World, ScienceWorld, and ALFWorld with multiple LLM backbones, showing that grounding skill updates in execution evidence yields broad gains and that evolving a skill does not guarantee improvement over its initial version. Ablation and mechanism analyses confirm that replay-guided edit verification improves behavioral corrections, while cross-epoch evidence propagation preserves supported edits and unresolved evidence, with many edits from rejected revisions later incorporated into accepted skills and evidence cards reused across epochs.
Execution-grounded skill evolution yields broad task-success gains across interactive benchmarks, improving over the no-skill baseline in every setting and ranking among the top methods in most comparisons. Several skill-evolution baselines regress on ScienceWorld, falling below both the no-skill and initial-skill accuracy, while the execution-grounded approach avoids this pattern. The results indicate that verifying updates through observed behavior helps preserve useful skills while incorporating new experience. Execution-grounded skill updates achieve the best accuracy in most model-dataset settings and improve over no skill in all reported settings. On ScienceWorld, several evolution baselines underperform the initial skill, with some dropping below the no-skill baseline, whereas execution-grounded updates improve over the initial skill in nearly all settings.
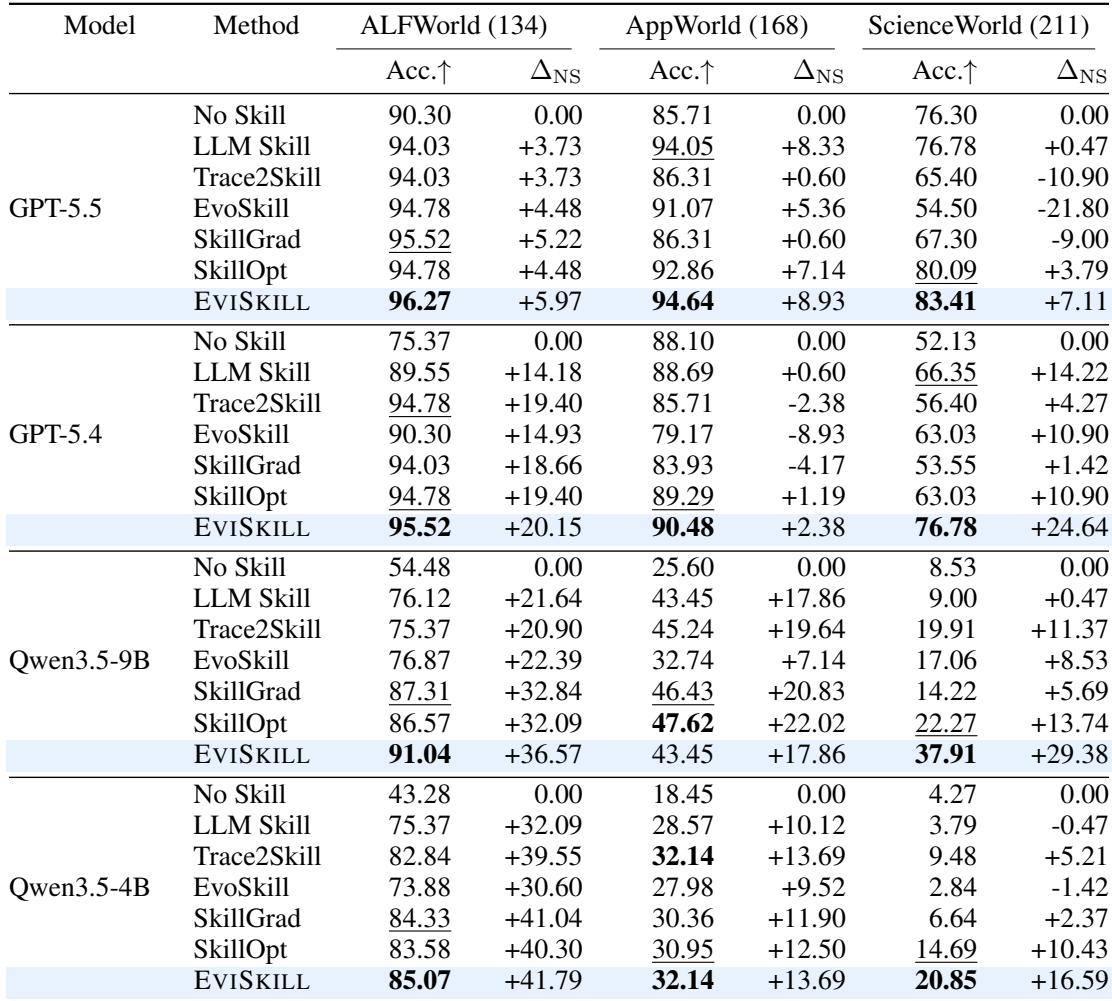
The experiments evaluate execution-grounded skill evolution on interactive benchmarks, testing whether updates grounded in observed behavior improve task success. The approach consistently improves over the no-skill baseline across all settings and ranks among the top methods, while several skill-evolution baselines regress on ScienceWorld and fall below both no-skill and initial-skill accuracy. Execution-grounded updates also achieve the best accuracy in most model-dataset settings and improve over the initial skill in nearly all ScienceWorld settings. These results suggest that grounding skill updates in execution helps retain useful skills while integrating new experience.