Command Palette
Search for a command to run...
YUE2: Vereinheitlichung von symbolischer und Audio-Musikgenerierung in Frontier-Qualität
YUE2: Vereinheitlichung von symbolischer und Audio-Musikgenerierung in Frontier-Qualität
Zusammenfassung
Symbolische Modelle machen Melodie, Harmonie, Rhythmus und Form explizit, enden jedoch typischerweise vor einer fertigen Aufnahme; Audiomodelle erzeugen vollständige Songs, wobei die Komposition implizit bleibt. Wir stellen YuE2 vor, das symbolische und Audio-Musikgenerierung durch symbolische Planung in Frontier-Qualität vereint. Ein einzelnes AR–NAR-Mixture-of-Transformers (MoT) [14] schreibt zunächst eine lesbare Partitur, die Melodie und Harmonie festlegt, erweitert diese zu semantischen Musiktokens und realisiert sie als vollständiges Song-Audio. In Vergleichen mit demselben Checkpoint bevorzugen Expert:innen symbolische Planung hinsichtlich Gesamtqualität und Musikalität, mit 49,3 % der Gesamtpräferenzen gegenüber 34,6 % ohne Planung. Expert:innen bevorzugen zudem das vereinheitlichte Modell gegenüber einem separaten Sprachmodell und Diffusions-Transformer [81]. Auf WildSongBench erreicht YuE2 im SongBench [77] Global Avg 6,73 und übertrifft damit alle evaluierten öffentlichen Baselines. Bei Auswahl aus acht Kandidaten (Best-of-8) erreicht YuE2 6,96, den höchsten beobachteten Mittelwert unter allen evaluierten Systemen. Expert:innen-Hörtests belegen darüber hinaus die Wettbewerbsfähigkeit gegenüber proprietären Songgeneratoren: Best-of-8 wird gegenüber Suno v4.5 [68] bevorzugt, und gegenüber Suno v5 [65] ergeben sich nahezu ausgeglichene Präferenzen. Um diesen Generierungsprozess aus Aufnahmen ohne ausgerichtete Partituren zu lernen, führen wir MERT2 und SheetSage2 ein, die semantische und symbolische Supervision bereitstellen. MERT2 setzt einen neuen Stand der Technik beim Lernen von Musikrepräsentationen und übertrifft frühere Bestwerte in 14 von 15 MARBLE [87]-Metriken; SheetSage2 führt in 12 von 15 Benchmark-Metrik-Paaren in unserem Lead-Sheet-Transkriptionsvergleich. Derselbe Checkpoint folgt Partituränderungen, während unveränderte musikalische Inhalte weitgehend erhalten bleiben, und erzeugt Zero-Shot-Cover ohne cover-spezifisches Training. Die lesbare Partitur ermöglicht zudem agentische Musikbearbeitung, indem externe Sprachmodelle Nutzerfeedback in Überarbeitungen der Komposition übersetzen.
One-sentence Summary
Researchers from The Hong Kong University of Science and Technology, HKGAI, and collaborators introduce YuE2, a single AR-NAR Mixture-of-Transformers that unifies symbolic and audio music generation at frontier quality by first planning a readable score and then realizing full-song audio, with MERT2 and SheetSage2 supplying semantic and symbolic supervision so that YuE2 scores 6.73 on SongBench Global Avg, exceeding all evaluated public baselines, reaches 6.96 with best-of-8, and enables editable, zero-shot song generation.
Key Contributions
- YuE2 unifies symbolic and audio music generation at frontier quality by generating a readable score specifying melody and harmony, expanding it into semantic music tokens, and rendering full-song audio with a single AR-NAR Mixture-of-Transformers.
- MERT2 and SheetSage2 supply semantic and symbolic supervision for learning this composition-to-audio hierarchy from recordings without pre-existing aligned scores; MERT2 sets a new state of the art on 14 of 15 MARBLE metrics, and SheetSage2 leads 12 of 15 benchmark-metric pairs in full-song transcription.
- The same checkpoint supports score edits, zero-shot cover generation, and agentic music editing; experts prefer symbolic planning over no planning by 49.3% to 34.6% overall, favor best-of-8 over Suno v4.5, and YuE2 achieves 6.73 SongBench Global Avg while best-of-8 reaches 6.96, exceeding all evaluated public baselines.
Introduction
The authors focus on the gap between symbolic and audio music generation: symbolic models expose editable scores but do not produce finished recordings, while audio models generate recordings but leave the composition implicit. This limits control over melody, harmony, and form in full-song generation. The authors introduce YuE2, a unified model that first writes a symbolic composition containing melody, chords, key, meter, tempo, and form through symbolic composition planning, then renders it as stereo audio using semantic music tokens and continuous acoustic latents. Because ordinary audio corpora lack aligned notes, chords, beats, and sections, they also introduce MERT2 and SheetSage2 to derive semantic and symbolic supervision from recordings. The approach improves perceived song quality and enables score-based editing, zero-shot cover generation, and agentic music editing with the same checkpoint.
Dataset
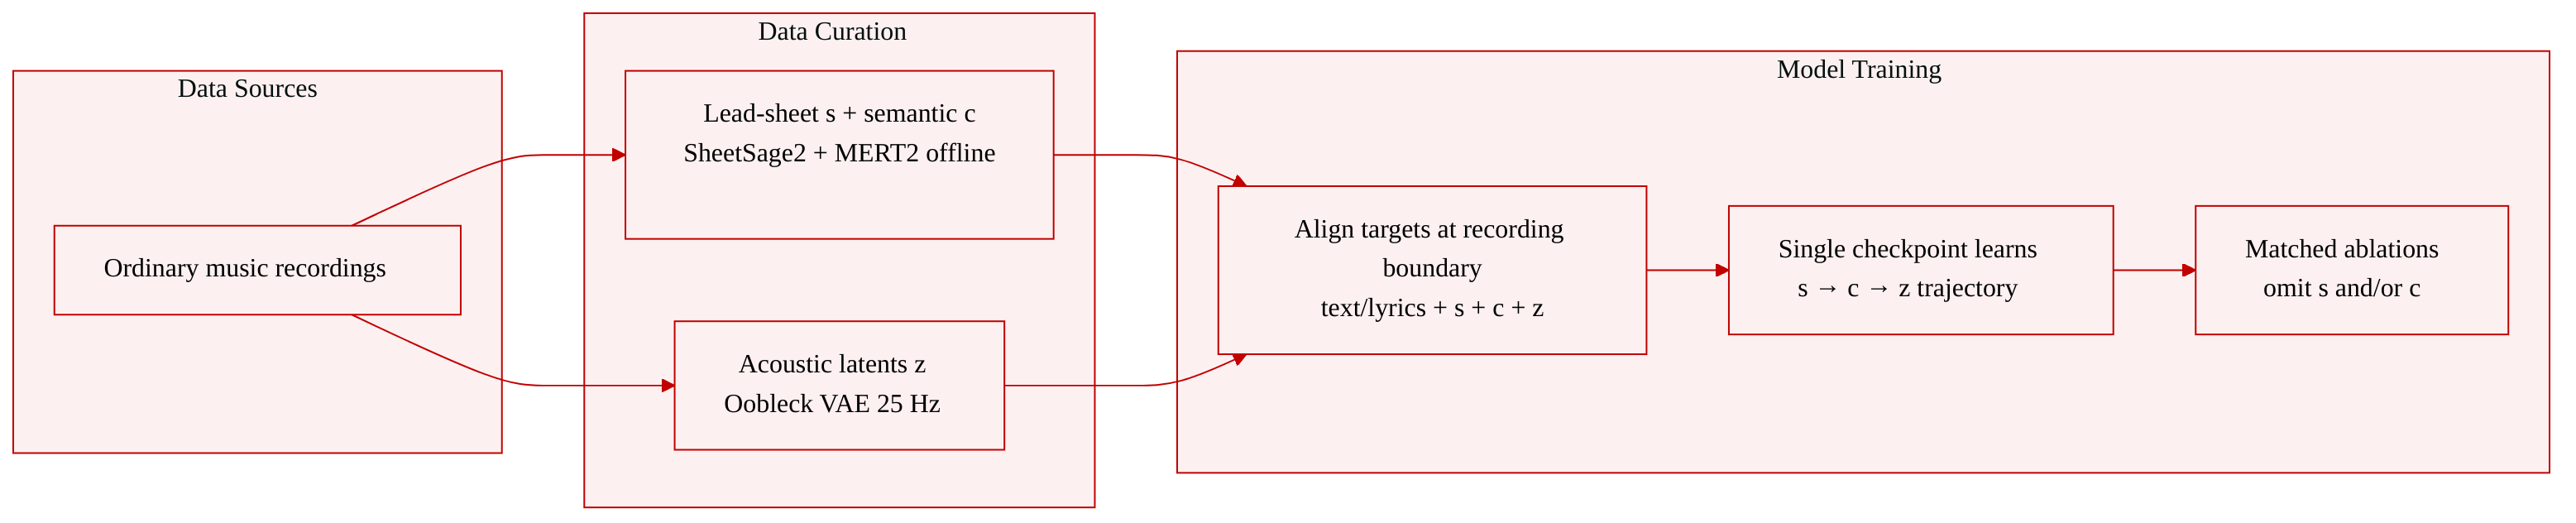
The authors build supervision from ordinary music recordings. For each training recording x, three frozen target constructors produce aligned views: a symbolic lead-sheet s, compact semantic tokens c, and continuous acoustic latents z.
-
Composition and sources: The excerpt describes supervision derived from training recordings, but it does not name the underlying corpora, dataset sizes, or filtering rules. The focus is on how each recording is converted into aligned symbolic, semantic, and acoustic targets.
-
Target details:
- s: lead-sheet transcription from SheetSage2, using bidirectional full-song context.
- c: compact semantic tokens from a separate MERT2 tokenizer branch with causal self-attention, following Qwen-Music and intended for autoregressive prediction.
- z: continuous acoustic latents from an Oobleck variational autoencoder trained separately after Stable Audio Open. Its convolutional encoder compresses 48-kHz stereo audio by 1,920 times into a 64-dimensional bottleneck at 25 Hz.
-
How the data is used: Each training example concatenates text and lyric conditions with the available symbolic and semantic targets, then aligns the acoustic latent sequence at the recording boundary. Symbolic tokens share the text vocabulary, semantic IDs occupy a disjoint range, and acoustic latents remain continuous. This sequence format lets a single checkpoint learn the complete s→c→z trajectory. Matched ablations can omit s, c, or both.
-
Processing details: The target constructors operate offline and are frozen. The provided material does not specify cropping strategy, metadata construction, training split, or mixture ratios beyond the aligned sequence layout.
Method
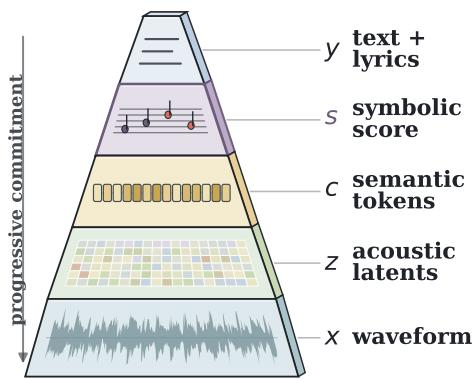
YuE2 represents music composition explicitly and progressively realizes it through three representations: symbolic composition s, semantic tokens c, and continuous acoustic latents z. The model factorizes generation as pθ(s,c,z∣y)=pθ,AR(s,c∣y)pθ,NAR(z∣y,s,c), where y denotes text and lyrics. The sparse symbolic sequence s carries human-readable decisions, the 25-Hz semantic sequence c supplies a dense musical trajectory, and the 25-Hz latent sequence z retains acoustic detail for a 48-kHz stereo decoder.
To construct aligned training targets from recordings, the authors leverage frozen analysis paths. For symbolic targets, they use SheetSage2, an autoregressive transcriber that recovers an editable lead sheet. As shown in the figure below:
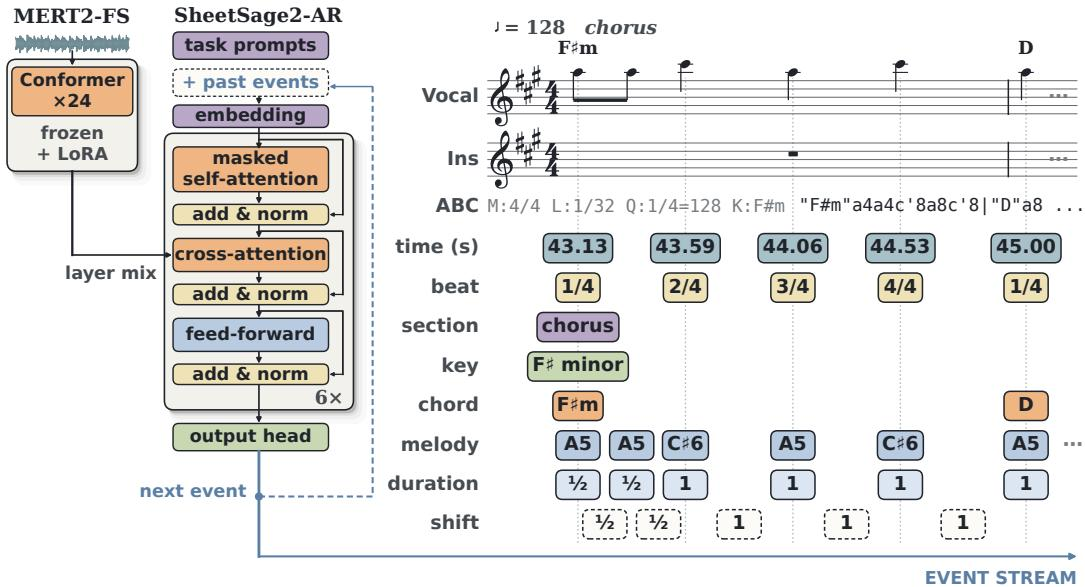
SheetSage2-AR uses a full-context MERT2-FS encoder with a frozen backbone and trainable low-rank adapters, feeding a six-layer autoregressive RoFormer decoder to generate a chronological event sequence, which is converted to ABC notation.
For semantic targets, the authors develop MERT2. The process begins with Multi-View Target Synthesis, where frozen MuQ and Qwen2-Audio-Instruct encoders map audio to time-aligned features, combined via a shared bottleneck and discretized by a four-level residual vector quantizer. As shown in the figure below:
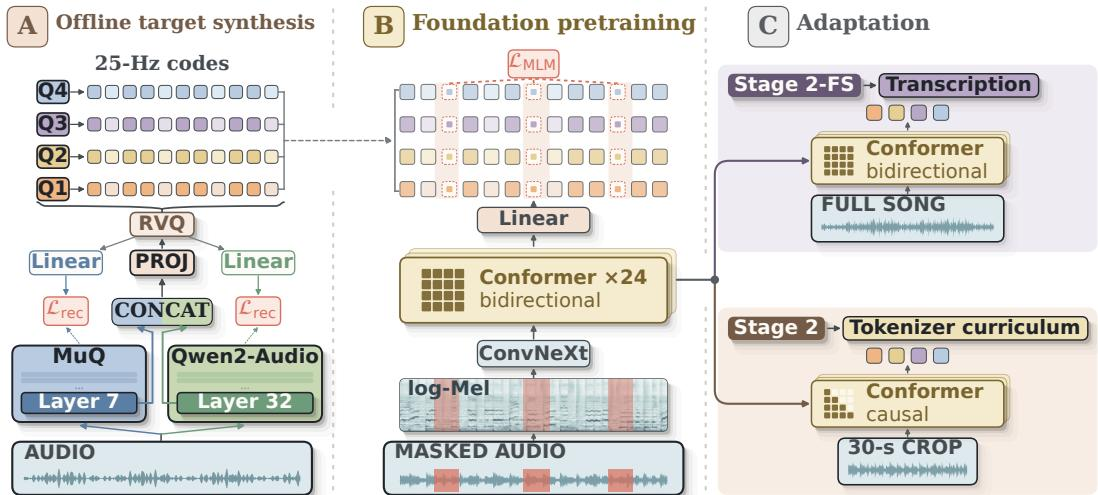
A new audio encoder is then trained in Stage 1 (Foundation Pretraining) to predict these codes from masked audio using a ConvNeXt frontend and a 24-layer bidirectional Conformer. Subsequent adaptation branches into full-song transcription and semantic tokenization. The tokenizer branch undergoes Causal Adaptation, Supervised Fine-Tuning, and Semantic Quantization. As shown in the figure below:
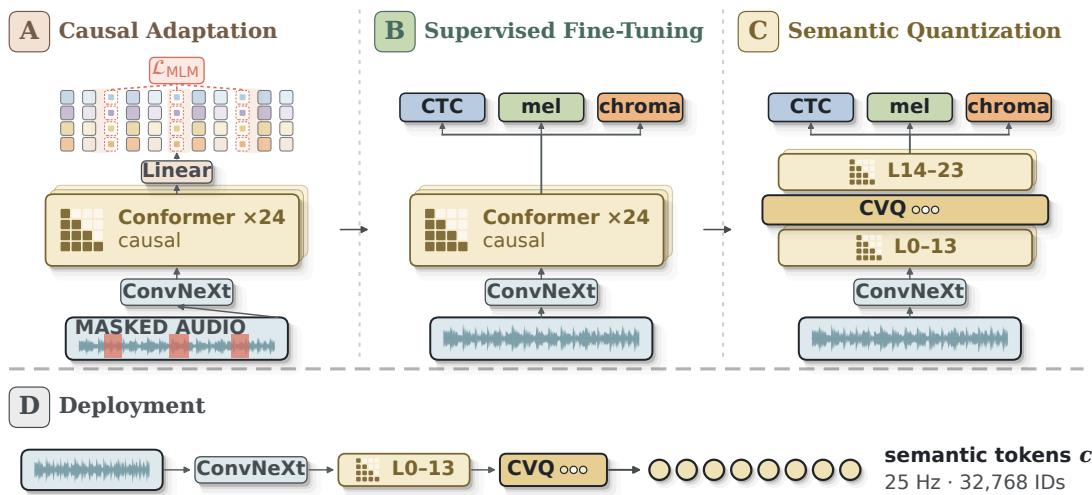
Causal Adaptation switches the Conformer to causal attention. Supervised Fine-Tuning adds lyric connectionist temporal classification and mel and chroma reconstruction. Semantic Quantization inserts a 32,768-entry clustered vector quantizer between layers 13 and 14. Deployment retains the frontend, causal Conformer layers 0 to 13, and the quantizer to emit semantic IDs at 25 Hz.
The main YuE2 model implements both autoregressive and non-autoregressive computations in a single 28-layer backbone inspired by Mixture-of-Transformers. Each layer features separate AR and NAR normalization, query, key, value and output projections, and multilayer-perceptron experts, while sharing the positional scheme and participating in one attention computation. A hybrid mask ensures discrete predictions cannot read acoustic targets, while acoustic states attend bidirectionally to all text, score, and semantic tokens. At acoustic positions, a projection of the noisy latent replaces the token embedding, and a linear head predicts the flow velocity.
The AR stream is trained with next-token cross-entropy over symbolic and semantic spans:
LAR=−∣A∣1i∈A∑logpθ(wi∣w<i)For acoustic learning, conditional flow matching minimizes:
LFM=64∣Z∣1i∈Z∑∥vθ(zt,t,y,s,c)i−(ϵi−z0,i)∥22where zt=(1−t)z0+tϵ. The joint objective is L=0.25LAR+LFM. The authors train on approximately 346,000 hours of music, packing whole songs into a 24,576-position context. They sample from four tasks during training, including settings that omit the score, semantic tokens, or both, enabling the model to generate with varying available inputs and supporting classifier-free guidance.
Experiment
The experiments evaluate YuE2's full-song generation on WildSongBench against public and proprietary systems using automatic metrics and expert listening, and isolate the contributions of symbolic planning and unified generation. They find that YuE2 achieves frontier-competitive song quality, that explicit melody-and-chord planning improves perceived overall quality and musicality, that a unified Mixture-of-Transformers outperforms a separate language model plus diffusion design, and that the score is realized in audio and supports controlled local and global edits while preserving unedited content. Further studies show zero-shot cover generation preserves work identity when conditioned on the full score, agentic editing enables iterative musical revision, and the underlying MERT2 and SheetSage2 models lead music understanding and full-song transcription benchmarks.
Across 192 WildSongBench prompts, Suno variants lead the proprietary comparison on most musical quality, production quality, text alignment, and lyric accuracy measures. Suno v5 leads SongBench musicality and average as well as both text alignment metrics, while Suno v4.5 leads SongEval, production quality, and lyric accuracy. MiniMax Music 2.6 trails the Suno systems across most metrics and shows much weaker lyric intelligibility. Suno v5 records the highest SongBench musicality and average among compared systems, and also leads MuLan and AllMusicCaps text alignment. Suno v4.5 achieves the best SongEval musicality and average, the top AudioBox production quality, and the lowest phoneme error rate. Suno v5.5 is the runner-up on SongBench average, AudioBox production quality, MuLan alignment, Q3O prompt adherence, and has the second-lowest phoneme error rate. Suno v6 has the highest Q3O prompt adherence despite lower SongBench musicality than several other Suno versions. MiniMax Music 2.6 posts the weakest SongBench, SongEval, MuLan, and AllMusicCaps scores and a substantially higher phoneme error rate.
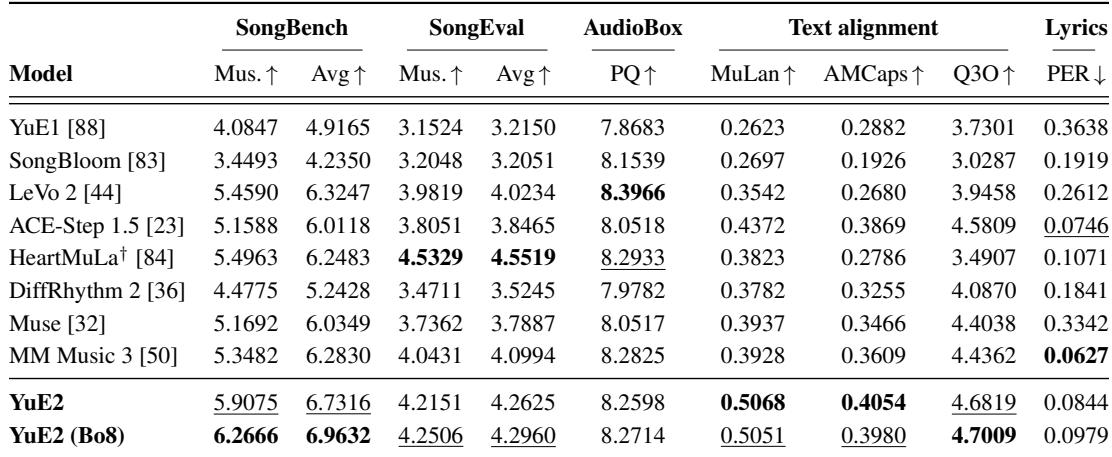
Across the public systems compared on WildSongBench, ACE-Step 1.5 shows the strongest text alignment and lyric accuracy, with the highest Q3O, MuLan, and AMCaps scores and the lowest phoneme error rate. HeartMuLa leads on musicality, achieving the best SongBench Musicality and SongEval Musicality and average scores, while LeVo 2 ranks best on SongBench average and AudioBox production quality. YuE1 and SongBloom generally trail on musical and text-alignment metrics, though SongBloom retains relatively strong production quality. ACE-Step 1.5 leads prompt adherence and lyric accuracy among the compared public systems, with the best Q3O, MuLan, AMCaps, and PER results. HeartMuLa achieves the top SongBench Musicality and SongEval Musicality and average scores, while its phoneme error rate is second lowest. LeVo 2 records the strongest SongBench average and AudioBox production quality, but its text alignment and lyric accuracy metrics are weaker than ACE-Step 1.5. YuE1 and SongBloom generally score lower on musical and text-alignment metrics, although SongBloom posts relatively high production quality.
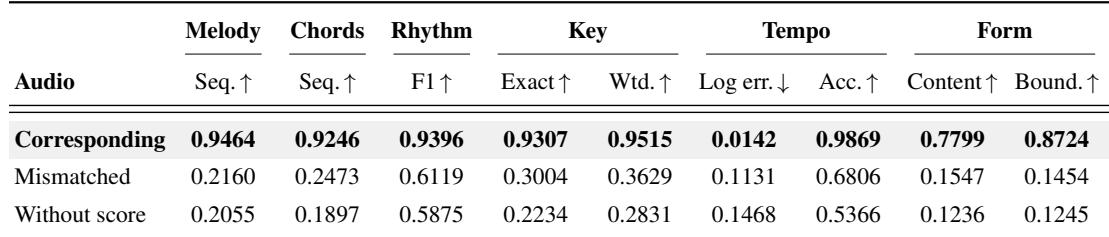
Audio generated from the corresponding score shows strong agreement with the notated composition across melody, chords, rhythm, key, tempo, and form. In contrast, audio generated from a mismatched score or without a score shows much lower consistency on the same prompt and lyrics. This gap indicates that the observed agreement is specific to the particular score being realized. Corresponding score audio achieves high consistency across melody, chords, rhythm, key, tempo, and section-boundary measures. Mismatched-score audio and audio without a score perform far below corresponding audio, especially on melodic, harmonic, and formal similarity. Tempo error is lowest for corresponding audio, and tempo accuracy is substantially higher than both controls. Key and rhythm agreement also decline sharply when the audio does not follow its own generated score.
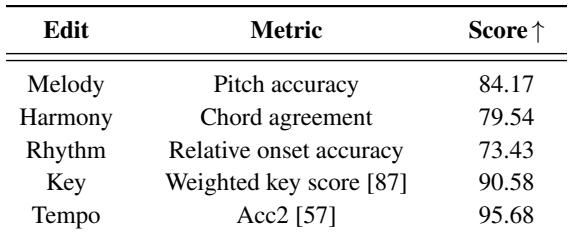
Key and tempo edits show the strongest adherence among the five score-edit types, while rhythm edits are the least accurately followed. Melody and harmony adherence fall in between, with melody pitch accuracy above harmony chord agreement. The benchmark reports these adherence scores separately from content preservation, focusing here on how precisely the edited musical attributes are realized. Tempo edits achieve the highest adherence score among the evaluated edit types, followed by key edits. Rhythm edits show the lowest adherence, indicating relative onset timing is the most challenging local change to follow. Melody pitch accuracy exceeds harmony chord agreement, though both are below key and tempo adherence.
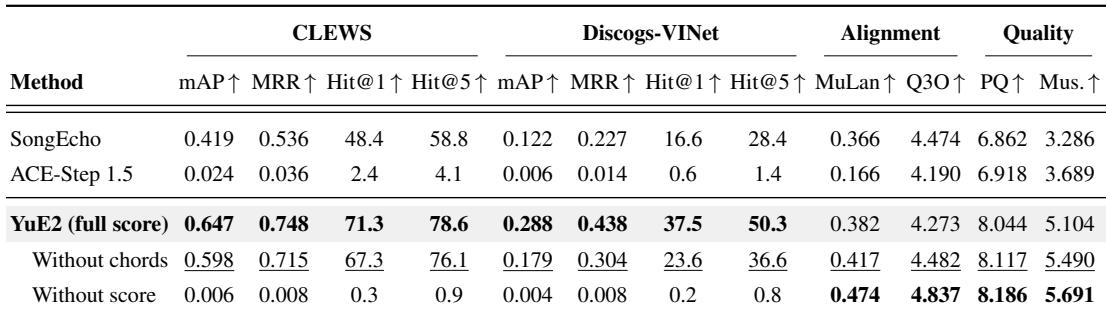
YuE2 with the full score outperforms both evaluated cover-generation baselines across all eight retrieval measures in the zero-shot SHS100K evaluation, despite having no cover-specific training. Score conditioning is essential for preserving work identity, as removing chords reduces retrieval performance and removing the score entirely causes retrieval to drop to near zero. The full-score YuE2 configuration leads SongEcho and ACE-Step 1.5 on every retrieval metric without cover-specific training. Removing chord information from the score still retains clear retrieval advantages over both cover baselines. Without any score, retrieval performance collapses to near zero, showing that score conditioning is central to preserving work identity.
The paper evaluates music generation systems on WildSongBench, comparing proprietary Suno variants and public models. Suno systems generally lead the proprietary comparison on musical quality, production quality, text alignment, and lyric accuracy, while among public models ACE-Step 1.5 excels at text alignment and lyric accuracy and HeartMuLa or LeVo 2 lead musicality and production quality. Controlled experiments confirm that score-conditioned generation strongly preserves musical attributes and work identity, with full-score YuE2 outperforming cover baselines, and that score edits are followed more reliably for key and tempo than for rhythm. Overall, score conditioning is shown to be essential for accurate score alignment and retrieval of work identity.