Command Palette
Search for a command to run...
VoxMem: Benchmarking des multimodalen Gedächtnisses in großen Audio-Sprachmodellen
VoxMem: Benchmarking des multimodalen Gedächtnisses in großen Audio-Sprachmodellen
Yang Xiao Vidhyasaharan Sethu Eun-Jung Holden Ting Dang
Zusammenfassung
Gesprochene Dialogsysteme müssen Informationen aus früheren Interaktionen wieder abrufen (d. h. Gedächtnis); relevante Informationen in gesprochener Sprache gehen jedoch über das Gesagte hinaus: Wer hat gesprochen, wie wurde gesprochen und was war hörbar – Informationen, die nur im Audiosignal vorliegen und sich nicht aus einem Transkript rekonstruieren lassen. Über die Frage, was erinnert werden soll, hinaus verlangt Gedächtnis zudem unterschiedliche Operationen: das Abrufen einer einzelnen Tatsache, das Integrieren von Evidenz über mehrere Gesprächsbeiträge hinweg und das Verfolgen eines sich verändernden Zustands. Reale Interaktionen entfalten sich zudem über mehrere Sitzungen hinweg, d. h. Informationen sammeln sich über getrennte Episoden an und nicht in einer einzigen kontinuierlichen Aufzeichnung. Bestehende Benchmarks greifen in allen drei Dimensionen zu kurz: Sie konzentrieren sich überwiegend auf lexikalische Inhalte, verwenden begrenzte und ad hoc definierte Gedächtnisoperationen und behandeln Gedächtnis als Problem innerhalb einer einzelnen Sitzung. Wir argumentieren, dass eine prinzipiengeleitete Gedächtnisevaluation erfordert, die zu behaltende akustische Evidenz und die darauf angewendeten Operationen gemeinsam zu charakterisieren; wir führen eine Taxonomie entlang dieser beiden Achsen ein. Aufbauend auf dieser Taxonomie präsentieren wir VoxMem: 3.196 Evaluationsinstanzen über 34.743 gesprochene Sitzungen (177 Stunden), die vier akustische Evidenztypen (sprachliche Semantik, Sprecheridentität, paralinguistische Hinweisreize, Umgebungsgeräusche) mit vier Gedächtnisoperationen (Informationsextraktion, sitzungsübergreifendes Schlussfolgern, zeitliches Nachverfolgen und Antwortverweigerung) kreuzen, in sitzungsübergreifenden Historien verankert sind und über Kontextbudgets von 8K bis 64K Token stratifiziert sind. Bei der Evaluierung von 15 LALMs überschreitet kein Modell 40 % bei 32K Token. Modelle behalten das Gesagte weitaus besser als Informationen darüber, wer etwas gesagt hat, wie es gesagt wurde oder was hörbar war; diese Lücke vergrößert sich bei komplexen Operationen, wächst mit der Länge der Vorgeschichte und äußert sich in qualitativ unterschiedlichen Fehlermodi je nach Evidenztyp. VoxMem soll eine Grundlage bieten, um Fortschritte im gesamten Spektrum des gesprochenen Konversationsgedächtnisses zu messen und voranzutreiben.
One-sentence Summary
Researchers from the University of Melbourne and the University of New South Wales introduce VoxMem, a benchmark of 3,196 evaluation instances over 34,743 spoken sessions that applies a taxonomy jointly characterizing acoustic evidence and memory operations to evaluate 15 large audio language models across 8K to 64K token contexts, finding that none exceeds 40% at 32K and that models retain lexical content far better than speaker identity, paralinguistic cues, and environmental sound, exposing gaps beyond lexical memory.
Key Contributions
- Introduces a two-dimensional taxonomy for spoken conversational memory that jointly characterizes acoustic evidence to be retained, including speech semantics, speaker identity, paralinguistic cues, and environmental sound, alongside memory operations such as information extraction, multi-session reasoning, temporal tracking, and answer refusal.
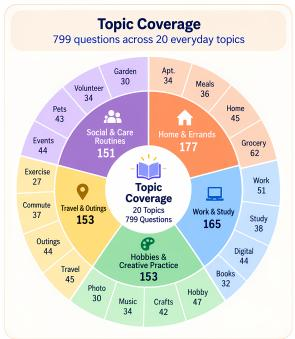
- Presents VoxMem, a multi-session benchmark with 3,196 quality-controlled instances over 34,743 spoken sessions totaling 177 hours, stratified across context budgets from 8K to 64K tokens and built from evidence, competing, and unrelated sessions across 20 topic families.
- Reports a systematic evaluation of 15 LALMs showing that no model exceeds 40% at 32K context, that lexical content is retained much better than speaker identity, paralinguistic cues, or environmental sounds, and that failure modes differ qualitatively by evidence type, such as misattribution for speaker identity and lost acoustic cues for paralinguistic information.
Introduction
Large audio language models (LALMs) are enabling longer spoken interactions across separate sessions, making long-term memory a critical requirement. However, existing spoken-memory benchmarks lack a principled taxonomy of what acoustic evidence must be retained and which memory operations are needed, and they mostly evaluate isolated recordings or continuous dialogues rather than multi-session histories. They also tend to confound history length with question difficulty and evidence type. The authors introduce VoxMem, a multi-session benchmark organized along two axes: acoustic evidence, encompassing speech semantics, speaker identity, paralinguistic cues, and environmental sound, and memory operation, comprising information extraction, multi-session reasoning, temporal evolution tracking, and answer refusal. VoxMem contains 3,196 quality-controlled instances over 34,743 spoken sessions, spanning four context budgets from 8K to 64K tokens, and supports controlled evaluation of how spoken memory degrades as context length scales.
Dataset
VoxMem Benchmark Dataset
-
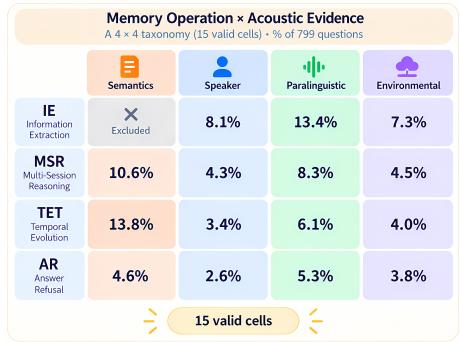
Scope and taxonomy. VoxMem is a spoken conversational memory benchmark organized around two dimensions: acoustic evidence and memory operations. Acoustic evidence covers speech semantics, speaker identity, paralinguistic cues, and environmental sound. Memory operations cover information extraction, multi-session reasoning, temporal evolution tracking, and answer refusal. The benchmark includes 15 evaluation scenarios, leaving out information extraction over speech semantics.
-
Data composition. Each multi-session history contains three session types. Evidence sessions hold the information required to answer a question. Haystack sessions add plausible but misleading content on the same topic, preventing the model from answering by topic matching alone. Filler sessions contain unrelated conversation and extend the history to the target length. Every item begins with a structured plan specifying the question, gold answer, and required evidence before dialogue or audio is written.
-
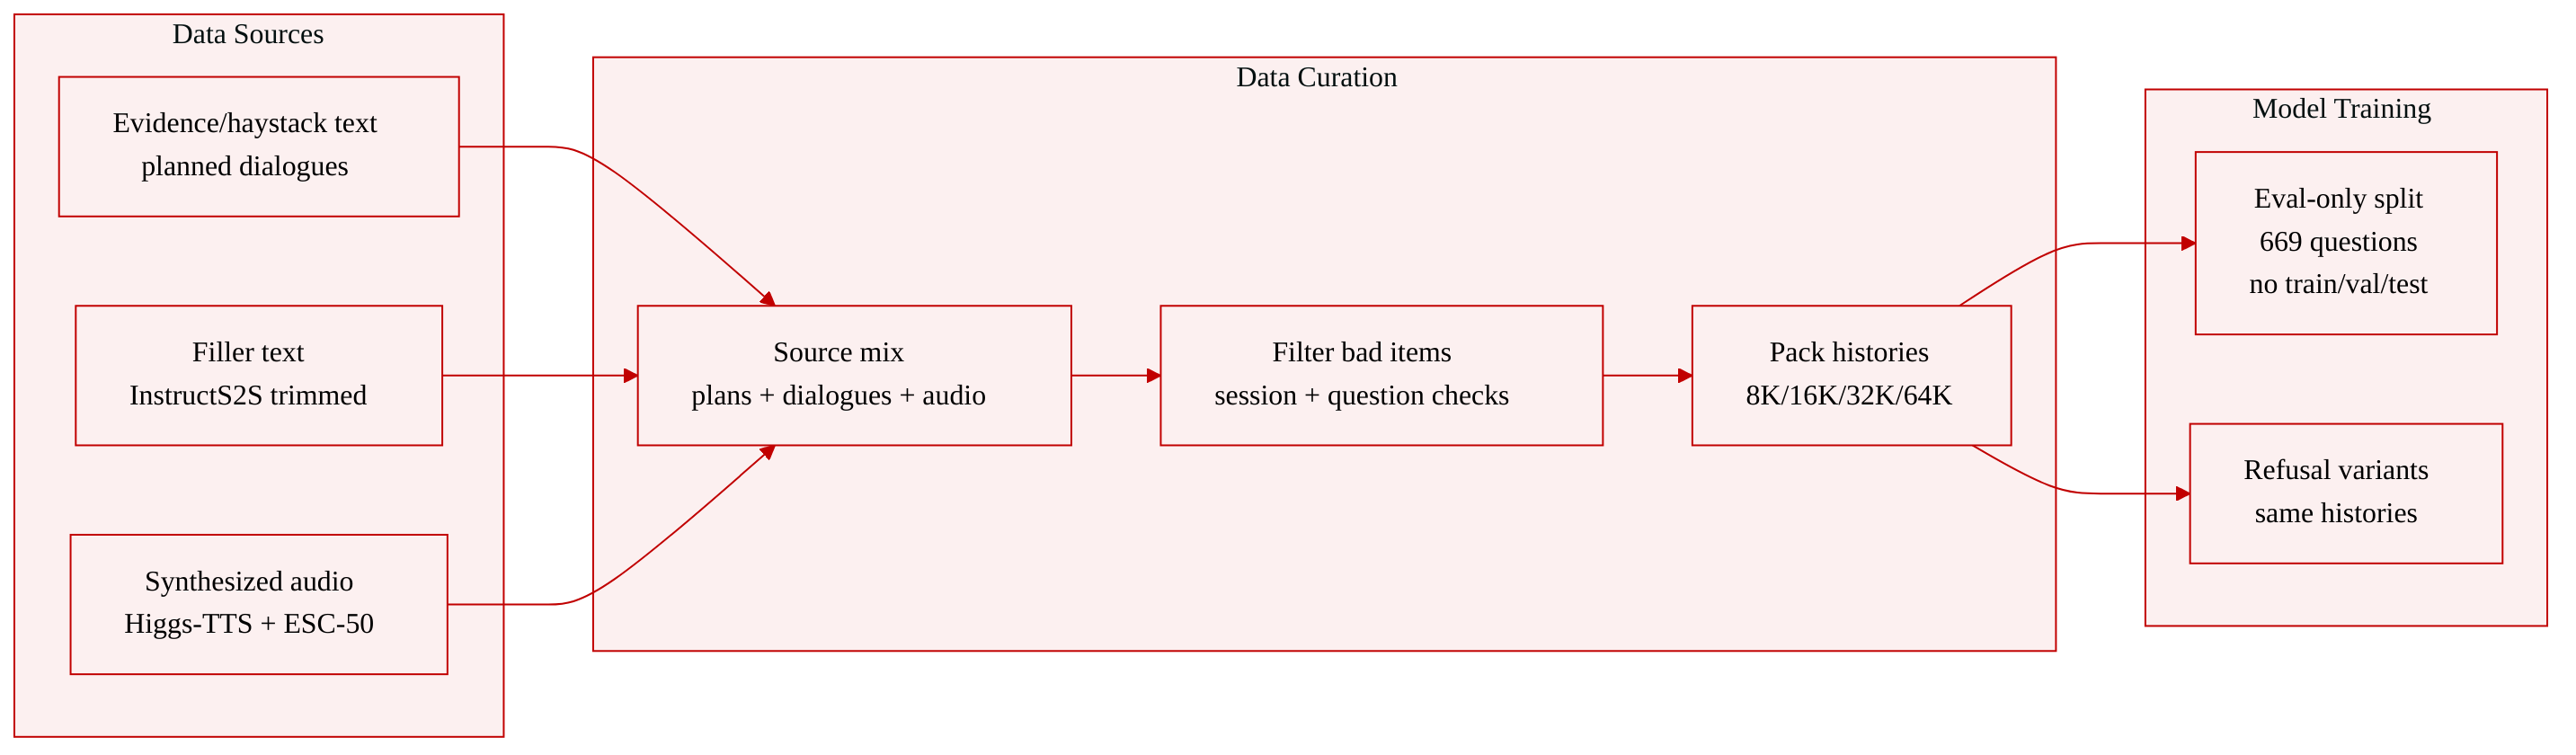
Text and audio sources. Evidence and haystack dialogues are written as text first. Filler text is taken from InstructS2S and trimmed to match VoxMem session lengths. User turns are synthesized with Higgs-TTS-3, using a fixed VCTK voice per user. Paralinguistic cues are introduced through style controls, and environmental sounds from ESC-50 are mixed in at 10dB SNR. Questions are rendered into natural language using Gemini-3.7-Flash and GPT-5.6-Luna. In the final input, user turns are audio, assistant turns are text, and session boundaries and timestamps are included.
-
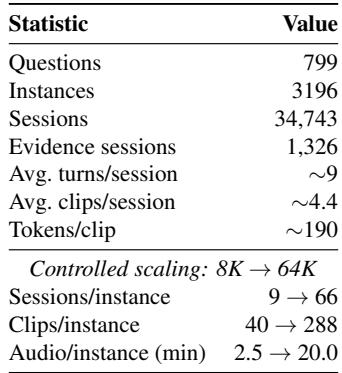
Scale. The construction pipeline generates more than 30,000 plans. The final answerable set contains 669 questions, with answer-refusal variants derived from existing answerable questions. Each answerable question is embedded in histories at four lengths: 8K, 16K, 32K, and 64K tokens measured with a Whisper encoder, approximately 2.5 to 20 minutes of audio. Longer histories strictly extend shorter ones, and evidence and haystack sessions are distributed uniformly except where temporal order matters for temporal evolution tracking.
-
Filtering and quality control. Session-level checks verify transcript fidelity, speaker consistency, target-cue perceptibility, and deterministic consistency of paired paralinguistic and environmental renditions. Question-family checks verify that evidence uniquely determines the answer, the question requires the intended operation, audio-native questions cannot be answered from the transcript, and full histories contain no leaked or alternative answers. Items that fail are revised and rechecked or discarded. A text-only classifier also cannot reliably distinguish evidence from haystack sessions, confirming that surface patterns do not reveal the answer.
-
Usage. VoxMem is an evaluation-only benchmark, not a training set. It is designed to evaluate LALMs that accept audio input but do not generate speech. Every model receives the same history with audio user turns and text assistant turns, and performance is compared across the four context lengths so that changes can be attributed to growing context rather than changing evidence.
Method
The authors construct the VoxMem benchmark along a two-dimensional taxonomy, utilizing a multi-session conversation structure composed of three distinct session types to ensure both naturalism and controlled evaluation scenarios. Evidence sessions contain the specific information required to answer a query. Haystack sessions introduce plausible but misleading content on the same topic, forcing the model to reason over the full acoustic and semantic context rather than relying on topic matching. Filler sessions consist of ordinary conversations unrelated to the question, serving to extend the history to the target context length.
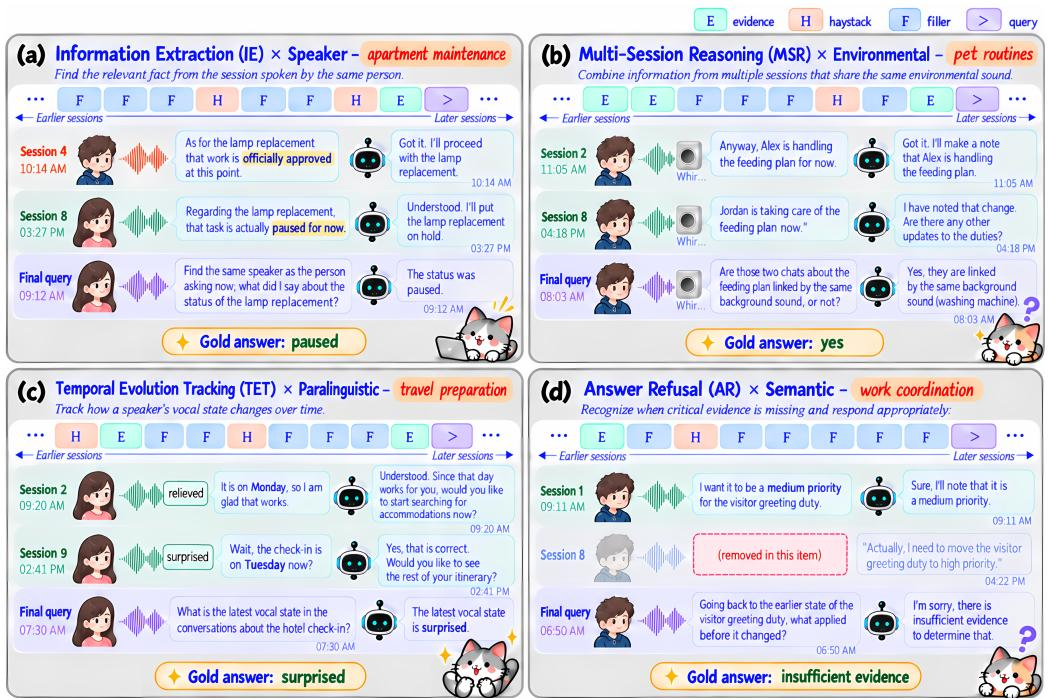
As shown in the figure below, this structure is applied across different memory types. For instance, in an Information Extraction scenario involving speaker identity, the evidence session contains the answer spoken by the querying user, while a haystack session features a different user discussing the same topic with different content.
The construction of every item follows a rigorous pipeline, as illustrated in the framework diagram.
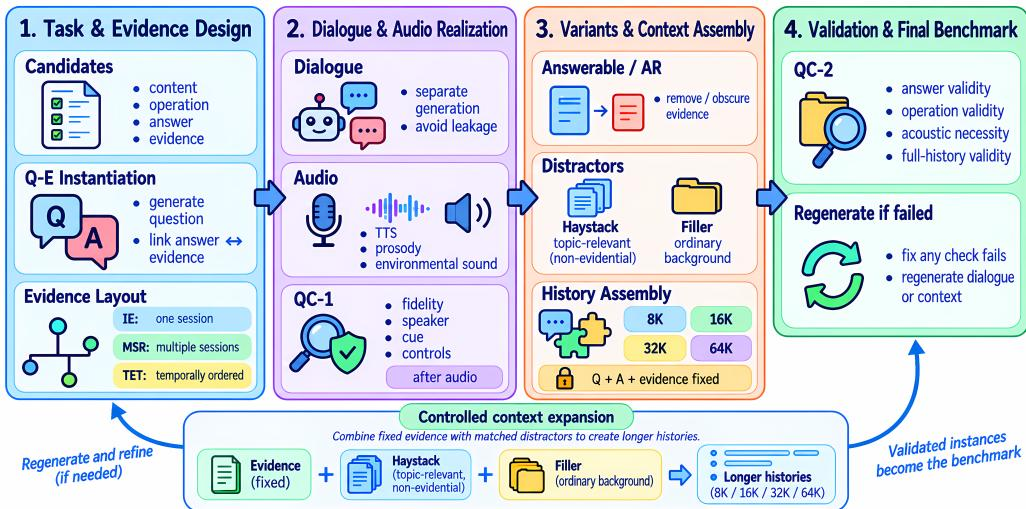
The process begins with Task and Evidence Design, where a structured plan specifies the question, gold answer, and required evidence. Evidence is distributed across sessions based on the operation type: a single session for Information Extraction, multiple for Multi-Session Reasoning, and an ordered sequence for Temporal Evolution Tracking. During the Dialogue and Audio Realization phase, evidence sessions are written as user-assistant dialogues. To prevent answer leakage, the two sides are authored independently. User turns are synthesized using a TTS system with fixed voices, and paralinguistic cues or environmental sounds are introduced.
In the Variants and Context Assembly stage, the authors create Answerable and Answer Refusal variants. Haystack and filler sessions are added as distractors. Histories are assembled at four lengths (8K, 16K, 32K, and 64K tokens) by strictly extending shorter histories with more distractors, ensuring the question and evidence remain identical. Finally, the Validation and Final Benchmark stage involves multi-stage quality control.
The authors implement a two-level quality control process. Session-level validation targets failures within a single session, verifying transcript fidelity, speaker consistency, and the perceptibility of acoustic cues. Question-family validation targets failures emerging in the full history. This includes checking answer and operation validity, ensuring acoustic necessity by rejecting questions answerable from text alone, and verifying full-history validity to ensure no leaked or alternative answers exist. Items failing these checks are revised and rechecked.
Experiment
The VoxMem benchmark evaluates spoken conversational memory across a two-dimensional taxonomy of acoustic evidence and memory operations, testing 15 large audio-language models on histories from 8K to 64K tokens with LLM-judged short answers. The experiments show that current models remain unreliable, with no model exceeding 40% overall accuracy at 32K, and that non-lexical acoustic information such as speaker identity, paralinguistic cues, and environmental sounds is substantially harder to retain than speech semantics. Memory operation difficulty depends on the evidence type, while refusal patterns indicate that models often abstain because of weak acoustic processing rather than genuine awareness of missing evidence. Longer histories reduce access to the same evidence, with speaker and environmental memory degrading fastest and error profiles differing across evidence types and operations.
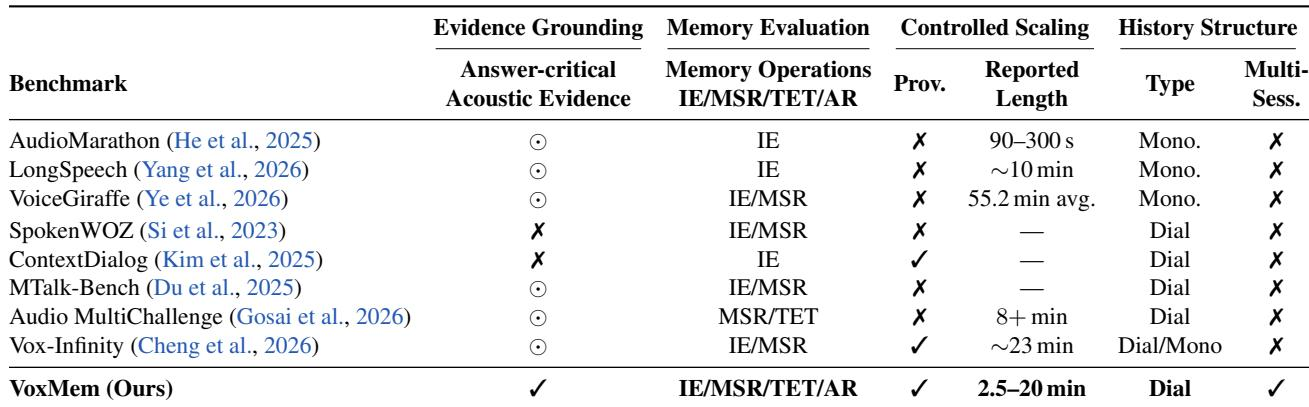
The comparison shows that existing spoken-memory benchmarks cover acoustic evidence and memory operations only partially. Most emphasize linguistic content or selected acoustic cues and evaluate only retrieval or integration, while temporal evolution tracking and answer refusal are absent. The benchmarks also rely on single-session monologues or dialogues, with controlled scaling and evidence provenance rarely reported. Prior benchmarks rarely test speaker identity, paralinguistic cues, or environmental sound; several focus only on lexical content. Memory operation coverage is narrow: all listed benchmarks include information extraction, a few add multi-session reasoning, and none include temporal evolution tracking or answer refusal. All listed benchmarks use single-session histories, with no multi-session evaluation. Evidence provenance is missing for most listed benchmarks, with only one dialogue benchmark providing it.
The evaluation taxonomy is uneven, with paralinguistic and semantic questions dominating and answer refusal less common. Experimental results show that longer histories reduce access to previously available evidence, especially for speaker and environmental sound memory, while paralinguistic understanding remains low at all context lengths. Error attribution also reveals distinct failure modes across operations and evidence types, such as binding errors for speaker information and localization errors for temporal evolution. The taxonomy is unevenly distributed: paralinguistic and semantic questions are the most common evidence categories, with answer refusal less frequent across all operations. As history grows, models retain less access to evidence, and speaker identity and environmental memory degrade fastest; paralinguistic cues remain difficult at every context length.
The benchmark includes several hundred questions and several thousand instances drawn from tens of thousands of sessions, with a smaller subset of evidence sessions. Sessions are relatively compact, averaging about nine turns and a few clips per session. Controlled context expansion from 8K to 64K shows accuracy declines as history grows, with the steepest relative drops for speaker identity and environmental sound. The dataset contains 799 questions and 3,196 instances, but only a small fraction of sessions serve as evidence sessions. Longer context windows reduce accuracy across evidence types, with speaker and environmental memory degrading faster than speech semantics and paralinguistic cues.
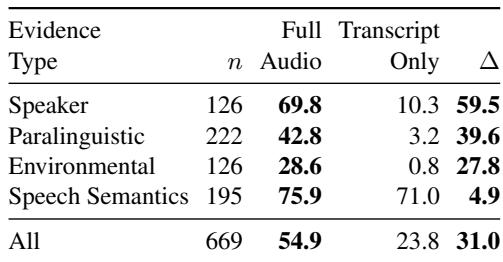
For Gemini-3.7-Flash on answerable acoustic-memory questions, replacing full audio with transcript-only turns causes a large overall accuracy drop, confirming reliance on non-text acoustic cues. The impact is highly uneven: speech semantics remains relatively stable, while speaker identity, paralinguistic cues, and environmental sounds lose most of their accuracy. Overall full-audio accuracy falls from about 55 percent to below a quarter with transcript-only input. Speech semantics is least affected, while speaker identity drops roughly 60 points to just over 10 percent, and paralinguistic and environmental scores fall near zero.
Spoken-memory accuracy declines as reference history grows, with both proprietary and open-weight models losing accuracy between 8K and 32K. The drop is steeper for speaker identity and environmental sound than for speech semantics and paralinguistic cues. Paralinguistic cues show the lowest absolute accuracy but decline at a rate similar to speech semantics, indicating that baseline difficulty and history sensitivity are distinct failure modes. At 64K, speech semantics and paralinguistic cues retain about 70% of their 8K accuracy, while speaker identity and environmental sound retain about 63% to 67%. Proprietary models score above open-weight models at 8K and 32K, but both groups lose accuracy as history grows. Speaker errors are most often binding failures, whereas paralinguistic errors are dominated by localization failures and environmental errors split between localization and unsupported answers.
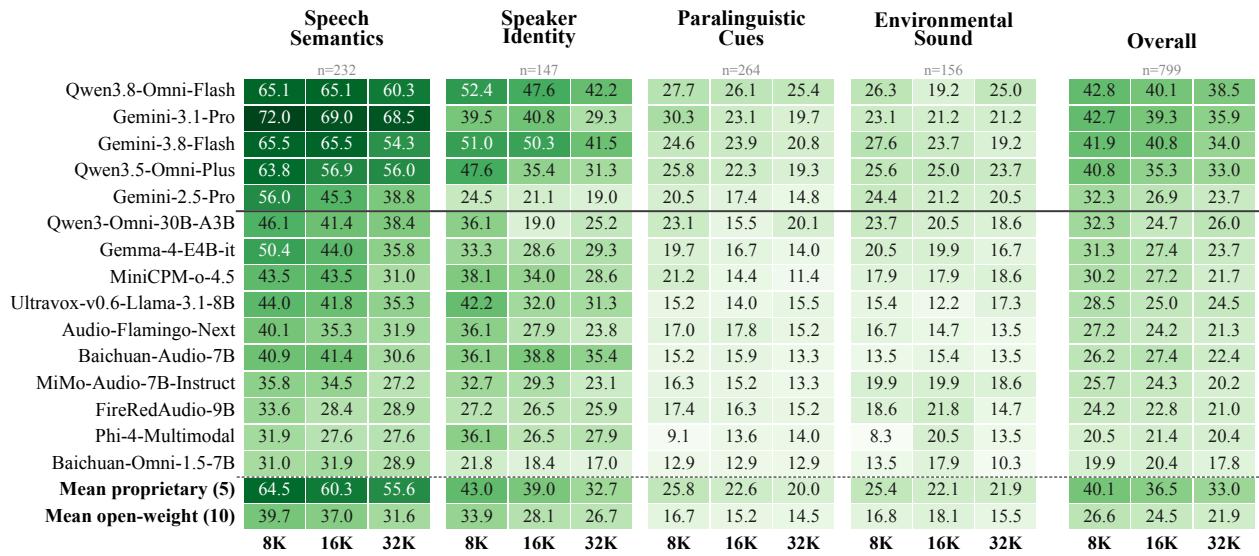
Existing spoken-memory benchmarks cover acoustic evidence and memory operations only partially, often missing speaker identity, paralinguistic and environmental cues, temporal evolution tracking, answer refusal, multi-session histories, and evidence provenance. The benchmark's controlled context expansion shows that both proprietary and open-weight models lose access to earlier evidence as history grows, with speaker identity and environmental sound degrading more steeply than speech semantics, while paralinguistic cues remain difficult across all context lengths. Replacing audio with transcripts causes a large overall drop and leaves speaker, paralinguistic, and environmental performance near zero, confirming that models rely on acoustic cues beyond text. Error attribution reveals distinct failure modes, including binding errors for speaker information and localization errors for paralinguistic and temporal evolution questions.