Command Palette
Search for a command to run...
FuseReg: Regularisierung der Layer-Fusion mildert die Rekonstruktions-Generierungs-Lücke in Repräsentations-Autoencodern
FuseReg: Regularisierung der Layer-Fusion mildert die Rekonstruktions-Generierungs-Lücke in Repräsentations-Autoencodern
Zusammenfassung
Repräsentations-Autoencoder (RAEs) verwenden Merkmale eines vortrainierten visuellen Encoders als latente Repräsentationen für Rekonstruktion und Diffusion wieder und integrieren so starke visuelle Repräsentationen in die Bildgenerierung. Allerdings müssen RAEs weiterhin entscheiden, welche Encoder-Schichten den gemeinsamen latenten Raum für den Generator und den Pixel-Decoder bilden. Diese Wahl ist mit einem Zielkonflikt verbunden. Flachere Schichten neigen dazu, feine Pixeldetails besser zu erhalten, während tiefere Schichten tendenziell bessere Generierungsmetriken liefern. Eine feste heuristische Layer-Fusion koppelt daher zwei Stufen, die von unterschiedlichen Informationen profitieren. Wir stellen FuseReg vor, das die heuristische Merkmalsauswahl durch Training über zufällige Teilmengen von Encoder-Schichten ersetzt. Wir analysieren den zugrunde liegenden Mechanismus theoretisch: Das Stichprobenziehen von Teilmengen bestraft die Empfindlichkeit gegenüber Diskrepanzen zwischen Schichten explizit. Auf ImageNet-256 mit DINOv3-L rekonstruiert ein einzelner FuseReg-Decoder aus vollständigen, spärlichen und einlagigen Fusionen ohne erneutes Training und erreicht einen höheren PSNR als Decoder, die auf feste Fusionen spezialisiert sind. Diese Flexibilität kommt auch der Generierung zugute: Allein der Austausch des Decoders reduziert die ungeführte gFID um 27 % bei einem unveränderten RAEv2-DiT-XL-Generator. Das gleiche Regularisierungsprinzip lässt sich auf das Diffusionstraining übertragen; die gemeinsame Regularisierung beider Stufen reduziert die ungeführte gFID bei DiT-Base um 29 %. Diese Ergebnisse zeigen, dass das Training nachgelagerter Modelle auf Robustheit gegenüber Layer-Fusionen die Rekonstruktions-Generierungs-Lücke verringert, ohne den vortrainierten Encoder zu verändern.
One-sentence Summary
Researchers at USC PSI Lab and collaborators propose FuseReg, which regularizes representation autoencoders by training on random subsets of encoder layers to penalize cross-layer disagreement, enabling a single decoder to reconstruct from full, sparse, and single-layer fusions without retraining while improving PSNR and reducing unguided gFID by up to 29%.
Key Contributions
- FuseReg is a layer-fusion regularizer that trains representation autoencoder decoders and generators on normalized fusions of randomly sampled encoder layers, replacing fixed heuristic layer selection.
- A theoretical analysis shows that randomized subset sampling preserves the full-layer mean while making cross-layer disagreement an explicit regularization penalty and establishes a second-order separation from deterministic global fusion methods.
- On ImageNet-256 with DINOv3-L, a single FuseReg decoder reconstructs from full, sparse, and single-layer fusions without retraining and achieves higher PSNR than decoders specialized to fixed fusions; decoder replacement alone reduces unguided gFID from 3.01 to 2.21 at k=23, while joint regularization reduces DiT-Base gFID from 13.96 to 9.93.
Introduction
The authors work with representation autoencoders (RAEs), where a frozen visual encoder defines the latent space of a diffusion model but its hierarchical features must be collapsed into a single latent through layer fusion. This interface matters because the decoder reconstructs pixels from generated latents while the generator models the latent distribution, and prior fixed fusion choices such as RAEv2 create a reconstruction-generation gap: reconstruction favors shallow pixel-aligned layers, whereas diffusion favors deeper semantic layers. For example, in the DINOv3-L setting, expanding the fused subset from k=7 to k=23 improves reconstruction PSNR from 22.58 to 27.04 dB but worsens unguided gFID from 1.65 to 3.01. The authors introduce FuseReg, a layer-fusion regularization approach that trains the decoder and generator on randomly sampled, normalized subsets of encoder layers. This preserves the full-layer representation in expectation while reducing reliance on any single layer composition, yielding a single decoder that supports full, sparse, and single-layer fusions without retraining, and improving generation quality without architectural changes or additional computational cost.
Method
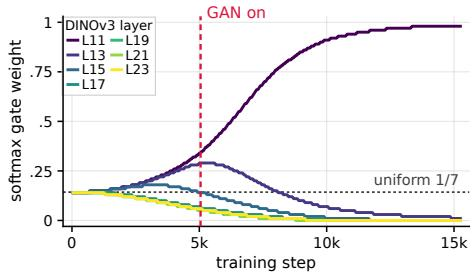
The authors address the limitations of fixed layer fusion in Representation Autoencoders by introducing FuseReg, a method that leverages randomized layer fusion as a regularization technique. In traditional setups, a fixed fusion rule or a learned global gate exposes downstream models to only a single layer composition during training. However, learned gates often fail to utilize deep semantic features effectively, instead collapsing to rely almost exclusively on shallow, pixel-aligned layers.
As shown in the figure below:
To overcome this dependency on fixed shortcuts, the authors replace deterministic fusion weights with a mean-preserving distribution over layer subsets. Given an image and a frozen encoder, the layer-normalized tokens from K chosen layers are mapped to a single latent representation. While a standard normalized fusion uses fixed weights a such that za=∑k=1Kakhk with 1⊤a=1, FuseReg samples a separate layer-dropout mask for each training example. For a drop rate p∈[0,1), the method draws an independent and identically distributed Bernoulli mask m and conditions it on being nonzero. The resulting fused latent is computed as:
zm=∑kmk∑kmkhkThis normalization is critical because it ensures that the expected value of the sampled latent equals the full-layer mean. Consequently, the variation introduced by the sampling strictly targets directions where the encoder layers disagree without shifting the average representation.
The framework applies this randomized fusion to both the pixel decoder and the diffusion transformer, but employs separate drop rates for each stage since they solve fundamentally different prediction problems. For the decoder, subset fusions are used to reconstruct pixels. The decoder is trained to map the sampled latent zm back to the image using a combination of pixel, perceptual, and adversarial objectives. This forces the decoder to reconstruct images from multiple layer compositions, reducing its reliance on shallow-layer shortcuts.
For the diffusion transformer, the generator receives noisy subset fusions but is trained to predict the full-layer aggregate target. Using a flow-matching interpolant built from the subset aggregate, the model regresses the full-layer target with a time-weighted prediction loss. Setting the drop rate to zero recovers the standard full-fusion objective, while any positive rate trains the generator to map multiple subset fusions to the same full-layer target.
Theoretical analysis confirms that this normalized subset sampling preserves the all-layer representation on average while adding variance precisely along the components where layers disagree. Furthermore, the second moment of these random fusion weights spans the entire layer-contrast subspace. Because deterministic input-independent fusion rules possess a rank-one second moment, no fixed global fusion can match both the mean and the variance properties of the randomized approach, making FuseReg a uniquely effective regularizer for bridging the reconstruction and generation gap.
Experiment
The evaluation uses a frozen DINOv3-L encoder and a ViT decoder trained on ImageNet-256 with matched DiT-Base and DiT-XL budgets, and it isolates decoder, generator, and joint effects by testing one decoder across different layer fusions, swapping decoders while fixing the generator and latents, and jointly regularizing both stages. The experiments show that a randomized-fusion decoder reconstructs robustly across full, subset, and single-layer fusions, whereas fixed-fusion decoders specialize and degrade on shifted fusions; improving decoder robustness also improves generation with the generator fixed, especially for shifted fusions. Joint regularization yields complementary gains on DiT-Base but more nuanced, metric-dependent behavior on DiT-XL, motivating separate selection of decoder and generator regularization rates depending on scale, evaluation metric, and guidance.
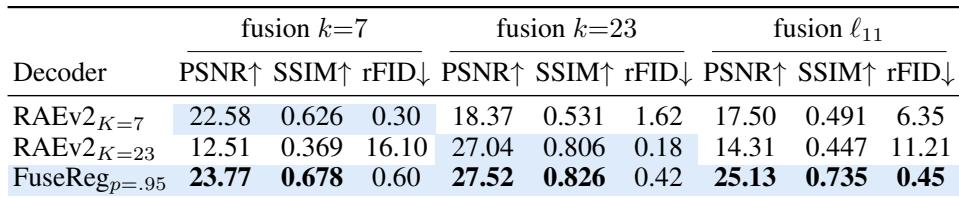
The experiment compares reconstruction quality across full, subset, and single-layer fusions. Fixed-fusion RAEv2 decoders perform well only on the fusion they were trained on and degrade sharply when transferred to other fusions. A single FuseReg decoder, trained across nontrivial fusions, retains consistently strong PSNR, SSIM, and rFID across all evaluated fusion types. Fixed-fusion RAEv2 decoders specialize heavily to their training fusion, with large drops in PSNR and rFID on off-training fusions. The FuseReg decoder matches or exceeds the deterministic decoders across all tested fusions, keeping rFID below 0.6 and SSIM above 0.67 in every case.
In this unguided ImageNet-256 Inception Score sweep, decoder regularization has a non-monotonic effect: small decoder rates improve over the fixed-fusion baseline, but larger decoder rates reduce scores. Generator regularization generally lowers Inception Score, so the strongest results come from no or little generator regularization paired with a modest decoder rate. The best Inception Score appears at zero generator rate with a small decoder rate, improving substantially over the reproduced fixed-fusion baseline. For each generator rate, scores tend to peak at decoder rates of 0.05 or 0.1 and then decline as decoder regularization increases. High generator regularization combined with high decoder regularization produces the lowest scores in the sweep.
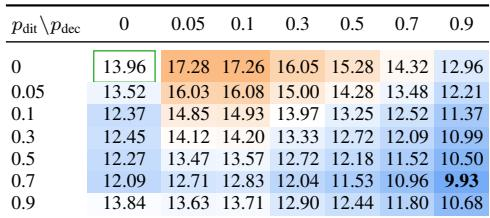
The first experiment evaluates reconstruction quality across full, subset, and single-layer fusions, showing that fixed-fusion RAEv2 decoders overfit to their training fusion and degrade sharply when transferred, while a single FuseReg decoder trained across nontrivial fusions maintains consistently strong PSNR, SSIM, and rFID. The second experiment sweeps decoder and generator regularization on unguided ImageNet-256 using Inception Score, finding that mild decoder regularization improves over the fixed-fusion baseline but larger amounts hurt, and generator regularization generally reduces scores. The best setup uses no or little generator regularization with a modest decoder rate, whereas high regularization on both sides yields the lowest scores.