Command Palette
Search for a command to run...
Block-Sparse-Attention mit log-linearer Komplexität
Block-Sparse-Attention mit log-linearer Komplexität
Bohao Tang Zhen Qin Yuqi Pan Zheng Li Pengfei Liu
Zusammenfassung
Die Skalierung von Sprachmodellen auf lange Kontexte wird durch die quadratischen Kosten der Selbstaufmerksamkeit eingeschränkt. Blocksparse Attention bietet eine effiziente Alternative, jedoch bleibt die Auswahl der beibehaltenen Blöcke ein Engpass. Die herkömmliche Blockauswahl erfordert die Bewertung aller Query-Block-Paare und bleibt daher quadratisch in der Sequenzlänge. Um dieses Problem zu adressieren, schlagen wir PISA vor, einen block-sparsen Aufmerksamkeitsmechanismus, der eine pyramidale Top-K-Auswahlstrategie verwendet. Die Grundidee besteht darin, die Kandidaten über verschiedene Ebenen hinweg schrittweise einzugrenzen, wodurch die Suche nach den relevantesten Schlüsseln effizienter wird. Konkret konstruieren wir eine Grob-zu-fein-Hierarchie von Schlüsseln und führen die Auswahl ab der gröbsten Ebene durch. Auf jeder Ebene wird eine LogSumExp-Bewertung auf eine begrenzte Kandidatenmenge angewendet, um Kandidaten für die nächstfeinere Ebene auszuwählen, bis die feinste Ebene erreicht ist. Durch Pooling konstruieren wir O(log N) Ebenen von Schlüsseln, was zu einer Gesamtkomplexität von O(N log N) führt, wobei N die Sequenzlänge bezeichnet. Wir entwickeln hardwarebewusste Triton-Kernel für Training und Inferenz, die hierarchisches Routing und LogSumExp-Bewertung fusionieren, ohne die Query-Key-Bewertungsmatrix zu materialisieren. Darüber hinaus evaluieren wir unsere Methode anhand von Sprachmodellierungsaufgaben. Im Vergleich zur Baseline erzielt unsere Methode vergleichbare Leistungen bei Benchmarks wie Commonsense-Reasoning und liefert bessere Ergebnisse bei Retrieval-Aufgaben.
One-sentence Summary
Researchers at Shanghai Jiao Tong University, Shanghai Innovation Institute, and ByteDance Seed propose PISA, a block-sparse attention mechanism that uses pyramid Top-K selection over a coarse-to-fine key hierarchy with bounded LogSumExp scoring to achieve O(N log N) complexity, and they develop hardware-aware Triton kernels for training and inference, yielding performance comparable to baselines on language modeling benchmarks and better results on retrieval tasks.
Key Contributions
- The paper introduces PISA, a block-sparse attention mechanism that uses pyramid Top-K selection over a coarse-to-fine hierarchy of keys and LogSumExp scoring at each level, reducing block selection complexity to O(N log N).
- Hardware-aware Triton kernels for training and inference fuse hierarchical routing and LogSumExp scoring, maintain a bounded candidate set, and avoid materializing the dense query-key score matrix.
- Experiments on language modeling show that PISA achieves comparable performance to conventional block-sparse attention baselines on commonsense reasoning, delivers better results on retrieval tasks, and attains lower selection latency than single-level block selection for sequences up to 256K tokens.
Introduction
Scaling language models to longer contexts is important, but full self-attention grows quadratically with sequence length. Block-sparse attention reduces this cost by restricting each query to selected key blocks; however, conventional Top-K block selection still scans every candidate key block, creating an O(N2/C) selection bottleneck for long sequences. To address this, the authors propose PISA, a pyramid sparse attention method that builds a multilevel pooled key hierarchy and performs coarse-to-fine Top-K selection with LogSumExp scoring. This reduces block-selection complexity to O(NlogN) and uses hardware-aware Triton kernels that fuse hierarchical routing while avoiding dense query-key score matrices.
Method
The authors introduce PISA as a pyramid block sparse attention mechanism. It combines three main components: a block sparse attention backbone, a hierarchical top-K block selector built over a coarse-to-fine key pyramid, and dedicated training, prefill, and decoding kernels.
Block Sparse Attention
Keys and values are partitioned into contiguous blocks. For a query qt, the block selector retains only a subset of key blocks, and attention is computed over the corresponding original keys and values:
ot=∑j∈Ttexp(qt⊤kj/d)∑j∈Ttexp(qt⊤kj/d)vj.A flat block sparse attention method scores M=⌈N/C⌉ block summaries for every query, which still costs O(N2d/C) for full-sequence scoring. PISA instead organizes block selection as a hierarchical search.
Pyramid Key-Block Hierarchy
The key hierarchy is constructed from fine to coarse. Level 0 contains the original keys as singleton blocks:
M0=N,Ki(0)=[ki].The first merging step uses g0=C and produces leaf blocks. For all higher levels, the merging factor is gℓ=g=2:
Mℓ+1=⌈gℓMℓ⌉, Ki(ℓ+1)=Concatr∈Chℓ(i)Kr(ℓ).Each block Ki(ℓ) has a summary vector kˉi(ℓ). Starting from kˉi(0)=ki, the summaries are computed recursively by mean pooling:
kˉi(ℓ+1)=∣Chℓ(i)∣1r∈Chℓ(i)∑kˉr(ℓ).Because the hierarchy uses a fixed merging factor g=2 after the leaf level, it contains L=O(logN) levels. Queries remain token-wise throughout the selection process.
Coarse-to-Fine Top-K Selection
Selection proceeds from the coarsest level L down to the leaf level 1. For each query, the candidate set at the coarsest level is initialized as:
At(L)={1}.At level ℓ, PISA scores only the candidate blocks in At(ℓ), selects the top K blocks, and expands the retained blocks into their children:
At(ℓ−1)=i∈It(ℓ)⋃Chℓ−1(i).Since each retained block has at most g children for ℓ>1, the candidate set size is bounded by gK at the next level. If a level contains at most K valid candidates, all candidates are retained without scoring. The final leaf-level selection set Tt=Tt(1) determines the original key and value blocks used by the sparse attention layer.
For scoring, PISA uses a LogSumExp block score. The score of candidate block Ki(ℓ) for query qt is:
st,i(ℓ)=logr∈Chℓ−1(i)∑exp(dqt⊤kˉr(ℓ−1)),ℓ≥1.At the leaf level, the children are original keys, so a leaf score is the exact raw-key LogSumExp score of that block. At intermediate levels, each candidate is scored from its child summaries, and each score reduces at most g logits. This keeps the scoring cost small while making leaf-level selection consistent with the attention log-sum-exp computation.
Kernel Implementation
For training and prefill, PISA uses a two-stage kernel design.
In the first stage, the kernel processes intermediate levels from L to 2. It parallelizes over query positions and key/value heads. Query heads within the same GQA group share the same selected key blocks. For a key/value head h, the kernel computes LSE scores for all query heads in H(h) and sums them:
uh,t,i(ℓ)=h′∈H(h)∑sh′,t,i(ℓ).It then applies top-K selection on the summed scores and expands the retained blocks into their children to form the next candidate set. The candidate indices remain local to the program throughout this loop.
After the first stage, each query has at most gK candidate leaf blocks. The second stage groups queries that need to score the same candidate key block into clusters. Each cluster is divided into tiles of at most Qtile queries, with Qtile=4 in the implementation. Each kernel program loads a key tile of shape d×C once and reuses it across a query tile of shape (QtileGQ)×d, where GQ=∣H(h)∣. It computes
(QtileGQ)×d×d×C⟶(QtileGQ)×C,applies LSE over keys for each query head, and then sums over the GQ query heads. A final kernel independently applies top-K selection for each query and key/value head.
During decoding, PISA caches the mean pyramid and updates only the current leaf mean and the affected ancestor path for each new token. Block selection uses a single fused kernel that runs from the coarsest level down to ℓ=1, directly scoring the original key blocks. This avoids the overhead of launching multiple kernels per decoding step.
Complexity
Because the pyramid hierarchy has O(logN) levels and each query scores at most gK candidate blocks per level, the selection cost per query is O(logN). Full-sequence training or prefill therefore costs O(NlogN), while decoding costs O(logN) per step on average.
The two-stage training/prefill kernel is chosen mainly for input/output efficiency. By grouping queries that share a candidate key block, the second stage reuses each loaded key block across multiple queries. For the implementation settings GQ=16, Qtile=4, and C=64,
GQ+QtileC=32<64=C,so the two-stage design reduces leaf-level query/key IO compared with a single-stage design. During decoding, clusters contain only one query, so there is no cross-query key reuse. The fused single-stage kernel reuses the query vectors already loaded during intermediate selection and avoids separate grouping and final-selection launches.
Experiment
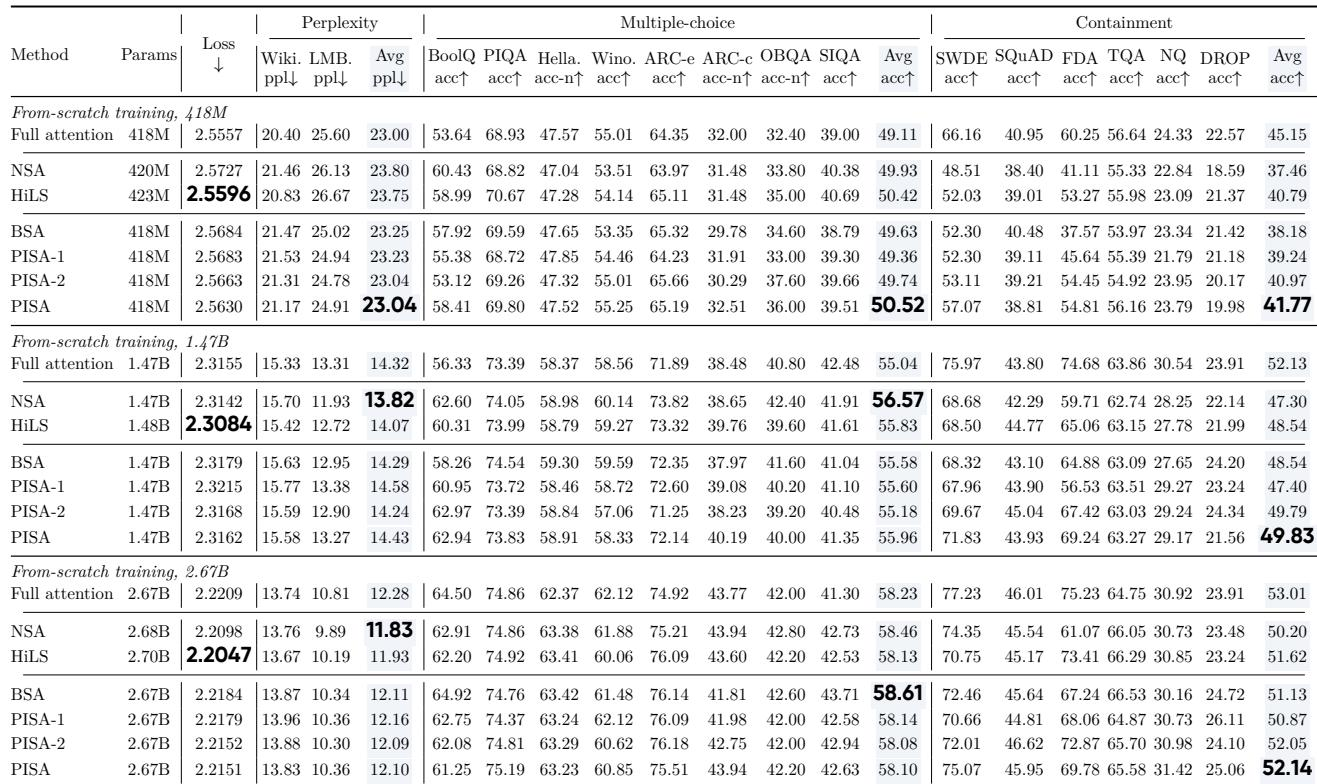
The experiments compare PISA with Full Attention, BSA, NSA, and HiLS at 418M, 1.47B, and 2.67B scales under matched training, with 100B tokens at 4K sequence length followed by 10B tokens of continued pretraining at 16K. PISA performs comparably to sparse baselines on language modeling and commonsense reasoning, achieves the highest average containment accuracy among sparse methods at all scales though Full Attention remains higher, and shows strong long-context retrieval on RULER. Ablations indicate that the LSE-based scoring improves Top-K block selection quality and downstream performance relative to PISA-1, PISA-2, and BSA, while block-selection efficiency becomes advantageous over BSA at very long contexts.
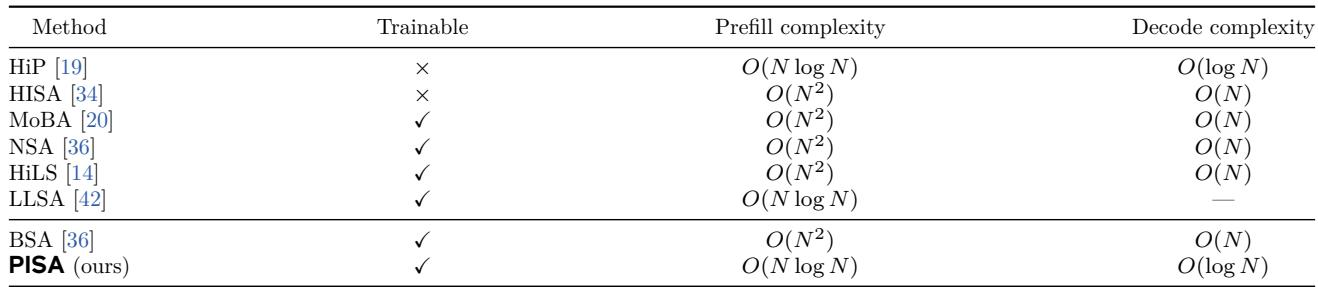
The table compares training settings and computational complexity for sparse attention methods. HiP is notable as a training-free method with subquadratic prefill and logarithmic decode complexity, while HISA and most trainable methods use quadratic prefill and linear decode complexity. LLSA is the trainable exception with subquadratic prefill, but its cost is reported per diffusion attention pass rather than autoregressive prefill. HiP achieves lower prefill and decode complexity than HISA among the listed training-free methods, with subquadratic prefill and logarithmic decode. Most trainable methods share quadratic prefill and linear decode complexity; LLSA has subquadratic prefill but is reported for diffusion attention passes rather than autoregressive prefill.
PISA performs comparably to BSA, NSA, and HiLS on language modeling and commonsense reasoning after 100B tokens of pretraining. Among sparse methods, PISA achieves the highest average accuracy on containment tasks across evaluated scales, while full attention retains a higher containment average. PISA also shows lower training loss and higher average containment accuracy than PISA-1, PISA-2, and BSA. PISA reaches the best containment average among the compared sparse methods across model scales. Full attention still leads containment accuracy, while PISA matches sparse baselines on language modeling and commonsense reasoning. PISA improves over PISA-1, PISA-2, and BSA in training loss and average containment accuracy.
After continued pretraining at 16K, full attention has the highest average RULER needle-in-a-haystack accuracy for the 2.67B models. Among sparse methods, PISA and PISA-2 lead overall and are nearly tied, with PISA-2 slightly ahead on average and both above NSA and BSA. Accuracy declines with context length across methods, especially on multi-key, multi-query, and multi-value tasks. Full attention records the top average accuracy, while PISA-2 and PISA are the strongest sparse methods and nearly tied. PISA variants outperform full attention on several short-context multi-key and multi-query settings, but all sparse methods drop more sharply by 16K, especially on multi-key and multi-value tasks.
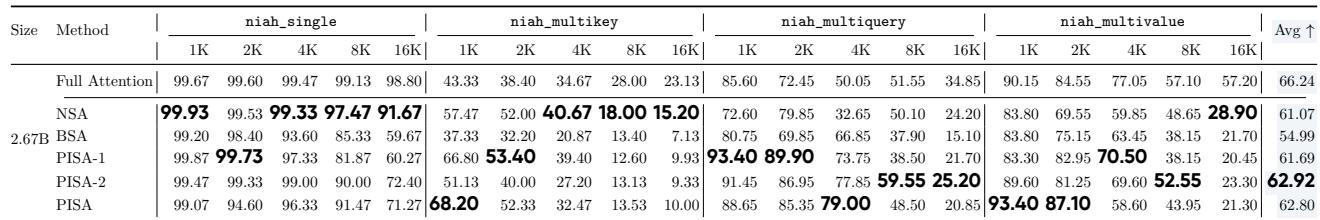
The experiments compare sparse attention methods on efficiency, language modeling and commonsense reasoning after 100B-token pretraining, and long-context retrieval after continued pretraining at 16K. PISA performs comparably to BSA, NSA, and HiLS on language modeling and commonsense reasoning, and it achieves the highest average containment accuracy among sparse methods, though full attention remains stronger overall. In long-context RULER evaluation, PISA and PISA-2 are the strongest sparse methods and nearly tied, with some short-context advantages over full attention, but all sparse methods degrade more sharply by 16K. Complexity results also show that training-free HiP offers subquadratic prefill and logarithmic decode, while most trainable methods use quadratic prefill and linear decode.