Command Palette
Search for a command to run...
RewardVerse: Rubrikgeleitete Policy-Optimierung für die Video-Reward-Modellierung
RewardVerse: Rubrikgeleitete Policy-Optimierung für die Video-Reward-Modellierung
Zhenchen Tang Yang Li Songlin Yang Bo Peng Xiaotong Zhao Shuai Li Haotian Fan Alan Zhao Jing Dong
Zusammenfassung
Reinforcement Learning (RL) ist für die Optimierung von Videogenerierungsmodellen von zentraler Bedeutung, wobei ein robustes Reward-Modell (RM) den Grundstein bildet. Bestehende Video-Reward-Modelle erzeugen jedoch häufig instabile skalare Scores, da sie komplexe, subjektive Videoqualität ohne explizite Bewertungskriterien direkt in einen einzelnen Score abbilden. Dies führt zu Skalardrift, bei der die Bewertungsskala über verschiedene Prompts hinweg kollabiert oder sich verschiebt, wodurch die Belohnung für RL unzuverlässig wird. Inspiriert von professioneller menschlicher Annotationstechnik adressieren wir dieses Problem mit RewardVerse, einem rubrikenbasierten Video-Reward-Framework, das eine dynamische Rubrik als Zwischenrepräsentation zwischen der Bewertungsanfrage und dem Scorer einführt. Statt einer unkontrollierten direkten Bewertung generiert RewardVerse zunächst explizite Bewertungskriterien und führt anschließend eine rubrikgeleitete Bewertung durch, wodurch ein stabiler semantischer Anker entsteht, der die Skalardrift abschwächt. Zur effizienten Optimierung dieser kollaborativen Pipeline schlagen wir Rubric-Guided Policy Optimization (RGPO) vor, einen zweistufigen Trainingsalgorithmus. RGPO führt zunächst einen Warmstart des Scorers mit selbst-evolvierenden Seed-Rubriken durch und optimiert anschließend gemeinsam den Rubrikgenerator, um anfrageadaptive Bewertungskriterien zu erzeugen, während der Scorer kontinuierlich an menschliche Bewertungen angeglichen wird. Umfangreiche Experimente auf dem 16-dimensionalen EvalVerse-Benchmark und externen Datensätzen zeigen, dass RewardVerse die Skalardrift abschwächt, bei punktweiser und paarweiser Evaluation eine Leistung auf dem neuesten Stand erzielt und ein robustes sowie interpretierbares Belohnungssignal für RL in der Videogenerierung bereitstellt.
One-sentence Summary
Researchers from the Chinese Academy of Sciences, The Hong Kong University of Science and Technology, and Tencent propose RewardVerse, a rubric-guided video reward framework that generates dynamic query-adaptive rubrics before scoring and employs two-stage Rubric-Guided Policy Optimization (RGPO) to mitigate scalar drift, achieving state-of-the-art pointwise and pairwise evaluation results for video generation reinforcement learning.
Key Contributions
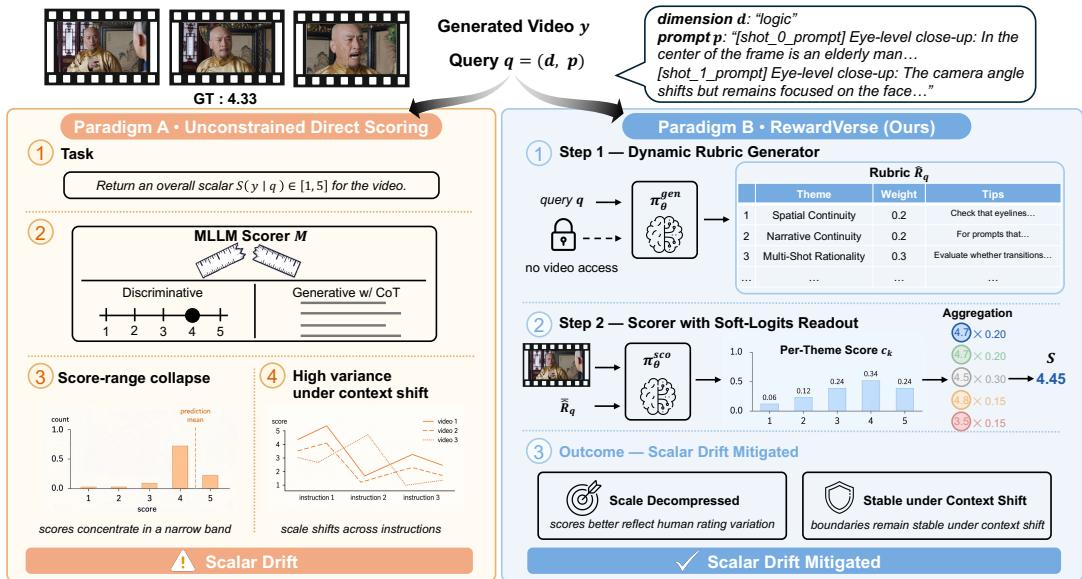
- RewardVerse is a rubric-based video reward framework that uses a dynamic rubric as an intermediate representation between the evaluation query and the scorer. It first generates explicit evaluation criteria and then performs rubric-guided scoring, providing a stable semantic anchor that mitigates scalar drift.
- Rubric-Guided Policy Optimization (RGPO) is a two-stage training algorithm that first warms up the scorer using self-evolving seed rubrics and then jointly optimizes the rubric generator to produce query-adaptive criteria while continuously aligning the scorer with human ratings.
- Experiments on the 16-dimensional EvalVerse benchmark and external datasets show that RewardVerse mitigates scalar drift and achieves state-of-the-art pointwise and pairwise evaluation performance. RewardVerse attains high pointwise correlation on EvalVerse, strong pairwise agreement on VGRB, and improved downstream video generation while being more robust to reward hacking.
Introduction
Generative video models rely on reward models to align outputs with human preferences during reinforcement learning, but existing video reward models typically map a video directly to a single scalar score. Because video quality is subjective and multidimensional, this unconstrained scoring often produces scalar drift, where scores collapse into a narrow range or shift across prompts and contexts. Prior methods lack explicit evaluation criteria before scoring, making their reward signals unstable for downstream RL. The authors propose RewardVerse, a video evaluation framework that inserts a dynamic rubric as an intermediate representation, decoupling criterion generation from scoring to stabilize pointwise and pairwise rewards. They also introduce Rubric-Guided Policy Optimization, a two-stage training algorithm that jointly learns query-adaptive rubrics and aligns the scorer using only 30 preference pairs per dimension without supervised fine-tuning.
Method
The authors reframe rubrics as a learnable intermediate representation rather than a fixed prompt scaffold. The goal is to generate query-adaptive evaluation criteria while keeping the scorer aligned with human ratings. RewardVerse implements this through a dual-role policy model πθ that acts as both a dynamic rubric generator and a scorer. The training procedure, Rubric-Guided Policy Optimization (RGPO), consists of two stages: a scorer warm-up using self-evolving seed rubrics, followed by joint optimization of the generator and scorer.
An evaluation query is defined as q=(d,p), where d∈D is a target evaluation dimension and p is the prompt used to synthesize the candidate video. Each video is scored independently during training and inference.
The dynamic rubric generator samples a structured rubric from the query:
R^q∼πθgen(⋅∣q),R^q={(tk,wk,Tk)}k=1K,where tk is a theme, wk∈(0,1) is a normalized weight, and Tk is a set of execution tips. Importantly, the generator sees only the query and does not observe the candidate video. This candidate-independent design prevents the generator from producing biased rubrics that are overly lenient to weak videos or overly strict to strong videos.
The scorer uses a soft-logits readout instead of parsing discrete digits. For each theme, the model reads the logits of the five rating tokens and computes an expected rating:
ck(y∣R)=v=1∑5v⋅Pθ(v∣y,tk,Tk),where
Pθ(v∣y,tk,Tk)=∑v′=15exp(lv′)exp(lv).The pointwise reward aggregates theme scores by their rubric weights:
S(y∣R)=k=1∑Kwk⋅ck(y∣R).The generator and scorer share the same backbone and are distinguished by role-specific prompts.
In Stage 1, the authors warm up the scorer with seed rubrics. For each dimension d, a frontier MLLM constructs an initial seed rubric Rd⋆ through an offline self-evolving loop. Given preference triples, the MLLM proposes a rubric that explains why yw≻yl, verifies whether the rubric recovers that preference when used for scoring, and revises the rubric on failure. Verified rubrics are pooled, deduplicated with a two-level Jaccard filter, and reduced to five representative rubrics using an MCR2 sampler.
Under each seed rubric, the scorer samples G completion pairs for the preferred and non-preferred videos. The preference reward is:
rpref(aw,g,al,g)=σ(Sg(yw∣Rd⋆)−Sg(yl∣Rd⋆)).The full warm-up reward adds a format reward that checks whether the completions follow the requested scoring format. The joint reward is standardized across the group to produce a trajectory-level advantage, and the scorer is optimized with a clipped GRPO objective plus a KL penalty against a frozen reference policy.
Because preference reward alone does not control the magnitude of score differences, the authors add a human-aligned margin calibration loss:
Lcal(θ∣R)=Smax−Smin1(S(yw∣R)−S(yl∣R))−Δs^w,l.This loss calibrates predicted score gaps against human-annotated margins. The Stage 1 objective combines the GRPO loss with this calibration term:
Lstage1(θ)=LGRPO(1)(θ)+λcalLcal(θ∣Rd⋆).In Stage 2, the generator learns to produce dynamic rubrics tailored to each query. For each preference triple, it samples G rubrics {R^g}g=1G∼πθoldgen(⋅∣q). Each rubric is scored according to how well its induced pointwise scores separate the preferred and non-preferred videos:
rpref(R^g)=σ(Sg(yw∣R^g)−Sg(yl∣R^g)).The Stage 2 reward also includes a format reward and an alignment reward:
R2(R^g)=rpref(R^g)+βrfmt(R^g)+λralign(R^g).The alignment reward measures cosine similarity between BGE-M3 embeddings of the generated and seed themes. The composite reward is standardized across the group and broadcast to all tokens in the generated rubric. The generator is then updated with a clipped GRPO objective.
The optimization signals for the two roles are asymmetric. The generator receives the rubric-level policy gradient from R2, while the scorer receives no direct policy-gradient update from this reward. Instead, the scorer is optimized only by the margin calibration loss, treating each generated rubric as fixed text context:
Lscorer(θ)=G1g=1∑GLcal(θ∣R^g).The full Stage 2 objective is:
Lstage2(θ)=LGRPO(2)(θ)+α(t)Lscorer(θ),where α(t) is a scheduled coefficient that activates scorer calibration after the initial generator warm-up. This joint formulation allows the generator to produce query-adaptive rubrics with varying weights and prompt-specific tips, while the scorer remains calibrated to human score margins.
Experiment
The analytical study shows that unconstrained MLLM video scoring suffers from scalar drift through score collapse and context sensitivity, while rubric guidance anchors the scale and soft-logits decoding further decompresses it, though static rubrics alone are insufficient. Evaluation on EvalVerse and VGRB validates that jointly optimizing rubric generation and scoring improves pointwise human correlation and transfers to pairwise ranking, including unseen dimensions. Ablations confirm the importance of rubric-mediated training, scorer warm-up, and dynamic rubric adaptation under a low-data budget, and downstream RL experiments show that RewardVerse improves target visual quality while preserving other video capabilities.
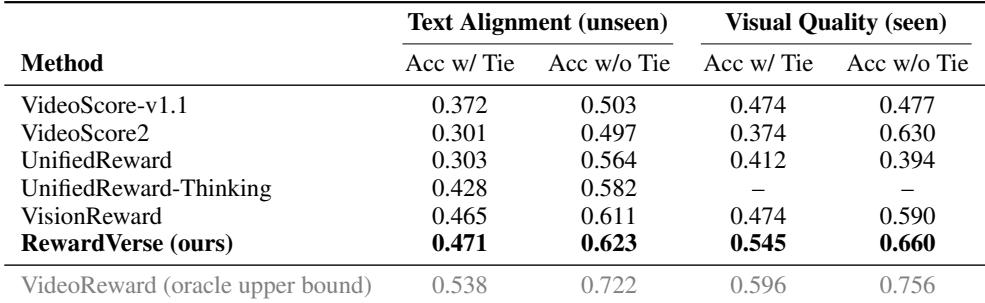
RewardVerse (Joint) leads pointwise evaluation across EvalVerse dimensions, achieving the top PLCC in 14 of 16 dimensions and outperforming prior reward models most clearly on challenging cognitive and temporal axes such as Logic and Action. External video scorers are often poorly calibrated on these fine-grained dimensions, including negative alignment on Logic. Some non-quality dimensions remain competitive for Q-Scorer, indicating partial overlap with low-level visual quality. RewardVerse (Joint) achieves the strongest overall performance, with the highest PLCC in 14 of 16 EvalVerse dimensions. It shows especially large gains on cognitive and temporal tasks such as Logic and Action compared with the next-best models. External video scorers can be poorly calibrated on fine-grained dimensions, with VideoScore-v1.1 showing negative Logic alignment. Q-Scorer remains competitive on non-quality dimensions like Lighting and Logic, suggesting those axes partly correlate with low-level visual quality.
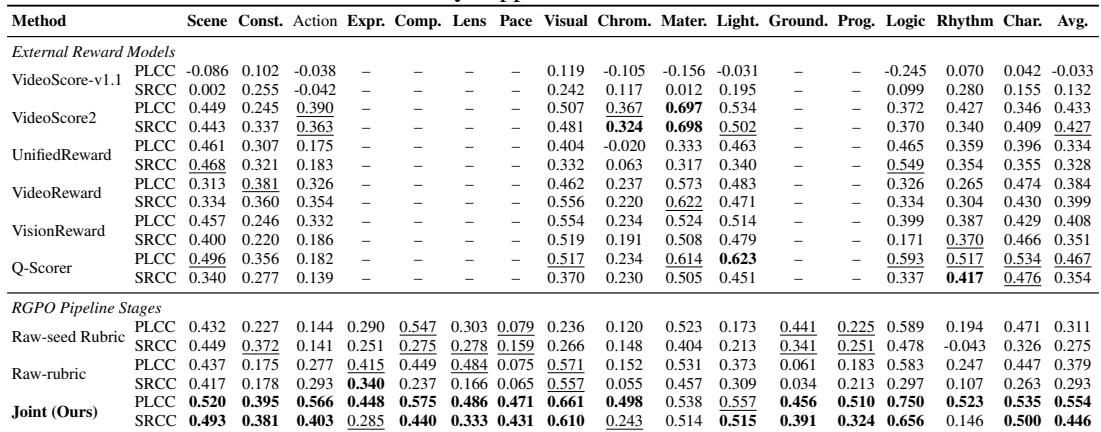
RewardVerse records the highest pairwise agreement among non-oracle methods on both the unseen text alignment and seen visual quality splits. It improves over the strongest non-oracle baseline on visual quality by a substantial margin while using a limited training budget. The results suggest that reducing scalar drift in pointwise scoring also improves pairwise preference alignment, including on unseen evaluation dimensions. RewardVerse ranks first among non-oracle methods on both the unseen text alignment and seen visual quality splits. Despite limited training pairs, RewardVerse outperforms the strongest non-oracle baseline and closes much of the gap to the oracle upper bound. On the unseen text alignment split, RewardVerse shows stronger zero-shot generalization than all non-oracle baselines.
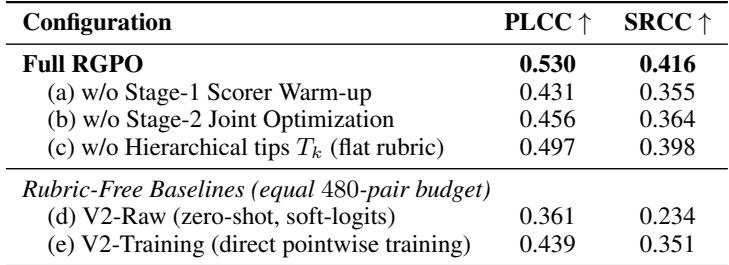
On EvalVerse, the full RGPO configuration achieves the highest macro-averaged PLCC and SRCC among all tested settings. Omitting Stage-1 scorer warm-up produces the largest drop among model ablations, while skipping Stage-2 joint optimization or using flat rubrics also lowers alignment. Rubric-free training improves only modestly over zero-shot and remains below the rubric-guided full model; downstream, RewardVerse improves target visual quality while better preserving text and quality capabilities than VideoReward. The full RGPO configuration outperforms every ablation and rubric-free baseline on both PLCC and SRCC. Removing Stage-1 scorer warm-up causes the largest correlation drop among ablations, highlighting its role in score calibration. Skipping Stage-2 joint optimization or replacing hierarchical tips with a flat rubric reduces alignment relative to the full model. Direct rubric-free training improves only slightly over zero-shot and remains well below the full rubric-guided model. RewardVerse improves visual quality in downstream generation while preserving text and quality capabilities better than VideoReward.
RewardVerse (Joint) is evaluated across fine-grained EvalVerse dimensions, pairwise preference alignment, and ablation settings, and it consistently provides the strongest pointwise and pairwise agreement among non-oracle models. The experiments show that its advantages are especially clear on challenging cognitive and temporal dimensions, while external scorers can be poorly calibrated and some non-quality axes partly overlap with low-level visual quality. Ablations confirm that scorer warm-up, joint optimization, and hierarchical rubrics all contribute to alignment, with rubric-free training remaining weaker, and RewardVerse also improves downstream visual quality while better preserving text and quality capabilities than prior reward models.