Command Palette
Search for a command to run...
Kontinuierliche Lernmechanismen komponieren sich für langfristiges Memorieren
Kontinuierliche Lernmechanismen komponieren sich für langfristiges Memorieren
Zheyuan Zhang Alvin Zhang Daniel Khashabi Tianmin Shu
Zusammenfassung
Sprachmodelle müssen möglicherweise Informationen internalisieren, die im Laufe der Zeit eintreffen, und sie über viele nachfolgende Aktualisierungen hinweg behalten. Zur Untersuchung dieser Herausforderung führen wir das langfristige Memorieren ein, eine Umgebung, in der ein Modell 100 Abfrage-Antwort-Aufgaben durch kontinuierliches überwachtes Feintuning lernt, ohne frühere Trainingsbeispiele zu behalten oder Aufgabenidentifikatoren bei der Inferenz zu erhalten. Sequentielle Aktualisierungen verursachen katastrophales Vergessen, und kein einzelner kontinuierlicher Lernmechanismus, den wir bewerten, erhält eine starke Retention über diesen Zeithorizont aufrecht. Wir stellen die Hypothese auf, dass Mechanismen, die komplementäre Quellen des Vergessens adressieren, bei Komposition wirksamer sein werden. Wir organisieren diese Kompositionen entlang zwei Gestaltungsdimensionen. Daten-, Funktionsund Gewichtsanker spezifizieren, welche vorherigen Informationen jede Aktualisierung bewahren soll, während Regeln für die Zuweisung von niedrigem Rang bestimmen, wo aufeinanderfolgende Aktualisierungen beibehalten werden. Um diese Hypothese systematisch zu testen, konstruieren wir drei verschiedene 100-Aufgaben-Memorierungsdatensätze. Wir führen eine sukzessive Halbierung auf Aufgabenebene ein, um den kombinatorischen Gestaltungsraum zu durchsuchen, und verwenden ein faktorielles Experiment, um einzelne und Interaktionseffekte zu messen. Unsere beste Methode kombiniert alle drei Anker mit zusammengeführtem LoRA, rangiert unter den Top-3-Methoden in allen Datensätzen und erhöht die durchschnittliche finale Retention von 1,2 % unter naivem sequentiellem Feintuning auf 34,9 %, eine 28-fache Verbesserung. Der Datenanker und zusammengeführtes LoRA liefern die größten durchschnittlichen Gewinne und interagieren super-additiv auf allen drei Datensätzen. Zusammen zeigen diese Ergebnisse, dass die Komposition komplementärer Mechanismen das langfristige Memorieren erheblich verbessert, über das hinaus, was jeder einzelne Mechanismus erreicht.
One-sentence Summary
Johns Hopkins University researchers introduce long-horizon memorization, in which a language model learns 100 query-answer tasks via continual supervised fine-tuning, and show that composing data, function, and weight anchors with merged LoRA—using task-level successive halving for search—raises average final retention from 1.2% under naive sequential fine-tuning to 34.9%, a 28-fold improvement, with the data anchor and merged LoRA providing the largest average gains and interacting super-additively across all three datasets, thereby substantially improving memorization beyond any individual mechanism.
Key Contributions
- Introduces long-horizon memorization as a 100-task continual supervised fine-tuning setting without task identifiers, along with three new query-answer datasets of increasing naturalness to study knowledge retention in language models.
- Organizes continual learning mechanisms into data, function, and weight anchors composed with merged LoRA, and uses task-level successive halving plus a factorial experiment to systematically search and evaluate the combinatorial design space.
- Shows that the best composition, combining all three anchors with merged LoRA, ranks among the top 3 methods across all datasets, raising average final retention from 1.2% under naive sequential fine-tuning to 34.9%, a 28-fold improvement, with a super-additive interaction between the data anchor and merged LoRA.
Introduction
Language models that learn sequentially from new data face a core challenge: as parameters update for new tasks, they can overwrite previously acquired knowledge, leading to catastrophic forgetting. This problem, known as long-horizon memorization, is especially acute for continual supervised fine-tuning, where a model must retain associations from hundreds of past tasks without access to raw examples or task identifiers at inference. Prior approaches, such as rehearsal with distillation, have shown promise but do not systematically explore how different memory-preservation mechanisms interact. Limitations of existing benchmarks also complicate evaluation; they often focus on transfer across heterogeneous tasks or targeted edits rather than the sustained recall of facts from many successive tasks.
The authors address this by proposing a structured design space for composing mechanisms, organized along two dimensions: anchors, which specify what prior information to preserve (via data, function, or weight regularization), and low-rank allocation rules, which determine how LoRA updates are stored across tasks (shared versus merged). To test their composition hypothesis, they introduce three new 100-task datasets and a factorial experimental approach. Their main contribution is demonstrating that combining all three anchors with merged LoRA significantly improves retention, boosting average final accuracy from 1.2% under naive fine-tuning to 34.9% after 100 tasks, a 28-fold gain, and outperforming every single mechanism. The analysis further reveals that the data anchor and merged LoRA are the largest contributors, with a super-additive interaction between them.
Dataset
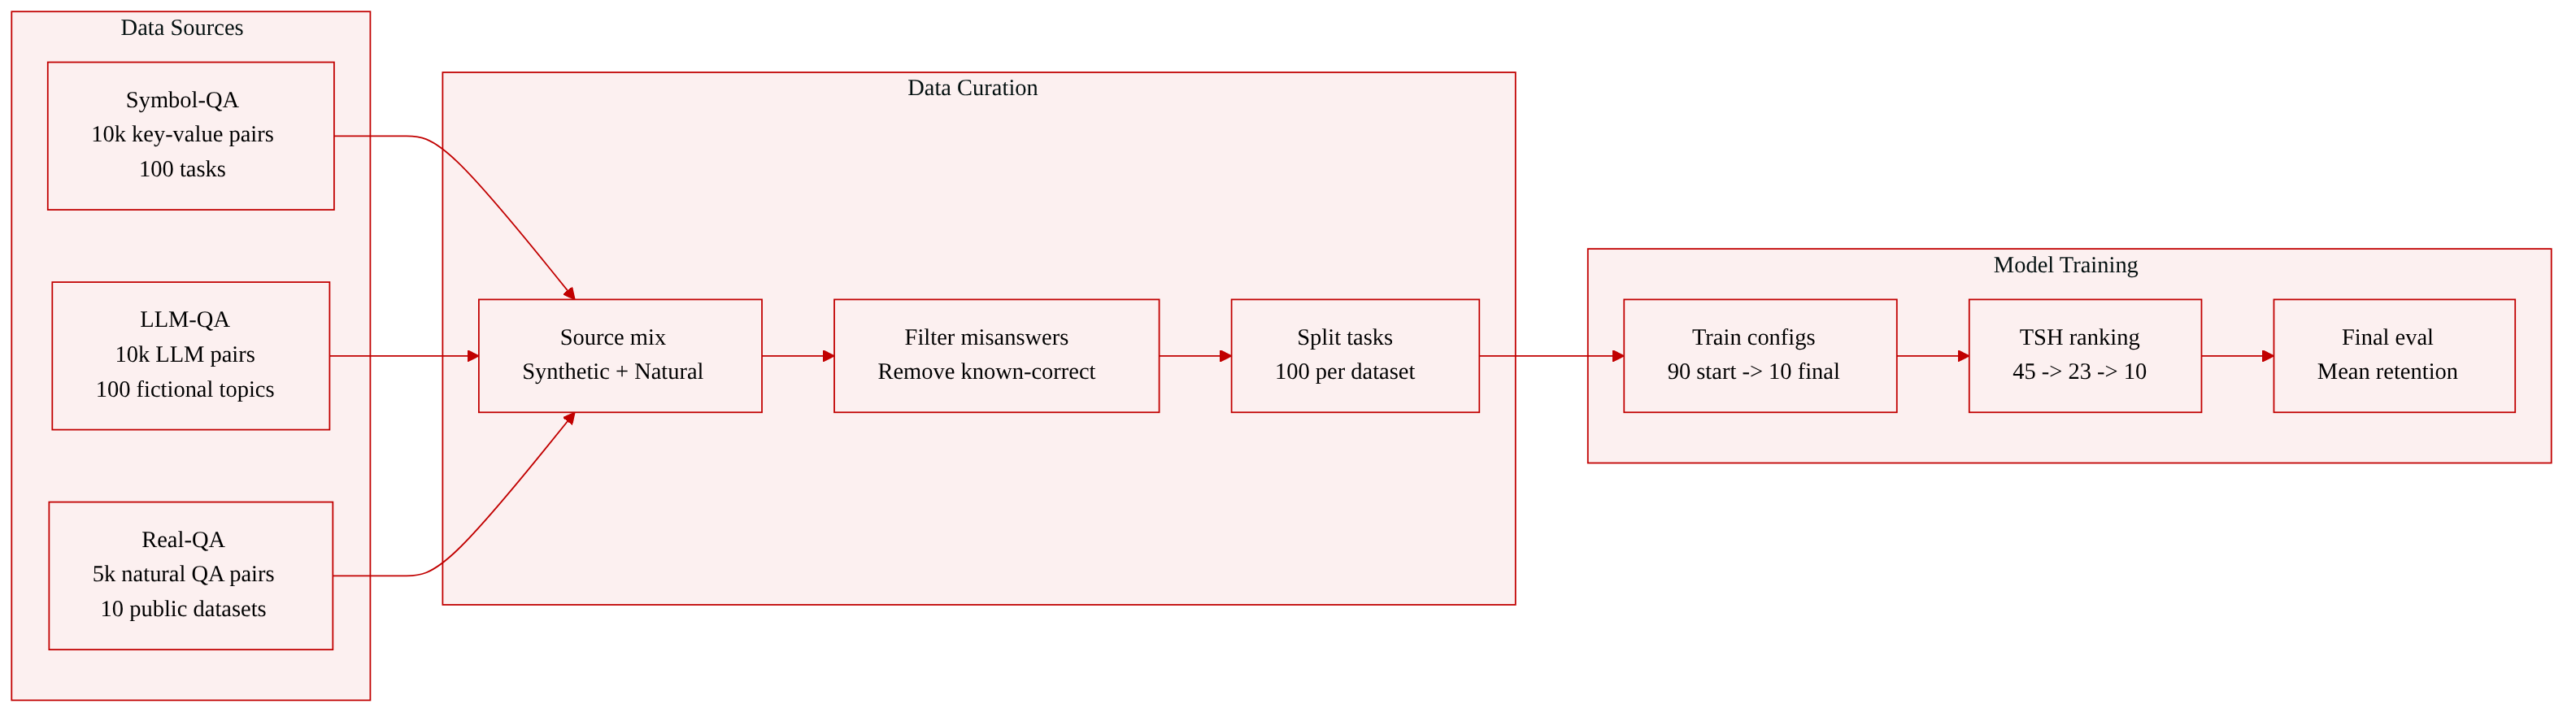
The authors construct three memorization datasets that increase in semantic realism, each designed to evaluate how models retain specific knowledge over sequential tasks.
-
Dataset composition and sources:
- Symbol-QA: 10,000 random key-value associations, with 100 tasks and 100 examples per task.
- LLM-QA: 10,000 query-answer pairs generated by an LLM across 100 fictional topics, also with 100 tasks and 100 examples per task. For both synthetic datasets, each query maps to exactly one target answer across all tasks.
- Real-QA: 5,000 natural query-answer pairs from ten public QA datasets, filtered to exclude items the model answers correctly in any of five sampled completions. This subset has 100 tasks with 50 examples per task.
-
Filtering and construction details:
- Real-QA is filtered by removing any query the model already answers correctly, ensuring the dataset focuses on memorization of new, previously incorrect information.
- The source list and full construction procedures for all datasets are provided in Appendix C, with method definitions and experimental settings in Appendices B.1 to B.8.
-
Use in the model search:
- The authors use these datasets to search a combinatorial design space of continual learning methods. The full search space includes 90 configurations, crossing anchor categories (e.g., online EWC, SI) with low-rank allocation rules (shared LoRA, merged LoRA), self-distillation loss weights, and replay settings (varying loss weights and generation temperatures).
- To manage computational cost, they employ task-level successive halving (TSH). Starting with all 90 configurations, they retain the top 45 after 10 tasks, the top 23 after 20 tasks, and the top 10 after 50 tasks, which then continue through all 100 tasks.
- Each configuration is scored by mean final retention across training seeds, using a fixed task order (the development task order) to isolate training stochasticity from task-order sensitivity.
- TSH early rankings show strong agreement with final 100-task evaluations, despite different task orders, supporting the efficiency of the search strategy.
-
Processing and metadata:
- All optimization settings besides the varied components remain fixed, with complete settings in Appendix B.8.
- Resource accounting and ranking comparisons are detailed in Appendix D.1 and D.5, respectively.
Method
3. Composing Continual Learning Mechanisms
The authors address the problem of long-horizon continual supervised fine-tuning (SFT) for autoregressive language models. At each task, the model receives a new supervised dataset and inherits the previous model state, but cannot retain or revisit raw training examples from earlier tasks. The core objective combines the current-task SFT loss with three complementary retention mechanisms, each targeting a different level of the learning system.
3.1. Long-Horizon Memorization via Continual SFT
Given a sequence of T tasks arriving one at a time, the model parameterized by Θ is trained on task t using the standard SFT objective on the current-task data Dt:
LSFTt(Θ)=−E(x,y)∼Dt[logpΘ(x,y)].The authors do not mask query tokens during loss computation, since in practical applications such as test-time training, separating query from answer is difficult. The full objective for task t combines the SFT loss with three regularization terms:
Θt=ΘargminLSFTt(Θ)+RDt(Θ)+RFt(Θ)+RWt(Θ),where RDt, RFt, and RWt correspond to the data, function, and weight anchors respectively. These anchors provide complementary constraints: the data anchor replays past information, the function anchor enforces output consistency on current inputs, and the weight anchor penalizes changes to important parameters. The authors also introduce low-rank allocation rules that determine which parameters are updated for each task and how the learned updates are carried forward.
3.2. Three Anchors
Data anchor. The data anchor replays sequences representing earlier tasks. Let Qt−1 denote a distribution over replayed sequences, and let ℓD(Θ,z) be the loss applied to a sampled sequence z. The data retention term takes the form:
RDt(Θ)=Ez∼Qt−1[ℓD(Θ,z)].Instead of storing raw examples, the authors use a frozen copy of the previous model to generate pseudo-sequences from a single task-agnostic replay token. Before each task after the first, they generate a fixed number of sequences and discard empty outputs. During training, each current-task minibatch is paired with one replay minibatch. The replay weight balances the current-task and replay losses, while the generation temperature controls the randomness of replay sampling; both are tuned via the task-level successive-halving procedure described later. Additionally, the frozen model provides soft next-token targets for the replay sequences, which are used only while learning the current task.
Function anchor. The function anchor constrains the current model’s predictions on current-task inputs by comparing them to a reference distribution. Let μt denote the distribution of current-task inputs, qt−1(⋅∣x) the reference distribution for input x, and d a divergence measure. The retention term is:
RFt(Θ)=Ex∼μt[d(qt−1(⋅∣x),pΘ(⋅∣x))].In practice, the authors use the previous model to define the reference distribution, following the Learning without Forgetting paradigm. This self-distillation objective applies only to current-task data, whereas the data anchor applies soft targets to generated replay sequences. The two anchors are thus complementary: the function anchor restricts how the model changes its behavior on new data, while the data anchor reminds the model of old data.
Weight anchor. The weight anchor constrains updates to model parameters according to their accumulated importance for previously learned behavior. Let ϑ denote the parameters tracked, ϑt−1⋆ their value before task t, and Ht−1 a positive semidefinite importance matrix. The general form is:
RWt(Θ)=21(ϑ−ϑt−1⋆)⊤Ht−1(ϑ−ϑt−1⋆),Ht−1⪰0.This quadratic penalty is a generalization of several classic continual learning methods. EWC applies this penalty separately for each previous task using diagonal Fisher information as importance weights. Online EWC maintains a single running Fisher centered at the latest parameters, avoiding a growing set of penalties. SI estimates importance from contributions accumulated along the optimization trajectory. The authors consider online EWC and SI as instantiations of the weight anchor, leaving the specific estimator as a configuration choice.
3.3. Low-Rank Allocation
The anchors constrain the update direction, but a low-rank allocation rule determines which parameters are updated for each task and how the learned update is retained. For a pretrained weight matrix W0, LoRA parameterizes the update as ρBA, where A∈Rr×din, B∈Rdout×r, and ρ=αLoRA/r. Let At and Bt denote the LoRA matrices optimized during task t, with superscript ⋆ denoting their values after training. The authors consider two ways to carry these matrices across tasks:
Wt={W0+ρBtAt,Wt−1+ρBtAt,shared LoRA,merged LoRA.Shared LoRA continues optimizing the same pair of matrices A and B across all tasks, so BtAt represents the single complete LoRA adapter after learning tasks 1 through t. Merged LoRA assigns each task a fresh pair of LoRA matrices. After task t, it folds ρBt⋆At⋆ into the dense weight matrix Wt−1, then initializes a new pair of LoRA matrices (and a new optimizer state) for the next task. This adapts ReLoRA’s merge-and-reinitialize pattern to continual learning. Both methods retain a single dense model and one LoRA pair per adapted weight matrix, so the retained state size remains constant as the number of tasks grows. This constant-memory property distinguishes them from methods like O-LoRA or sequential OSRM, whose state grows with the number of tasks.
4.3. Searching the Combinatorial Design Space
Crossing the three anchor categories with the two low-rank allocation rules yields a large combinatorial space of possible continual learning methods. Evaluating every combination on all tasks is computationally prohibitive, but short-horizon evaluation may not reliably predict long-horizon performance. The authors introduce task-level successive halving (TSH) to address this trade-off.
Unlike standard successive halving, which allocates increasing training iterations to promising hyperparameters, TSH increases the number of sequential tasks and prunes configurations by retention at each task horizon. Let A1 denote the initial candidate set and S the set of training seeds. For a configuration a∈A1 and seed s∈S, define the temporal accuracy matrix Mi,ja,s, where Mi,ja,s is the accuracy on task j after learning tasks 1 through i. All seeds share the same task order, so averaging over S captures training stochasticity but not task-order sensitivity. After r tasks, each configuration is scored by its mean final retention:
Fr(a)=∣S∣1s∈S∑r1j=1∑rMr,ja,s.The initial candidate set is constructed as the Cartesian product of anchor options and allocation rules:
A1={∅,online EWC, SI}×{∅,SD1,SD2}×{∅,Replay1,…,Replay4}×{shared LoRA, merged LoRA},where ∅ indicates the anchor is absent, SD1 and SD2 use self-distillation loss weights 1 and 3, and the replay variants enumerate the Cartesian product of replay loss weights {0.5,0.75} and generation temperatures {1.0,1.5}. This yields n1=3×3×5×2=90 initial configurations.
Starting with all 90 configurations, TSH retains the top 45 after 10 tasks, the top 23 after 20 tasks, and the top 10 after 50 tasks. These final ten configurations continue through all 100 tasks. The authors verify that rankings at the 10-task horizon show strong agreement with the 100-task final rankings for the configurations evaluated in both phases, providing confidence that early pruning identifies the most promising compositions despite the different task orders used.
Experiment
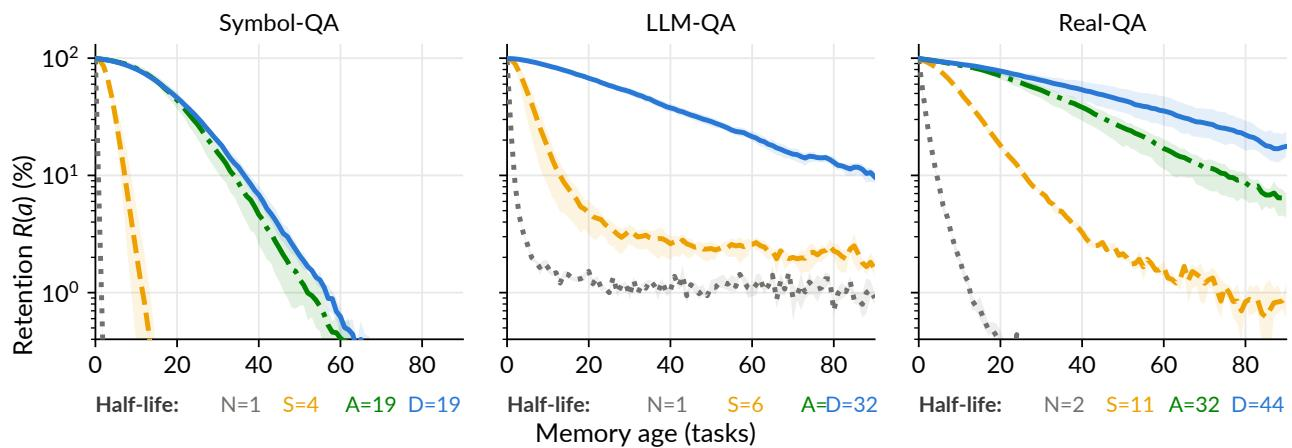
The evaluation uses three datasets of increasing semantic realism (Symbol-QA, LLM-QA, Real-QA) under a domain-incremental protocol with 100 tasks, measuring final retention, immediate acquisition, and forgetting. A task-level successive halving search over 90 method compositions found that no standalone mechanism survived the 50-task stage, while all top performers combined a data anchor with merged LoRA, and the best method also included a weight anchor. Across a full factorial evaluation, compositions substantially outperformed standalone mechanisms, with the best method combining all three anchors and merged LoRA achieving the highest average final retention (34.9%) across datasets. Replay and merged LoRA produced the largest main effects and a strong synergistic interaction, while weight and function anchors (SI and SD) added smaller, dataset-dependent gains; replacing merged LoRA with task-growing alternatives (O-LoRA or sequential OSRM) did not consistently improve retention and often reduced general capability. Memory half-life analysis showed composition delayed forgetting (from 1-2 tasks for naive fine-tuning to 19-44 tasks for the strongest compositions) but did not prevent eventual memory loss.
Replay and merged LoRA are the dominant mechanisms, showing the largest main effects and a positive, statistically significant interaction across all datasets, with their combined gains far exceeding the sum of their individual effects. SI and SD offer dataset-dependent benefits, with SD's positive main effect sometimes reduced when replay is present, and SI showing no effect on Symbol-QA and a negative interaction with merged LoRA on that dataset. Replay and merged LoRA consistently provide the largest average retention gains across datasets. The interaction between replay and merged LoRA is positive and significant, yielding super-additive retention improvements. SD has a positive main effect everywhere, but its benefit diminishes when replay is already active on two datasets. SI shows positive main effects on natural-language datasets but no detectable effect on Symbol-QA, and a negative interaction with merged LoRA on Symbol-QA.
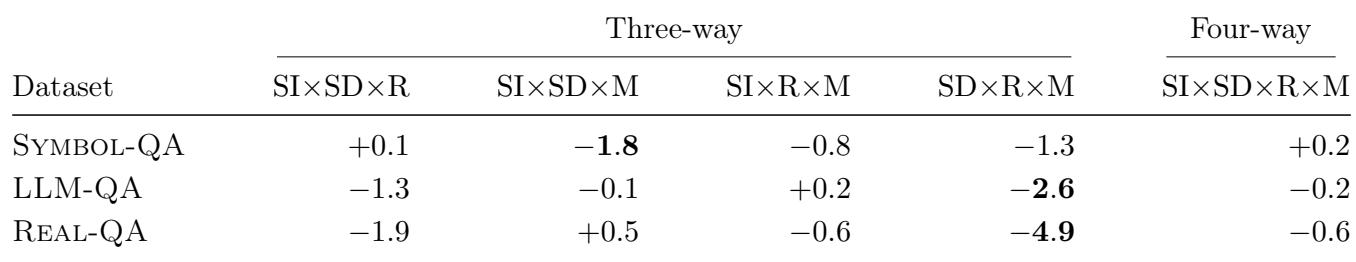
The evaluation tests replay, merged LoRA, SI, and SD on multiple datasets to assess their individual and interactive effects on retention. Replay and merged LoRA emerge as the strongest mechanisms, showing large positive main effects and a significant super-additive interaction, so their combination yields retention gains well beyond the sum of the two alone. SD provides consistent but smaller benefits, although its effect often weakens when replay is already present. SI is helpful on natural-language datasets but shows no clear benefit on Symbol-QA and can even interfere with merged LoRA on that dataset. Overall, the findings point to replay plus merged LoRA as the most effective strategy, with SD as a useful secondary option and SI best reserved for language-heavy tasks.