Command Palette
Search for a command to run...
TRAININGSBERICHT ZU TELECHAT3-MOE
TRAININGSBERICHT ZU TELECHAT3-MOE
Zusammenfassung
TeleChat3-MoE ist die neueste Modellreihe der großen TeleChat-Sprachmodelle Wang et al. (2024a;b; 2025); Li et al. (2024a;b), die über eine Mixture-of-Experts-Architektur (MoE) mit Parameteranzahlen von 105 Milliarden bis über einer Billion verfügen und end-to-end auf einem Ascend-NPU-Cluster Huawei Technologies Co. (2023) trainiert wurden. Dieser technische Bericht stellt im Wesentlichen die zugrunde liegende Trainingsinfrastruktur vor, die zuverlässiges und effizientes Skalieren auf Modellgrößen an der Leistungsspitze ermöglicht. Wir erläutern ausführlich systematische Methoden zur numerischen Genauigkeitsverifikation auf Operatorund End-to-End-Ebene, die Konsistenz über Hardwareplattformen und verteilte Parallelisierungsstrategien hinweg sicherstellen. Ferner stellen wir eine Reihe von Leistungsoptimierungen vor, darunter interleaved Pipeline-Scheduling, attention-aware Daten-Scheduling für das Training langer Sequenzen, hierarchische und überlagerte Kommunikation für Expertenparallelismus sowie DVM-basierte Operator-Fusion. Ein systematisches Parallelisierungsframework, das analytische Schätzung und ganzzahlige lineare Programmierung einsetzt, wird ebenfalls zur Optimierung multidimensionaler Parallelisierungskonfigurationen vorgeschlagen. Darüber hinaus stellen wir methodische Ansätze zur Optimierung auf Clusterebene vor, die Hostund gerätegebundene Engpässe während großskaliger Trainingsaufgaben adressieren. Diese Infrastrukturfortschritte führen zu erheblichen Durchsatzverbesserungen und nahezu linearem Skalieren auf Clustern mit Tausenden von Geräten und bieten eine robuste Grundlage für die Entwicklung großskaliger Sprachmodelle auf Hardware-Ökosystemen.
One-sentence Summary
Institute of Artificial Intelligence (TeleAI), China Telecom Corp Ltd, and Huawei present TeleChat3-MoE, a Mixture-of-Experts large language model series ranging from 105 billion to over one trillion parameters and trained end-to-end on an Ascend NPU cluster, with a training infrastructure that combines operator-level and end-to-end numerical accuracy verification, pipeline and expert-parallel performance optimizations, integer linear programming for multidimensional parallelization, and cluster-level tuning to yield throughput improvements and near-linear scaling on clusters comprising thousands of devices.
Key Contributions
- A systematic training infrastructure is developed for TeleChat3 MoE language models on Ascend NPU clusters, including operator-level and end-to-end numerical accuracy verification to maintain consistency across hardware platforms and distributed parallelism strategies.
- Performance optimizations are introduced for frontier-scale training, including interleaved pipeline scheduling, attention-aware data scheduling for long sequences, hierarchical overlapped communication for expert parallelism, DVM-based operator fusion, and an analytical integer linear programming framework for multidimensional parallelism configuration.
- Profiling-driven cluster-level optimizations address host and device bottlenecks, yielding high Model Flops Utilization, near-linear scaling on clusters of thousands of devices, and an open-sourced training stack for large language models.
Introduction
Large language models increasingly rely on Mixture-of-Experts (MoE) architectures to scale toward hundreds of billions or even trillions of parameters while keeping active computation manageable. This makes training on large accelerator clusters an infrastructure challenge: the system must preserve numerical accuracy, sustain distributed efficiency, and choose effective parallelism strategies across many devices. Prior practice often depends on manual expert tuning and can suffer from precision mismatches when models move across hardware, frameworks, or distributed configurations. The authors address this by building the training infrastructure for TeleChat3-MoE on Huawei Ascend NPUs using MindSpore. They introduce systematic accuracy verification, framework optimizations for pipeline scheduling, long-sequence load balancing, expert-parallel communication overlap, and operator fusion, plus a parallelism optimizer that combines analytical estimation with integer linear programming to cut tuning time from days to hours.
Method
The authors develop the TeleChat3-MoE series, a family of large language models ranging from 105 billion to trillions of parameters, built upon a unified Mixture-of-Experts architecture. To enable efficient training and inference at frontier scales, the architecture incorporates several key refinements. First, Multi-Latent Attention compresses key-value vectors into a low-dimensional latent space, significantly reducing cache usage and increasing computational intensity during inference. Second, the models adopt a shallow-and-wide topology with fewer layers and wider hidden dimensions, which enhances computational density and reduces pipeline bubble overhead. Third, a high-sparsity MoE design is employed, where active parameters constitute only a small fraction of the total, such as top-4 to top-8 routing out of hundreds of experts plus one shared expert, resulting in a low activation memory footprint and higher concurrency.
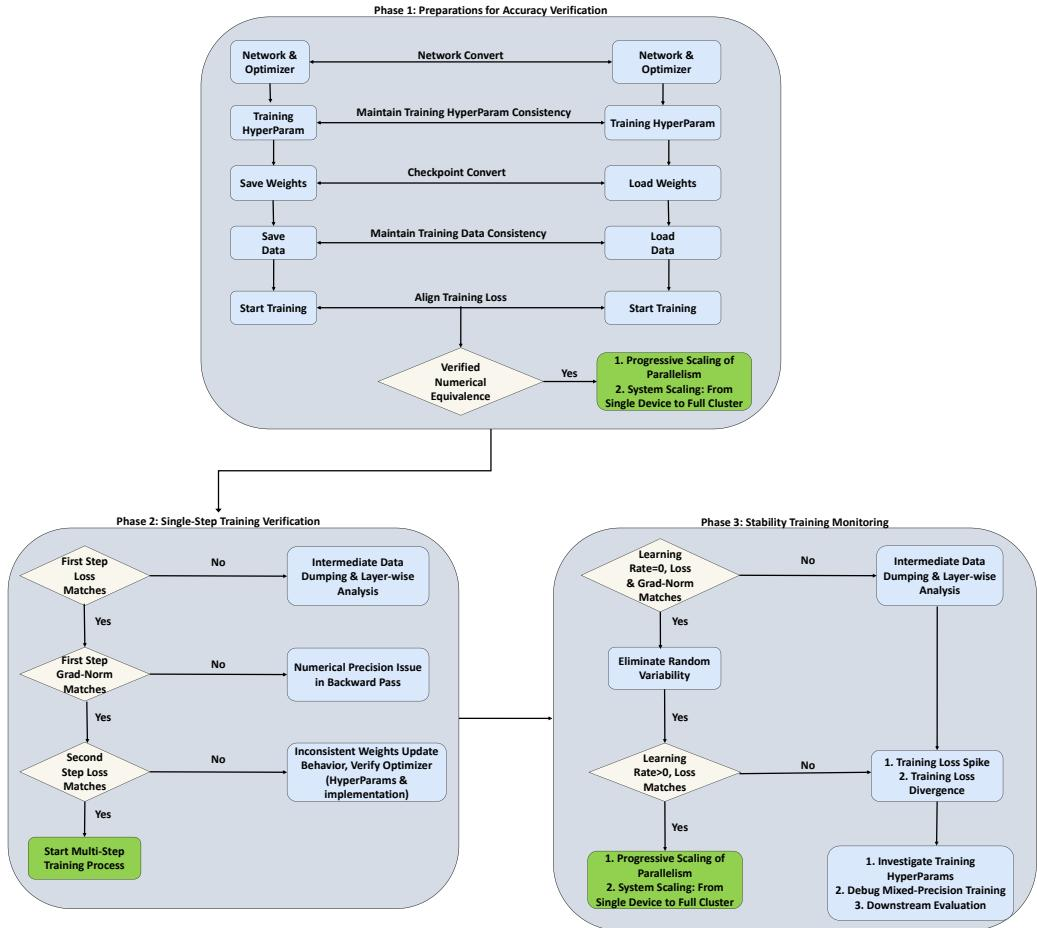
To ensure the reliability and reproducibility of training across heterogeneous hardware, the authors establish a systematic workflow for cross-hardware precision alignment. This process begins by aligning foundational configurations, including vocabulary tables, network architecture, hyperparameters, and mixed-precision settings. If discrepancies persist, a structured localization workflow is executed to isolate the root cause, progressing from single-device verification to full-cluster scaling, as shown in the figure below.
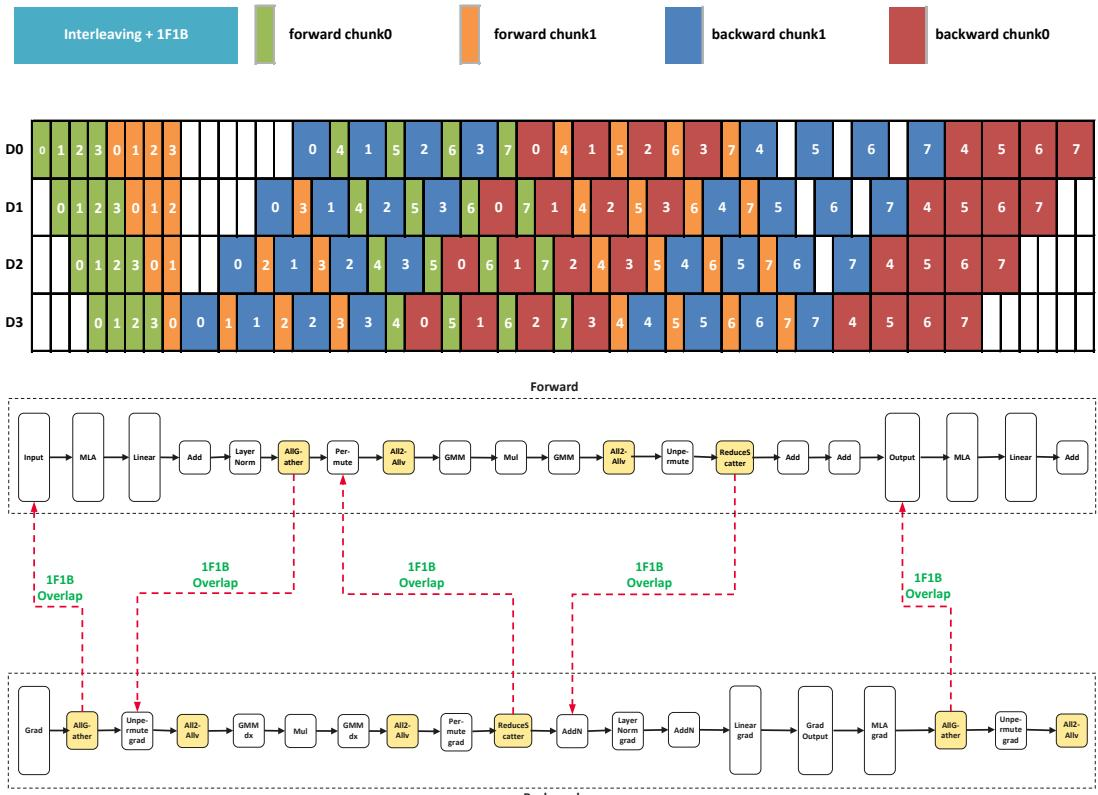
To achieve efficient training on massive clusters, the authors implement several critical optimizations within the training framework. For pipeline parallelism, they adopt interleaved pipeline scheduling combined with a 1F1B overlapping strategy. Unlike conventional methods that assign contiguous layers to each stage, interleaved scheduling distributes non-contiguous layers, enabling finer-grained parallelism. In the steady-state phase, adjacent forward and backward passes from different micro-batches are scheduled to overlap computation with communication, substantially reducing pipeline bubbles and improving end-to-end throughput, as illustrated in the figure below.
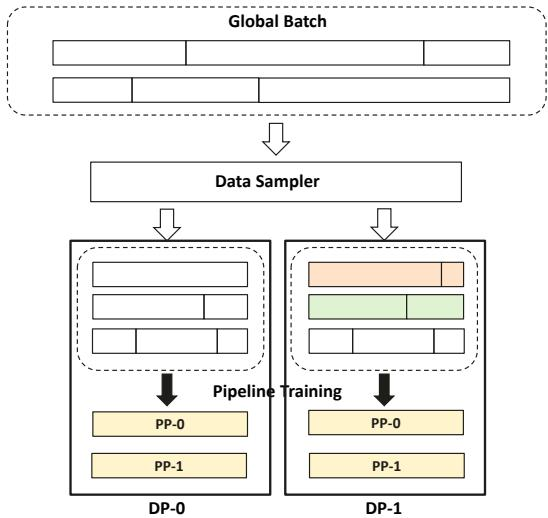
For long-sequence pre-training tasks involving sparse attention, severe load imbalance often occurs due to the input-dependent computational cost and variability in document lengths. To address this, an attention-aware data scheduling mechanism is proposed. By redistributing samples within each micro-batch according to subsequence lengths, the scheduler balances the total attention computation across devices, ensuring load-balanced execution and improved throughput for long-context models, as depicted in the figure below.
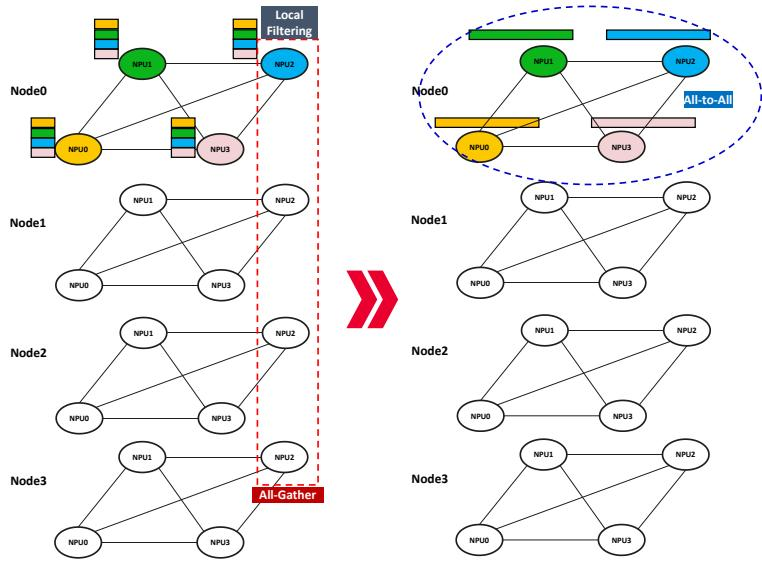
In Mixture-of-Experts training, inter-device communication via Expert Parallelism often dominates training time. The authors introduce a hierarchical topology-aware communication scheme to replace the global All-to-All collective. This three-step workflow first performs an inter-node AllGather to collect complete data on each machine, followed by local filtering to retain only required expert copies, and finally an intra-node All-to-All for redistribution. By aligning communication patterns with the physical cluster topology, this design dramatically reduces redundant cross-device traffic, as shown in the figure below.
Building upon the hierarchical scheme, an Expert Parallelism communication overlapping technique is designed to further minimize overhead. The input data is partitioned across batch and sequence dimensions and fed into multiple concurrent execution streams. This allows the communication in one stream to be overlapped by the feed-forward network computation in another. Additionally, inter-node and intra-node communications are executed in parallel over different networks without bandwidth contention, significantly reducing the proportion of communication time during training, as illustrated in the figure below.
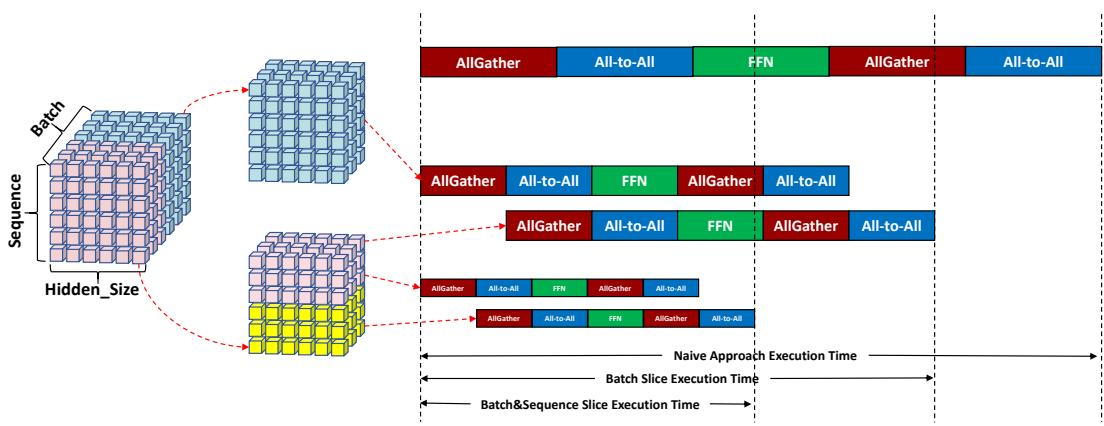
Finally, to address memory-bound small operators that limit compute unit utilization, an automatic operator fusion technique built on the Device Virtual Machine framework is applied. This approach fuses memory-bound operators with neighboring operators for joint execution, eliminating explicit materialization of intermediate tensors and reducing global memory traffic, which is particularly effective for compute-intensive and memory-intensive kernel combinations.
Experiment
The experiments evaluate the scalability, correctness, and practical efficiency of a large-scale MoE training stack. Results show that pipeline, communication, and automatic parallelization techniques support efficient scaling from smaller clusters to thousands of devices, with the proposed tool matching or exceeding manual tuning while reducing engineering effort. Precision alignment studies demonstrate that stepwise scaling and tensor comparison can identify framework-level inconsistencies, enabling consistent behavior across heterogeneous hardware. Additional cluster profiling confirms that host isolation, device power-policy adjustment, and reduced monitoring overhead improve throughput stability and utilization.
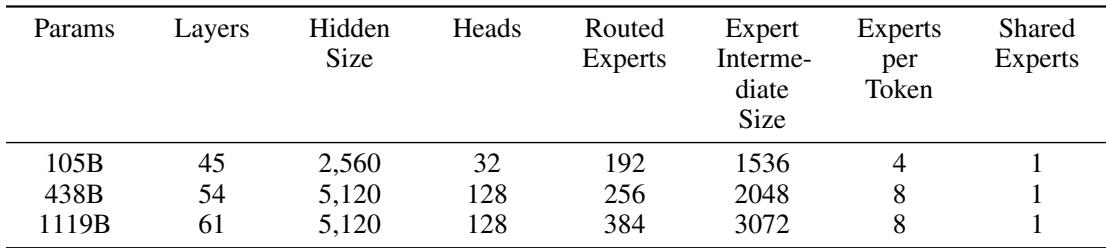
The TeleChat3-MoE series covers three model sizes with a consistent Mixture of Experts design. As parameter count increases, the models mainly scale by adding layers, increasing capacity dimensions, and expanding routed expert capacity, while all share one shared expert and long-context support through optimized positional embeddings. Larger models scale depth and routed expert capacity as overall parameter count grows. The largest model uses the same hidden width and head count as the mid-sized model but has more routed experts and wider experts. All models retain a single shared expert and support extended context lengths.
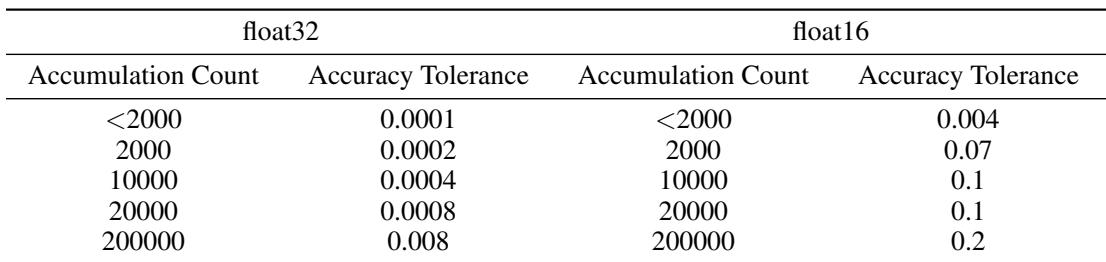
The suggested accuracy tolerance standard increases with accumulation count because repeated accumulation can compound numerical errors. Float32 testing requires tighter tolerances than float16, while both precision types need looser limits for operators with higher accumulation counts. Operators with more accumulation operations are given larger accuracy tolerances. Float32 tolerances are stricter than float16 tolerances.
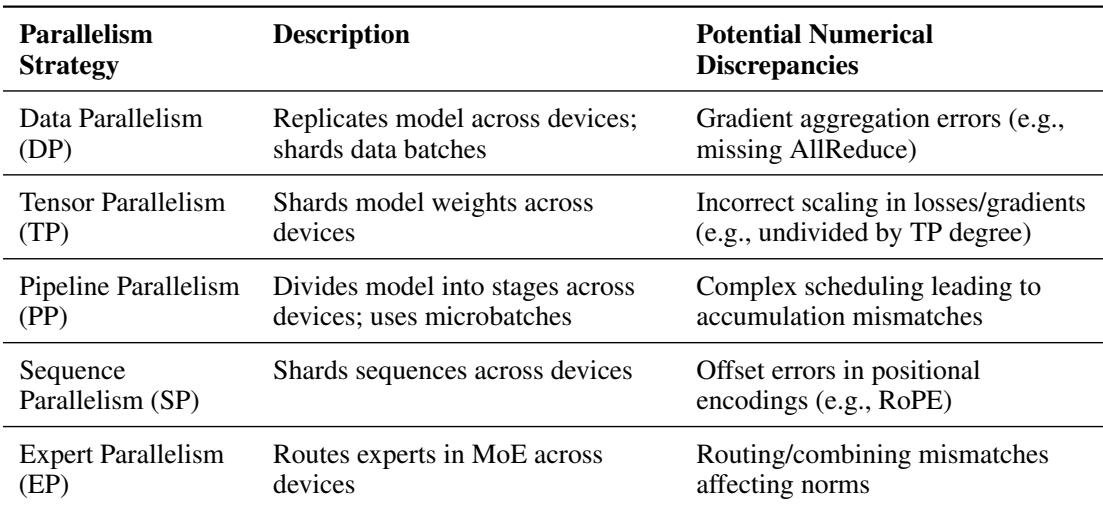
The table outlines major parallelism schemes and their possible numerical inconsistencies during large-scale training. It supports a verification workflow that starts from reproducible baselines, applies new parallel configurations, checks forward and backward equivalence, and localizes deviations in tensors, gradients, or optimizer states. The broader context emphasizes these risks when scaling MoE models, where expert routing, pipeline scheduling, and sequence sharding can introduce hidden numerical changes. Data parallelism mainly risks gradient aggregation errors, such as missing AllReduce operations. Tensor parallelism can produce incorrect loss or gradient scaling if TP degree is not handled correctly. Pipeline parallelism may cause accumulation mismatches due to complex microbatch scheduling. Sequence parallelism can introduce positional offset errors in mechanisms such as RoPE. Expert parallelism may affect norms through routing and combining mismatches in MoE models. The described debugging method uses identical seeds and weights, equivalence checking, and incremental rollback to isolate communication or scheduling issues.
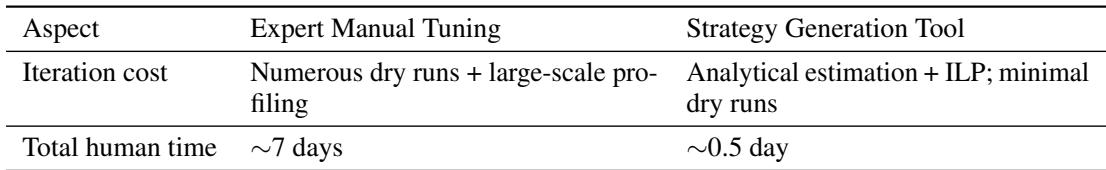
The table compares expert manual tuning with a systematic parallelization framework that uses a strategy generation tool. The tool reduces iteration cost by replacing numerous dry runs and large-scale profiling with analytical estimation and ILP-based search. It also substantially lowers total human tuning effort, cutting the workflow from about a week to under a day. Manual tuning relies on repeated dry runs and large-scale profiling. The strategy generation tool uses analytical estimation and ILP with minimal dry runs. Total human time for parallelization tuning is reduced from roughly one week to less than a day.
The tool-generated strategy achieves the lowest step time among the compared configurations on 4,096 devices, slightly outperforming expert-designed baselines. It also reduces engineering effort by automating parallelism design search, supporting faster and more reproducible scaling of large MoE models on large clusters. The tool-generated configuration has the lowest reported step time. It matches or slightly improves on expert-designed strategies under the same large-scale setting. The result shows automated parallelism optimization can lower tuning effort while preserving performance.
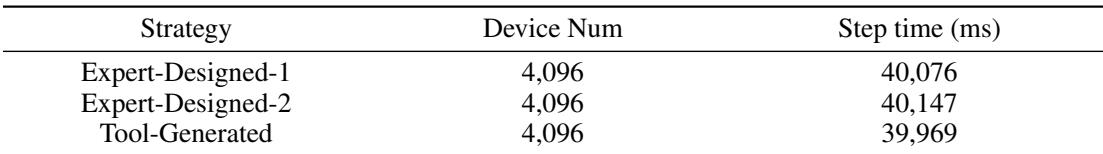
The evaluation examines the TeleChat3-MoE scaling design and validates numerical stability, parallelism debugging, and automated strategy optimization. It shows that accuracy tolerances should loosen with accumulation count while remaining stricter for Float32 than Float16. The parallelism analysis identifies numerical risks across data, tensor, pipeline, sequence, and expert parallel settings and supports a baseline-driven workflow for isolating deviations. Comparisons with expert tuning show that analytical and ILP-based strategy generation greatly reduces tuning time and achieves competitive step time on large clusters.