Command Palette
Search for a command to run...
MS MARCO: Ein von Menschen erstellter Datensatz für maschinelles Leseverständnis
MS MARCO: Ein von Menschen erstellter Datensatz für maschinelles Leseverständnis
MS MARCO: Ein von Menschen erzeugter Datensatz für maschinelles Leseverständnis
Zusammenfassung
Wir stellen einen großen Datensatz für maschinelles Leseverständnis vor, den wir MS MARCO nennen. Der Datensatz umfasst 1.010.916 anonymisierte Fragen – entnommen aus Bings Suchanfrageprotokollen – jeweils mit einer von Menschen generierten Antwort sowie 182.669 vollständig von Menschen neu formulierten generierten Antworten. Darüber hinaus enthält der Datensatz 8.841.823 Textpassagen – extrahiert aus 3.563.535 von Bing abgerufenen Webdokumenten –, die die notwendigen Informationen für die Erstellung der natürlichsprachlichen Antworten liefern. Eine Frage im MS MARCO-Datensatz kann mehrere Antworten oder gar keine Antwort haben. Anhand dieses Datensatzes schlagen wir drei verschiedene Aufgaben mit unterschiedlichen Schwierigkeitsgraden vor: (i) Vorhersagen, ob eine Frage anhand einer Menge von Kontextpassagen beantwortbar ist, und Extrahieren sowie Synthetisieren der Antwort, wie es ein Mensch tun würde; (ii) Generieren einer wohlgeformten Antwort (sofern möglich) auf Basis der Kontextpassagen, die mit der Frage und dem Passagenkontext verständlich ist; und schließlich (iii) Rangordnen einer Menge abgerufener Passagen zu einer gegebenen Frage. Die Größe des Datensatzes und die Tatsache, dass die Fragen aus echten Nutzersuchanfragen stammen, unterscheidet MS MARCO von anderen bekannten öffentlich verfügbaren Datensätzen für maschinelles Leseverständnis und Fragebeantwortung. Wir sind überzeugt, dass der Umfang und die reale Natur dieses Datensatzes ihn attraktiv für das Benchmarking von Modellen zum maschinellen Leseverständnis und zur Fragebeantwortung machen.
One-sentence Summary
Microsoft AI & Research presents MS MARCO, a large-scale machine reading comprehension dataset comprising 1,010,916 anonymized real Bing queries with human-generated answers and 8,841,823 extracted passages, and proposes three tasks—answerability prediction, answer generation, and passage ranking—that, by virtue of its scale and real-world origin, distinguish it from earlier datasets, establishing a compelling benchmark for question-answering models.
Key Contributions
- The paper introduces MS MARCO, a large-scale machine reading comprehension dataset containing 1,010,916 anonymized real user questions from Bing search logs, human-generated answers, and 8,841,823 passages extracted from web documents.
- The dataset defines three tasks of increasing difficulty: predicting answerability and synthesizing an answer, generating a well-formed answer from context passages, and ranking retrieved passages for a given question.
- The scale and real-world query origin of MS MARCO distinguish it from existing MRC datasets, providing a benchmark for evaluating natural language answer generation and neural information retrieval models.
Introduction
Machine reading comprehension (MRC) is a critical capability for intelligent assistants, chatbots, and spoken interfaces, but deploying it in the wild requires models that can handle noisy text, conflicting information, and answers that span multiple documents. Existing MRC datasets often fall short: they are too small to train large neural models, rely on synthetic or crowd-sourced questions not drawn from real user queries, use clean source material like Wikipedia, and typically demand answers from a single text span. The authors introduce MS MARCO, a large-scale dataset of over one million anonymized Bing search queries paired with web-retrieved passages and human-generated, free-form answers; it includes unanswerable questions and requires models to extract and synthesize information from multiple passages, addressing the realism and scale gaps of prior benchmarks.
Dataset
The authors introduce the MS MARCO dataset, a large-scale machine reading comprehension collection built from real-world Bing search queries. Its composition and processing are described below.
Dataset composition and sources
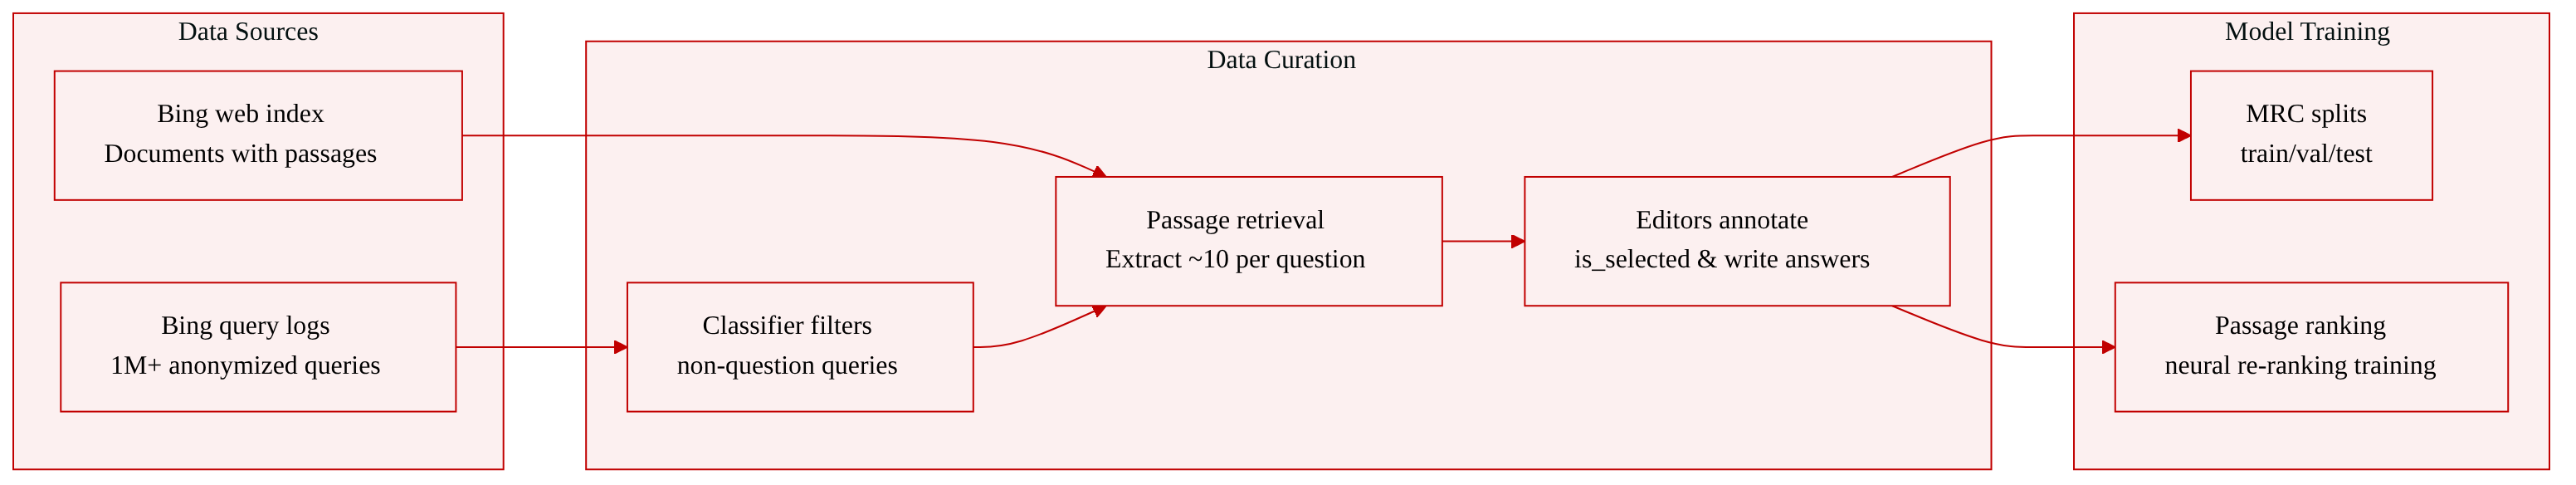
- The dataset comprises 1,010,916 questions, 1,026,758 unique answers, and roughly 10 million passages (average 10 per question). All questions originate from anonymized Bing search logs.
- A machine learning classifier first filters out non‑question queries. Editors then further annotate whether each question is answerable using the provided passages.
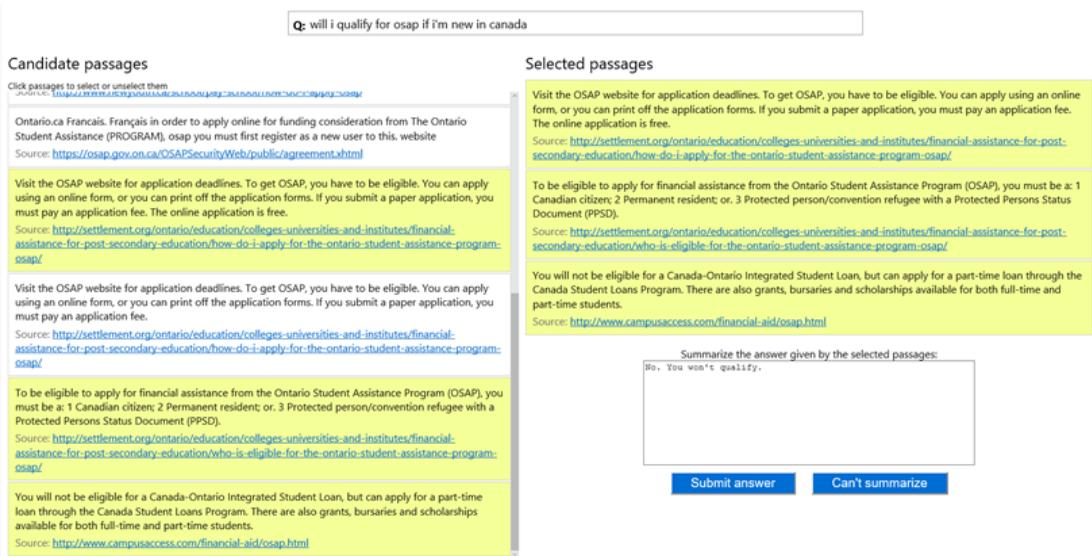
- Relevant web documents are retrieved using Bing’s large‑scale index, and passages are automatically extracted from those documents. Human editors mark passages that contain useful information (
is_selected) and compose natural language answers strictly from the passage content.
Key subsets and details
- Questions: Filtered question queries from Bing logs. An additional classifier labels each question with a segment type: NUMERIC, ENTITY, LOCATION, PERSON, or DESCRIPTION.
- Passages: For each question, about 10 passages are retrieved. Editors annotate which passages they used to write the answer (
is_selected=1) and set all to 0 when no answer is present. - Answers: Manually written answers; some questions have multiple answers, some have none. Answers are synthesized only from the provided passages.
- Well‑formed answers: A separate editor rewrites a subset of answers to improve grammar, reduce verbatim overlap with passages, and make answers self‑contained (e.g., “There are 16 tablespoons in a cup.”).
- Documents: Post‑processed from Bing’s index, containing URL, body text, and title. Roughly 300,000 documents could not be retrieved because they were no longer in the index.
- Question types: Automatically assigned segment labels, as listed above.
Derived passage ranking dataset
- The authors take the union of all passages from MS MARCO (about 10 million) and create a collection of question–passage relevance pairs using the
is_selectedannotation. This annotation is incomplete—passages that are relevant but not selected by editors are not marked. - This subset is used to propose a re‑ranking challenge and to set up an ad‑hoc retrieval task at the TREC 2019 Deep Learning track.
How the paper uses the data
- The full MS MARCO dataset serves as a challenging benchmark for training and evaluating machine reading comprehension models, reflecting real user information needs with complex, sometimes ambiguous queries.
- The passage ranking dataset is employed for training neural ranking models. The
is_selectedlabels act as training signals for relevance, even though they are sparse. - The paper does not explicitly detail training/validation/test splits here, but the standard MS MARCO release includes predefined splits for training, development, and test sets.
Method
The authors design three machine learning tasks of progressive difficulty using the MS MARCO dataset, each targeting a distinct capability in question answering and information retrieval. These tasks collectively form a structured benchmark for evaluating both generative and reranking-based systems.
The novice task focuses on answerability detection and concise answer generation. The system must first determine whether the question can be answered solely from the provided passages. If the answer is not supported, the system must output “No Answer Present”. Otherwise, it should generate the correct answer in a minimal form, without any requirement for natural language fluency.
The intermediate task extends the novice task by requiring well-formed answers. The system again decides answerability, but when an answer exists, the generated text must be self-contained and readable when spoken aloud, even without the original question and passage context. This forces the model to produce grammatically coherent, context-independent responses.
The passage re-ranking task shifts the focus to information retrieval. For a given question, the system receives a set of 1000 candidate passages retrieved by BM25. It must produce a relevance ranking of these passages, ordered by their likelihood of containing information needed to answer the question. This task is designed to provide a large-scale dataset for training and evaluating neural IR models, complementing the generative challenge of the other two tasks.
Experiment
The experiments evaluate generative, discriminative, and cloze‑style models on the MS MARCO v1.1 dataset using metrics tailored to different answer types, and then benchmark a reading comprehension model on the v2.1 dataset. The v2.1 dataset is found to be more difficult, as models struggle with unanswerable questions and with generating answers that require vocabulary outside the provided passages.
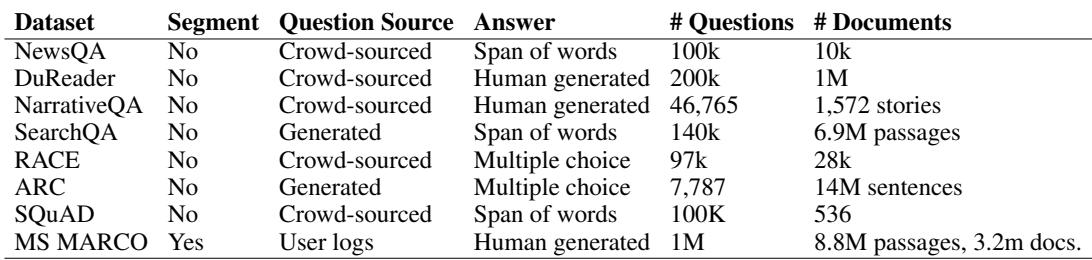
The table compares MS MARCO with several established MRC datasets, all of which are non-segmented. Unlike MS MARCO, these datasets rely entirely on crowd-sourced or algorithmically generated questions, and their answer formats span extractive spans, human-written responses, or multiple-choice options. All listed datasets have 'Segment' marked as No, contrasting with MS MARCO's segmented structure. Question sources are either crowd-sourced or generated, while MS MARCO uses real user queries from Bing. Answer types include span-of-words, human-generated, and multiple-choice, whereas MS MARCO provides human-generated answers.
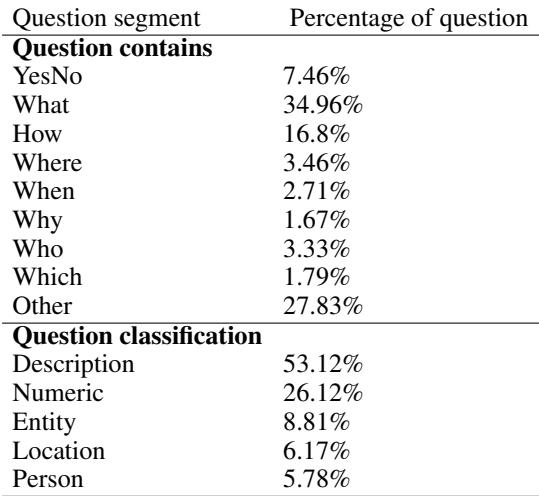
The answer-type distribution shows a strong skew toward 'What' questions, which form the largest single category at roughly 35%. 'How' and yes/no questions are the next most frequent, while 'Where', 'When', and 'Why' queries each appear in only a small fraction of the dataset. 'What' questions dominate, making up about 35% of all queries in the dataset. Yes/no and 'How' questions together account for over 24% of the data, whereas 'Where', 'When', and 'Why' each remain below 4%.
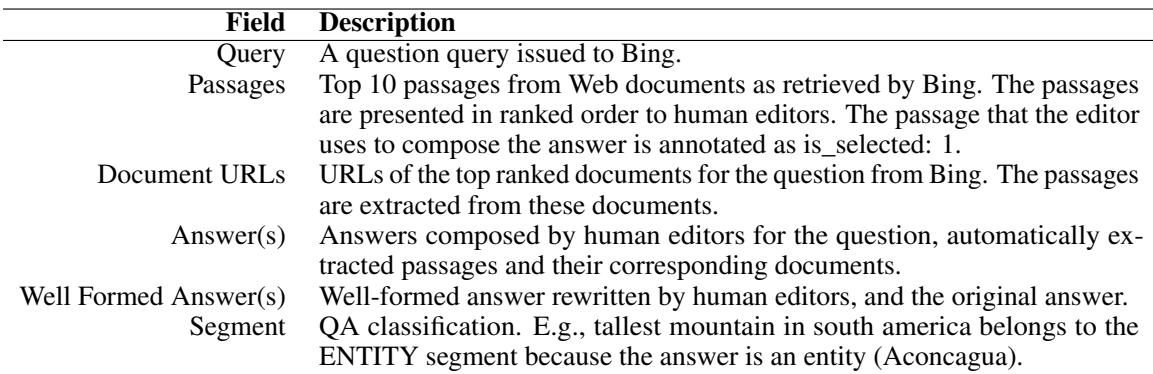
The MS MARCO dataset is built from real Bing search queries filtered to question intents, with passages extracted from top-ranked web documents. Human editors select relevant passages and compose natural language answers, while also providing a rewritten well-formed answer. The dataset includes a segment classification for each question-answer pair. Queries are real user questions from Bing logs, filtered by a machine learning classifier to exclude navigational and non-question intents. The top 10 passages retrieved by Bing are presented to editors, who mark the passage used to compose the answer as selected. Editors generate both an original answer and a well-formed answer that may use general vocabulary beyond the passage. Each QA pair is classified into a segment, such as ENTITY for questions like 'tallest mountain in south america'.
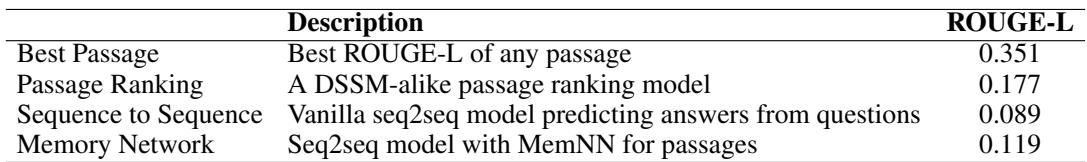
On a subset of MS MARCO, the best achievable ROUGE-L from any passage is 0.351. Among the trained models, a DSSM-like passage ranking approach reaches 0.177, outperforming the generative models by a wide margin. The vanilla sequence-to-sequence model and the memory network obtain 0.089 and 0.119, respectively, indicating that passage ranking is far more effective for this task. The passage ranking model's ROUGE-L (0.177) is roughly double that of the vanilla sequence-to-sequence model (0.089). The memory network improves over the vanilla seq2seq model but still falls well below the passage ranking baseline. The oracle best passage score of 0.351 suggests substantial headroom for all models.
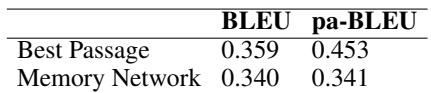
On the multi-answer MS MARCO subset, the best passage baseline achieves higher BLEU and substantially higher pa-BLEU than the memory network model. The memory network's pa-BLEU score is nearly identical to its BLEU, while the best passage baseline exhibits a large gain from BLEU to pa-BLEU. The best passage baseline outperforms the memory network on both metrics, with a particularly large margin in pa-BLEU. The memory network shows almost no difference between BLEU and pa-BLEU, in contrast to the best passage baseline where pa-BLEU is much higher than BLEU.
The evaluation compares MS MARCO against existing MRC datasets, highlighting its unique use of real user queries, segmented structure, and human-generated answers, and examines the distribution of question types, which is heavily skewed toward "What" questions. The dataset construction process involves filtering Bing queries and having editors select passages and compose natural language answers, with each pair assigned a segment label. Experiments on a subset demonstrate that passage ranking models substantially outperform generative approaches, and the oracle best passage score indicates significant headroom for improvement. In a multi-answer setting, selecting the best passage again proves more effective than a memory network, with a pronounced gain in passage-aware BLEU.