Command Palette
Search for a command to run...
通过卷积实现更深网络
通过卷积实现更深网络
Christian Szegedy Wei Liu Yangqing Jia Pierre Sermanet Scott Reed Dragomir Anguelov Dumitru Erhan Vincent Vanhoucke Andrew Rabinovich
摘要
我们提出了一种名为 Inception 的深度卷积神经网络架构,在 ImageNet 大规模视觉识别挑战赛 2014(ILSVRC14)中实现了分类和检测的新最优性能。该架构的主要特征在于对网络内部计算资源的更高效利用。通过精心的设计,我们在保持计算预算不变的情况下增加了网络的深度和宽度。为了优化性能质量,架构设计基于赫布原理和多尺度处理的直觉。我们在 ILSVRC14 提交中使用的一个特定实现版本称为 GoogLeNet,这是一个 22 层深的网络,其性能在分类和检测任务中进行了评估。
一句话总结
Google Inc.、北卡罗来纳大学、密歇根大学和 Magic Leap Inc. 提出 GoogLeNet(Inception),一种 22 层卷积网络,在保持计算预算不变的情况下,通过利用由 Hebbian 原则指导的多尺度处理来增加深度和宽度,在 ILSVRC14 分类和检测上取得 state-of-the-art 结果。
核心贡献
-
Inception 架构以 22 层 GoogLeNet 模型实现,通过增加网络深度和宽度、同时几乎保持计算预算不变,提升图像分类和物体检测性能。
-
论文提出了一种面向高效卷积神经网络的设计原则:由 Hebbian 原则和多尺度特征处理直觉指导,使用适合密集硬件的密集构建模块来近似有用的稀疏网络结构。
-
Inception 架构在 ILSVRC14 分类和检测基准上取得新的 state-of-the-art 性能,并在不使用上下文信息或 bounding box regression 的情况下获得有竞争力的物体检测。
引言
在计算机视觉中,深度卷积网络快速提升了物体分类和检测性能,其效率对于移动和嵌入式应用尤其重要。早期方法通常通过使网络更深、更宽或更大来获得精度,这会提升参数量、过拟合风险和计算成本,而真正稀疏的设计难以在密集硬件上高效实现。作者提出 Inception 架构,并以 GoogLeNet 实现,它使用密集组件,包括用于降维的 1x1 卷积,以近似稀疏网络结构,并在固定推理预算下增加深度和宽度,同时取得强 ImageNet 分类和检测结果。

方法
作者围绕 Inception 模块构建模型,该模块旨在用可高效实现的密集组件来近似最佳局部稀疏卷积结构。起始假设是平移不变性,这意味着网络由重复的卷积构建模块组成。设计从检查相关单元如何在层中出现开始。在较低层,高度相关的单元通常集中在较小局部区域,这可以用 1×1 卷积高效表示。同时,一些相关范围扩展到更大空间区域,需要更大的感受野,例如 3×3 和 5×5 卷积。由于池化操作在卷积视觉网络中被认为有价值,所以也包含池化路径。这些并行分支的输出被拼接为一个向量,作为下一阶段的输入。参考框架图。

图中还显示了使模块高效的实际修改。直接在大量输入通道上应用 5×5 卷积的朴素版本计算代价高昂,尤其是同时拼接池化输出时。因此作者在更昂贵的 3×3 和 5×5 卷积之前引入 1×1 卷积进行降维。这些 1×1 层有两个作用:减少输入通道数以限制计算,并包含 rectified linear activation,因此也是非线性变换。这使 Inception 模块具有多尺度结构,同时保持参数量和浮点运算数可控。随着模块堆叠,更高层预计包含更抽象的特征,其空间集中度降低,因此在更深层中更大卷积的相对使用可以增加。
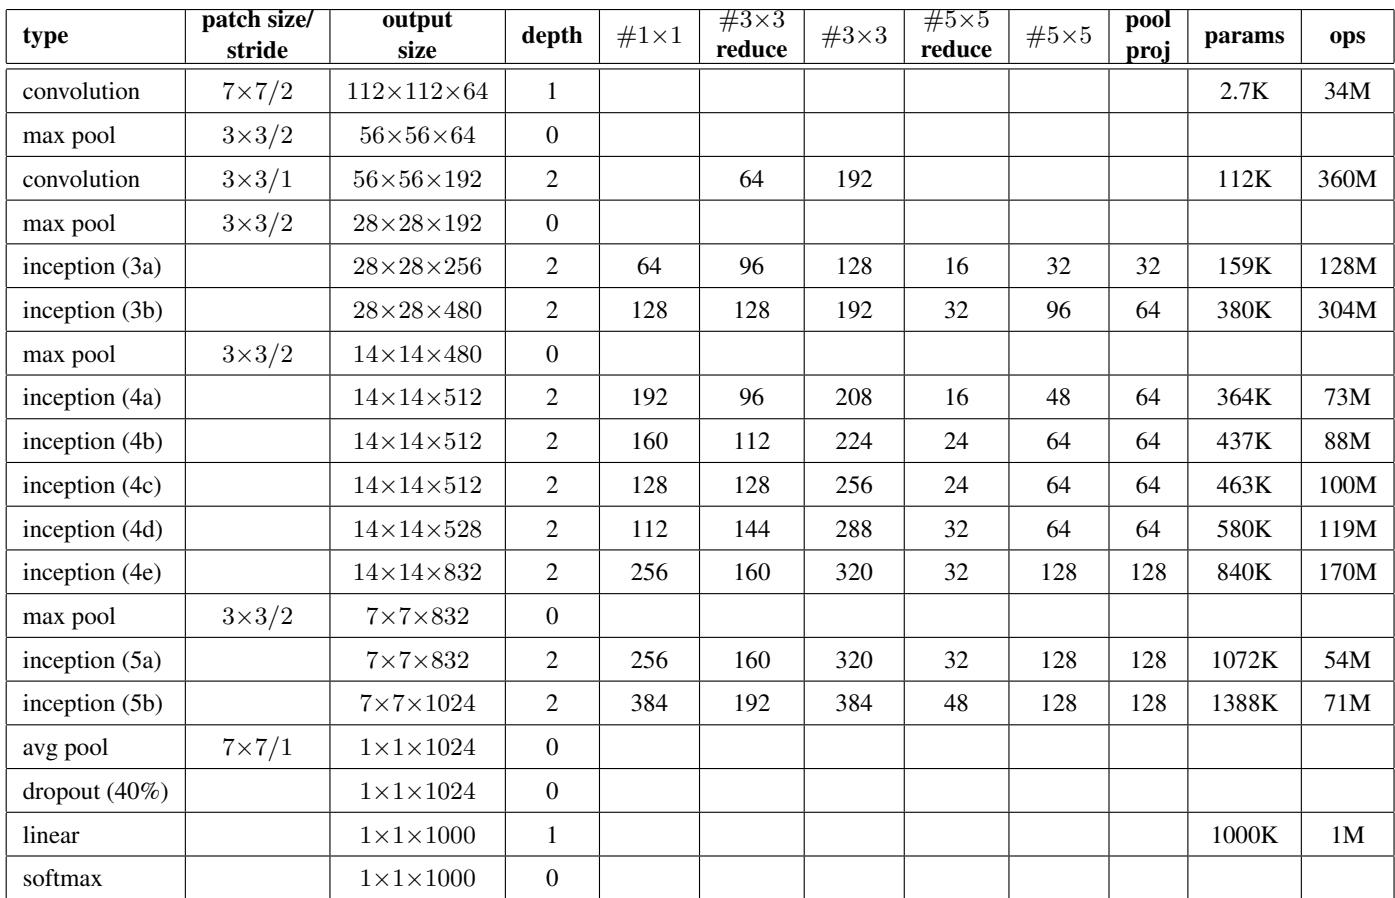
完整的 GoogLeNet 架构反复使用这些模块作为主要构建模块。网络接受 224×224 RGB 输入,并采用零均值归一化。早期层使用常规卷积、池化和归一化,然后架构过渡为堆叠的 Inception 模块。在模块组之间,max-pooling 层降低空间分辨率。网络包含 22 个可训练参数层,如果单独计算池化层则为 27 层,并且大约有 100 个独立构建模块,具体取决于实现如何分组操作。所有卷积,包括 Inception 模块内部,都使用 rectified linear activation。如下网络示意图所示:

示意图显示完整分类流程:底部输入处理、多个深度拼接 Inception 块、通过 max-pooling 进行空间缩减,以及分类器前的最终缩减。网络不依赖大型全连接层,而是在分类前使用 average pooling,随后接一个小的 linear layer。linear layer 有助于使网络适配不同 label sets,而 average pooling 替代 fully connected layers 以提升效率并改善 top-1 accuracy。在转向 average pooling 之后,Dropout 仍然重要。
为了解决梯度可能难以在如此深网络中传播的担忧,作者在中间 Inception 模块附加 auxiliary classifiers,具体是模块 (4a) 和 (4d) 的输出。这些辅助分支促使中间特征具有判别性,降低 gradient vanishing 风险,并提供额外 regularization。每个 auxiliary classifier 包含一个带有 5×5 filter 和 stride 3 的 average pooling layer,一个包含 128 filters 并带有 rectified linear activation 的 1×1 convolution,一个包含 1024 units 并带有 rectified linear activation 的 fully connected layer,一个带有 70% drop rate 的 Dropout layer,以及一个预测与主输出相同目标类别的 linear softmax classifier。During training,auxiliary losses 以 discount weight 加到主损失上,形成如下形式的总目标
Ltotal=Lmain+0.3Laux0+0.3Laux1.Inference time 时,丢弃 auxiliary classifiers,仅使用主网络。
训练使用 DistBelief distributed machine learning system,具有适度的 model and data parallelism。优化基于 momentum 0.9 的 asynchronous stochastic gradient descent。learning rate 遵循每 8 epochs 下降 4% 的 schedule。使用 Polyak averaging 生成最终 inference model。Training procedure 还强调 patch sampling 和 data augmentation 以提升 robustness。作者描述采样 image patches,其 area 分布在全图面积的 8% 到 100% 之间,并 aspect ratio 限制在区间 [3/4,4/3]。还应用 photometric distortions 以减少对训练数据特定 imaging conditions 的过拟合。
实验
实验在 ILSVRC 2014 ImageNet classification 和 detection 挑战中评估 GoogLeNet,测试核心架构和实际 inference enhancements。Classification results 验证:训练多个 model variants,使用广泛的 multi-scale 和 multi-crop testing,以及 averaging predictions,可在不使用 external data 的情况下提升 top-level performance,而额外 models 和 crops 的收益递减。Detection experiments 验证了一种基于 Inception 的 R-CNN-style pipeline,结合改进 region proposals 和 ensemble region classification,表明相比早期 detection approaches 取得大幅进展,并且 ensembling 带来显著收益。
所描述的 Inception 架构的 GoogLeNet 版本使用 repeated Inception modules,带有 1x1 reduction 和 projection layers,以保持 computation 和 memory requirements 较低。其设计强调 efficient inference 和 modest parameter counts,同时用 average pooling 替换 fully connected layers 可提升 accuracy,虽然 Dropout 仍然必要。同一架构在六个模型的 ensemble 中也能支持 strong detection results。在 3x3 和 5x5 convolutions 前的 1x1 reduction layers,以及 1x1 pool projections,是该架构的关键 efficiency feature。classifier 前的 average pooling 将 top-1 accuracy 提升约 0.6 个百分点,但即使移除 fully connected layers 后 Dropout 仍然重要。使用六个 GoogLeNet 模型 ensemble 进行 region classification,使 detection accuracy 从 40 个百分点提升至 43.9 个百分点。
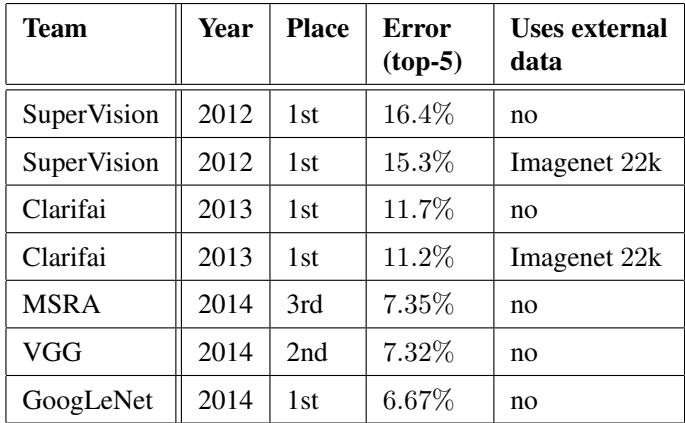
Classification results 使用 top-5 error 比较 2012 到 2014 的 top ILSVRC entries。Error rates 随时间稳定下降,2014 年 leading result 优于 earlier winners。Top 2014 entry 在不使用 external data 的情况下取得该结果,而一些 earlier top entries 使用了 ImageNet 22k pretraining。Top-5 error 从最早列出的 winners 到 2014 leaders 显著下降。GoogLeNet 在列出的 2014 entries 中排名第一,并具有最低 reported top-5 error。对于同一 team 和 year,使用 external ImageNet 22k data 的 entry 比 no-external entry 具有更低 top-5 error。
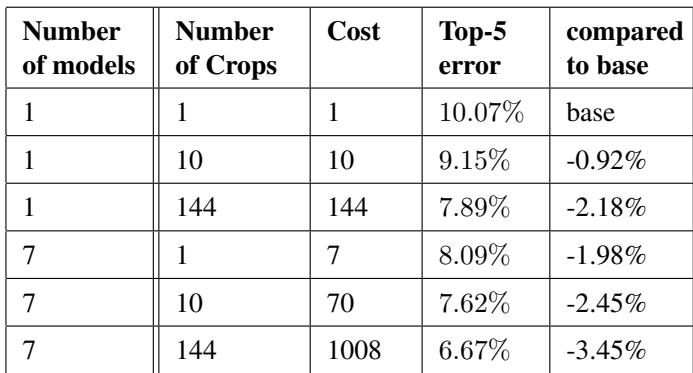
增加 ensemble model 数量和 test-time crops 会降低 top-5 error,两者同时应用时降低最强。Aggressive cropping 带来的单模型提升大于将 crops 从 one 增加到 ten,而 model ensembling 也有帮助。Validation results 显示,better accuracy 与 higher testing cost 相互权衡。与 a single crop 相比,使用 ten crops 适度降低 top-5 error 在 one crop 上测试时 Seven models 比 ten crops alone 降低更多 error 将 Seven models 与 many crops 组合 gives the lowest top-5 error 尽管 cost much higher
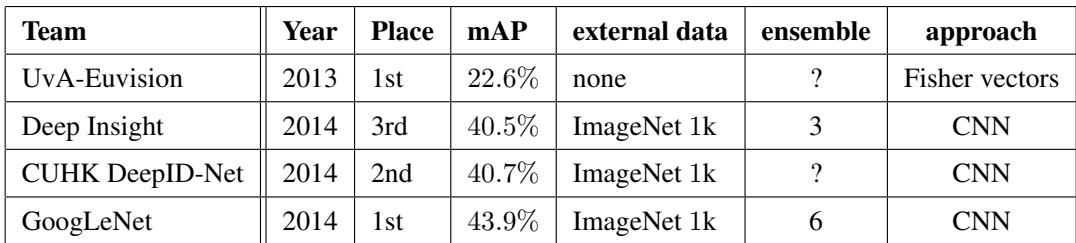
Reported detection results 显示出从 2013 到 2014 的大幅提升,leading entries 使用 convolutional networks,而不是 earlier Fisher vector approaches。Top entry 结合 external ImageNet pretraining 与 large model ensemble,而接下来 CNN-based entries 彼此接近,并使用 fewer 或 unreported ensembles。Ensembling 似乎是重要 differentiator,因为 top entry 强烈受益于它,而 another strong method 只获得 modest 提升。Convolutional networks 主导 leading 2014 detection results。External ImageNet pretraining 在 top 2014 teams 中常见。Top result 因取得 highest reported mean average precision 而突出。Ensemble size 似乎是 leading approaches 之间的重要 differentiator。
Single-model detection results 显示,Deep Insight 在 reported teams 中取得 highest mAP,GoogLeNet 紧随其后。尽管没有使用 contextual model 或 bounding box regression,GoogLeNet 仍具竞争力,而 leading Deep Insight model 使用 both strategies。Deep Insight 在 single-model detection performance 上领先。GoogLeNet 在不使用 contextual modeling 或 bounding box regression 的情况下达到 strong accuracy。
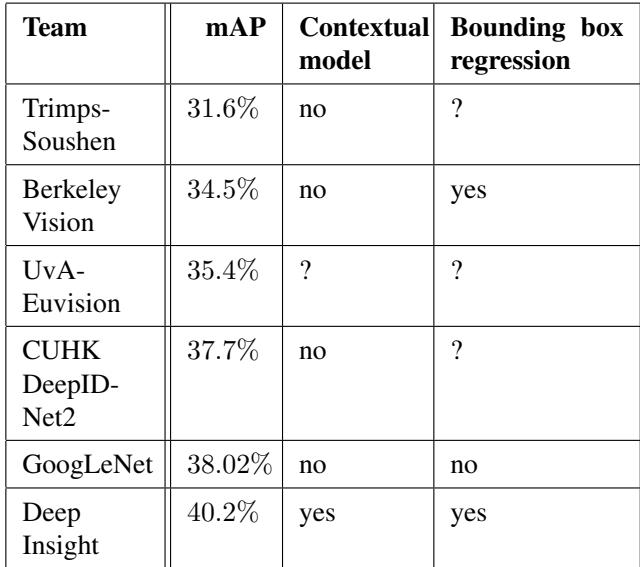
实验评估 GoogLeNet’s architecture and performance 在 large-scale image classification 和 object detection tasks 上,并与 leading ILSVRC entries 和 single-model detection methods 比较。Results 显示,efficient Inception design elements、average pooling、ensembling 和 multiple test-time crops 能提升 accuracy,同时也增加 testing cost。Across classification and detection settings,GoogLeNet 展现出 strong competitiveness,其中 external pretraining、larger ensembles 和 convolutional architectures 在 best-performing approaches 中起重要作用。