Command Palette
Search for a command to run...
Modèles de diffusion responsables via la contrainte des plongements de texte dans des régions sûres
Modèles de diffusion responsables via la contrainte des plongements de texte dans des régions sûres
Résumé
La capacité remarquable des modèles de diffusion à générer des images de haute fidélité a conduit à leur adoption généralisée. Cependant, des préoccupations ont également émergé concernant leur potentiel à produire du contenu Not Safe for Work (NSFW) et à présenter des biais sociaux, entravant leur utilisation pratique et leur progression dans des applications réelles. En réponse à ce défi, les travaux antérieurs se sont principalement concentrés sur l'utilisation de filtres de sécurité pour identifier puis exclure les textes toxiques, ou alternativement, sur le réglage fin de modèles de diffusion pré-entraînés pour effacer les concepts sensibles. Malheureusement, les méthodes existantes peinent à atteindre des performances satisfaisantes dans la mesure où elles peuvent avoir un impact significatif sur la sortie normale du modèle tout en échouant encore à empêcher la génération de contenu nuisible dans certains cas. Dans cet article, nous proposons une nouvelle approche d'auto-découverte pour identifier un vecteur de direction sémantique dans l'espace de plongement afin de restreindre le plongement de texte dans une région sûre. Notre méthode évite le besoin de corriger des mots individuels dans le texte d'entrée et oriente l'intégralité de l'invite textuelle vers une région sûre dans l'espace de plongement, améliorant ainsi la robustesse du modèle contre toutes les invites potentiellement dangereuses. De plus, nous employons une adaptation de faible rang (LoRA) pour l'initialisation du vecteur de direction sémantique afin de réduire l'impact sur la performance du modèle pour d'autres sémantiques. En outre, notre méthode peut également être intégrée à des méthodes existantes pour améliorer leurs performances socialement responsables. Des expériences approfondies sur des ensembles de données de référence démontrent que notre méthode peut réduire efficacement le contenu NSFW et atténuer les biais sociaux générés par les modèles de diffusion par rapport à plusieurs références de pointe.
One-sentence Summary
Researchers propose a self-discovery method that identifies a semantic direction vector to constrain text embeddings within a safe region in embedding space, employing Low-Rank Adaptation for initialization, thereby reducing NSFW content and social bias in diffusion models without per-word correction and integrating with existing safeguards to enhance robustness across unsafe prompts.
Key Contributions
- The paper introduces a novel self-discovery approach that learns a semantic direction vector in the CLIP embedding space, steering entire text prompts toward a safe region and improving robustness against all potentially unsafe prompts without relying on word-level corrections.
- The method adopts Low-Rank Adaptation (LoRA) for semantic direction vector initialization, which preserves model performance on unrelated semantics and can be integrated with existing responsible generation methods to further reduce harmful outputs.
- Experiments on benchmark datasets show that the approach effectively reduces NSFW content and mitigates social bias in diffusion models, outperforming several state-of-the-art baselines in safe and fair generation tasks.
Introduction
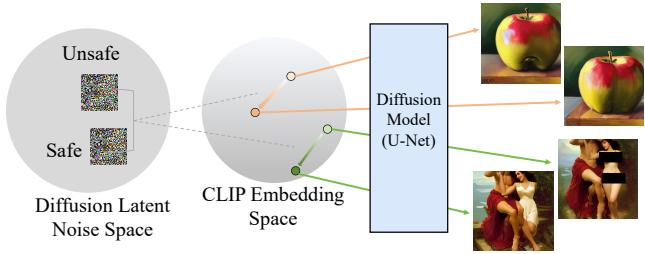
Text-to-image diffusion models can generate photorealistic images from text descriptions, but they often produce unsafe or biased content, including pornography, violence, gender discrimination, and racial prejudice. Prior approaches fall into two broad categories. The first relies on external classifiers to detect and reject toxic input, yet these mechanisms are unreliable because prompts without explicit NSFW terms, such as "a beautiful woman," can still trigger unsafe image generation. The second category tries to build more responsible models through data cleaning, parameter fine-tuning, model editing, or intervention in the inference process. Data filtering and retraining are computationally expensive and degrade performance. Fine-tuning risks catastrophic forgetting. Model editing methods typically modify projection matrices in cross-attention layers for specific target words, yielding poor results for related but non-targeted concepts. Inference-time interventions avoid parameter updates but can alter image semantics and add overhead. Existing prompt-tuning methods train pseudo-tokens to symbolize specific concepts, but these operate at the token level and fail to capture global semantic directions. The authors propose a novel self-discovery approach that identifies a semantic direction vector in the embedding space and constrains text prompt embeddings within a safe region. They leverage classifier-free guidance to learn a low-rank direction vector that moves the text embedding along specific semantic dimensions without affecting other semantics. This approach reduces NSFW content generation and mitigates social bias in stable diffusion models, and it can combine linearly with existing methods to further enhance responsible generation.
Method
The authors propose a method to identify semantic directions within the text embedding space, enabling precise control over diffusion model generation for safe and fair outcomes. This approach, termed Latent Region Anchoring, involves identifying a direction vector that steers the generated content towards or away from specific target concepts.
Initially, the method explores a linear approach in the CLIP embedding space. By computing the difference between the embeddings of two contrasting prompts (e.g., "a person" versus "a person wearing clothes"), a direction vector is derived.
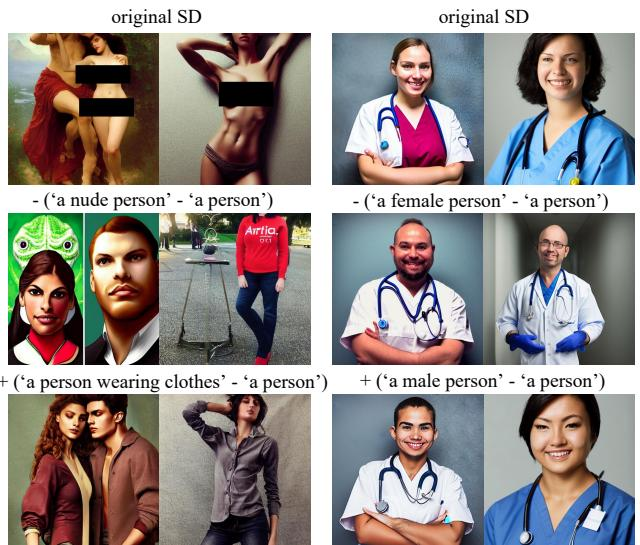
As shown in the figure below, this naive subtraction effectively alters specific attributes such as nudity or gender. However, it often introduces unintended distortions and affects unrelated features, indicating that a simple difference vector is insufficient for precise and safe control.
To address these limitations, the authors employ an optimization strategy integrated directly into the diffusion denoising process. The goal is to find a direction vector d that minimizes the discrepancy between the noise predicted by the augmented base prompt and a target noise distribution derived from the target concept co.
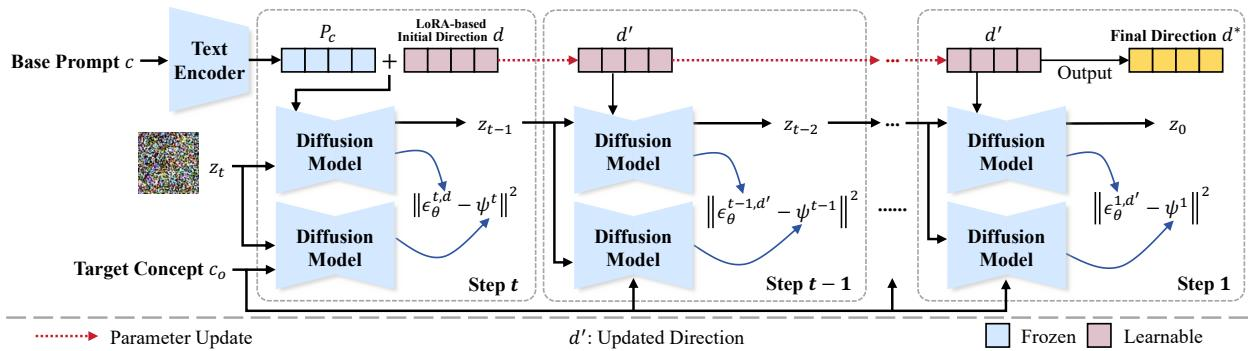
Refer to the framework diagram. The process utilizes classifier-free guidance to define target noise estimates, ϵ~θ+ for moving towards the concept and ϵ~θ− for moving away. The optimization minimizes the following objective:
d∗=argdminc∼D∑t∼[0,T]∑∥ϵθ(zt,c+d,t)−ψ(zt,co,t)∥2Crucially, this optimization occurs dynamically during the iterative denoising steps. The direction vector is updated at each time step t to influence the subsequent step t−1, allowing the model to learn a precise semantic trajectory that aligns with the target concept throughout the generation process.
Regarding the initialization of the direction vector d, the authors note that standard full-rank initialization often leads to distorted images due to the sensitivity of the embedding space.
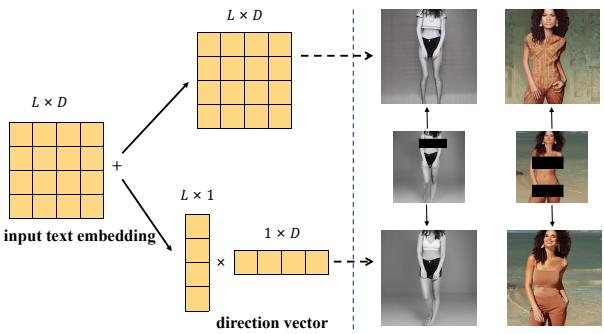
As illustrated in the figure below, the authors address this by adopting Low-Rank Adaptation (LoRA) for initialization. Instead of a full-rank vector, the direction is initialized as a product of two low-rank matrices, d=BA, where B is initialized to zeros and A is drawn from a normal distribution. This constrains the search space, allowing the model to amplify relevant features without disrupting the primary pre-trained representations.
During inference, the learned direction vectors are applied to the prompt embedding Pc with a guidance coefficient. For safe generation, the direction pointing away from unsafe concepts is added to prevent inappropriate content. For fair generation, direction vectors corresponding to sensitive attributes (e.g., gender) are randomly selected and added with equal probability to ensure balanced attribute distribution in the outputs.
Experiment
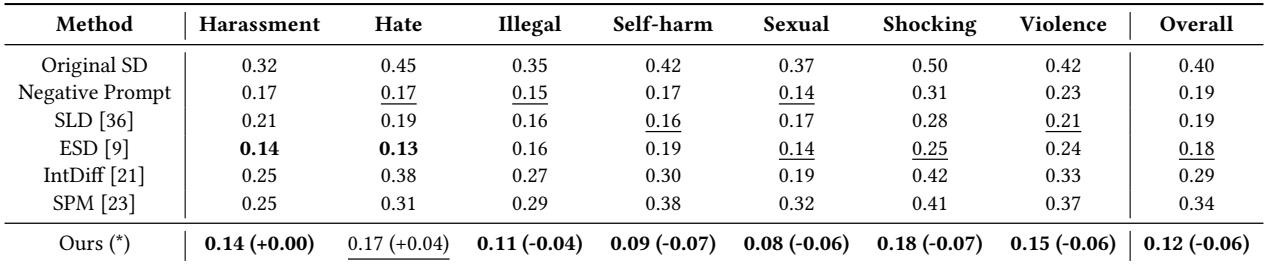
The experiments validate the method's effectiveness in both safe and fair generation tasks using Stable Diffusion. For safety, direction vectors learned in embedding space suppressed inappropriate content across categories on the I2P benchmark and adversarial prompts, outperforming baselines except in the 'hate' category. For fairness, vectors applied to gender and race attributes reduced social bias and achieved the lowest average deviation ratio on Winobias compared to baseline methods. The direction vectors also transferred well to existing fine-tuning approaches and models with different architectures, could be linearly combined for multi-attribute control with some weakening of individual effects, and maintained image quality and text alignment on par with the original model.
The proposed method achieves the lowest inappropriate content detection ratios on the I2P benchmark across most unsafe prompt categories, outperforming all baselines in six of seven categories. It is second-best only in the hate category, where ESD is slightly better. Overall, the method shows consistent and substantial reductions in unsafe content generation compared to existing approaches. Achieves the best performance in harassment, illegal, self-harm, sexual, shocking, and violence categories. Second-best only in the hate category, where ESD yields a lower detection ratio. Overall detection ratio is the lowest among all compared methods, including original SD and negative prompting.
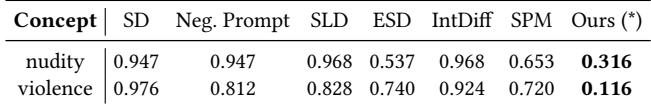
The table reports the ratio of inappropriate images generated from adversarial prompts for nudity and violence. the method consistently achieves the lowest ratios on both categories, demonstrating superior robustness against adversarial attacks compared to all baselines. For nudity, the method yields a ratio of 0.316, roughly half that of the closest baseline ESD at 0.537. For violence, the ratio is 0.116, far below the best baseline SPM at 0.720. Original SD and negative prompting produce very high ratios, indicating they are largely ineffective on these adversarial prompts.
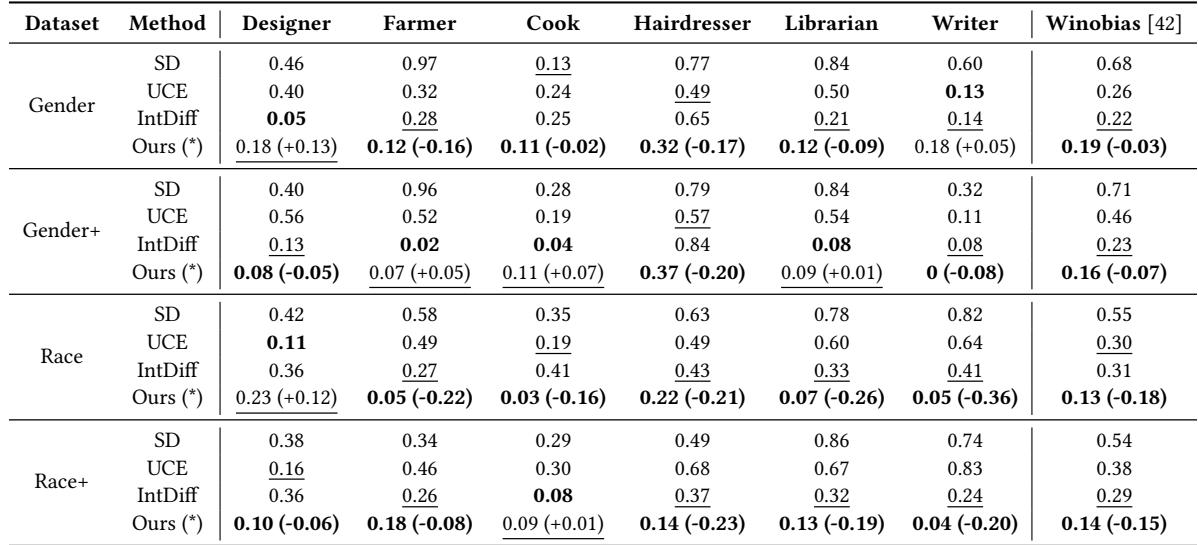
The proposed method achieves the lowest average deviation ratios across both standard and extended prompt templates, indicating fairer generated images. It consistently performs best or second best across sampled professions, while baseline methods like UCE show greater sensitivity to template changes. The proposed method attains the lowest average deviation ratio for both normal and extended templates, corresponding to the most balanced attribute distributions. It ranks best or second best in most sampled professions, whereas UCE exhibits notable performance drops under the more challenging extended templates.
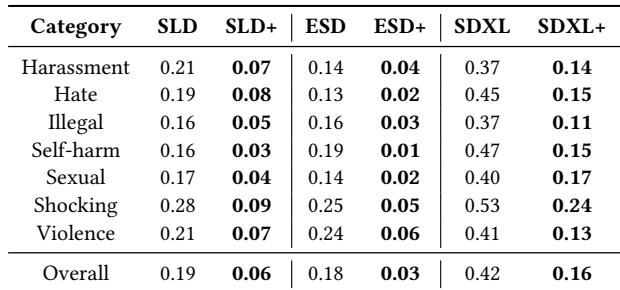
The proposed direction vectors improve safety performance when integrated with existing methods like SLD, ESD, and SDXL on the I2P benchmark. Across all categories, the combined approaches consistently lower unsafe scores, with notable reductions for ESD and SLD. The method also transfers to SDXL after retraining, showing effectiveness in models with multiple text encoders. Integrating the direction vectors reduces unsafe scores for SLD, ESD, and SDXL across every category tested. The improvements are most pronounced for ESD, where scores drop dramatically, often to near zero. For SDXL, which requires shape adjustment and retraining due to its dual-encoder architecture, the method still yields substantial reductions in unsafe generation.
On the COCO-30K benchmark, the proposed method maintains image fidelity and text alignment comparable to the original Stable Diffusion, while other debiasing approaches show larger degradations in either FID or CLIP scores. This indicates that the learned semantic direction is accurate and does not disrupt unrelated semantics. The method yields FID and CLIP scores close to the original Stable Diffusion, whereas SLD and ESD show noticeably worse fidelity and alignment. Compared with other debiasing techniques, the proposed approach strikes a better balance between reducing unwanted biases and preserving generation quality. The close-to-baseline performance suggests the semantic direction vector acts on relevant attributes without broadly harming prompt-image consistency.
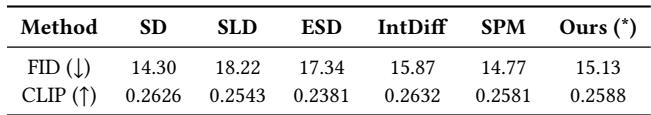
The proposed method was evaluated across multiple benchmarks, including I2P for safety, adversarial prompts for robustness, fairness tests with standard and extended templates, and COCO-30K for generation quality. It consistently achieved the lowest inappropriate content detection ratios in most safety categories, outperformed baselines on adversarial nudity and violence prompts, and produced the most balanced attribute distributions across professions. Additionally, integrating the learned direction vectors improved safety for existing methods like SLD and ESD, while preserving image fidelity and text alignment on COCO-30K, demonstrating that the approach reduces unsafe and biased generation without sacrificing overall quality.