Command Palette
Search for a command to run...
Tous les jetons ne sont pas ce qu'il vous faut pour le pré-entraînement
Tous les jetons ne sont pas ce qu'il vous faut pour le pré-entraînement
Résumé
Les méthodes précédentes de pré-entraînement de modèles de langage appliquaient uniformément une perte de prédiction du jeton suivant à l'ensemble des jetons d'entraînement. Remettant cette norme en question, nous avançons l'hypothèse selon laquelle « tous les jetons d'un corpus ne sont pas d'importance égale pour l'entraînement des modèles de langage ». Notre analyse préliminaire examine les dynamiques d'entraînement au niveau du jeton du modèle de langage, révélant des motifs de perte distincts pour différents jetons. En tirant parti de ces observations, nous introduisons un nouveau modèle de langage appelé RHO-1. Contrairement aux modèles de langage traditionnels qui apprennent à prédire chaque jeton suivant dans un corpus, RHO-1 met en œuvre une Modélisation Sélective du Langage (SLM), qui n'entraîne que sur les jetons utiles alignés avec la distribution souhaitée. Cette approche consiste à attribuer un score aux jetons à l'aide d'un modèle de référence, puis à entraîner le modèle de langage avec une perte ciblée sur les jetons obtenant les scores les plus élevés. Lors du pré-entraînement continu sur un corpus OpenWebMath de 15 milliards de jetons, RHO-1 produit une amélioration absolue de la précision en mode few-shot allant jusqu'à 30 % sur 9 tâches mathématiques. Après réglage fin, RHO-1-1B et 7B atteignent des résultats de pointe de 40,6 % et 51,8 % respectivement sur le jeu de données MATH — rivalisant avec DeepSeekMath avec seulement 3 % des jetons de pré-entraînement. De plus, lors du pré-entraînement continu sur 80 milliards de jetons généraux, RHO-1 réalise une amélioration moyenne de 6,8 % sur 15 tâches variées, augmentant à la fois l'efficacité en données et les performances du pré-entraînement de modèles de langage.
One-sentence Summary
Researchers from Xiamen University, Tsinghua University, and Shanghai AI Laboratory propose RHO-1, a language model that diverges from uniform next-token prediction by introducing Selective Language Modeling (SLM), which uses a reference model to score and filter tokens for focused loss computation, achieving up to 30% absolute improvement on 9 math tasks and state-of-the-art MATH results matching DeepSeekMath with only 3% of the pretraining tokens.
Key Contributions
- Token-level analysis of pretraining dynamics shows that substantial loss reduction occurs mainly on selected tokens, while many easy tokens and difficult tokens can cause inefficient gradient updates.
- RHO-1 introduces Selective Language Modeling, in which a reference model scores tokens according to a desired distribution and the target model is trained with a focused loss only on tokens with high reference-model scores or large excess loss.
- Math continual pretraining on the 15B OpenWebMath corpus yields absolute few-shot accuracy gains up to 30% across 9 math tasks, and fine-tuned RHO-1-1B and 7B reach 40.6% and 51.8% on MATH, with RHO-1-7B matching DeepSeekMath using 3% of its pretraining tokens. General continual pretraining on 80B tokens improves average results across 15 tasks by 6.8%, and self-referencing yields up to 3.3% gains without high-quality reference data.
Introduction
Large language models improve by scaling parameters and data, but training on all available tokens is neither always optimal nor feasible. Existing data filtering often works at the document level, yet high-quality corpora can still contain noisy, ambiguous, or poorly aligned tokens that add ineffective gradient updates and limit learning. Prior work also struggles with balancing token removal against preserving meaning and useful data.
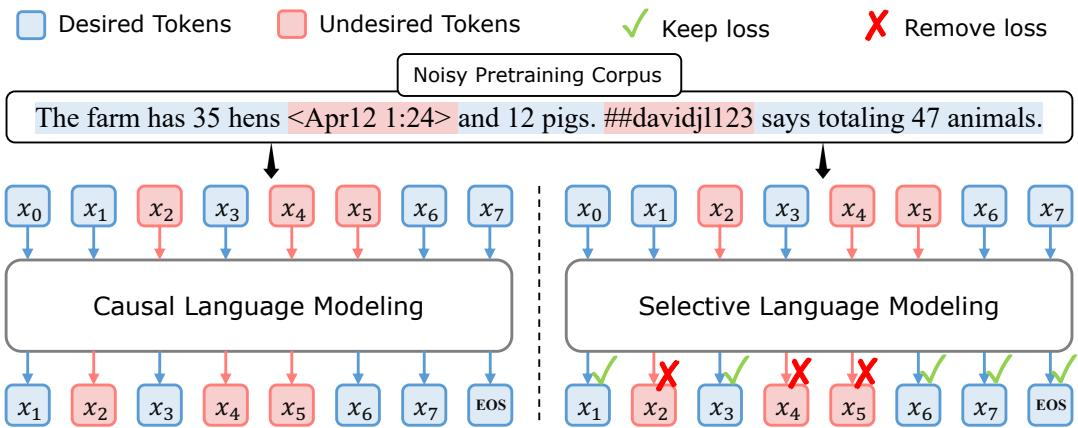
The authors analyze token-level training dynamics and show that loss reduction is concentrated in a subset of informative tokens, while many easy tokens are already learned and hard tokens may resist convergence. They introduce Selective Language Modeling, or SLM, which uses a reference model to score tokens and then trains on tokens with high excess loss, focusing updates on tokens most beneficial for downstream tasks. This approach improves token efficiency and performance, especially in math continual pretraining and general continual pretraining.
Method
The proposed method is built around a token-level observation: during standard causal language modeling, different tokens do not contribute equally to learning. The authors first examine how token-level losses evolve during pretraining. They continue training a small language model on a large corpus and repeatedly evaluate losses on a validation set. Refer to the figure below:
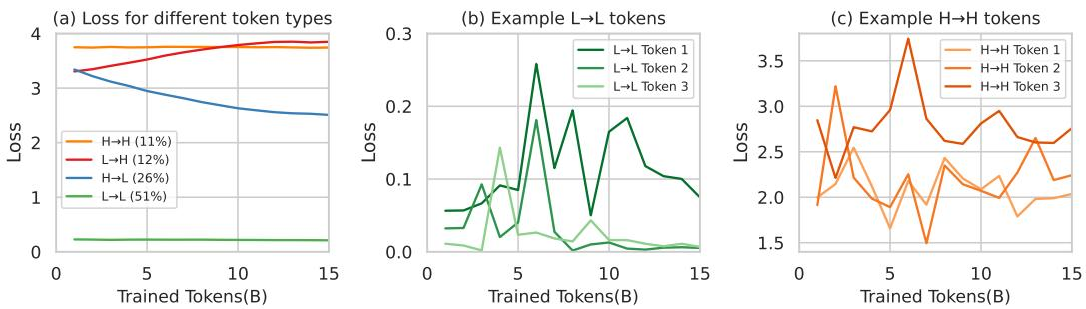
The training trajectories separate tokens into four behavioral categories. Some tokens remain persistently low loss, indicating they have already been learned. Others start with high loss and reduce significantly, meaning they still provide meaningful learning signal. A smaller group remains persistently high loss, which may reflect ambiguous or intrinsically uncertain content. Another group initially has low loss but increases during training, suggesting unstable optimization or noisy supervision. Moreover, many tokens show fluctuating losses rather than smooth convergence, which can cause inefficient gradient updates if all tokens receive equal training weight. This motivates a selective training objective that emphasizes tokens with richer learnable signal and suppresses tokens that are already learned, irrelevant, or noisy.
To operationalize this insight, the authors propose Selective Language Modeling, a three-step training pipeline that uses a reference model to guide token selection during language model pretraining. The framework diagram is shown below:
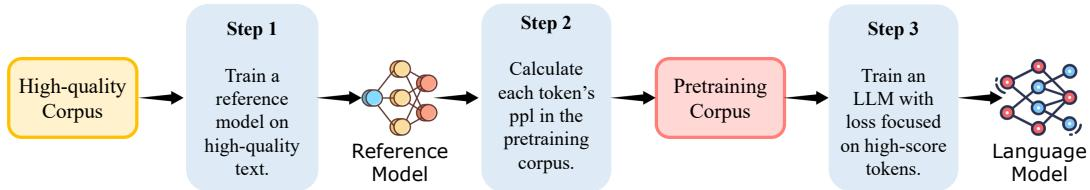
The first step is reference modeling. A reference model is trained on a curated high-quality corpus that represents the desired data distribution. This reference model acts as a scoring module rather than the final deployment model. For each token xi in a target pretraining corpus, the reference model computes a reference loss based on the probability it assigns to the token under the previous context x<i:
LRM(xi)=−logP(xi∣x<i).This reference loss captures how well the desired distribution supports the token. Low reference loss generally indicates tokens that are consistent with high-quality training data, while poorly supported tokens may reflect noise, ambiguity, or distribution mismatch.
The second step is token scoring. The trained reference model evaluates every token in the pretraining corpus, producing a reference-loss profile for the full training data. During active pretraining, the training model also computes its own token-level loss Lθ(xi) under parameters θ. The method then computes an excess loss for each token:
LΔ(xi)=Lθ(xi)−LRM(xi).This excess loss measures the gap between what the current training model predicts and what the reference model expects. Tokens with high excess loss are treated as more useful learning targets because they may still require adaptation while also being relevant to the reference distribution. Tokens with low excess loss are down-weighted or excluded, which reduces unnecessary updates on already learned or uninformative tokens.
The third step is selective pretraining. Instead of applying the standard causal language modeling loss uniformly to all tokens, the model optimizes cross-entropy only over a selected subset of high-scoring tokens. Given a batch with sequence length N and a selection ratio k%, the Selective Language Modeling loss is:
LSLM(θ)=−N⋅k%1i=1∑NIk%(xi)logP(xi∣x<i;θ),where the indicator function is
Ik%(xi)={1,0,if xi ranks in the top k% by S(xi),otherwise.By default, the score function S(xi) is the excess loss LΔ(xi). In practice, tokens in each batch can be ranked by this score, and only the top k% tokens contribute to the gradient. The full input sequence is still processed by the model, but the loss is masked away from tokens deemed less beneficial. This design preserves the context needed for autoregressive modeling while focusing optimization effort on the most informative token targets.
Experiment
The experiments evaluate selective language modeling through continual pretraining on both mathematical and general corpora, comparing against directly pretrained baselines and strong public models across few-shot reasoning, fine-tuning, and broad benchmark tasks. In mathematical training, the method improves chain-of-thought and tool-integrated reasoning while demonstrating efficient data use and some transfer to unseen tasks; in general training, it also yields broader benchmark gains, especially in code and math. Additional self-reference and ablation studies validate that the approach can select informative tokens without external high-quality data, that selected-token losses better track downstream performance, and that the method primarily retains relevant, high-learning-value tokens.
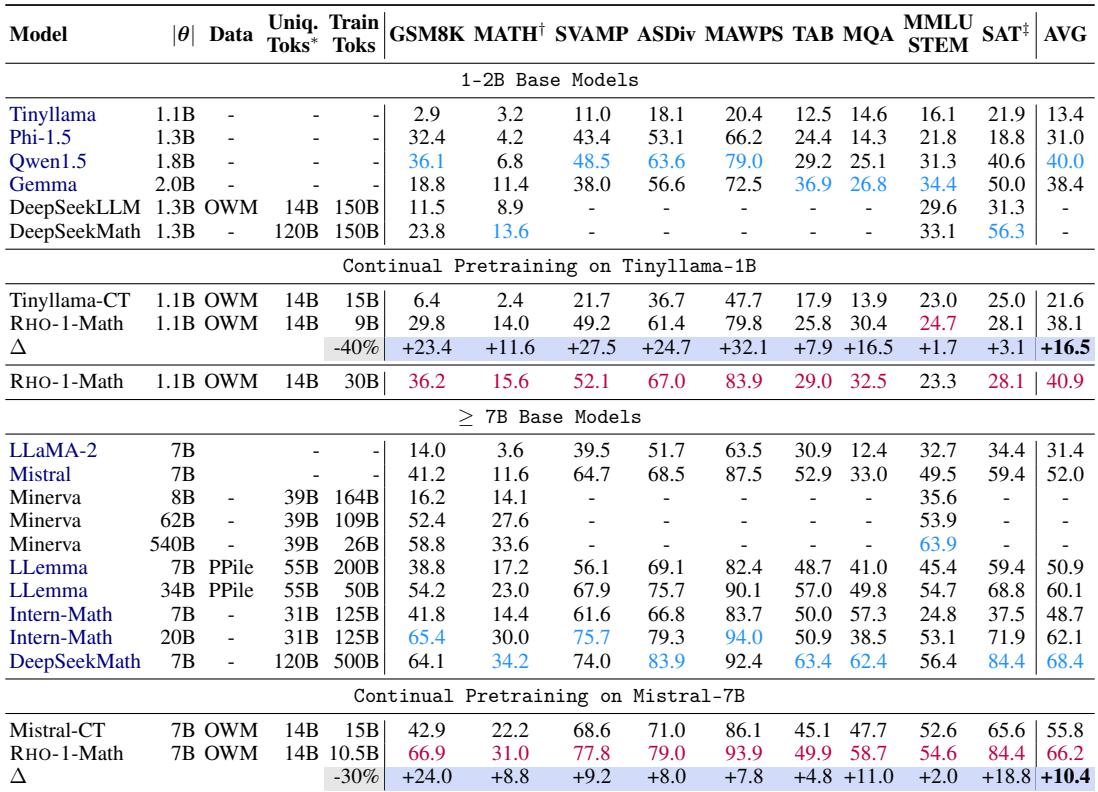
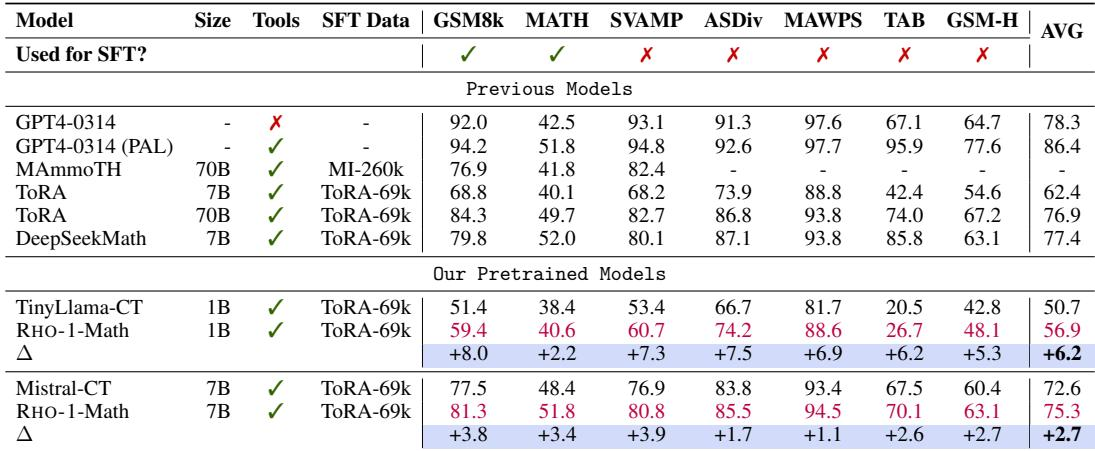
Few-shot CoT evaluations show that RHO-1-Math improves math reasoning accuracy over direct continued pretraining, with the clearest gains in smaller 1B models. Additional epochs on OpenWebMath further raise average accuracy. RHO-1-7B reaches performance comparable to much larger-token baselines while using far fewer selected math tokens. RHO-1-Math improves few-shot CoT accuracy over direct continued pretraining, with stronger gains for 1B models. Training on OpenWebMath for multiple epochs further raises average performance. RHO-1-7B reaches comparable few-shot results to DeepSeekMath-7B with a much smaller selected token budget.
Tool-integrated fine-tuning improves math reasoning performance, with the RHO-1 models achieving strong MATH accuracy at both 1B and 7B scales. Models using external tools and larger parameter counts tend to show stronger average results across the listed math tasks. RHO-1 also shows some generalization to unseen math tasks, with clearer relative gains for the 1B model than the 7B model. RHO-1 reaches strong MATH accuracy at both small and mid-sized model scales. Tool use and larger model size are associated with better overall math-reasoning performance.
A reference model trained only on OpenWebMath can guide further pretraining on the same corpus and improve average downstream math reasoning scores while using fewer training tokens. Selecting tokens with both reference-model loss and next-token entropy gives stronger gains than either score alone, and the same OWM-trained reference model also improves training on Proof-Pile-2 with fewer tokens. OWM-trained reference model improves OWM pretraining with less token training Entropy-only scoring yields gains similar to reference-model loss Intersection of loss and entropy selection gives best OWM average performance OWM-trained reference model also improves Proof-Pile-2 pretraining with fewer tokens
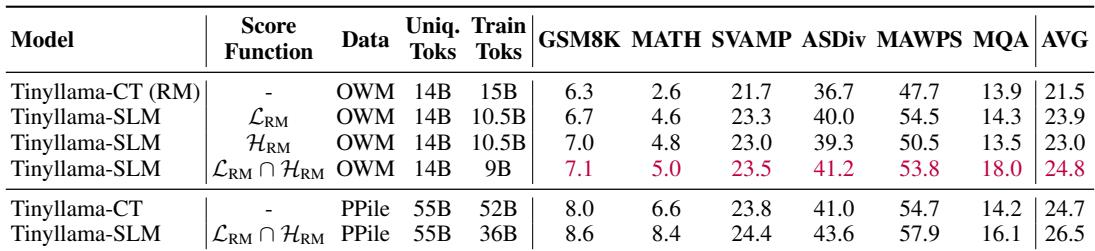
The experiments evaluate RHO-1 through few-shot chain-of-thought reasoning, tool-integrated fine-tuning, and reference-guided token selection for continued pretraining. These results validate that math-focused data selection improves reasoning over direct continued pretraining, with clearer benefits for smaller models, while tool use and larger model scales further strengthen performance. They also show that a reference model trained on OpenWebMath can guide more effective pretraining, especially when combining loss and entropy selection, and that the approach remains useful across related math corpora.