Command Palette
Search for a command to run...
Quel est réellement le niveau des grands modèles de langage en traduction littéraire ? Évaluation de la traduction littéraire avec des humains et des grands modèles de langage
Quel est réellement le niveau des grands modèles de langage en traduction littéraire ? Évaluation de la traduction littéraire avec des humains et des grands modèles de langage
Ran Zhang Wei Zhao Steffen Eger
Résumé
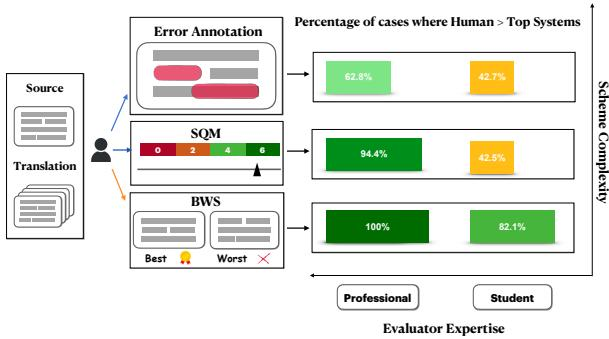
Des travaux récents se sont intéressés à la traduction automatique (TA) littéraire comme nouveau défi en traduction automatique. Toutefois, l'évaluation de la traduction automatique littéraire demeure une question ouverte. Nous contribuons à cette discussion en introduisant LITEVAL-CORPUS, un corpus parallèle au niveau du paragraphe contenant des traductions humaines vérifiées et les sorties de neuf systèmes de TA, totalisant plus de 2 000 traductions et 13 000 phrases évaluées sur quatre paires de langues, pour un coût de 4 500 €. Ce corpus nous permet de (i) examiner la cohérence et la pertinence des schémas d'évaluation humaine de complexités variées, (ii) comparer les évaluations d'étudiants et de professionnels, et d'évaluer l'efficacité (iii) des métriques fondées sur les LLM et (iv) des LLM eux-mêmes. Nos résultats indiquent que la pertinence de l'évaluation humaine est régie par deux facteurs : la complexité du schéma d'évaluation (plus le schéma est complexe, moins il est pertinent) et l'expertise des évaluateurs (une expertise plus élevée produit des évaluations plus pertinentes). Par exemple, MQM (Multidimensional Quality Metrics), un schéma complexe et le standard de facto de l'évaluation humaine non littéraire de la TA, s'avère largement inadéquat pour l'évaluation de la traduction littéraire : avec des évaluateurs étudiants, près de 60 % des traductions humaines sont mal jugées comme indistinguables ou inférieures aux traductions automatiques. En revanche, BWS (BEST-WORST SCALING), un schéma beaucoup plus simple, identifie les traductions humaines à un taux de 80 à 100 %. Les métriques automatiques obtiennent des résultats nettement inférieurs, avec des taux ne dépassant pas 20 %. Notre évaluation globale indique que les traductions humaines publiées surpassent systématiquement les traductions produites par les LLM ; même les LLM les plus récents tendent à produire des traductions considérablement plus littérales et moins diversifiées que celles des humains.
One-sentence Summary
Researchers from the University of Mannheim, University of Aberdeen, and University of Technology Nuremberg introduce LITEVAL-CORPUS, a 13$k$-sentence parallel corpus for literary translation evaluation across four language pairs, finding that simpler schemes like BWS identify human translations at 80–100%whilethecomplexMQMstandardmisjudgesnearly60%$$ as indistinguishable or inferior, and that LLM-generated translations are more literal and less diverse than human ones.
Key Contributions
- LITEVAL-CORPUS is introduced as a paragraph-level parallel corpus for literary machine translation evaluation, containing verified published human translations and outputs from nine MT systems, with more than 2,000 translations and 13,000 evaluated sentences across four language pairs.
- The paper presents a systematic comparison of human evaluation schemes and evaluator expertise, including Multidimensional Quality Metrics (MQM) and Best-Worst Scaling (BWS), and assesses the consistency and adequacy of LLM-based metrics and LLM-generated translations for literary texts.
- The results show that BWS identifies human translations at rates of 80 to 100 percent, while MQM with student evaluators misjudges nearly 60 percent of human translations as indistinguishable from or inferior to machine translations, and published human translations consistently outperform LLM translations, which tend to be more literal and less diverse.
Introduction
With large language models increasingly capable of translating literature, researchers are examining whether these systems can preserve authorial voice, cultural nuance, and aesthetic quality, especially for low resource languages. Literary translation is harder to evaluate than ordinary machine translation because linguistic accuracy is only one dimension and judgments must also account for creativity and target language acceptability. Prior automatic metrics have limited ability to separate high quality human literary translation from literal model output, while human evaluation frameworks such as MQM, SQM, and BWS have not been systematically compared for literary texts, and existing datasets are small, cover few systems, and often lack verified professional human translations. The authors address these gaps by releasing LITEVAL CORPUS, a verified paragraph level parallel corpus across four language pairs with nine translation systems, and by comparing human evaluation schemes and modern large language model based metrics to show which methods best identify human quality and to reveal that recent models still produce more literal and less diverse literary translations.
Dataset
Dataset: LITEVAL-CORPUS
-
The authors present LITEVAL-CORPUS, a paragraph-level literary translation evaluation dataset covering English, Chinese, and German. It spans four language directions: English to Chinese, German to English, English to German, and German to Chinese.
-
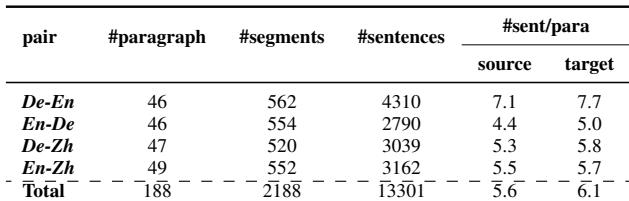
The corpus contains 188 source paragraphs, 2,188 paragraph-level translation segments, and more than 13k sentences. Source paragraphs average 5.6 sentences, while target paragraphs average 6.1 sentences.
-
The source and target paragraphs are collected from verified publications, including books from Project Gutenberg, published reading samples, and purchased materials. The dataset includes both classic and contemporary literary works. Classics are emphasized because they contain complex syntax, language change, and cultural references. Contemporary works are also included to reduce possible contamination from widely available texts already present in large language model pretraining corpora.
-
Quality filtering is based on verified publication status and human translation coverage. Classic works require at least two human translations for the target paragraph, while contemporary works require at least one human translation.
-
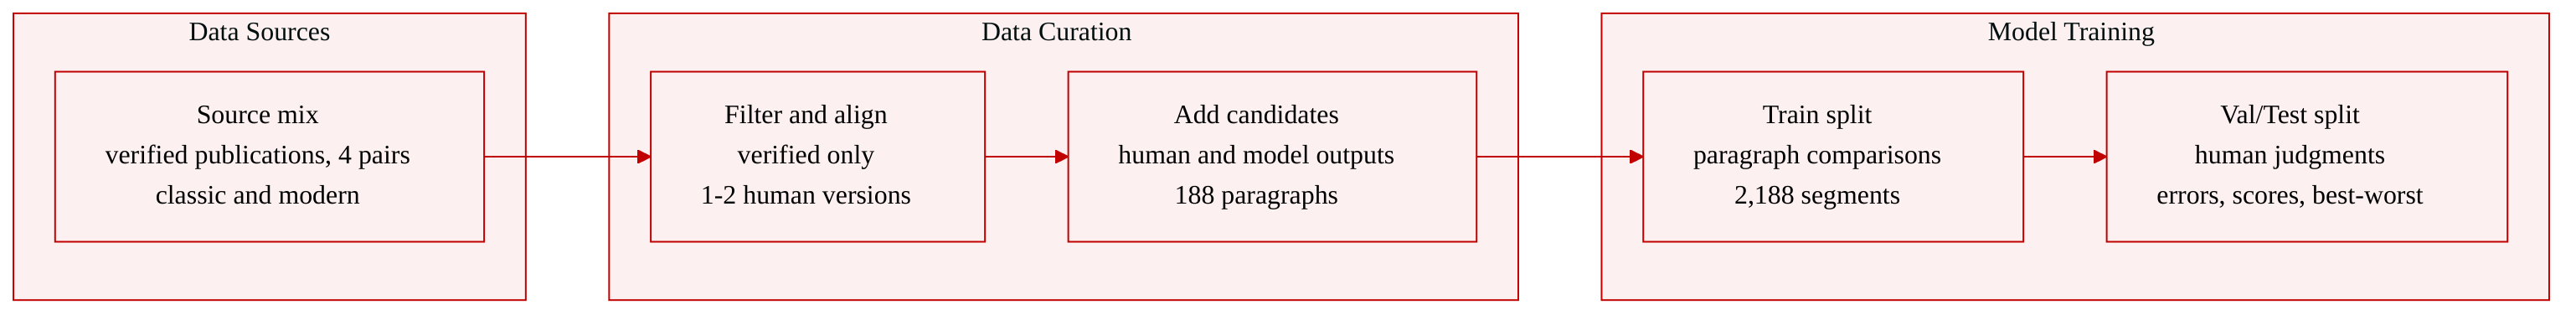
Dataset construction is divided into three steps: first, paragraph-level parallel corpora are selected and constructed; second, translation hypotheses are collected from machine translation and large language model systems; third, translation quality is assessed through human evaluation.
-
For classic German to English works, the authors reuse PAR3 samples. For contemporary German to English works and for all other language pairs, they build the corpus from scratch by manually aligning source and target paragraphs.
-
The dataset includes paragraph-level translation hypotheses from a broad set of generation systems. These include commercial systems such as Google Translate and DeepL, sentence-level transformer models such as NLLB-3.3B and M2M-100-1.3B, closed-source GPT-4o, and smaller open-source LLMs such as Llama 3, Qwen 2, Gemma 1.1, and TowerInstruct. LLM translation requests use a shared prompt template for literary text translation.
-
The evaluation subset is organized as paragraph-level comparisons. Each source paragraph is paired with multiple target translations, including human translations and model outputs, enabling direct comparison across systems and evaluation methods.
-
The authors use the data to construct human quality annotations with several evaluation schemes: guided error annotation based on MQM, free error annotation, SQM scalar rating, and best-worst selection. MQM annotations record error spans and classify errors into six categories: terminology, accuracy, fluency, style, locale convention, and non-translation. Each error is labeled as major or minor, and the MQM score is normalized by the number of sentences in the paragraph.
-
Human evaluation is divided by budget and role. Student evaluators perform MQM and SQM annotations for all segments, and also perform blind best-worst selection on samples. Professional translators perform free error annotation and SQM on samples, including comparisons involving human translations, GPT-4o, Google Translate, and DeepL, with Qwen used for pairs involving Chinese.
-
The dataset is processed at paragraph level rather than as isolated sentences. The authors do not describe sentence-level cropping for corpus construction; instead, paragraph alignment is used, and sentence counts are used for evaluation normalization and analysis.
-
The resulting dataset serves as a literary translation evaluation benchmark. It is used to generate system outputs, create translation comparison sets, collect span-level error annotations, record holistic quality judgments, and support analysis of paragraph-level literary translation quality across multiple systems and language pairs.
Method
The authors leverage a three-stage data construction pipeline for a literary translation corpus and benchmark. The process is designed around paragraph-level parallel data and combines curated human translation references, multiple machine translation outputs, and a final quality assessment step.
The first stage constructs paragraph-level parallel corpora for English, Chinese, and German, covering four language directions: English to Chinese, German to English, English to German, and German to Chinese. The authors select both classic and contemporary works to balance challenge and reliability. Classic texts are retained because they often contain complex syntax, historical language variation, and culturally specific references that are difficult for machine translation systems. At the same time, older human translations are valuable because they predate widespread machine translation use and are therefore less likely to contain machine translation traces. Contemporary works are also included to reduce the risk of contamination from texts that may already be present in the pretraining data of modern large language models.
To maintain high reference quality, the authors derive source and target paragraphs from verified publications, including books from Project Gutenberg, reading samples from published works, and purchased materials. For classic works, the target side contains at least two human translations, while contemporary works contain at least one. For classic German to English data, the authors use existing aligned samples from PAR3. For contemporary German to English data and the other three language pairs, the corpus is built manually, with the first author aligning source paragraphs to their human translations. This manual alignment step is a key quality-control component of the pipeline, especially for literary texts where paragraph-level equivalence may not be recoverable through automatic alignment alone.
The second stage selects machine translation systems and collects translation hypotheses for the same source paragraphs. The system selection is intentionally diverse, covering different model scales, deployment models, and training backgrounds. The authors include commercial systems such as Google Translate and DeepL, with DeepL being particularly relevant because it is widely used in translation workflows. They also include strong previous transformer models optimized for sentence-level translation, such as NLLB-3.3b and M2M-100-1.3b. In addition, the pipeline incorporates closed-source GPT-4o and several smaller open-source language models: Llama 3, Qwen 2, Gemma 1.1, and TowerInstruct. These models are selected to represent different parameter scales, language specializations, and instruction-following capabilities. For all large language models, the authors use the same prompt format to reduce prompt-induced variation across systems.
The third stage assesses translation quality over the collected hypotheses. This stage completes the workflow by evaluating the outputs produced from the curated source paragraphs and reference translations. Because the corpus is built at paragraph level and uses verified human references, the evaluation setting is suited for assessing how well machine translation systems handle literary and translation-specific phenomena such as long-range cohesion, stylistic nuance, and cultural adaptation.
Experiment
The study evaluates literary translation quality on LITEVAL-CORPUS using student and professional evaluators across guided MQM, free error annotation, SQM, and BWS, then compares these judgments with reference-free automatic metrics including GEMBA-MQM, XCOMET, and Prometheus. Human results show moderate to high consistency within schemes, with BWS giving the most reliable discrimination of human and top machine outputs, while student MQM and SQM are less adequate unless combined or guided by professional expertise. Automatic metrics correlate only moderately with human MQM and generally fail to distinguish high-quality human translations from strong LLM outputs, especially for fluency, style, and terminology. The findings also indicate that LLM-based translations are more literal and less diverse than human translations, and LLM evaluators may favor similar or their own outputs.
The corpus contains paragraph-level literary translations across four language pairs, with broadly comparable numbers of source paragraphs and translation segments but much larger sentence counts. Target paragraphs are generally more sentence-dense than source paragraphs, and the language pairs differ noticeably in average sentence load. German-to-English is the most sentence-heavy pair, while English-to-German is the most compact. German-to-English data shows the highest average sentences per source and target paragraph. English-to-German data is the most compact in sentence density, while Chinese-involving pairs fall between the extremes. Target text usually has more sentences per paragraph than source text, suggesting variation in sentence segmentation across languages.
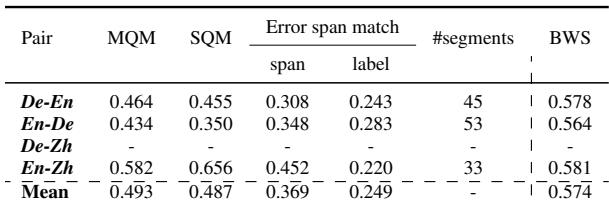
Student evaluator pairs show moderate agreement on overall translation scores, with MQM and SQM producing broadly similar Kendall's Tau agreement across the evaluated language pairs. Span and label agreement is lower than overall score agreement, especially when evaluators must match both error spans and labels, while BWS span agreement is comparatively higher. En-Zh generally yields the strongest score agreement, whereas En-De shows the weakest. MQM and SQM have similar average agreement among student evaluators. Label match is the weakest span-level agreement measure. BWS span agreement is higher than average MQM and SQM agreement.
Human evaluation schemes generally prefer human translations over other machine systems, but their judgments differ sharply for top models. Student MQM performs better against non-top systems than against top systems, while GEMBA-MQM versions rarely prefer human translations over top models. Professional SQM and combinations of student MQM with SQM show stronger human preference, indicating that evaluator expertise and scheme design matter. Human MQM and SQM frequently rank human translations above other systems. Student MQM is much less effective when top machine systems are included. Professional SQM shows a large improvement over student SQM in identifying human translations. GEMBA-MQM versions tend to prefer top machine outputs over human translations.
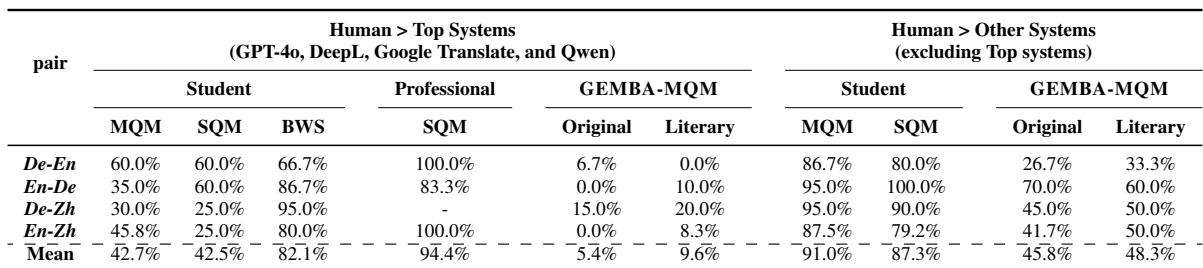
The experiments evaluate a paragraph-level literary translation corpus across four language pairs, an evaluator agreement study, and a human-evaluation system ranking study. The corpus analysis shows that target paragraphs are generally more sentence-dense than source paragraphs, with notable differences among language pairs in average sentence load. Agreement analysis indicates that student evaluators reach moderate consistency on overall scores, especially for En-Zh, while agreement is weaker when matching error spans and labels. System ranking results show that evaluation schemes with professional expertise and SQM-like design are more effective at preferring human translations, whereas LLM-based schemes can favor top machine outputs.