Command Palette
Search for a command to run...
Votre benchmark est-il véritablement adversarial ? ADVSCORE : évaluation de l'adversarité ancrée dans l'humain
Votre benchmark est-il véritablement adversarial ? ADVSCORE : évaluation de l'adversarité ancrée dans l'humain
Yoo Yeon Sung Maharshi Gor Eve Fleisig Ishani Mondal Jordan Boyd-Graber
Résumé
Les jeux de données adversariaux devraient valider la robustesse de l'IA en fournissant des échantillons sur lesquels les humains obtiennent de bons résultats, contrairement aux modèles. Cependant, à mesure que les modèles évoluent, les jeux de données peuvent devenir obsolètes. La mesure du caractère adversarial persistant d'un jeu de données est entravée par l'absence de métrique standardisée pour quantifier l'adversarité. Nous proposons ADVSCORE, une métrique d'évaluation ancrée dans les réponses humaines qui évalue l'adversarité d'un jeu de données en captant les capacités variables des modèles et des humains, tout en identifiant les exemples de mauvaise qualité. Nous utilisons ensuite ADVSCORE pour justifier un nouveau pipeline de création de jeux de données permettant de générer des échantillons adversariaux réalistes et de haute qualité, ce qui nous a permis de collecter un jeu de données de questions-réponses adversariales (QA), ADVQA. Nous appliquons ADVSCORE en utilisant 9 347 réponses humaines et les prédictions de dix modèles de langage pour suivre l'amélioration des modèles sur cinq ans (2020–2024). ADVSCORE fournit ainsi des orientations pour atteindre une robustesse comparable aux capacités humaines. De plus, elle permet de déterminer dans quelle mesure les jeux de données adversariaux continuent de représenter un défi, garantissant qu'ils testent effectivement les capacités des modèles plutôt que de refléter des difficultés obsolètes ou artificielles.
One-sentence Summary
University of Maryland and UC Berkeley introduce ADVSCORE, a human-grounded metric that quantifies adversarialness by capturing the performance gap between humans and models, enabling the construction of realistic adversarial QA datasets (ADVQA) and tracking whether benchmarks remain challenging as models improve over five years.
Key Contributions
-
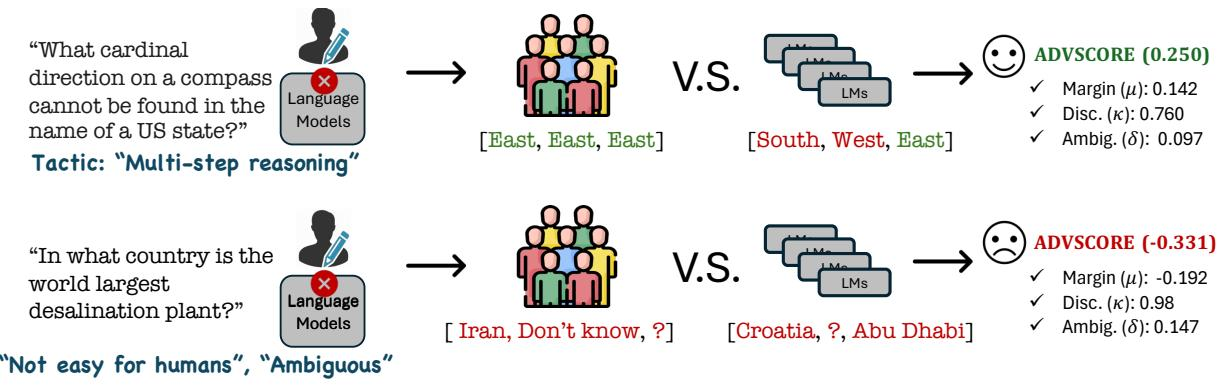
ADVSCORE is a human-grounded metric, built on item response theory, that scores dataset and example adversarialness and discriminability by capturing varying human and language model abilities and identifying poor examples.
-
A human-in-the-loop, ADVSCORE-driven creation pipeline is used to produce ADVQA, a QA benchmark of realistic, high-quality adversarial questions intended to remain discriminative across model and human skill levels.
-
Experiments using 9,347 human responses and predictions from ten language models from 2020 to 2024 show that ADVQA declines less in adversarialness than other adversarial benchmarks and that current models, including GPT4, still struggle with commonsense reasoning, multistep reasoning, and topics such as Lifestyle.
Introduction
As language models approach high scores on standard benchmarks, adversarial datasets are needed to expose weaknesses in safety, commonsense reasoning, and multistep reasoning. Prior work often relies on fixed, human authored, or synthetically amplified examples that can become outdated, ambiguous, or biased, and existing evaluation methods do not systematically measure whether a dataset still captures the human model ability gap. The authors leverage item response theory to introduce ADVSCORE, which quantifies adversarialness from human answers while penalizing ill posed items and evaluates discriminability for ranking model ability. They apply this framework to build ADVQA, a human-in-the-loop adversarial question benchmark designed to preserve realistic, challenging tasks where current models remain weaker than humans.
Dataset
-
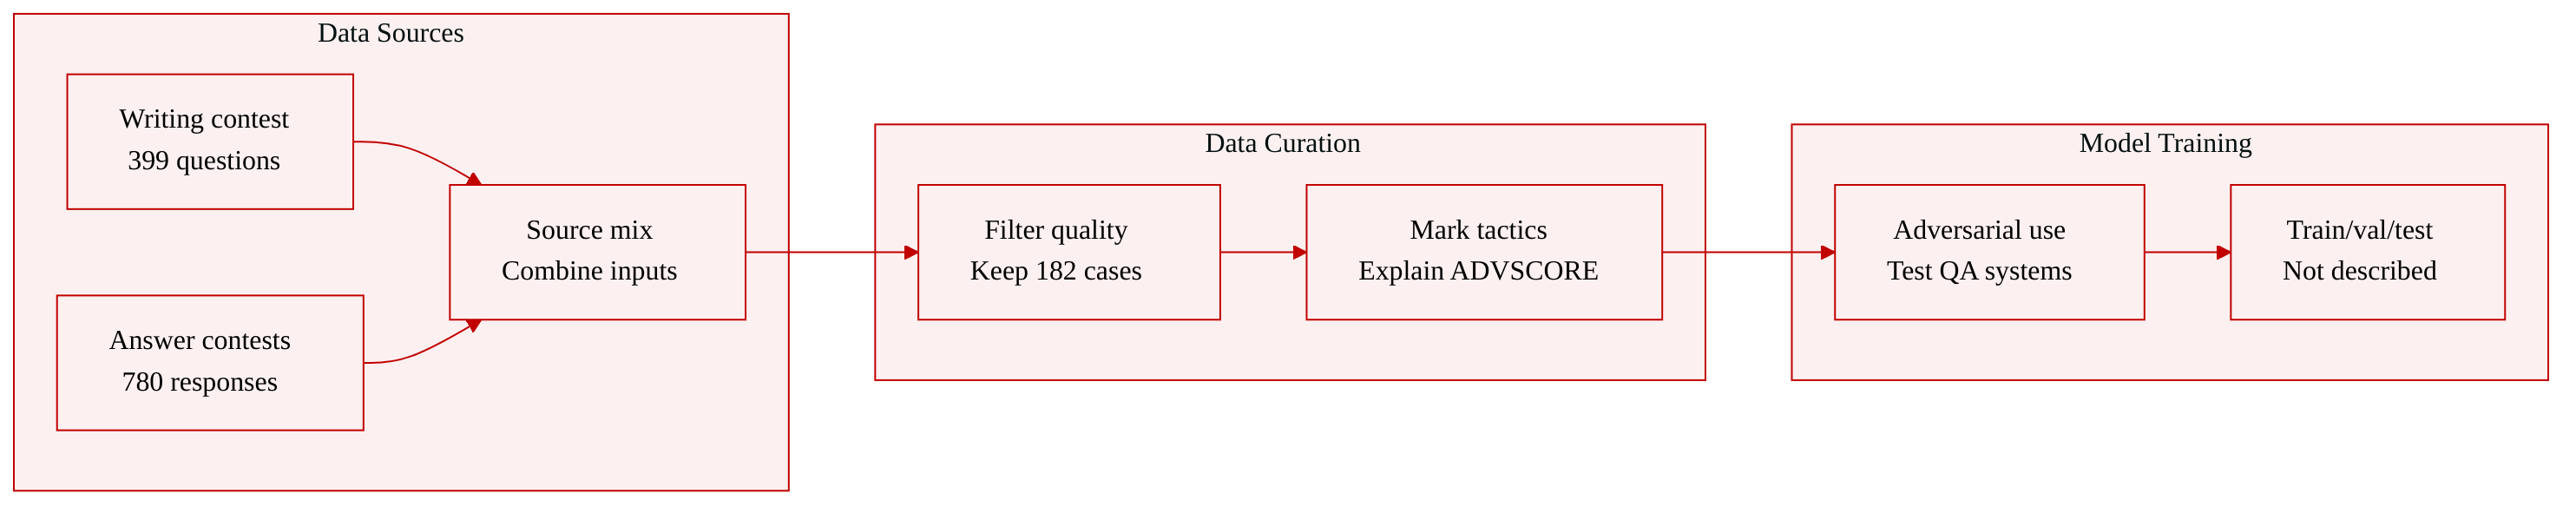
The authors construct ADVQA as a human-created adversarial question answering dataset, not as an automatically generated model attack dataset. It comes from two adversarial competitions: a question writing competition and an answering competition.
-
The writing competition yields 399 adversarial questions. Skilled writers use an adversarial interface while viewing a Wikipedia page for the target answer. The interface shows real time retrieval and QA feedback so writers can revise questions that models answer correctly.
-
The answering competition yields 780 human responses from eight expert trivia groups, each composed of three to four trivia experts. The authors run eight human versus model QA tournaments, each initially containing 30 questions.
-
After tournament filtering, based on expert comments such as detecting ill posed questions, the final ADVQA dataset contains 182 questions.
-
During writing, the feedback loop uses sentence indexed Wikipedia pages and lightweight retrieval models, specifically a TFIDF baseline and DPR. A RoBerta based FarmReader model fine tuned on SQuAD ranks retrieved sentences by relevance. DistilBERT fine tuned on SQuAD provides extractive QA predictions, and T5 provides closed book answer predictions.
-
These model components are used for dataset construction and writer guidance. The provided text does not describe a final cropping strategy, training split, validation split, mixture ratio, or training schema for downstream model use.
-
Filtering targets realistic adversarial quality. Questions are kept when they expose genuine model weaknesses, such as difficulty composing clues or excluding redundant clues, rather than failures caused by trivial issues like grammar mistakes. Editors and tournament answerers help exclude unnatural or ambiguous questions.
-
The authors also annotate adversarial tactics and topics and relate them to ADVSCORE. This helps explain why some questions are strongly adversarial, such as commonsense knowledge questions on lifestyle topics.
-
The paper uses ADVQA primarily as an adversarial evaluation dataset for QA systems. Human responses are treated as important evaluation signals because they capture diverse human reasoning and make the benchmark more realistic than purely model generated adversarial data.
Method
The authors leverage a psychometric evaluation pipeline called ADVSCORE to assess how adversarial and how informative a question answering dataset is. The core of the pipeline is an item response theory model that estimates latent parameters for both subjects and questions. These parameters are then used to construct two principal metrics: adversarialness, which captures whether well-formed questions are harder for skilled models than for skilled humans, and discriminability, which captures whether a question effectively separates subjects of different skill levels.
IRT-Based Subject and Item Modeling
The method treats a question answering task as an interaction between subjects and items, where subjects can be humans or language models. Each subject has a latent skill parameter, and each question has a latent difficulty and discriminability parameter. The authors use a two-parameter logistic IRT model to estimate the probability that subject i answers question j correctly.
The response probability is modeled as:
p(rij=1∣βi,θj,γj)=σ(γj(βi−θj))Here, βi is the skill of subject i, θj is the difficulty of question j, γj is the discriminability of question j, and σ is the sigmoid function. The term (βi−θj) is interpreted as the skill gap between the subject and the question. When the subject’s skill equals the question difficulty, the predicted correctness probability is 0.5. A larger positive skill gap produces a higher probability of a correct answer.
The parameter γj controls the sensitivity of the probability curve to changes in skill gap. A high γj means that answering the question correctly strongly depends on whether the subject has sufficient skill. A low γj means that responses are less informative about skill, which may happen when a question is ambiguous, ill-posed, or dominated by guessing.
The IRT fitting process estimates βi, θj, and γj by maximizing the likelihood of the observed correctness responses. In effect, the model learns which questions are difficult for most subjects, which questions produce correct answers in a way that depends on subject skill, and which subjects possess skills consistent with the observed answer patterns.
This formulation gives a more nuanced view than simple question success rate. A question answered correctly by half of the subjects could be difficult but well-posed, ambiguous, or poorly written. IRT can distinguish these cases because it accounts for which subjects answered each question. If high-skill subjects tend to answer correctly while low-skill subjects tend to fail, the model assigns the question high discriminability. If correctness appears uncorrelated with skill, the model assigns lower discriminability.
Quantifying Adversarialness
The authors define a question as adversarial when skilled humans answer it correctly more often than skilled models, while the question remains well-formed. To measure this, they use the fitted IRT parameters to compute predicted correctness probabilities for representative human and model subjects.
First, they define skilled groups based on statistical thresholds over subject skill. For a set of subjects S, a skilled group at level k consists of subjects whose skill exceeds the mean skill by at least k standard deviations:
βi>μβS+kτβSThe representative skill of a group g is defined as the expected skill of its members:
β∗g=Eβi∼g[βi]The main adversarialness computation uses k=0, which corresponds to subjects above the average skill level within their respective pools. The authors designate skilled humans as H(0) and skilled models as M(0). For each question j, they compute a performance margin:
μj=σ2pl(β∗H(0),θj,γj)−σ2pl(β∗M(0),θj,γj)In this expression, σ2pl(β,θ,γ) is the 2PL IRT response function using representative skill β, question difficulty θj, and question discriminability γj.
A positive value of μj indicates that the representative skilled human has a higher probability of answering question j correctly than the representative skilled model. The larger the positive margin, the more adversarial the question is considered to be, assuming the question is otherwise well-posed.
Discounting Ambiguous Questions
The raw margin μj captures the human-model gap but does not by itself guarantee that the human advantage comes from genuine question difficulty. Ambiguous or poorly specified questions could produce a large gap if humans and models interpret the question differently, or if expert humans disagree about the correct answer. To penalize such cases, the authors introduce a disagreement-based discount.
They define a highly skilled or expert human group as H(1), meaning humans whose skill is at least one standard deviation above the human mean. For each question, they compute the disagreement among these expert humans using the mean deviation of their predicted correctness probabilities:
δj=i∼H(1)MD[σ2pl(βiH(1),θj,γj)]The adjusted adversarialness score is then:
μj′=1+δjμjThis discount term reduces the adversarialness score when expert humans show higher disagreement. Questions that are ambiguous, ill-posed, or sensitive to interpretation are therefore penalized, even if they initially appear to create a large human-model performance gap. This makes the metric more faithful to true adversarial quality, because a useful adversarial dataset should contain challenging questions rather than questions that are merely confusing.
Measuring Discriminability
The authors also measure whether a question is informative for distinguishing subject skill levels. They define this as discriminability using Fisher information applied to the 2PL IRT response function.
For question j, the item information function is:
IIFj(θ)=γj2⋅pj(θ)⋅(1−pj(θ))where
pj(θ)=σ2pl(θ,θj,γj)The item information function quantifies how much statistical information a question provides about a subject’s skill θ. Questions with high discriminability, represented by a large γj, are more informative when they are at a moderate difficulty level, where the predicted correctness probability is close to 0.5. At that region, changing a subject’s skill level strongly affects the response probability, making the question useful for separating stronger and weaker subjects.
To obtain a single scalar discriminability score, the authors integrate the item information function over the entire skill range:
TIFj=∫−∞∞IIFj(θ)dθThis total item information is then mapped to a bounded discriminability score through exponential normalization:
κj=1−exp(−TIFj)The resulting κj is a calibrated measure of how strongly question j separates subjects with different skill levels. Higher values indicate that the question is more informative about subject competence.
Combining Adversarialness and Discriminability
The final ADVSCORE for an individual question combines the ambiguity-discounted adversarial margin with the discriminability bonus:
ADVSCOREj=1+δjμj⋅(1+κj)This design makes the human-model performance gap the main driver of the score, while discriminability acts as a multiplicative bonus. Questions that are only moderately discriminative still rely on a positive human-model gap to receive a meaningful score. Questions that show a large gap but low discriminability, or that show ambiguous expert disagreement, are penalized. Questions that are both adversarial and informative receive the highest scores.
For a dataset, the authors define the dataset-level ADVSCORE as the average question-level ADVSCORE. This aggregates the quality of individual questions into a dataset-level indicator. A higher dataset score suggests a collection containing more well-posed questions where skilled humans outperform skilled models and where the questions provide useful signal about subject skill.
ADVQA Creation Pipeline
The authors also present a dataset creation pipeline that uses the ADVSCORE logic as guidance. This pipeline is built around adversarial competitions in which humans attempt to write questions that challenge models while remaining clear and answerable.
The creation process has two main stages: a writing competition and an answering competition.
In the writing competition, human authors submit question answer pairs intended to be difficult for models but solvable by humans. The submitted questions are not accepted directly. Instead, expert editors review, edit, and filter the questions to improve answerability and reduce ambiguity. This editing stage is important because adversarial questions can easily become vague, unfair, or dependent on idiosyncratic phrasing. Human expert review helps preserve questions that are genuinely challenging rather than accidentally broken.
In the answering competition, human experts answer the collected questions against model systems. The authors organize human versus model tournaments, collect human responses, and then filter the question set based on expert feedback. Questions identified as ill-posed, ambiguous, or otherwise problematic are removed. The final retained question set therefore reflects a workflow that combines adversarial human writing with post-hoc expert validation.
The authors also use the ADVSCORE itself as a reward signal. Writers are incentivized based on the ADVSCORE of their questions, which encourages authors to produce questions that are not merely difficult for models, but also clear, discriminative, and consistent with human judgment. Players in the answering competitions are incentivized based on demonstrated skill, which helps identify subjects whose responses are informative for IRT fitting.
Adversarial Writing Interface
The writing process is supported by an interactive interface that turns question authoring into a human-AI adversarial loop. The interface gives authors real-time feedback about how retrieval and question answering models would likely respond to their draft questions. This lets authors revise wording that makes the question too easy for models and remove phrasing that inadvertently gives away the answer.
The interface centers on a target answer. Authors work from a reference page for that answer and construct a question whose intended answer is known. While they type, the system continuously updates multiple model components.
A retrieval widget shows whether the question retrieves passages or sentences that contain the target answer. If the target answer appears near the top of retrieval results, the question is likely easy for a retrieval-augmented QA system, so the author is prompted to rephrase it. The pipeline includes a lightweight sparse retrieval component and a neural dense retrieval component. To support fast feedback, the system indexes sentence-level passages from a controlled set of Wikipedia pages. Retrieved sentences are then passed to a reader model that scores and sorts them by relevance. This retrieval-reader loop approximates how a modern open-domain QA system might process the author’s question.
The interface also includes model prediction widgets. For extractive QA, a lightweight fine-tuned language model is used to predict answer spans from retrieved contexts. For closed-book or generative settings, a larger sequence-to-sequence model is used to answer the question directly. These predictions help authors see when a model can infer the target answer without explicit support from a retrieved passage.
In addition, the interface highlights input perturbations inside the question. The system identifies tokens or phrases whose substitution is especially likely to change the model prediction. This guides the author toward minimal wording changes that reduce model success without altering the intended question. For example, if a particular word strongly cues the model toward the correct answer, the author can replace or restructure that word while preserving the factual intent of the question.
Filtering and Quality Control
Filtering occurs at multiple points in the pipeline. In the writing competition, expert editors rewrite or remove low-quality adversarial questions. In the answering competition, expert human groups provide comments that help identify ill-posed or unfair items. Questions with ambiguous interpretations or questionable answerability are excluded from the final dataset.
This workflow couples adversarial generation with psychometric evaluation and human validation. The interface encourages authors to target weaknesses in retrieval and reading systems, while expert filtering ensures that accepted questions remain human-answerable and not merely adversarial in a pathological sense. The ADVSCORE then quantifies whether the resulting dataset successfully balances these two goals.
Experiment
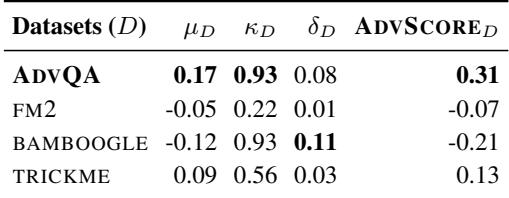
Researchers evaluate ADVSCORE by collecting human and model responses for several adversarial benchmarks, including ADVQA, TRICKME, FM2, and BAMBOOGLE, and applying item response theory to assess separation between human and model abilities. The experiments show that ADVQA best captures true adversarial questions by combining meaningful human versus model gaps with discriminative question design, while TRICKME is adversarial but less informative and FM2 and BAMBOOGLE often fail as adversarial benchmarks. A temporal analysis further indicates that some benchmarks have become less adversarial as models improve, with ADVQA retaining the strongest adversarial properties and overall ADVSCORE providing a more reliable assessment than simple success-rate comparisons.
ADVQA is identified as the most adversarial dataset because it combines a positive human advantage with very strong discrimination across skill levels. BAMBOOGLE shows comparable discrimination but a negative human advantage, indicating that models generally handled its questions better than humans, while FM2 appears weakly discriminative and easier for models. TRICKME remains positive in adversarialness but is described as having lost strength over time. ADVQA ranks highest overall in adversarialness. BAMBOOGLE separates skill levels well but favors models over humans. FM2 has weak discrimination and appears easier for models than humans. TRICKME is less adversarial than ADVQA and shows temporal decline.
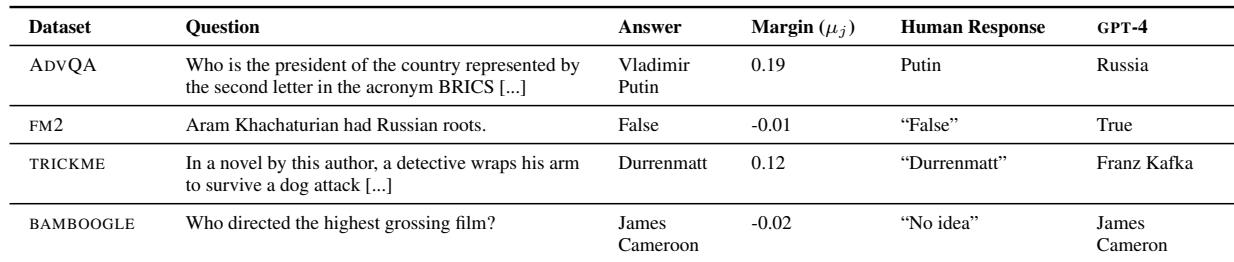
The examples show that ADVQA and TRICKME have positive human-model margins, where humans gave correct answers while GPT-4 made errors. In contrast, FM2 and BAMBOOGLE have negative margins, indicating that the models answered correctly when humans did not. This supports ADVQA as the most balanced adversarial benchmark among the shown datasets. ADVQA has a positive margin with a correct human answer and an incorrect GPT-4 answer. FM2 and BAMBOOGLE have negative margins, showing the examples were easier for GPT-4 than humans. TRICKME also shows a positive margin with a correct human answer and an incorrect GPT-4 answer.
The experiments compare adversarial datasets by assessing how well they discriminate between human and model performance over time. ADVQA emerges as the most adversarial and balanced benchmark, combining positive human advantage with strong skill-level separation, while TRICKME also shows human advantage but is less robust overall. BAMBOOGLE remains discriminative yet favors models over humans, and FM2 is weaker, more model-friendly, and less challenging for models relative to humans.